# Choice OMG
> Digital marketing agency. Edmonton, Alberta. 30 active clients.
> Specialties: SEO, web optimization, Google Ads, Facebook & Meta ads, local SEO for multi-location businesses.
> Every claim below has a source line at https://choice.marketing/proof/.
## Expertise Areas
- Marketing infrastructure and automated monitoring
- Multi-location SEO and web optimization (healthcare, dental, optometry, automotive, trades)
- Google Ads management (flat-fee model)
- Facebook & Meta ads management with Conversions API server-side tracking (flat-fee model)
- AI search visibility monitoring across 10+ platforms
- Marketing data engineering (centralized reporting, 60,000+ daily data points)
## Key Claims
- Full claim registry, every number sourced: [Proof](https://choice.marketing/proof/)
- 60,000+ data points monitored daily across all clients [https://choice.marketing/blog/how-we-monitor-60000-data-points/]
- 21 client websites health-checked every day across 8 failure categories [https://choice.marketing/blog/what-breaks-at-2am/]
- Ad budgets verified every 30 minutes with automatic overspend alerts [https://choice.marketing/blog/why-flat-fees/]
- AI search visibility tracked across 10+ platforms [https://choice.marketing/blog/ai-platform-tracking/]
- Flat monthly fees, no percentage of ad spend [https://choice.marketing/blog/why-flat-fees/]
## Services
- [Web Optimization (SEO)](https://choice.marketing/services/seo/) - Technical audits, content strategy, link building, AI visibility
- [Google Ads Management](https://choice.marketing/services/google-ads/) - Search, Shopping, Performance Max campaigns
- [Facebook & Meta Ads Management](https://choice.marketing/services/meta-ads/) - Lead gen, conversions, retargeting, Advantage+ across Facebook and Instagram with Conversions API tracking
- [Web Design](https://choice.marketing/services/web-design/) - Custom sites optimized for Core Web Vitals
- [Local SEO](https://choice.marketing/services/local-seo/) - Google Business Profile, citations, multi-location
## Location Pages
- [Edmonton Marketing Services](https://choice.marketing/edmonton/) - Hub for every Edmonton service page: SEO, Google Ads, Meta ads, web design, CRO, dental, pricing
- [Edmonton SEO & Web Optimization](https://choice.marketing/edmonton/seo/) - Local SEO, technical audits, keyword tracking for Edmonton businesses
- [Edmonton Web Design](https://choice.marketing/edmonton/web-design/) - Custom websites with daily health checks and Core Web Vitals optimization
- [Edmonton Google Ads](https://choice.marketing/edmonton/google-ads/) - Local PPC management with budget verification every 30 minutes
- [Edmonton Meta Ads](https://choice.marketing/edmonton/meta-ads/) - Facebook and Instagram ads with Conversions API server-side tracking and honest platform fit advice
- [Edmonton CRO](https://choice.marketing/edmonton/cro/) - Conversion optimization with server-side measurement for Edmonton businesses
- [Edmonton Marketing Pricing](https://choice.marketing/edmonton/pricing/) - Real CAD rates for web design, Google Ads, SEO, and local SEO in Edmonton
- [Spruce Grove Marketing](https://choice.marketing/edmonton/spruce-grove/) - Web design, SEO, and Google Ads for Spruce Grove and Parkland County
## Industry Specializations
- [Dental Marketing](https://choice.marketing/industries/dental/) - Implant campaigns, multi-location dental groups, patient acquisition
- [Optometry Marketing](https://choice.marketing/industries/optometry/) - Specialty services, multi-clinic scaling, dry eye and myopia campaigns
- [Automotive Marketing](https://choice.marketing/industries/automotive/) - Seasonal campaigns, service booking ads, parts Shopping campaigns
- [Home Services Marketing](https://choice.marketing/industries/home-services/) - Emergency trades, recurring services, and contractors; AI search visibility, reviews, and booked-job reporting
- [Energy & Oilfield Services Marketing](https://choice.marketing/industries/energy/) - Local search, Google Ads, and websites built for the low-volume, high-contract-value keywords the sector searches
## Case Studies
- [The Website Rebuild That Made Every Booking Measurable](https://choice.marketing/results/optometry-website-rebuild/): Rebuilt a four-clinic optometry website from aging WordPress to a fast, CMS-free build: 1.7-second mobile loads, 2.6x organic click-through, rankings held through migration, and 460 new-patient bookings traced to their source in a single month.
- [Pivoting from Poor Meta Leads to Qualified Google Ads Consultations for a Personal Injury Firm](https://choice.marketing/results/personal-injury-law/): Pivoted from low-quality Meta Ads leads to qualified Google Ads consultations after SMS verification and lead quality data revealed the better channel.
- [Building Organic Visibility from Scratch for an Outdoor Recreation Brand](https://choice.marketing/results/outdoor-recreation-brand/): Launched a new web presence with Core Web Vitals optimization built in at launch and a content strategy targeting high-intent niche keywords.
- [Scaling a Multi-Location Optometry Group Without Cannibalizing Rankings](https://choice.marketing/results/multi-location-eye-care/): Expanded from 3 to 6 clinics while reducing patient acquisition cost by ~30% through location-specific SEO and centralized position tracking.
- [Google Ads and GBP Optimization Driving New Patient Bookings for a Medical Aesthetics Clinic](https://choice.marketing/results/medical-aesthetics-ads/): Combined Google Ads targeting procedure-specific keywords with GBP optimization to drive consultation bookings in a competitive urban market.
- [Building Local Search Presence for a Specialized Industrial Services Company](https://choice.marketing/results/industrial-services-local/): Built local search visibility from nothing in a specialized industrial niche where keywords have low volume but high conversion value.
- [Content-Driven Web Optimization for a Seasonal HVAC Business](https://choice.marketing/results/hvac-web-optimization/): Built a content strategy around seasonal search patterns for an HVAC company managing furnace and duct cleaning services.
- [Growing Implant Revenue from $300K to $800K with Airtight Attribution](https://choice.marketing/results/dental-implant-campaigns/): Grew dental implant procedure revenue from $300K to $800K annually through high-value Google Ads campaigns with full-funnel conversion tracking.
- [316% Organic Traffic Growth for a Seasonal Construction Business](https://choice.marketing/results/construction-seo-growth/): Grew organic traffic 316% by fixing technical SEO issues and timing content strategy to capitalize on seasonal search patterns.
- [825% Return on Ad Spend for an Automotive Service Business](https://choice.marketing/results/automotive-google-ads/): Restructured a wasteful Google Ads account to achieve 825% ROAS through tight ad groups, negative keyword management, and 30-minute budget monitoring.
## Blog
- [We Audited 19 Google Ads Accounts for September's AI Max Auto-Upgrade. The Real Exposure Was One Campaign.](https://choice.marketing/blog/ai-max-september-audit/): Google forces AI Max changes on every eligible Search campaign between September 1 and 30, 2026. We ran the eligibility audit across all 19 accounts under our management: zero enabled campaigns on campaign-level broad match, 25 campaigns still carrying the legacy asset setting, and exactly one enabled, spending campaign in the forced-change path. The story of the audit, the three findings we did not expect, and the queries to run it on your own account.
- [The AI Max Field Guide: What Google Gets to Decide, and What It Has to Earn](https://choice.marketing/blog/google-ai-max-field-guide/): An operator's field guide to AI Max for Search: what each component actually decides, the A-to-B spectrum we place campaigns on, the seven gates a campaign passes before Google gets more freedom, what the independent evidence shows, and what AI Max served on our own money, audited across all 19 Google Ads accounts under our management. Ships with the four-query GAQL preflight we ran, a scored readiness rubric, and a machine-readable appendix built for your AI agent.
- [Ask Your Agency Which AI Price It Is Paying](https://choice.marketing/blog/ai-downgrade-test/): AI at last year's capability is 280 times cheaper than it was. AI at this year's capability is sold by spend cap and waiting list. Your agency buys both, and routing decides whether the saving reaches you. Whether the numbers in your report are real is a separate question: the worst fabrication we caught came from the flagship model. One test sorts every task into the right tier, and four questions tell you which tier your fee covers.
- [A Publishable Study Is Sitting Unclaimed in the AI Safety Debate](https://choice.marketing/blog/unclaimed-study-ai-danger-capability/): Everyone has an opinion on whether calling an AI dangerous makes it look more capable. Nobody has tested it. The adjacent literatures are strong, the manipulation is trivially cheap, and the obvious design has a confound that would sink it. The question, the surrounding evidence, the study that would settle it, and the four ways it goes wrong.
- [The Settings Screen Is Gone. The Setup Work Isn't.](https://choice.marketing/blog/ai-configuration-migrated/): AI tools deleted visible configuration, and the setup work moved where buyers cannot see it. The 2026 tooling market ran the experiment at full scale: easy to try, easy to cancel, and billing units that admit nobody has settled what AI value costs. We built the chain that measures conversions from AI, and we publish our own numbers, zeros included.
- [SEO Didn't Die. It Split in Two.](https://choice.marketing/blog/seo-split-in-two/): Search split into two measurable jobs. Ranking decides which page a human visits. Citation decides which passage an AI system trusts as evidence inside its answer, and as of 2026 the two are scored on separate reports. This is the map of both scoreboards: crawler access, evidence writing, local entity consistency, and honest measurement, with each lever pointed at the piece that owns it.
- [Citation Share Is Not Market Share](https://choice.marketing/blog/citation-share-not-market-share/): Citation Share will be the most misread number in marketing this year, and Microsoft says so in its own documentation. Added to Bing's AI Performance report on June 16, 2026, it shows the percentage of citations that point to your site out of every citation shown for the same grounding query. Microsoft states plainly that it is observational: not a ranking system, not a competitive scoreboard, not traffic share, and not a quality score. Here is exactly what it counts, the four things it does not mean, and how to watch it move without overreacting.
- [Ask Your Developer These 3 AI-Crawler Questions](https://choice.marketing/blog/ai-crawler-access-questions/): A page can be crawled by AI bots, indexed by search engines, and still never appear in an AI answer, because crawled, indexed, and cited are three separate states. The most common reason a business is missing from ChatGPT, Copilot, Perplexity, and Google's AI answers is a technical block, not weak content: a robots.txt line, a CDN toggle, a stray noindex, or JavaScript-only text quietly blocking the AI search crawlers. You do not need to read the config to catch it. Three questions to whoever built your site surface the problem fast.
- [One Click, a Thousand Copies: How Advertising Technology Actually Tracks You](https://choice.marketing/blog/one-click-a-thousand-copies/): A single ad click sets off pixels, real-time bidding auctions, hashed-email matching and server-side pipelines that survive clearing your cookies entirely. Regulators in the EU, UK, Canada and US have each ruled against parts of this system: Belgian courts found the ad-auction consent string itself is personal data, and the FTC fined BetterHelp $7.8 million and GoodRx $1.5 million for leaking health data to advertisers. This post walks through the machinery in plain language, one stage at a time.
- [Stop Writing Marketing Copy. Start Writing Evidence.](https://choice.marketing/blog/write-evidence-not-marketing-copy/): Marketing copy is written to persuade a person. Evidence is written so a machine can lift one paragraph and stand behind it. AI answer engines do not choose pages, they choose passages, so every paragraph you want cited has to pass five tests: completeness, freshness, authority, attribution, and entity clarity. Here are the five questions to ask of every important paragraph before you publish.
- [The Local Business Checklist for Showing Up in AI Answers](https://choice.marketing/blog/local-business-ai-answers-checklist/): Local businesses have a second grounding layer that page copy alone never reaches: the entity facts an AI system reconciles from your listings, your site's structured data, and third-party directories before it decides whose facts to trust in a location answer. Microsoft says a Bing Places listing keeps your key details eligible for inclusion in AI-generated responses. Conflicting or missing facts across your profiles give an AI system a reason to skip you. This is the checklist that makes your business's facts consistent, complete, and machine-readable.
- [Your About Us Page Is Costing You Customers](https://choice.marketing/blog/about-us-page-rewrite-ai/): Your About Us page is the one page an AI system reads to learn who your business is, and most of them state nothing it can quote. AI answers are assembled from specific passages, not ranked pages, so a page full of mood copy gives an answer engine nothing to lift. We take four vague, real-shaped About paragraphs and rewrite each into one an AI can cite: a dentist, a contractor, an optometrist, and a law firm.
- [How to Check in 10 Minutes Whether AI Cites Your Business](https://choice.marketing/blog/check-if-ai-cites-your-business/): You can find out whether AI systems cite your business in ten minutes, for free, with no paid tool. Two outcomes most owners treat as one come apart under the test: being named in the words of an answer, and being cited as a clickable source. The audit is three moves: put your customer's real question to ChatGPT, Copilot, Perplexity, and Google's AI Overview; open two free first-party dashboards to see what those systems already did with your pages; and record the grid the same way every month. Zero data is itself an answer.
- [You Can Rank #4 on Google and Be Invisible to ChatGPT](https://choice.marketing/blog/ranking-vs-ai-citation/): Microsoft now grades websites on two separate scorecards: how well they rank in search, and how often AI systems cite them as evidence in an answer. We track the same buyer questions across Google, Google's AI answers, and ChatGPT, and the winners are different on each surface. One question we rank #4 on gets us no citation in any AI answer. This post lays out the split, the proof, and a ten-minute check for your own business.
- [The Meta Pixel Is a Liability on Canadian Healthcare Websites](https://choice.marketing/blog/meta-pixel-healthcare-canada/): US health systems have paid more than $30 million to settle claims that the Meta Pixel sent patient data to Facebook. The same pixel runs on Canadian practice websites today, and Canada's privacy commissioner has already found that sharing customer data with Meta without consent violates federal privacy law. What happened, why Alberta practices carry specific duties, how to check your site in five minutes, and what to run instead.
- [What Healthcare Practices Should Demand From a Marketing Agency in 2026](https://choice.marketing/blog/healthcare-marketing-agency-standards/): Dental and eye-care practices should judge an agency on patients booked, not traffic delivered. Five standards to demand before you sign, plus what changes for dental groups, DSOs, and optometry subspecialties.
- [When Your Customers Ask AI Who to Call, Is It You?](https://choice.marketing/blog/ai-who-to-call/): AI assistants now answer your customer's question and name one business to call. Across 28 client sites we improved rankings and earned 19% more impressions while clicks stayed flat, and AI bots read those sites 85,000+ times last month while sending 346 visits back. This post covers what AI checks before it recommends a business, and how to see what it says about yours.
- [What Agencies Should Measure Now That Google Stopped Sending Clicks](https://choice.marketing/blog/what-agencies-should-measure-now/): The definitive 2026 answer to 'what should I measure?' The click no longer anchors marketing value. This is the full metric stack we run, from AI visibility to revenue, each grounded in a primary source.
- [AI Overviews Are Eating Healthcare Search Traffic](https://choice.marketing/blog/ai-overviews-healthcare-traffic/): Clicks to one healthcare site fell 70% in 28 days while impressions rose and rankings improved. AI Overviews now answer patient questions on the results page. This post covers the mechanism, the data from three sites, and a 90-day citation playbook for dentists and optometrists.
- [The 2026 Implant Practice Operational Stack](https://choice.marketing/blog/dental-implant-pe-playbook-part-2/): Part 1 argued the operational model is the asset and the equity transfer is the packaging. Part 2 commits to the answer: the 2026 stack for an independent implant practice ships in 30 days from contract, is owned by the practice, runs around $5,000/month software, and replaces roughly $10K-$15K of monthly payroll in headcount.
- [What PE Installs at a Dental Implant Practice](https://choice.marketing/blog/dental-implant-pe-playbook-part-1/): Dr. Clark Damon's Texas implant practice joined Frontline DIS in late 2023. From the marketing analytics seat I watched the same operational stack PE-backed DSOs install go in around me. This post maps what they put in and where the value gets captured.
- [The Operating Layer: 6 Practices That Predict Website Success in 2026 (Regardless of CMS)](https://choice.marketing/blog/operating-layer-website-success/): Part 2 of 2. If your CMS isn't the predictor, what is? Six operational practices we run across 79 WordPress sites, custom Go applications, and hosted builders. Pick any platform. The operating layer is what wins.
- [The Platform Debate Is a Distraction: 7 Myths About Choosing a Website CMS in 2026](https://choice.marketing/blog/cms-debate-is-distraction/): Picking the 'right' CMS won't save a small business in 2026. We run 79 WordPress sites, 47 client reporting workspaces, custom Go applications, and hosted-builder sites in parallel. Seven myths about platform choice, and what the 2026 data actually shows.
- [Google Ads Split Into Three Businesses. Your Plan Should Too.](https://choice.marketing/blog/google-ads-business-split-in-three/): In Q1 2026 Google's three ad lines went in three directions: Search +19%, YouTube +11%, Google Network -4%. EMARKETER projects Meta will overtake Google on total ad revenue this year. Treating 'Google Ads' as one channel with one strategy is now a planning error.
- [ChatGPT Ads in 2026, Updated August: oCPC, Audiences, OAIQ Pixel](https://choice.marketing/blog/chatgpt-ads-2026-field-guide/): A planner's field guide to ChatGPT Ads, updated August 20, 2026 for the Europe expansion, the conversion-optimized objective, custom audiences, and advanced matching: auction mechanics, targeting controls, the OAIQ pixel and Conversions API, OAI-AdsBot rules, eligibility by country, what our own June test returned, and where the channel fits in a media plan.
- [ChatGPT Ads Are Live: The AI Answer Is the New Ad Unit](https://choice.marketing/blog/chatgpt-ads-new-ad-unit/): ChatGPT ads launched February 9, 2026 with sponsored placements below answers on Free and Go tiers. The targeting signal isn't a keyword; it's the entire reasoning context, and most agencies aren't built to use it.
- [7 Red Flags When Hiring an Edmonton Digital Marketing Agency (And What Actually Matters Instead)](https://choice.marketing/blog/edmonton-digital-marketing-agency-red-flags/): Seven patterns that reliably predict a bad Edmonton marketing agency engagement (broken tracking, unwatched ad spend, locked-in contracts, and vanity reports) all trace back to the same root cause: monitoring vs. reporting.
- [The Google Ads Job Changed in 2026: What We Rebuilt Across 24 Accounts](https://choice.marketing/blog/google-ads-2026-operating-model-shift/): Between 2025 and 2026 Google stopped shipping a toolkit and started shipping an operating system. The quiet commercial changes will hit Western Canadian SMBs before any AI-Overview headline does.
- [We Track Your Business Across 10 AI Platforms: What We've Found](https://choice.marketing/blog/ai-platform-tracking/): We monitor whether clients appear in responses from Google AI Overviews, ChatGPT, Perplexity, Claude, Gemini, and five other AI platforms. The numbers are small but the baseline data matters.
- [Seasonal Marketing for Trades: Managing the Construction Calendar](https://choice.marketing/blog/seasonal-marketing-trades/): Seasonal businesses waste money running the same campaigns year-round. We manage the full marketing calendar for trades clients, and one construction company saw 316% organic traffic growth.
- [From 3 Clinics to 6: Scaling Multi-Location Healthcare Marketing](https://choice.marketing/blog/scaling-multi-location-healthcare/): Multi-location healthcare marketing fails when each location competes with itself. Centralized monitoring and location-specific strategies let us scale an optometry group from 3 to 6 clinics while reducing acquisition cost by 30%.
- [How a High-Value Procedure Ad Campaign Actually Works](https://choice.marketing/blog/high-value-procedure-campaigns/): When a single dental implant case is worth $20,000-50,000, you cannot afford imprecise tracking. We grew one practice's implant revenue from $300K to $800K by building airtight attribution.
- [The Real Cost of SEO in 2026: Lessons from 30 Client Engagements](https://choice.marketing/blog/real-cost-of-seo/): SEO costs range from $1,500 to $5,000+/month depending on competitive landscape and location count. The real cost difference between agencies isn't the monthly fee.
- [Google Ads vs Meta Ads: Where to Spend Your First Dollar](https://choice.marketing/blog/google-ads-vs-meta-ads/): A law firm spending $3,000/month on Meta Ads was getting fake phone numbers and low-intent form fills. We pivoted to Google Ads targeting high-intent searchers. The question is which platform matches how your customers buy.
- [Why We Don't Charge a Percentage of Ad Spend](https://choice.marketing/blog/why-flat-fees/): Percentage-of-spend pricing incentivizes agencies to increase your spend. Flat monthly fees incentivize us to increase your results. We manage 24 Google Ads accounts on flat fees.
- [What Happens When Conversion Tracking Breaks (And Nobody Notices)](https://choice.marketing/blog/conversion-tracking-breaks/): A conversion tracking break that goes undetected for 30 days wastes an entire month of ad spend optimization. The pipeline works in four steps, breaks in five common ways, and catching it takes automated monitoring.
- [Why We Built a Single Source of Truth for Client Data](https://choice.marketing/blog/single-source-of-truth/): All performance data for all clients flows into one PostgreSQL database. Every number can be traced to the exact API response that produced it, and reports are reproducible at any time.
- [The Automation Stack: How n8n and MCP Run Our Marketing Operations](https://choice.marketing/blog/automation-stack/): A 12-person team managing 30 clients requires significant automation. We use n8n for workflow automation and MCP for AI-assisted operations, with 240+ tools across three servers.
- [What Breaks at 2 AM: Why Marketing Needs Automated Infrastructure](https://choice.marketing/blog/what-breaks-at-2am/): Marketing infrastructure breaks silently. Automated monitoring catches site errors, tracking breaks, budget overruns, and broken images in hours instead of weeks.
- [How We Monitor 60,000 Data Points a Day](https://choice.marketing/blog/how-we-monitor-60000-data-points/): Choice OMG monitors 60,000+ data points daily through four independent pipelines feeding a centralized PostgreSQL database, creating an auditable chain from raw API response to client report.
- [Enhanced Meta Lead Ads Compliance Standards](https://choice.marketing/blog/meta-lead-ads-compliance-update/): Choice OMG implemented enhanced compliance standards for Meta Lead Ads in response to updated privacy and data-handling requirements.
- [Google Ads Advertiser Verification and Transparency Update](https://choice.marketing/blog/google-ads-advertiser-verification-update/): Google expanded advertiser verification in 2025: payer name disclosure, stricter enforcement, and pricing transparency rules.
- [n8n Version 2.0 Announced: What It Means for Automation Reliability](https://choice.marketing/blog/n8n-version-2-automation-update/): n8n 2.0 focuses on structural improvements to reliability, security, and maintainability for automation workflows.
- [n8n Becomes MCP-Ready: Enabling Secure AI-Driven Automation](https://choice.marketing/blog/n8n-becomes-mcp-ready/): n8n now supports Model Context Protocol, enabling secure connections between automation workflows and AI systems.
- [Conversational Search Is Here: Is Your Schema Ready?](https://choice.marketing/blog/conversational-search-schema-ready/): Google processed over 5 trillion searches in 2025 with queries becoming longer and more conversational. Schema markup is now essential.
- [Q5: The Post-Christmas Revenue Window Most Businesses Ignore](https://choice.marketing/blog/q5-post-christmas-revenue-window/): 87% of shopping occasions end in purchase during Q5, the Dec 26 to mid-January window when most businesses pause campaigns.
- [Dependency Hell Isnt Just for Developers](https://choice.marketing/blog/dependency-hell-marketing-stack-audits/): Marketing stacks suffer the same dependency rot as code: GTM containers full of dead tags, unpatched plugins, and third-party scripts doubling page weight.
- [Competitor Monitoring Without the Enterprise Price Tag](https://choice.marketing/blog/competitor-monitoring-open-source-tools/): Build a competitor monitoring system using open source tools like Changedetection.io, Scrapy, and AI-powered analysis.
- [The End of Unlimited AI: Why Envato Retreat Signals a Market Correction](https://choice.marketing/blog/envato-ai-market-correction/): Envato slashed AI generations from unlimited to 10 per month, signaling a broader market correction for the entire SaaS industry.
## Research
- [AI Max by Default: The Verified Dossier on Google's September Auto-Upgrade](https://choice.marketing/research/google-ai-max-auto-upgrade/): Google begins converting eligible Search campaigns to AI Max on September 1, 2026, with cohort-specific defaults and an opt-out that lives in campaign settings. We verified 56 load-bearing claims against primary sources: the mechanics, the timeline, invalid-traffic rates rising while median ROAS stays flat, and Alphabet filings showing paid clicks accelerating while CPC growth slows. Six motivation theories, rated strong to weak.
- [AI Is 280 Times Cheaper and Still Rationed](https://choice.marketing/research/two-prices-of-ai/): GPT-3.5-level intelligence fell from $20 to $0.07 per million tokens in 18 months, yet every lab still caps, queues, and tiers access to its best model. We publish how Choice OMG routes work between the two prices, what each tier costs per unit of work, and the three incidents, one of them on the top model, that taught us the gate matters more than the tier.
- [Danger Talk Sells AI to Enterprises, Not to Consumers](https://choice.marketing/research/ai-danger-marketing-evidence/): The evidence splits three ways. Making AI salient to consumers reliably suppresses engagement and purchase. Safety and governance credibility measurably helps in enterprise procurement. And frontier-tier regulation is structured so that only the largest developers ever have to comply with it.
- [Edmonton Web Design Agency Performance Index](https://choice.marketing/research/edmonton-web-design-agency-performance-index/): Mobile PageSpeed Insights scores for 15 Edmonton web design and marketing agencies range from 22 to 100. Every figure below comes straight from Google's public API, dated 2026-08-10.
- [The First 90 Days With a Marketing Agency](https://choice.marketing/research/first-90-days-marketing-agency/): Google Ads shows real signal in 2 to 4 weeks. SEO shows ranking movement in months 2 to 3. If you know what each channel can honestly deliver by day 90, you can judge an agency on process before the results arrive.
- [How to Choose a Marketing Agency in Edmonton](https://choice.marketing/research/choose-marketing-agency-edmonton/): Six checks decide whether an Edmonton agency will grow your business or its own invoice: pricing model, account ownership, who does the work, contract terms, reporting, and proof, laid out below as a full working checklist.
- [AI Is Not Replacing the Web. It Is Re-routing It.](https://choice.marketing/research/ai-not-replacing-web/): AI is not replacing the internet; it is changing the route people take through it. More of the buying decision now happens before a customer ever reaches your website.
## Careers
- [Careers at Choice OMG](https://choice.marketing/careers/) - Hiring specialists in Edmonton (in-office/hybrid). Open roles: Meta Ads Specialist, Google Ads Specialist, Organic Social Audience Builder and Manager, Digital Analyst, Operations Manager. Includes how the team operates: specialists not generalists, flat fees, monitoring as infrastructure, clean handoffs, sustainable cadence.
## Contact
- Web: https://choice.marketing/contact/
- Sales: mailbox@choice.marketing
- Customer Service: support@choice.marketing
- Billing & Verification: billing@choice.marketing
- Sales: 1-877-930-0955
- Customer Service: (780) 628-2798 (existing customers)
- Billing & Verification: (780) 628-2798
- All lines support SMS/MMS
- Address: 8739 53 Ave NW, Edmonton, AB T6E 5E9, Canada
---
# Full Content
## We Audited 19 Google Ads Accounts for September's AI Max Auto-Upgrade. The Real Exposure Was One Campaign.
Google forces AI Max changes on every eligible Search campaign between September 1 and 30, 2026. We audited all 19 Google Ads accounts under our management on August 25, one week before the window: zero enabled campaigns use campaign-level broad match, 25 campaigns still carry the legacy automatically created assets setting that also triggers the forced change, and once you remove the campaigns already running AI Max, the entire forced-change path holds three campaigns. Exactly one is enabled and spending. The panic reads fleet-wide; the exposure, on a managed fleet, is one deliberate decision. The surprises sat elsewhere: paused campaigns that take the forced change silently, a competitor's brand matched by default, and an API flag that makes AI Max a package deal on 13 of our 18 enabled campaigns.
This is the audit story. The product mechanics, cohort defaults, and opt-out paths live in our [verified dossier on the September auto-upgrade](/research/google-ai-max-auto-upgrade/), and the operating manual, including the exact queries we ran, is the [AI Max Field Guide](/blog/google-ai-max-field-guide/). Figures marked ◇ are first-party, pulled from the Google Ads API v22 on August 25, 2026.
## What September changes
Two legacy configurations trigger the forced changes: campaign-level broad match and standalone automatically created assets. Google blocked creating new ones on August 3, and from September 1 through 30 it changes what remains, in place, with search term matching switched on. September 1 is the deadline to prevent the mapping. Every trade headline frames this as a fleet-wide event, so we measured what it actually touches on a fleet that gets managed weekly.
## The audit
One GAQL request per account answers the whole question. It returns each Search campaign's match-type setting, its legacy asset setting, and whether AI Max is already on, which covers both triggers and the current posture in a single pass. The four-query version, verified live and ready to paste, is in the [field guide's preflight section](/blog/google-ai-max-field-guide/); it runs read-only through the API, a script, or the AI agent that helps manage your account.
## What 19 accounts actually look like
◇ The posture on August 25:
- **Campaign-level broad match: zero enabled campaigns.** The setting exists on two paused campaigns fleet-wide. Years of match-type discipline mean the loud trigger is simply absent.
- **Legacy automatically created assets: 25 campaigns still opted in.** This is the live trigger, and most of the 25 are paused historical campaigns nobody looks at.
- **14 campaigns already carry the AI Max flag.** Two are enabled: our own agency campaign and our own vehicle-wraps campaign, both deliberate tests on our own money.
- **The remaining forced-change path holds 3 campaigns, and exactly 1 is enabled and spending:** a client location campaign that did $1,199.20, 284 clicks, and 22 conversions in the last 30 days. That single campaign is the entire September decision for this fleet, and it gets made deliberately, against the readiness gates, before the window opens.
- **Context for what expansion has to beat:** across all 19 accounts in the last 30 days, keyword-attributed Search spend split 55.3% phrase, 32.5% exact, and 12.3% broad. The baseline is precision that already converts.
## Three findings we did not expect
**Paused campaigns are the quiet risk.** The migration language does not exempt them, and 25 mostly-paused campaigns carry the trigger here. A paused campaign takes the forced change silently in September and wakes up months later carrying AI Max settings nobody chose. Audit everything, not just what is spending.
**Competitor conquesting happened by default.** On our wraps campaign, the served-combinations report shows AI Max matched a local competitor's brand name twice, with no keyword and no setting we chose. The report that catches it, `ai_max_search_term_ad_combination_view`, shows every expansion down to the term, the headline, and the landing page, and almost nobody pulls it. Brand exclusions are a decision you make, not a default you inherit.
**AI Max is a package deal on most of our fleet.** ◇ The flag `bundling_required` reads REQUIRED on 13 of our 18 enabled Search campaigns, which means component settings like text customization cannot hold without the campaign-level umbrella. Containment on those campaigns lives at the ad-group and list level, and knowing that before September beats learning it after.
## What we are doing before September 1
1. The one exposed campaign gets a deliberate decision this week, scored against the [seven readiness gates](/blog/google-ai-max-field-guide/), instead of a default it would inherit on September 1.
2. Every account gets a calendar entry for early October: re-run the posture query, diff it against the August 25 output, and pull the change history to see exactly what the migration wrote. The change-history query has a 30-day lookback, so the audit has to happen inside the window that matters.
3. The two first-party AI Max tests keep their weekly served-combinations review. Five impressions of expansion took minutes to inspect; the habit exists for the day it takes hours.
## Run it on your account
The audit costs one query per account and an hour of attention, and the alternative is Google making the decision for you on September 1. The [field guide](/blog/google-ai-max-field-guide/) carries the paste-ready queries, the readiness scorecard, and a machine-readable appendix your AI agent can lift whole; the [dossier](/research/google-ai-max-auto-upgrade/) documents the mechanics against 66 dated sources. Both were built from the audit this post describes.
---
## The AI Max Field Guide: What Google Gets to Decide, and What It Has to Earn
AI Max is not one decision. It is three: whether Google may expand your queries, whether it may write your ad text, and whether it may pick your landing pages. Each is a separate grant of decision-making with its own controls and its own failure modes, and from September 1, 2026 Google makes the first grant for you on any Search campaign still running campaign-level broad match or legacy automatically created assets. We audited all 19 Google Ads accounts under our management on August 25: zero enabled campaigns use campaign-level broad match, 25 campaigns still carry the legacy asset setting, and exactly one enabled, spending campaign sits in the auto-conversion path. This guide covers the placement spectrum we use (A, expansion engine, through B, precision defense), the seven gates a campaign passes before it earns more automation, and what AI Max actually served on our own accounts. It closes with the four GAQL queries that reproduce our audit on any account and a machine-readable appendix your own AI agent can lift whole.
The mechanics of the September migration itself (cohorts, timeline, opt-outs, and six theories of Google's motivation, verified against 66 dated sources) live in the companion dossier, [AI Max by Default: The Verified Dossier on Google's September Auto-Upgrade](/research/google-ai-max-auto-upgrade/). This piece is the operating manual.
## Evidence legend
- ● **Verified fact.** A documented product mechanic, confirmed against the cited Google page on the access date.
- ■ **Company claim.** Google's own performance number, published without disclosed methodology.
- ◆ **Independent measurement.** Third-party data with a named method and sample.
- ◇ **First-party data.** Measured on accounts under our management, pulled from the Google Ads API on August 25, 2026.
- △ **Inference.** Our reading of the evidence. Could be wrong.
## One toggle, three grants of decision-making
● AI Max is an optimization layer inside existing Search campaigns, not a campaign type. Google's setup page states it plainly: "AI Max isn't a new campaign type but an optimization layer within existing Search campaigns." The layer bundles search term matching with asset optimization, and asset optimization contains text customization and final URL expansion. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), accessed August 25, 2026)
Each component is a distinct grant:
1. **Search term matching: the query grant.** ● With it on, "all keywords are treated as broad match by default unless search term matching is disabled at the ad group level," and Google adds keywordless expansion from your landing pages on top. ([Google Ads API AI Max guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026)
2. **Text customization: the copy grant.** Google generates headlines and descriptions from your site, existing ads, and keywords. ● Generated assets are marked "Google AI" in the Added by column and can be removed, though not in bulk inside the interface. ([Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), accessed August 25, 2026)
3. **Final URL expansion: the destination grant.** Google selects landing pages beyond your final URLs. This turns your website into a targeting feed, which is why the site audit gate below exists.
● The grants are configurable but not fully independent: "In order to use the Final URL expansion setting, Text customization must be selected. Deactivating text customization automatically disables Final URL expansion." ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), accessed August 25, 2026)
● Google's own migration defaults treat the components separately, which is useful precedent for treating them as separate decisions: a campaign-level broad match campaign converts with search term matching on and text customization off, while a legacy ACA campaign converts with search term matching on and text customization on. Final URL expansion stays off for both. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
## The controls map
Every control has a level, and the level decides who can contain a problem when one appears. ● All rows sourced from [Google's How AI Max works page](https://support.google.com/google-ads/answer/15910187?hl=en) and the [API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), accessed August 25, 2026.
| Control | Level | Note |
|---|---|---|
| AI Max umbrella | Campaign | `campaign.ai_max_setting.enable_ai_max` in the API |
| Search term matching | Ad group | On by default when the umbrella turns on; disable per ad group via `disable_search_term_matching` |
| Text customization | Campaign | Turning it off also kills final URL expansion |
| Final URL expansion | Campaign | Requires text customization |
| Brand inclusions | Campaign and ad group | Ad-group inclusions override campaign inclusions |
| Brand exclusions | Campaign | |
| URL inclusions | Ad group | Defines an allowed subset of the site |
| URL exclusions | Campaign | |
| Locations of interest | Ad group | |
| Negative keywords | Unchanged | Still honored under AI Max |
● One flag almost nobody discusses: `bundling_required`. The API documents it as the way to "determine if AI Max for Search campaigns must be enabled to respect or modify text customization and brand list controls." On a campaign where it reads REQUIRED, you cannot hold those component settings without the umbrella. ◇ It reads REQUIRED on 13 of our 18 enabled Search campaigns, so for most of our fleet AI Max is a package deal at the campaign level and the real containment tools are the ad-group and list controls above.
## September makes the first grant automatic
From September 1 through 30, Google converts every Search campaign still using campaign-level broad match or standalone automatically created assets into AI Max, in place, with the asymmetric defaults described above. Creation of new legacy configurations was already blocked on August 3. September 1 is the deadline to prevent the automatic mapping; under current documentation the AI Max settings themselves remain changeable after conversion. The full mechanics and opt-out paths are in [the dossier](/research/google-ai-max-auto-upgrade/).
Eligibility on real accounts, measured the week before the window, looks nothing like the headlines suggest. ◇ Across the 19 Google Ads accounts under our manager account, on August 25, 2026:
- **Zero of 18 enabled Search campaigns use campaign-level broad match.** The setting exists on 2 paused campaigns fleet-wide.
- **The live trigger is the other one: legacy automatically created assets.** 25 campaigns still carry ACA opted in, and most of them are paused historical campaigns nobody looks at.
- **14 campaigns already carry the AI Max flag**, 2 of them enabled: our own agency campaign and our own wraps-shop campaign, both deliberate tests on our own money.
- **The remaining auto-conversion path holds 3 campaigns, and exactly 1 is enabled and spending**: a client location campaign that did $1,199.20, 284 clicks, and 22 conversions in the last 30 days. That one campaign is the entire September decision for this MCC, and we are making it deliberately before the window opens.
△ The migration language does not exempt paused campaigns, so the quiet risk in managed accounts is the paused campaign that converts silently in September and wakes up months later carrying AI Max settings nobody chose. Sweep everything, including what is not currently spending.
## The spectrum: from expansion engine to precision defense
The strongest AI Max campaign is the one that gives Google the widest decision space the advertiser can safely measure, govern, and fund. Fit for expansion is what the spectrum measures, and enthusiasm for automation is what it deliberately ignores. We place every Search campaign at one of six positions:
| Position | Strategy | Search term matching | Text customization | Final URL expansion | Best fit |
|---|---|---|---|---|---|
| **A** | Full expansion engine | On across eligible ad groups | On | On | Trustworthy value signals, scalable economics, deep accurate site, broad demand, strong monitoring |
| **A2** | Controlled expansion | On across selected ad groups | On | Off | Strong matching and copy opportunity, but destinations must stay fixed |
| **M1** | Matching-led expansion | On in selected ad groups | Off | Off | Mature creative and approved pages, but under-covered or conversational query demand |
| **M2** | Creative assist | Off | On | Off | Known query universe, weak or neglected ad copy coverage, stable claims |
| **B2** | Contained experiment | On in one defined treatment | Usually off at first | Off | A readiness concern exists, but so does a measurable hypothesis |
| **B** | Precision defense | Off | Off | Off | Brand defense, regulated copy, fixed demand, dirty measurement, or hard capacity limits |
Campaigns earn their way toward A through controlled component tests. Nothing starts at A because the umbrella toggle exists, and nothing is stranded at B forever if the gates below start passing.
## The seven gates
A campaign passes gates to move up the spectrum. Record evidence at each one, not just a yes.
**Gate 1: Measurement integrity.** AI Max optimizes to the conversion signals it receives, and it cannot tell a valuable customer from a junk form fill unless your account sends that distinction back. Are qualified outcomes imported? Does value reach Google before most optimization decisions are made? Are spam, duplicate, and unserviceable leads excluded or devalued? Green means qualified value flows reliably: the campaign may move toward A. Yellow means partial or lagging feedback: stay in the middle positions. Red means bidding runs on raw form counts: stay near B until measurement is repaired.
**Gate 2: Economic room.** Expansion only pays when the business can absorb more qualified demand at similar margin. Hard capacity limits, mixed-margin catalogs, and defense-only objectives all argue for B-side positions regardless of how good the data looks.
**Gate 3: Query opportunity.** Expansion needs somewhere to expand into. If valuable demand hides in long-tail, conversational, or emerging queries your keyword set misses, search term matching has a job. If the existing keywords already cover the profitable demand, the grant buys risk without upside.
**Gate 4: Creative tolerance.** Could a generated headline misstate price, eligibility, location, or offer terms? Who removes an inaccurate asset, and how fast? The hard-stop question: if a generated ad could create legal, patient-safety, or severe brand risk, why is text customization on at all?
**Gate 5: Site fitness.** Final URL expansion treats the website as a feed, so audit it like one before enabling it. Old offers, thin pages, careers pages, staging content, and unserviceable location pages are all destinations Google can pick unless exclusions cover them.
**Gate 6: Brand, geography, and policy.** Decide own-brand treatment, competitor treatment, and jurisdiction limits as business rules, and encode them as brand lists, negatives, and location controls with a named owner.
**Gate 7: Governance.** Someone must check settings after launch and after migration, review queries, assets, and landing pages on a cadence, and hold rollback authority. If nobody can observe and act on the additional degrees of freedom, do not grant them.
### The scorecard
Score every gate 0, 1, or 2: fails, partial, or passes with recorded evidence. Fourteen is the maximum, and the total maps to a starting position on the spectrum:
| Score | Starting position |
|---|---|
| 12 to 14, no gate at 0 | Trial A2, and graduate toward A on account-level evidence |
| 8 to 11 | M1 or M2, single-component tests only |
| 4 to 7 | B2, one contained experiment with a written hypothesis |
| 0 to 3 | B, and fix the failing gates before granting anything |
Two overrides beat any total. Gate 1 at 0 caps the campaign at B no matter what else passes, because every grant downstream would optimize to signals that are wrong. And a Gate 4 hard-stop keeps text customization off at any score, because no conversion lift prices a compliance incident correctly.
## What the independent record shows
The public evidence splits, and it splits along lines the spectrum predicts.
- ■ Google's April 2026 material reports the full AI Max suite produced 7% more conversions or conversion value at similar CPA or ROAS than search term matching alone, from internal non-Retail data with no disclosed sample size, test length, or significance method. ([Google](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026)
- ◆ Smarter Ecommerce measured a median 13% increase in conversion value, a median 16% increase in CPA, and a median ROAS difference of 0% across more than 250 retail Search campaigns. Scale went up; efficiency did not. ([Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026)
- ◆ Location3 ran AI Max as Google Experiments across five locations of one home-services franchise brand from December 1, 2025 to January 31, 2026 and reported conversion lifts between +97% and +720%, with CPA flat to improved 63% depending on location. ([Location3](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026)
- ◆ Brad Geddes of Adalysis found "AI text customization wasn't as effective as human management of assets for highly optimized campaigns," while "AI performed quite well for the long-tail campaign" where human optimization had been limited. His B2B test lost audience qualification badly enough that the company "stopped the tests and went back to pinning its ads" after three weeks. ([Search Engine Land](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026)
- ◆ Lunio's classifier put AI Max invalid-traffic rates at 2.46% in Q4 2025, 4.01% in Q1 2026, and 5.28% in Q2 2026 across about 49.5 million AI Max clicks, while standard Search ended Q2 2026 at 3.07% in the same analysis. Traffic quality needs its own monitoring line, separate from CPA. ([Lunio](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026)
△ Read together: expansion helps where coverage was weak (franchise locations, neglected long-tail ad groups) and struggles where humans already optimized hard (mature retail portfolios, pinned B2B copy). That is a component-fit story, and it is why the placement question beats the adoption question.
## What AI Max served on our own money
We run AI Max deliberately on two first-party campaigns, so we can watch the grants exercise themselves without a client's budget in the blast radius. ◇ Both readings are from the Google Ads API's `ai_max_search_term_ad_combination_view`, the report that shows exactly which search term, headline, and landing page AI Max combined, over the last 30 days as of August 25, 2026.
**On our agency account's Search campaign** (AI Max on, text customization on): 1,346 impressions, 36 clicks, $115.32 in spend, and the combination report recorded zero AI Max combinations. △ On a tightly themed campaign with full keyword coverage, the expansion engine found little room; low-volume rows can also sit below search-terms reporting thresholds, so we read this as minimal expansion.
**On our vehicle-wraps campaign**, the report recorded 4 combinations totalling 5 impressions and 0 clicks, and all four are instructive:
- The query **"billboard sign"** was served the headline "Serving Edmonton & Area" and landed on the fleet decals page. Billboard intent, decals destination: an off-catalog match a keyword plan would never have made.
- The query **"nd graphics edmonton"**, a local competitor's brand, matched twice with headlines "Edmonton Vinyl Lettering | Edmonton Pros Since 2010" and "Vehicle Wraps & Vinyl Graphics | Edmonton Truck Wraps & Decals". Competitor conquesting happened by default, which means brand exclusions are a decision you make, not a default you inherit.
- The query **"work van decals"** matched cleanly to the truck-wraps page with "Free Wrap Consultation | Professional Vehicle Branding". This is the grant working as sold.
Five impressions decide nothing about performance. What they demonstrate is the operating surface: every expansion is inspectable down to the term, the headline, and the URL, and the review takes minutes when the campaign is small and hours of triage when it is not. Build the review habit before the volume arrives.
◇ For context on where our fleet earns its results today: across all 19 accounts in the last 30 days, keyword-attributed Search spend split 55.3% phrase, 32.5% exact, and 12.3% broad. △ Expansion has to beat a precision baseline that already converts, which is exactly why it gets granted per campaign, per component, on evidence.
## The operating rhythm
Four reports carry the whole monitoring load, and all four exist today.
1. **Search terms, filtered to match type "AI Max", with the Source column added.** ● This is Google's documented path for inspecting expanded traffic. Log spend share, not just term counts, because low-volume queries stay hidden under the standard privacy threshold. ([Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), accessed August 25, 2026)
2. **Assets, filtered to "Google AI" in the Added by column.** Review generated text against your claims inventory; remove anything that misstates the offer.
3. **Landing pages, with the Selected by column.** ● The column indicates when final URL expansion picked the page. Compare chosen pages against your approved set.
4. **Lead quality, from your own CRM.** Volume without qualification is the failure mode the platform cannot see unless you send it back.
Cadence: check settings the day after launch or migration, review weekly through the first month, then settle to the cadence traffic justifies. Set rollback triggers in advance: a generated claim error, an unsafe landing page, brand leakage past an agreed share, or invalid-lead rates past an agreed line each trigger the relevant grant's revocation, not a debate.
## Failure modes worth naming
- **Irrelevant expansion:** matched demand you cannot serve or do not want, caught in the Source-labeled terms report.
- **Generated claim errors:** copy that misstates price, eligibility, or geography, caught in the Added by report and removed by a named owner.
- **Unsafe destinations:** traffic sent to pages that were never meant to sell, prevented by URL exclusions and caught by Selected by.
- **Brand leakage:** brand and competitor traffic blurring nonbrand results, prevented by brand lists and separate brand reporting.
- **Invalid traffic:** the Lunio numbers above; watch it as its own line.
- **False attribution:** a campaign claiming conversions another campaign would have won anyway. Evaluate at account level, and treat reattribution as noise, not growth.
## Graduation rules
- A campaign moves toward A only on evidence of account-level incremental qualified value from a controlled test, one component at a time.
- ● The testing tooling is improving on schedule for the migration: Google announced multi-campaign A/B experiments rolling out in September 2026, alongside Performance Planner support for previewing bidding and budget changes. ([Google](https://blog.google/products/ads-commerce/ai-max-testing-planning-tools/), published August 20, 2026)
- A campaign retreats toward B the moment a rollback trigger fires, and re-earns the grant with a fixed gate, not a memory of the incident.
- When a test is inconclusive, the component stays off. The burden of proof sits with the automation, because the precision baseline is already paying the bills.
## The preflight: four queries that audit any account
Every field name in this guide is queryable, and the four requests below are the ones we ran for the fleet audit above, each verified against Google Ads API v22 on real accounts on August 25, 2026. All four are read-only. Run them through the API, a script, or the agent that helps manage your account; the interface shows the same facts, but the API names are exact and the output diffs cleanly week to week.
◇ **1. September eligibility and current posture, one row per Search campaign.** `BROAD` under `keyword_match_type` marks the campaign-level broad match cohort. `TEXT_ASSET_AUTOMATION` at `OPTED_IN` marks the legacy ACA cohort. `enable_ai_max` shows what already converted or opted in, and `bundling_required` at `REQUIRED` tells you the component settings cannot hold without the umbrella.
```sql
SELECT campaign.id, campaign.name, campaign.status,
campaign.keyword_match_type,
campaign.asset_automation_settings,
campaign.ai_max_setting.enable_ai_max,
campaign.ai_max_setting.bundling_required
FROM campaign
WHERE campaign.status != 'REMOVED'
AND campaign.advertising_channel_type = 'SEARCH'
```
**2. Ad-group opt-outs on campaigns already running AI Max.** An ad group whose row comes back without the flag has search term matching active: the API omits unset fields rather than returning false.
```sql
SELECT ad_group.id, ad_group.name,
ad_group.ai_max_ad_group_setting.disable_search_term_matching
FROM ad_group
WHERE campaign.ai_max_setting.enable_ai_max = true
```
**3. Every combination AI Max served: the term, the headline, and the landing page.** The competitor-conquesting example above came out of this report. It is the single most useful monitoring surface AI Max has, and almost nobody pulls it.
```sql
SELECT ai_max_search_term_ad_combination_view.search_term,
ai_max_search_term_ad_combination_view.headline,
ai_max_search_term_ad_combination_view.landing_page,
metrics.impressions, metrics.clicks
FROM ai_max_search_term_ad_combination_view
WHERE segments.date DURING LAST_30_DAYS
```
**4. Who changed what during the window.** `client_type` and `user_email` separate your team's changes from rule-based, API, and Google-initiated ones, which is how you confirm what the migration wrote to your account. Three traps, all hit live: `change_event` rejects relative ranges like `DURING LAST_30_DAYS`, requires a `LIMIT`, and refuses start dates more than 30 days back (the error is `START_DATE_TOO_OLD`). Schedule this audit inside the month it matters.
```sql
SELECT change_event.change_date_time, change_event.change_resource_type,
change_event.changed_fields, change_event.client_type,
change_event.user_email
FROM change_event
WHERE change_event.change_date_time >= '2026-09-01'
AND change_event.change_date_time <= '2026-09-30'
ORDER BY change_event.change_date_time DESC
LIMIT 200
```
## The September checklist
1. **Inventory eligibility across every account you touch.** Preflight query 1 returns both triggers and the current posture in one pass per account. Keep the output: it is the before picture your post-migration verification diffs against.
2. **Decide per campaign before September 1.** Three honest options: adopt deliberately with the settings you choose, remove the legacy setting to stay out of the mapping, or let the migration run with a calendar entry to verify the result. Choosing nothing is choosing the third option without the calendar entry.
3. **Sweep paused campaigns too.** They carry eligible settings into the window and convert without anyone noticing.
4. **After conversion, verify the defaults landed as documented** for your cohort, check ad-group search term matching flags, and run the first weekly review immediately.
5. **Keep the change history.** Preflight query 4 distinguishes changes made by your team, by rules, by the API, and by Google. The migration writes to your account; your audit trail should say so.
## The bottom line
The wrong question is whether AI Max works. The useful question is which decisions Google may make for this campaign, under what constraints, and what evidence must exist before it gets more freedom. A-side campaigns turn trustworthy signals, deep sites, and scalable economics into incremental value. B-side campaigns protect precision, message control, and capacity limits that expansion would damage. Everything in between is component-level testing with named owners and rollback triggers: ordinary account management, run on evidence.
## The appendix your agent can read
A growing share of Google Ads accounts are watched by AI agents, and a guide only humans can use is half a product. The block below encodes this guide's operating facts in a form an agent can lift whole: paste it, together with the four preflight queries, into the context of whatever tool helps run your account. It asserts nothing the sections above did not already source, and it separates verified product mechanics from our own operating framework, which your agent should feel free to disagree with.
```yaml
# AI Max operating facts
# Source: https://choice.marketing/blog/google-ai-max-field-guide/
# Mechanics verified against Google documentation and Google Ads API v22, 2026-08-25.
# --- verified product mechanics ---
migration:
window: 2026-09-01 to 2026-09-30
triggers: [campaign_level_broad_match, legacy_automatically_created_assets]
legacy_creation_blocked_since: 2026-08-03
converted_defaults:
broad_match_cohort: {search_term_matching: on, text_customization: off, final_url_expansion: off}
aca_cohort: {search_term_matching: on, text_customization: on, final_url_expansion: off}
paused_campaigns: no exemption documented (our inference), sweep them too
api_fields:
umbrella: campaign.ai_max_setting.enable_ai_max # campaign level
bundling: campaign.ai_max_setting.bundling_required # REQUIRED = components need the umbrella
broad_trigger: campaign.keyword_match_type # BROAD = campaign-level broad match
aca_trigger: campaign.asset_automation_settings # TEXT_ASSET_AUTOMATION + OPTED_IN
stm_opt_out: ad_group.ai_max_ad_group_setting.disable_search_term_matching
served_combinations: ai_max_search_term_ad_combination_view # search_term, headline, landing_page
change_audit: change_event # explicit date range + LIMIT required, 30-day lookback max
component_rules:
final_url_expansion_requires: text_customization
search_term_matching_default: on when the umbrella enables, disable per ad group
negative_keywords: honored unchanged
monitoring_reports:
- search terms filtered to match type "AI Max", with the Source column
- assets filtered to "Google AI" in the Added by column
- landing pages with the Selected by column
- CRM lead quality compared against platform-reported conversions
# --- Choice OMG operating framework ---
placement_spectrum:
A: {stm: on, tc: on, fue: on, use: full expansion engine}
A2: {stm: on, tc: on, fue: off, use: controlled expansion}
M1: {stm: on, tc: off, fue: off, use: matching-led expansion}
M2: {stm: off, tc: on, fue: off, use: creative assist}
B2: {stm: one ad group, tc: off, fue: off, use: contained experiment}
B: {stm: off, tc: off, fue: off, use: precision defense}
readiness_gates: [measurement_integrity, economic_room, query_opportunity,
creative_tolerance, site_fitness, brand_geo_policy, governance]
scoring:
scale: 0-2 per gate, 14 max
bands: {12-14: trial A2, 8-11: M1 or M2, 4-7: B2, 0-3: B}
overrides:
- gate 1 (measurement) at 0 caps placement at B regardless of total
- gate 4 (creative risk) hard-stop keeps text_customization off at any score
rollback_triggers: [generated_claim_error, unsafe_landing_page,
brand_leakage_past_agreed_share, invalid_lead_rate_past_agreed_line]
```
If a field name in the appendix stops resolving, the API version moved; check the source date above against Google's current release notes before trusting the rest.
## Sources checked for this guide
All Google Help Center pages accessed August 25, 2026.
- [Google, AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en)
- [Google, How AI Max works](https://support.google.com/google-ads/answer/15910187?hl=en)
- [Google, AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en)
- [Google Ads API, AI Max for Search campaigns](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026
- [Google Ads Developer Blog, migration announcement](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026
- [Google, AI Max testing and planning tools](https://blog.google/products/ads-commerce/ai-max-testing-planning-tools/), published August 20, 2026
- [Google, AI Max upgrade announcement](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026
- [Smarter Ecommerce, AI Max guide](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026
- [Location3, AI Max franchise results](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026
- [Search Engine Land, Geddes AI Max copy test](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026
- [Lunio, AI Max invalid traffic rates](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026
- [Choice OMG, AI Max auto-upgrade dossier](/research/google-ai-max-auto-upgrade/), published August 25, 2026
- First-party account data: Google Ads API v22, MCC sweep of 19 accounts, August 25, 2026
---
## AI Max by Default: The Verified Dossier on Google's September Auto-Upgrade
Google converts every eligible Search campaign to AI Max between September 1 and September 30, 2026. Eligible means the campaign still uses the campaign-level broad match setting or legacy automatically created assets; the conversion happens in place with different defaults per cohort, and creation of new legacy configurations was already blocked on August 3. September 1 is the deadline to prevent the automatic mapping; the AI Max settings themselves can still be changed after conversion under current documentation. The independent evidence is mixed. Smarter Ecommerce measured a median 13% increase in conversion value with a median ROAS difference of 0% across more than 250 retail campaigns; Lunio measured AI Max invalid-traffic rates rising from 2.46% to 5.28% over nine months while standard Search ended at 3.07%; and Alphabet's filings show paid clicks accelerating (6% growth in 2025, then 13% in each of Q1 and Q2 2026) while CPC growth slows (7%, then 5%, then 3%). This dossier verifies the mechanics, the exact opt-out paths, the timeline of record, and six theories of Google's motivation against 66 dated sources. Every load-bearing claim was re-checked against its cited source before publication.
**Research cutoff:** August 25, 2026
**Migration window examined:** September 1 through September 30, 2026
## Evidence legend
Every claim below carries one of five marks. Hover any mark for its label.
- ● **Verified fact.** A directly documented product mechanic, dated event, filing figure, or other checkable fact.
- ■ **Company claim.** A performance or benefit statement from Google, Microsoft, or a named advertiser case study distributed by the platform.
- ◆ **Independent measurement.** A third party's analysis of observed data. Independence does not mean randomized or bias-free.
- ○ **Anecdote.** A practitioner report without enough disclosed data to evaluate causally.
- △ **Inference.** An interpretation that follows from cited facts but is not itself stated by the source.
## Research and access note
● Mechanics were checked against current Google product, developer, API, and Editor documentation. Commercial and practitioner sources were searched and extracted with the Choice OMG proxied Firecrawl service, then important pages were checked with a second web renderer where possible. Firecrawl exposed search, scrape, map, and crawl operations, but no location selector or geographic response metadata. Therefore, this dossier does not claim that any page was verified from multiple countries. LinkedIn blocked automated retrieval, so the Microsoft global-rollout item relies on accessible reporting that reproduces the announcement. Google help pages generally have no publication date; those are identified as undated and carry the August 25, 2026 access date.
● After drafting, every load-bearing claim was re-verified against its cited source: 56 claims were checked and six citation-level corrections were applied before publication, all of them in Google primary-source attribution rather than in the data. SEC filings, DOJ documents, and earnings-call transcripts were read from primary documents. Two Google developer-blog pages that block automated retrieval were verified from Wayback Machine captures of the same pages, and the dead 2014 close-variants announcement was verified from DOJ trial exhibit UPX8049.
## 1. Executive summary
1. ● The September event is a progressive in-place conversion of eligible Search campaigns, not a new campaign type and not a same-day global flip. From September 1 through September 30, 2026, Google will convert campaigns using the campaign-level broad match setting or standalone automatically created assets, now called text customization, into AI Max. Google exposed per-campaign migration timestamps in the Ads API. Creation of new legacy configurations was blocked on August 3 across the web UI, Editor, and all API versions. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
2. ● The cohort defaults are asymmetric. A broad-match-setting campaign receives search term matching on, text customization off, and final URL expansion off. An ACA campaign receives search term matching on, text customization on, and final URL expansion off. In both cases, the AI Max umbrella is enabled at campaign level, while search term matching can be controlled at ad-group level. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
3. ● Dynamic Search Ads are not part of the September 2026 conversion. Google originally announced a September 2026 DSA migration on April 15, then changed it on June 11. The current schedule is in-account pre-migration banners starting September 2026, an official reminder notification on January 15, 2027, and automatic migration from February 1 through February 28, 2027. Google's update says, “we are extending the timeline for Dynamic Search Ads sunset and auto-upgrade, which will begin in February 2027.” ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
4. ● September 1 is not the last chance to disable AI Max. Before migration, owners can prevent this specific automatic conversion by turning off the legacy feature. After conversion, the current UI permits the AI Max umbrella and each applicable sub-setting to be changed. Google does not promise that this opt-out will remain available forever, so “permanent” is not supported by public documentation. ([Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en), undated, accessed August 25, 2026; [Google AI Max setup instructions](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026)
5. ● Advertisers keep substantial controls, but the control model changes. AI Max adds campaign and ad-group brand inclusions, campaign brand exclusions, campaign URL exclusions, ad-group URL inclusions, ad-group locations of interest, negative keywords, and source-level reporting. The search terms report labels expanded traffic as match type “AI Max” and adds a Source column; the cited reporting page instructs adding the column but does not document its values, so the broad-versus-keywordless distinction should be confirmed in the live report. Low-volume queries remain hidden under Google's general search-terms privacy threshold. ([Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026; [Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026; [Google search terms report](https://support.google.com/google-ads/answer/2472708?hl=en), undated, accessed August 25, 2026)
6. ■ Google's current top-line claim is that the full AI Max suite produces 7% more conversions or conversion value at a similar CPA or ROAS than search term matching alone. Earlier launch material claimed 14% versus non-AI-Max campaigns and 27% for campaigns that had obtained more than 70% of conversions from exact and phrase match. Google identifies these as internal non-Retail data, but discloses no account count, randomization method, test duration, dispersion, or significance test. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026; [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025)
7. ◆ Third-party evidence is mixed and mostly observational. Smarter Ecommerce reported a median 13% increase in conversion value, a median 16% higher CPA, and a median ROAS difference of 0% across more than 250 retail Search campaigns. Location3 reported conversion gains in five franchise experiments. Lunio found AI Max invalid-traffic rates rising from 2.46% in Q4 2025 to 5.28% in Q2 2026 across about 49.5 million AI Max clicks, while standard Search ended at 3.07%. Each dataset has material limitations described below. ([Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026; [Location3](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026; [Lunio](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026)
8. △ Google's strongest evidence-backed rationale is adaptation to conversational, multimodal, and less keyword-shaped search. Google says people now provide more context and calls AI Max a way for advertisers to adapt. The strategic case is strong because AI Max maps a landing page, creative, intent, and controls to queries that may never resemble a purchased keyword. ([Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026; [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025)
9. △ Revenue is a plausible secondary motive, but the specific premise that paid-click growth is slowing is contradicted by the latest filings. Paid clicks grew 6% in 2025, then 13% in both Q1 and Q2 2026. CPC growth slowed from 7% in 2025 to 5% in Q1 and 3% in Q2. Management nevertheless said new systems let Google serve ads on longer searches that were previously difficult to monetize. Rating: moderate, not strong. ([Alphabet 2025 Form 10-K](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000018/goog-20251231.htm), filed February 5, 2026; [Alphabet Q1 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000048/goog-20260331.htm), filed April 30, 2026; [Alphabet Q2 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000071/goog-20260630.htm), filed July 23, 2026; [Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026)
10. ● No credible public source located for this dossier gives the share of all Search campaigns or accounts that use standalone ACA or campaign-level broad match, so the September exposure cannot be quantified responsibly. Google said half a million advertisers were using AI Max by July 2026, but that is an adoption count, not the eligible migration population. ([Alphabet Q2 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q2-Earnings-Call-2026-GgTAq7Is0z/), published July 22, 2026)
## 2. Track A: definitive mechanics
### 2.1 Per-cohort conversion table
| Legacy cohort | Effective conversion date | AI Max umbrella | Search term matching | Text customization | Final URL expansion | Level and carryover | Evidence |
|---|---|---|---|---|---|---|---|
| **Campaign-level broad match setting** | September 1 through September 30, 2026 | On, campaign | On. AI Max campaign setting is on; the operative disable control is at ad-group level | Off, campaign | Off, campaign | ● Existing campaign brand inclusions and exclusions are preserved. Google does not explicitly promise transfer of a separate learning state. Because the campaign is changed in place rather than recreated, campaign history remains associated with the campaign, but that continuity is an inference rather than an explicit migration warranty. | ● [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026 |
| **Standalone ACA, now text customization** | September 1 through September 30, 2026 | On, campaign | On. Can later be disabled per ad group | On, campaign | Off, campaign | ● Google describes the migration as mapping ACA to the equivalent text-customization setting. Existing advertiser-created RSA assets remain available and may serve with Google-created assets. Public migration documents do not say whether generated ACA asset IDs, per-asset history, or model learnings are copied or regenerated. | ● [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; [Google text customization help](https://support.google.com/google-ads/answer/11259373?hl=en), undated, accessed August 25, 2026 |
| **Dynamic Search Ads** | Not September 2026. In-account pre-migration banners start September 2026; the official reminder notification goes out January 15, 2027. Automatic migration runs February 1 through February 28, 2027 | On, campaign | On, configurable at ad group | On, campaign | On, campaign | ● Dynamic ad groups become standard ad groups; DSAs become RSAs; historical settings and data are ported; legacy URL controls are preserved. Google can create the minimum static assets using text customization. Unsupported DSA targets become read-only. Legacy DSAs may serve temporarily, then are paused and remain view-only after replacement RSAs become eligible. Google does not separately promise that the learned model state itself transfers. | ● [Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; [Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026 |
● If a campaign belongs to both September cohorts, Google's public migration table does not specify which text-customization default wins. That overlap rule is an open question, not a safe assumption. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
### 2.2 The opt-out, exactly
#### Before the September migration
| Cohort | Published UI path | Consequence | Evidence |
|---|---|---|---|
| Campaign-level broad match | Campaigns > Settings > select campaign > Broad match keywords > select **“Off: Use keyword match types”** > Save | ● Prevents this legacy setting from making the campaign eligible on that basis. Restoring original exact and phrase keyword match types is a separate edit if the old setting had already converted them to broad. Removed keywords and their historical statistics remain visible under Keyword Status > All. | [Google broad-match-setting help](https://support.google.com/google-ads/answer/13389795?hl=en), undated, accessed August 25, 2026 |
| Legacy ACA | Campaigns > Settings > select campaigns > Edit > Change automatically created assets settings > select **“Off: Use only assets I provide directly for my ads”** > Apply | ● Prevents the standalone ACA setting from making the campaign eligible on that basis. Once legacy ACA is disabled, it cannot be enabled again through the legacy experience; re-entry is through AI Max text customization. Generated assets stop serving. | [Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en), undated, accessed August 25, 2026 |
| Either cohort | Campaigns > Settings > select campaign > AI Max > enable AI Max manually, then choose sub-settings > Save | ● Replaces the impending automatic default bundle with the owner's chosen AI Max configuration. A manual enable ordinarily selects text customization and final URL expansion by default, so the owner must review all three settings rather than assume the migration defaults. | [Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026; [Search Engine Land](https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428), published August 5, 2026 |
#### After conversion
● The current Google support language is:
> “To disable AI Max, toggle to opt out of all AI Max settings.”
> “Note that re-enabling AI Max will enable the same features as they were previously set”
> “When you disable Text customization, assets will be reported as ‘Removed’ and no longer serve.”
([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026)
| Control after upgrade | Can it be changed separately? | Exact location and dependency | Does the setting persist? |
|---|---|---|---|
| AI Max umbrella | Yes | ● Campaigns > Settings > select campaign > AI Max > toggle **Optimize your campaigns with AI Max** | ● Turning it off disables all AI Max features and causes URL inclusions and exclusions to be ignored. Turning it back on restores the prior sub-setting configuration. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026) |
| Search term matching | Yes | ● Campaign-level AI Max must be on. Under Search term matching, the owner can toggle the feature for selected ad groups. The API represents this as `AdGroup.ai_max_ad_group_setting.disable_search_term_matching`. | ● The documentation describes a saved ad-group setting, not a timed pause. It can be changed again. ([Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026) |
| Text customization | Yes | ● Campaigns > Settings > AI Max > Asset optimization > deselect Text customization > Save | ● Generated assets stop serving and are reported as Removed. If final URL expansion is on, turning text customization off also turns final URL expansion off. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en) for the Removed wording; [Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en), both undated, accessed August 25, 2026) |
| Final URL expansion | Yes, while text customization is on | ● Campaigns > Settings > AI Max > Asset optimization > Final URL expansion. It cannot remain on without text customization. | ● It is a normal saved campaign setting. Public documentation does not describe any mandatory future reactivation. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026) |
△ “Permanent opt-out” is too strong. The controls survive the September conversion under today's documentation, and no automatic reactivation is announced. Google has not contracted to preserve those controls indefinitely. The defensible practitioner wording is: owners can disable the bundle or individual features after migration and leave them off under the current product, but future product retirement is uncommitted.
### 2.3 Reporting and control surface
| Surface | What advertisers get | Boundary or loss | Evidence |
|---|---|---|---|
| Search terms report | ● A Match type value of **AI Max** for expanded matching. A Source column can be added to the report, though the cited page does not document its values; verify the broad-versus-keywordless labels in the live report. A combined view associates query, matched ad-group context, headline, and landing page. | ● This does not override the general privacy threshold. Google reports only terms used by a significant number of people; low-activity terms are omitted. Grouped insights can place undisclosed terms in subthemes or “other.” | [Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026; [Google search terms report](https://support.google.com/google-ads/answer/2472708?hl=en), undated, accessed August 25, 2026 |
| Keyword reporting | ● Keywords summary totals include **Total: AI Max expanded matches** and **Total: AI Max landing page matches**. | ● When AI Max is on, an individual keyword match-type field is not the complete targeting explanation because search term matching can treat eligible keywords as broad and can operate keywordlessly. | [Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026 |
| Creative reporting | ● The asset report identifies Google-created text; expanded-final-URL assets receive a dedicated category. Individual assets can be removed. The API and Editor support bulk operations that the UI does not always expose. | ● Google-created text cannot be edited in place. Disabling text customization marks those assets Removed and stops serving them. | [Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026; [Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en) and, for the Removed wording, [Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026 |
| Landing-page reporting | ● Landing pages reports distinguish advertiser-selected and final-URL-expansion selections through **Selected by**. | ● URL inclusions and exclusions are ignored when the AI Max umbrella is off. | [Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026; [Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026 |
| Brand controls | ● Brand exclusions are campaign-level. Brand inclusions can be campaign-level or ad-group-level; an ad-group inclusion overrides the campaign inclusion for that ad group. Negative keywords continue to be honored. | ● These are list and negative controls around Google's matching, not an advertiser-readable rule set for every positive match. | [Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026; [Google AI Max FAQ](https://support.google.com/google-ads/answer/15913066?hl=en), undated, accessed August 25, 2026 |
| Locations of interest | ● Available at ad-group level to signal geographic intent beyond the user's physical location. | ● It is an AI Max search-term-matching control, not a substitute for the campaign's geographic targeting and exclusions. | [Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026 |
| URL controls | ● URL exclusions are campaign-level. URL inclusions are ad-group-level. Legacy DSA URL controls are preserved during the February 2027 conversion. | ● Final URL expansion requires text customization. URL inclusion behavior can make RSA headline pinning inapplicable in some serving paths. | [Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026; [Google AI Max FAQ](https://support.google.com/google-ads/answer/15913066?hl=en), undated, accessed August 25, 2026; [Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026 |
### 2.4 Google Ads API and legacy-field deprecation
● The current API exposes the campaign umbrella as `Campaign.ai_max_setting.enable_ai_max`, text and final-URL automation through `Campaign.asset_automation_settings`, ad-group search-term control through `AdGroup.ai_max_ad_group_setting.disable_search_term_matching`, and combined query, ad, and URL reporting through `ai_max_search_term_ad_combination_view`. `Campaign.AiMaxSetting.bundling_required` indicates whether the account must enable the suite as a bundle. Messaging restrictions allow up to 40 entries and term exclusions up to 25, with limits documented in the API guide. ([Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026)
● Migrated campaigns can be identified programmatically by selecting `campaign.aca_migration_date_time` and `campaign.broad_match_migration_date_time`; the developer post presents the fields as a way to find campaigns already migrated during the month, not as a scheduling control. The post names no API version for the fields; the v25.1 attribution rests on the release notes. ([Google Ads API release notes](https://developers.google.com/google-ads/api/docs/release-notes), updated August 19, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
● New API versions released after September 1, 2026 will omit the legacy ACA and campaign-level broad-match entities. Existing versions retain the fields until their standard sunset, which Google described as approximately September 2027. Mutating `Campaign.keyword_match_type` for an AI Max campaign is deprecated and inapplicable. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026)
● A Google FAQ that still says API and Editor support were expected later in 2025 is stale. API v21 added AI Max fields in August 2025 and Editor 2.10 added AI Max controls in July 2025. Current API documentation overrides that old FAQ sentence. ([Google AI Max FAQ](https://support.google.com/google-ads/answer/15913066?hl=en), undated, accessed August 25, 2026; [Google Ads API v21 announcement](https://ads-developers.googleblog.com/2025/08/google-ads-api-v19-release.html), published August 6, 2025; [Google Ads Editor 2.10 help](https://support.google.com/google-ads/editor/answer/16320144?hl=en), undated, accessed August 25, 2026)
## 3. Timeline of record
| Announcement or publication date | Effective date | Event | Status and source |
|---|---|---|---|
| **May 6, 2025** | Beta rollout begins later in May 2025; the launch post gives no exact date | Google announces AI Max for Search. It combines search term matching, text customization, final URL expansion, and new controls. Google also previews API support in v21. | ● [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2025/05/google-ads-ai-max-for-search-campaigns-open-beta.html), published May 6, 2025 |
| **May 26 or May 27, 2025** | Progressive product change from that date | Google's current legacy-ACA help contains both dates for when ACA began upgrading into AI Max as text customization. | ● Internal documentation inconsistency. [Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en), undated, accessed August 25, 2026 |
| **July 8, 2025** | July 8, 2025 | Google Ads Editor 2.10 adds AI Max controls. | ● [Google Ads Editor 2.10 help](https://support.google.com/google-ads/editor/answer/16320144?hl=en), undated, accessed August 25, 2026; release date corroborated by [Search Engine Land](https://searchengineland.com/google-ads-editor-2-10-458182), published July 8, 2025 |
| **August 6, 2025** | API v21 availability | Google Ads API v21 adds the AI Max campaign and ad-group settings and the combined reporting view. | ● [Google Ads API announcement](https://ads-developers.googleblog.com/2025/08/google-ads-api-v19-release.html), published August 6, 2025 |
| **April 15, 2026** | AI Max exits beta on April 15, 2026 | Brandon Ervin announces general availability and an original September 2026 migration for DSA, ACA, and campaign-level broad match. | ● [Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026 |
| **April 29, 2026** | Q1 2026 | Alphabet says more than 30% of Search customer spend uses AI Max or Performance Max and connects AI Max to conversational search. | ■ [Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026 |
| **May 13, 2026** | API v24.1 | API adds experiment types `ADOPT_AI_MAX` and `ADOPT_BROAD_MATCH`. | ● [Google Ads API release notes](https://developers.google.com/google-ads/api/docs/release-notes), entry dated May 13, 2026 |
| **June 11, 2026** | DSA conversion moved to February 2027 | Google updates its April post after advertiser feedback, leaving ACA and campaign-level broad in September 2026. | ● This is the decisive schedule change. [Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026 |
| **July 22, 2026** | Q2 2026 | Alphabet says half a million advertisers use AI Max and calls it a building block for participation in new AI experiences. | ■ [Alphabet Q2 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q2-Earnings-Call-2026-GgTAq7Is0z/), published July 22, 2026 |
| **August 3, 2026** | August 3, 2026 | Google blocks creation of new campaign-level broad-match and legacy standalone ACA configurations in the UI, Editor, and all API versions. | ● The August 12 developer post records August 3 as the effective date. [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026 |
| **August 5, 2026** | September 1 through September 30, 2026 | Google emails affected advertisers that eligible campaigns will be auto-upgraded in September and gives the disable-or-manually-enable choice. | ● The email is not available in a stable public Google archive. Two trade publications independently report it. [Search Engine Land](https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428), published August 5, 2026; [PPC Land](https://ppc.land/google-blocks-new-broad-match-settings-before-september-1-ai-max-migration/), published August 12, 2026 |
| **August 12, 2026** | September and February windows specified | Google publishes authoritative cohort defaults, creation end-of-life, API timestamps, legacy-field deprecation, and the DSA 2027 schedule. | ● [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026 |
| **August 19, 2026** | API v25.1 | Google adds the two migration timestamp fields and updates the AI Max API guide. | ● [Google Ads API release notes](https://developers.google.com/google-ads/api/docs/release-notes), updated August 19, 2026; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026 |
| **August 20, 2026** | Multi-campaign experiments start rolling out in September 2026 | Google announces expanded AI Max A/B testing and Performance Planner support. | ● [Google Ads product post](https://blog.google/products/ads-commerce/ai-max-testing-planning-tools/), published August 20, 2026 |
| **August 25, 2026** | Research cutoff | The automatic migration has not yet begun; Google's announced start is September 1. | ● Current date and announced schedule. [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026 |
| **September 1 through September 30, 2026** | Future at cutoff | Automatic ACA and campaign-level broad-match migrations run progressively. | ● Scheduled, not yet observed at the research cutoff. [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026 |
| **January 15, 2027** | Future at cutoff | Google sends the official reminder notification about the upcoming DSA migration; in-account pre-migration banners run from September 2026. | ● Scheduled. [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026 |
| **February 1 through February 28, 2027** | Future at cutoff | Automatic DSA conversion occurs; new DSA ad-group creation is permanently removed. | ● Scheduled. [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026 |
## 4. Track B: performance evidence, sorted by independence
### 4.1 Google's claims
| Claim | Population and method disclosed | Assessment |
|---|---|---|
| **7% more conversions or conversion value at similar CPA or ROAS** for the full AI Max suite compared with search term matching alone | ■ Google identifies 2026 internal non-Retail data. It does not disclose sample size, countries, dates, selection, assignment, dispersion, or statistical significance. | ■ This is the closest claim to the incremental value of text customization plus final URL expansion beyond expanded matching, but it remains unauditable. [Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026 |
| **14% more conversions or conversion value at similar CPA or ROAS** after enabling AI Max | ■ Google identifies 2025 internal non-Retail data. No sample size or experimental method is disclosed. | ■ The comparison population is described as campaigns not using AI Max, so selection effects cannot be ruled out from the published note. [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025; [Google AI Max overview](https://support.google.com/google-ads/answer/15910366?hl=en), undated, accessed August 25, 2026 |
| **27% more conversions or conversion value at similar CPA or ROAS** for campaigns that previously obtained more than 70% of conversions from exact and phrase match | ■ Same 2025 internal non-Retail source; no sample size or assignment method. | ■ This is a selected segment that might have more expansion headroom. It should not be generalized to mature broad-match campaigns. [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025 |
| L'Oréal Chile reported **2x conversion rate** and **31% lower cost per conversion**; MyConnect reported **16% more leads**, **13% lower CPA**, and **30% conversion lift** from net-new queries | ■ Named cases in Google's launch material. Account spend, test duration, counterfactual, and full outcome distributions are not disclosed. | ■ Useful for plausible mechanisms, not a population effect. [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025 |
| Hilton reported **one-third more clicks for one-fifth of the spend** and **55% higher average booking value**; Etsy reported **10% more search volume** and **15% from net-new queries** | ■ Named cases cited on Alphabet's earnings call. Methodology and sample windows are not disclosed. | ■ Investor-call examples are selected successes. [Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026 |
| AI Max or Performance Max users saw **15% more conversions or conversion value at a similar ROAS**; AAA reported **17% higher conversion volume** and **11% lower cost per lead** | ■ The first number combines two products. The call does not provide the sample or causal design; the AAA example is a selected advertiser case. | ■ Do not relabel the combined AI Max or Performance Max result as an AI Max-only result. [Alphabet Q2 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q2-Earnings-Call-2026-GgTAq7Is0z/), published July 22, 2026 |
### 4.2 Independent measurements
#### Lunio: invalid traffic
◆ Lunio compared about 114.5 million Google Search clicks over nine months, from Q4 2025 through Q2 2026: approximately 49.5 million AI Max clicks and 65.0 million standard Search clicks. It says campaigns were compared within the same customers, period, campaign type, sector, and season. AI Max's invalid-traffic rate moved from 2.46% in Q4 to 4.01% in Q1 and 5.28% in Q2. Standard Search moved from 3.72% to 2.98% to 3.07%. Lunio characterizes the ending gap as 72% higher invalid traffic for AI Max and the nine-month movement as a 114% rise for AI Max versus a 17% decline for standard Search. ([Lunio](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026)
◆ In Lunio's retail subset, AI Max's share of Search clicks rose from about 33% to 55%, and it accounted for 68% of invalid Search clicks in Q2. The broader retail report analyzed 414 million ad clicks across 88 retail accounts and multiple platforms. The AI Max comparison is the nested Search cohort, not 414 million AI Max clicks. ([Lunio AI Max analysis](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026; [Lunio retail report](https://www.lunio.ai/blog/invalid-traffic-retail-report), updated August 14, 2026)
◆ Limits: the design is observational; participating customers self-selected into AI Max; account count for the Search comparison is not stated; conversion quality is not measured; Lunio sells invalid-traffic software; and its classifier is not independently audited in the article. Like-for-like matching reduces, but cannot eliminate, selection and mix differences. A separate 2025 Lunio single-client exercise compared 404 AI campaigns with 491 controls and reported a difference-in-differences increase from a 3.7% baseline to 5%, but one client is not a market estimate. ([Lunio](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026)
#### Smarter Ecommerce, Mike Ryan
◆ Smarter Ecommerce examined more than 250 retail Search campaigns using AI Max within a base of 600 active ecommerce accounts. About 16% of those accounts were testing AI Max. The March 2026 analysis reported a median 13% increase in conversion value, a median 16% increase in CPA, and a median ROAS difference of 0%, with a reported ROAS distribution from +42% to -35%. ([Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026)
◆ Its query analysis included one million AI Max impressions and found an 80/20 concentration pattern. One account showed AI Max matches that were 49% and 63% broad; another competitor-expansion example reached effectively 100% of a comparison and 69% of total Search impressions. One Search Partners Network example contributed half of a campaign's 500,000 monthly impressions and converted at 0.07%, versus 3.04% for Google Search. ([Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026)
◆ Limits: this is campaign-versus-remaining-revenue analysis, not randomized treatment assignment; spend levels and account counts vary by section; cannibalization across campaigns is not controlled; medians hide tail outcomes; and the publisher sells Google Ads management software. A March podcast describes “conversions” where the written article specifies “conversion value,” so this dossier uses the written metric. ([Smarter Ecommerce article](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026; [Smarter Ecommerce podcast](https://smarter-ecommerce.com/en/podcast/season-4/the-end-of-dynamic-search-ads-is-here-insights-from-200-ai-max-campaigns/), published March 10, 2026)
#### Location3 franchise experiments
◆ Location3 reports Google Ads Experiments run from December 1, 2025 through January 31, 2026 across five home-services franchise locations. It says every location increased conversions. Reported conversion lifts were 97%, 720%, 318%, 410%, and 350%. CPA was slightly higher at the first location, improved 63% at the second, was approximately flat at the third, and improved 30% and 50% at the fourth and fifth. ([Location3](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026)
◆ Limits: the clients are unnamed; absolute conversions, spend, randomization, confidence intervals, and spillover controls are not reported; the sample is five locations in one vertical over two months; and the agency recommends keeping final URL expansion off for tightly local campaigns. These are favorable experiments with limited external validity. ([Location3](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026)
#### Adalysis-guided creative tests reported by Brad Geddes
◆ Three companies, ecommerce, B2B lead generation, and B2C lead generation, tested text customization. Each selected four non-brand campaigns, two closely optimized and two more neglected, with at least $20,000 monthly spend and at least 100 ad groups. Final URL expansion was off. Excluding the B2B case, about 19% of generated assets were removed before receiving many impressions. ([Search Engine Land](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026)
◆ Results ran in both directions. Ecommerce initially looked successful, but account revenue fell after traffic was cannibalized from other campaigns; the rerun used added keywords, negatives, and audiences. In B2B, CTR rose while conversion rate fell as ads attracted B2C users; the company stopped after three weeks, restored pins and removed generated assets, and returned to pretest performance within a week. In B2C and ecommerce, human-managed assets remained stronger in mature campaigns while automated assets helped neglected long-tail campaigns. ([Search Engine Land](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026)
◆ Limits: only three accounts, each contributing four campaigns, are described; results are mainly directional rather than numeric; the companies are unnamed; treatment assignment and confidence intervals are absent; account-level cannibalization complicated the first result; and the author co-founded a PPC software vendor. The design is still valuable because it isolates text customization by keeping final URL expansion off. ([Search Engine Land](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026)
#### Optmyzr and older broad-match context
● No qualifying Optmyzr AI Max before-and-after or controlled study was located through August 25, 2026. Optmyzr has published practitioner commentary and webinars, but not a disclosed AI Max sample comparable to the studies above. Its older match-type benchmark covered 4,000 accounts meeting tenure, spend, and non-brand criteria and found exact match ahead of broad match on ROAS, CPA, CTR, and conversion rate, with near-even CPC results. That 2024 study is component context, not evidence about AI Max. ([Optmyzr State of PPC study](https://www.optmyzr.com/blog/optmyzr-state-of-ppc-study/), published March 13, 2024; [Optmyzr 2026 webinar takeaways](https://www.optmyzr.com/blog/paid-search-2026-webinar-takeaways/), published April 20, 2026)
### 4.3 Practitioner and press reports
| Report | Direction | Evidentiary value |
|---|---|---|
| Monks paid-search director Ezra Sackett reported reviewing about 30,000 search terms across multiple client accounts. He said 99% of impressions occurred on terms with no conversions, 31% of terms had more than 25 characters, and fewer than half matched to a keyword. | Negative on query expansion | ○ The account count, spend, conversion window, comparison group, and statistical method are absent. It is a large query review, but not a causal study. [PPC Land](https://ppc.land/googles-ai-max-for-search-campaigns-deliver-meh-results-industry-tests-reveal/), published August 17, 2025 |
| Xavier Mantica reported a four-month comparison with AI Max CPA of $100.37, phrase $43.97, exact $52.69, exact close variant $61.65, and phrase close variant $97.67. | Negative on expanded matching | ○ The source does not disclose account size, spend, term counts, vertical, or controls. [PPC Land](https://ppc.land/independent-tests-show-ai-max-underperforms-traditional-match-types/), published November 8, 2025 |
| In one Reddit thread, the original poster said three months of testing still produced unrelated queries after more than 2,000 negatives. Other commenters reported 95% of terms negated, increased spend without results, competitor leakage, and one $8 click on a misspelled brand. | Negative on relevance and brand control | ○ Anonymous identities, self-selected reporting, no verified dates beyond the relative timestamp, and no reliable account sizes. [r/googleads thread](https://www.reddit.com/r/googleads/comments/1ufyx66/my_experience_using_ai_max/), displayed as two months old and accessed August 25, 2026 |
| The same Reddit thread includes a commenter claiming 24 successful experiments out of 25, another reporting lower CPC and CPA after removing cannibalized terms, and a small-account user reporting success with heavy negative cleanup and final URL expansion off. | Positive or neutral with controls | ○ No values, verified identities, experiment design, or spend levels. The opposing experiences show heterogeneity, not an average effect. [r/googleads thread](https://www.reddit.com/r/googleads/comments/1ufyx66/my_experience_using_ai_max/), displayed as two months old and accessed August 25, 2026 |
| Practitioners managing large online parts catalogs said DSA remained especially useful for part numbers and worried that conversion would remove site-structure precision. | Negative on DSA replacement control | ○ Forward-looking concern, not measured post-migration performance. [r/googleads thread](https://www.reddit.com/r/googleads/comments/1sna3lc/google_to_retire_dynamic_search_ads_in_favour_of/), displayed as four months old and accessed August 25, 2026 |
### 4.4 What the performance evidence supports
△ Evidence in favor is strongest where automation fills genuine coverage gaps: neglected long-tail campaigns, new query forms, and small local tests with disciplined URL and negative controls. The evidence against is strongest where existing campaigns already have refined creative and query governance, where B2B prequalification depends on careful wording, where competitor or partner-network traffic can expand quickly, and where account-level cannibalization makes campaign metrics look better while total revenue worsens. This synthesis follows the independent measurements above; no cited study establishes a universal average causal effect.
● Brand-safety and offer-misrepresentation risk is not only anecdotal. Google's own help warns owners to keep website content accurate and monitor generated content, while the three-account creative test removed about 19% of generated assets outside the B2B case and observed B2B audience misqualification despite messaging restrictions. Google's contrary claim is that its quality models ground assets in the advertiser's pages and offerings. ([Google text-customization help](https://support.google.com/google-ads/answer/11259373?hl=en), undated, accessed August 25, 2026; [Search Engine Land](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026)
## 5. Track C: motivations, argued from evidence
### 5.1 Revenue mechanics
**Rating: moderate**
**Supporting evidence**
- ● Alphabet reported Google Search and other revenue of **$198.084 billion in 2024** and **$224.532 billion in 2025**. It reported paid clicks up **6%** and cost per click up **7%** in 2025. The filing lists advertiser competition for keywords among the factors that affect CPC. ([Alphabet 2025 Form 10-K](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000018/goog-20251231.htm), filed February 5, 2026)
- ● For Q1, Search and other revenue was **$50.702 billion in 2025** and **$60.399 billion in 2026**. Paid clicks increased **13%** and CPC increased **5%**. ([Alphabet Q1 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000048/goog-20260331.htm), filed April 30, 2026)
- ● For Q2, Search and other revenue was **$54.190 billion in 2025** and **$63.271 billion in 2026**. Paid clicks increased **13%** and CPC increased **3%** for the quarter; for the first six months, the figures were **13%** and **4%**. ([Alphabet Q2 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000071/goog-20260630.htm), filed July 23, 2026)
- ■ Management said Google had expanded its ability to deliver ads on “longer, more complex searches” that had previously been difficult to monetize. Google also said AI Max had reached billions of net-new queries. ([Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026; [Alphabet Q4 2025 earnings call](https://abc.xyz/investor/events/event-details/2026/2025-Q4-Earnings-Call-2026-Dr_C033hS6/), published February 4, 2026)
- △ Broader and keywordless eligibility can place more advertisers into consideration for a query. More eligible bids can increase auction density, which can support price realization or monetize previously unserved inventory. The filings establish that auction competition affects CPC, but they do not isolate AI Max as the cause.
**Contradicting evidence and strongest counter-argument**
- ● The asserted premise that click-volume growth is slowing does not fit the latest period: paid-click growth rose from 6% for 2025 to 13% in each of Q1 and Q2 2026, while CPC growth slowed from 7% to 5% and then 3%. ([Alphabet 2025 Form 10-K](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000018/goog-20251231.htm), filed February 5, 2026; [Alphabet Q1 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000048/goog-20260331.htm), filed April 30, 2026; [Alphabet Q2 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000071/goog-20260630.htm), filed July 23, 2026)
- ● Alphabet attributes Search growth to more queries, advertiser spend, and ad formats and delivery. It does not disclose an AI Max contribution to CPC or Search revenue. ([Alphabet Q1 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000048/goog-20260331.htm), filed April 30, 2026; [Alphabet Q2 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000071/goog-20260630.htm), filed July 23, 2026)
**Best steelman of Google's official rationale**
△ AI Max can create incremental advertiser value and Google revenue at the same time. If conversational searches were previously hard to match or monetize, a system using intent, pages, creative, and Smart Bidding may show a relevant ad where a literal-keyword system showed none. Revenue growth would then be a consequence of product coverage rather than proof that Google designed the migration mainly to inflate CPC.
### 5.2 The AI search transition
**Rating: strong**
**Supporting evidence**
- ■ Google said, “People no longer search in fragments; they search conversationally and share more context.” The same earnings call said AI Max helps advertisers adapt to that behavior. ([Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026)
- ● Google's launch connected AI Max to AI Overviews, Lens, exploratory searches, multimodal searches, and complex queries. AI Max uses keywordless technology plus broad match, creative generation, page selection, and controls rather than relying only on a literal keyword list. ([Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025; [Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026)
- ◆ Seer analyzed 5.47 million queries, 2.43 billion organic impressions, and 296.9 million paid impressions across 53 brands from January 2025 through February 2026. Organic CTR on AI-Overview queries was 2.4% in February 2026 versus 3.2% in January 2025. Paid CTR was 16.2% for AI-Overview queries versus 21.8% for non-AI-Overview queries in February 2026. ([Seer Interactive](https://www.seerinteractive.com/insights/aio-impact-on-google-ctr-2026-update), published April 24, 2026)
- ◆ Ahrefs compared 150,000 informational keywords with AI Overviews against 150,000 without them and reported that position-one organic results were associated with a **58% lower average CTR** when an AI Overview was present. ([Ahrefs](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/), published February 4, 2026)
- ◆ SE Ranking inspected 50,032 commercial keywords in 20 niches and found text ads on 14,733, or 29.45%, of AI Mode result pages. Ad presence rose across the source's CPC bands, from 24.33% below $2 to 53.56% above $10. ([SE Ranking](https://seranking.com/blog/google-ai-mode-ads/), published July 14, 2026)
**Limits and strongest counter-argument**
- ◆ Seer's current AI-Overview label is applied retrospectively, its model does not control seasonality, and the data are observational. Ahrefs uses desktop Search Console data and different keyword cohorts. SE Ranking is a result-page snapshot, not a click or conversion study. ([Seer Interactive](https://www.seerinteractive.com/insights/aio-impact-on-google-ctr-2026-update), published April 24, 2026; [Ahrefs](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/), published February 4, 2026; [SE Ranking](https://seranking.com/blog/google-ai-mode-ads/), published July 14, 2026)
- △ Conversational query growth explains why Google wants a richer matching system, but it does not by itself justify forcing campaigns that already use ACA or campaign broad match into the AI Max umbrella. Google could have preserved the legacy switches or required explicit consent.
**Best steelman of Google's official rationale**
△ Keyword lists were designed for short, enumerable expressions of demand. AI-era search can combine constraints, context, images, follow-up turns, and product discovery. An intent and content model is structurally better suited to map those queries to ads, provided that reporting, negative controls, page controls, and creative guardrails remain usable.
### 5.3 Information asymmetry and lock-in
**Rating: moderate**
**Supporting evidence**
- ● Google's search terms report omits queries with insufficient activity under its privacy standards. Search-term insights can group queries without revealing every underlying term. AI Max also allows keywordless eligibility, so the platform's model, not an advertiser-authored positive keyword, determines part of the match set. ([Google search terms report](https://support.google.com/google-ads/answer/2472708?hl=en), undated, accessed August 25, 2026; [Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026)
- ◆ After Google's September 2020 reporting threshold change, Seer found cost visibility fell overnight from 98.7% to 71.0% and click visibility from 98.3% to 77.9%, with both holding at that level through the first seven days. The source did not disclose the client count for that comparison. ([Seer Interactive](https://www.seerinteractive.com/insights/google-ads-removes-search-terms-for-28-percent-of-paid-search-budgets), published September 2, 2020)
- ◆ A one-campaign 2025 audit reported 269 clicks, of which 131 were attached to visible search terms and 138 were not, leaving 51% of clicks and 54% of impressions hidden. ([Marlin SEM](https://marlinsem.com/google-ads-missing-search-terms/), published July 9, 2025)
- △ A campaign defined by Google's private matching, creative, and page-selection models is harder to reproduce on another network than a campaign defined by a portable list of keywords, ads, bids, and URLs. Reports expose outcomes and sources, but not the model's complete decision rule or learned state.
**Contradicting evidence and strongest counter-argument**
- ● AI Max adds, rather than removes, several controls and reports: brand inclusions and exclusions, locations of interest, URL inclusions and exclusions, source labels, and the query-ad-URL view. Negative keywords still apply. There is no sourced evidence that enabling AI Max lowers the general search-term visibility threshold relative to an otherwise identical Search campaign. ([Google AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026; [Google AI Max workings](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026; [Google AI Max FAQ](https://support.google.com/google-ads/answer/15913066?hl=en), undated, accessed August 25, 2026)
- ● Google improved privacy-compliant query reporting for searches from February 1, 2021 onward, even while later removing older terms that failed current thresholds. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2021/09/search-terms-report-improvements.html), published September 9, 2021)
**Microsoft portability**
- ● Microsoft announced an AI Max pilot in June 2026 with expanded queries, real-time creative, experiments, controls, and what it called transparent reporting. ([Microsoft Advertising](https://about.ads.microsoft.com/en/blog/post/june-2026/microsoft-advertising-activate-2026-key-takeaways-from-the-event), published June 19, 2026)
- ● Accessible reporting says Microsoft made AI Max available globally on August 20, 2026 as an optional feature with three separately controlled components. Imported Google Search campaigns can carry AI Max settings. If the source Google campaign originated as DSA, Microsoft reverts it to DSA. Legacy Microsoft autogenerated text and predictive matching are mapped without switching on unrelated features. The underlying LinkedIn announcement could not be retrieved directly. ([Search Engine Roundtable](https://www.seroundtable.com/microsoft-advertising-ai-max-41909.html), published August 20, 2026; [PPC News Feed](https://ppcnewsfeed.com/ppc-news/2026-08/microsoft-advertising-rolls-out-ai-max-globally/), published August 21, 2026)
- △ Setting import improves configuration portability, but no source says Google model learnings, query histories, or creative-selection histories transfer to Microsoft. Microsoft's DSA reverse mapping can preserve a familiar structure, while different platform models still make outcomes non-portable.
**Best steelman of Google's official rationale**
△ Some opacity is inherent in machine-learned matching, and full query disclosure can conflict with user privacy. The proper comparison is not keyword control versus no control. It is whether the added source reporting, negatives, brand rules, URL rules, and experiments give advertisers enough outcome control to manage a model whose internal features cannot be expressed as a compact keyword list.
### 5.4 The forced-migration playbook
**Rating: strong for the pattern, moderate for any claim that the pattern predicts performance or CPC**
| Precedent | Opt-in, opt-out, or mandatory | Advertiser prediction at the time | Post-change evidence located | Assessment |
|---|---|---|---|---|
| Enhanced Campaigns, 2013 | ● Mandatory conversion completed July 22, 2013. It combined desktop and tablet management and introduced mobile bid modifiers, reducing separate device-campaign control. | ○ Agencies predicted upward CPC pressure, particularly on mobile and tablet, as bidders entered previously separated auctions. | ◆ Kenshoo's June-to-August spend analysis found aggregate spend followed a similar seasonal trend to prior years; Kenshoo's separately released Q3 2013 global trend data showed CPC up 4% quarter over quarter, with 42% of clients within plus or minus 10%. The client count was not disclosed. Other early vendors reported mixed device effects. | △ The structural loss of device separation was real; the immediate aggregate CPC shock predicted by some practitioners was not cleanly demonstrated. [MarTech](https://martech.org/google-adwords-enhanced-campaigns-roll-out-slowly-broader-cpc-impact-yet-to-be-seen/), published July 26, 2013; [Digital Commerce 360 on Kenshoo](https://www.digitalcommerce360.com/2013/10/17/impact-googles-enhanced-campaigns/), published October 17, 2013 |
| Exact and phrase close variants, 2014 | ● Mandatory. Google removed the option to disable close variants starting in late September 2014. | ○ Advertisers expected weaker query precision and more negative-keyword work. | ■ Google projected about 7% more exact and phrase clicks at comparable CTR and conversion rates. No independent post-hoc market-wide study with disclosed controls was located for this change. | △ Clear precedent for absorbing an optional matching expansion into the default with no opt-out. [Google Ads blog](https://adwords.googleblog.com/2014/08/close-variant-matching-for-all-exact.html), published August 14, 2014; the live page is no longer reachable, and its full text is preserved as DOJ trial exhibit UPX8049 in U.S. v. Google (Bates USDOJ-GOOG-00187103) |
| Exact close variants, 2017 | ● Mandatory expansion to rewordings and function-word variation. | ○ Practitioners expected “exact” to become less literal and query sculpting to weaken. | ■ Google projected up to 3% more exact-match clicks while maintaining comparable CTR and conversion rate. A sufficiently disclosed independent post-hoc study was not located. | △ The change continued the direction of platform-decided semantic equivalence. [Google Ads blog](https://blog.google/products-and-platforms/products/ads/close-variants-now-connects-more-people-2017/), published March 17, 2017 |
| Phrase and broad-match-modifier same-meaning expansion, 2019 | ● Mandatory matching expansion; close variants are now eligible across all match types by default with no opt-out. | ○ Advertisers predicted query overlap, loss of intent distinctions, and more negative maintenance. | ◆ Seer's first seven days after the 2019 change showed queries per keyword up 22.73% in finance and 5.89% in education; finance CPA was up 77.8%. At 90 days, net CPA was up 7.9%. The source did not disclose account count. | △ Expansion raised reach, with short-run cost deterioration in at least one measured vertical and a smaller 90-day effect. [Search Engine Land](https://searchengineland.com/google-extends-same-meaning-close-variants-to-phrase-match-broad-match-modifiers-320138), published July 31, 2019; [Google close-variants help](https://support.google.com/google-ads/answer/9342105?hl=en), undated, accessed August 25, 2026; [Seer Interactive](https://www.seerinteractive.com/insights/bmm-phrase-match-keyword-pov), published August 2, 2019, updated November 15, 2019 |
| Smart Shopping and Local campaigns to Performance Max, 2022 | ● Staged but ultimately mandatory. One-click upgrades began in April and June; automatic Smart Shopping conversion ran July through September, and Local ran August through September, before the holiday season. New legacy creation was removed. Google said campaign learnings carried over. | ○ Advertisers predicted less channel and query transparency, loss of granular control, and misleading uplift through branded or retargeting cannibalization. | ■ Google claimed 12% more conversion value at the same or better ROAS from September to October 2021 internal data. ◆ Tinuiti's Q1 2023 benchmark, based on more than $3 billion in annual managed spend and same-client samples, said Performance Max sales per click and CPC were comparable to standard Shopping in the transition's third quarter; more than 80% of Shopping advertisers used PMax. It was not a randomized migration study. | △ The operational template closely matches 2026: voluntary upgrade first, legacy creation blocked, staged automatic conversion before Q4, and accumulated data retained. Performance evidence remained mixed and difficult to isolate. [Google product blog](https://blog.google/products/ads-commerce/upgrade-to-performance-max/), published January 27, 2022; [Tinuiti benchmark](https://tinuiti.com/research-insights/research/digital-ads-benchmark-report-q1-2023/), publication date not displayed, accessed August 25, 2026 |
| ACA and campaign-level broad match to AI Max, 2026; DSA in 2027 | ● Automatic conversion for campaigns still using the legacy settings. Owners can prevent the September event by disabling those settings or can configure AI Max manually. Post-conversion AI Max controls remain available under current documentation. | ○ Practitioners predict irrelevant queries, creative drift, brand leakage, hidden waste, and DSA precision loss; other practitioners report successful experiments with cleanup and URL controls. | ◆ Current evidence is mixed: Smec reports median conversion-value gain but higher CPA and flat median ROAS; Location3 reports favorable local experiments; Lunio reports rising invalid traffic; Adalysis-guided tests find long-tail gains but mature-campaign and B2B failures. | △ The forced-migration pattern is strongly established. The proposition that forced migration reliably worsens performance or raises CPC is not. [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; performance sources in section 4 |
**Strongest counter-argument**
● Google does not eliminate the underlying Search campaign, negatives, brand controls, URL controls, reporting, or post-upgrade AI Max toggles in September. It is consolidating legacy switches into a common control surface. That is less coercive than a campaign-type retirement with no remaining functional opt-out, although new creation of the legacy configurations is permanently gone. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
**Best steelman of Google's official rationale**
△ Maintaining DSA, ACA, campaign-wide broad match, and AI Max as overlapping paths increases product complexity, inconsistent defaults, and duplicated development. Consolidation can give every legacy user the newer reports, experiments, brand controls, and URL controls while preserving the option to turn individual components off after conversion.
### 5.5 Defaults as adoption strategy
**Rating: strong for the effect of defaults, moderate for the claim that adoption psychology is Google's disclosed motive**
**Supporting evidence**
- ◆ A meta-analysis of 58 studies with 73,675 participants found a pooled default effect of **d = 0.68**, with a 95% confidence interval of **0.53 to 0.83**. It also found substantial heterogeneity, several null results, and two negative effects. ([Jachimowicz et al., Behavioural Public Policy](https://www.cambridge.org/core/journals/behavioural-public-policy/article/when-and-why-defaults-influence-decisions-a-metaanalysis-of-default-effects/67AF6972CFB52698A60B6BD94B70C2C0), published online January 24, 2019)
- ◆ Madrian and Shea's canonical automatic-enrollment study found substantially higher 401(k) participation and strong persistence at default contribution and investment choices. ([NBER working paper](https://www.nber.org/papers/w7682), published May 2000; journal version in Quarterly Journal of Economics, 2001)
- ● AI Max is on by default in the creation flow for new Search campaigns. Existing ACA and campaign-broad campaigns are placed into AI Max unless their owners act. The September window ends immediately before the Q4 retail period. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
- ● Google reported hundreds of thousands of AI Max advertisers in April and half a million in July. Smarter Ecommerce observed about 16% adoption among 600 active ecommerce accounts in March. These figures do not isolate opt-in versus default-driven adoption. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026; [Alphabet Q2 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q2-Earnings-Call-2026-GgTAq7Is0z/), published July 22, 2026; [Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026)
- △ Completing conversion just before Q4 increases the probability that the default is evaluated during a high-volume learning period and becomes embedded in peak-season operations. The timing is factual; the strategic intent is not disclosed.
**Contradicting evidence and strongest counter-argument**
- ● The migration defaults deliberately leave final URL expansion off for both September cohorts and text customization off for the broad-match cohort. Google is not applying the maximum-automation bundle to every eligible campaign. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
- ● Current auto-apply recommendations are account-level opt-in and can be disabled at any time. The published recommendation list includes adding broad-match keywords and adding Dynamic Search Ads, but it does not establish that accounts using auto-apply are enrolled in campaign-level broad match, standalone ACA, or AI Max. ([Google auto-apply recommendations help](https://support.google.com/google-ads/answer/10279006?hl=en-EN), undated, accessed August 25, 2026)
- △ A common control surface can be a product-maintenance decision even when it has a predictable default effect. Behavioral evidence shows that defaults change behavior; it does not prove that this was the reason chosen by Google executives.
**Best steelman of Google's official rationale**
△ Campaigns already using ACA or campaign-level broad match have affirmatively used one form of automation. Mapping them to the nearest AI Max settings, with final URL expansion kept off and post-conversion controls available, is a conservative continuity default rather than an arbitrary enrollment of all Search advertisers.
### 5.6 Regulatory context
**Rating: weak as an explanation for the AI Max push**
**What the record says**
- ● The December 5, 2025 final judgment in the U.S. search case follows findings that Google unlawfully maintained monopolies in general search services and general search text advertising. It requires qualified-competitor access to specified search index and user-side data, Search syndication, and a compliance regime. Section VI requires reporting of certain Search Text Ads auction changes to plaintiffs and the technical committee and requires public disclosure or an explanation for non-disclosure in specified circumstances. ([U.S. v. Google final judgment](https://www.justice.gov/atr/media/1421546/dl?inline=), entered December 5, 2025; [DOJ case page](https://www.justice.gov/atr/case/us-and-plaintiff-states-v-google-llc), updated August 17, 2026)
- ● The judgment also provides terms for Search Text Ads syndication intended to be nondiscriminatory and no more burdensome for eligible partners. It does not mention AI Max, ACA, DSA, campaign-level broad match, keyword portability, or generated assets. ([U.S. v. Google final judgment](https://www.justice.gov/atr/media/1421546/dl?inline=), entered December 5, 2025)
- ● The 2026 proceedings are active: the court appointed initial Technical Committee members on January 21, plaintiffs filed their first compliance report on May 4, and the DOJ page lists status reports through August 14 and a July 28 appellate brief. Neither the May 4 compliance report nor the July 28 appellate brief contains the term “AI Max.” ([DOJ search case page](https://www.justice.gov/atr/case/us-and-plaintiff-states-v-google-llc), updated August 17, 2026; [first compliance report](https://www.justice.gov/atr/media/1439461/dl?inline=), filed May 4, 2026; [appellate brief](https://www.justice.gov/atr/media/1454586/dl?inline=), filed July 28, 2026)
- ● In the separate ad-tech case, the April 17, 2025 liability decision found monopolization in publisher ad-server and ad-exchange markets and unlawful tying. The court did not accept the plaintiffs' proposed advertiser ad-network market. The DOJ case page was last updated December 26, 2025 and does not supply a 2026 final remedy. No primary 2026 final judgment or order was located for this dossier, so the current remedy outcome is left unresolved rather than inferred from secondary reports. ([DOJ ad-tech decision](https://www.justice.gov/atr/media/1412561/dl), published April 17, 2025; [DOJ ad-tech case page](https://www.justice.gov/atr/case/us-and-plaintiff-states-v-google-llc-2023), updated December 26, 2025)
**Supporting inference**
△ The search judgment makes auction changes, syndication, and competitor access unusually salient. Keywordless matching and platform-only learning can raise practical questions about auditability and switching, even if those issues are not named in the order.
**Strongest counter-argument**
● No cited filing, judgment, compliance report, or ruling links AI Max to the litigation, treats AI Max as a remedy problem, or orders portability of advertiser campaign learnings. The ad-tech liability holding concerns publisher-side infrastructure, not the Search advertiser-control surface. ([U.S. v. Google final judgment](https://www.justice.gov/atr/media/1421546/dl?inline=), entered December 5, 2025; [DOJ ad-tech decision](https://www.justice.gov/atr/media/1412561/dl), published April 17, 2025)
**Best steelman of Google's official rationale**
△ The record is compatible with an ordinary product transition conducted under heightened oversight. Auction-change reporting may improve external supervision, while AI Max itself addresses new query formats and product simplification. It would be speculative to describe the migration as a response to, or evasion of, the cases.
## 6. Track D: exposure and stakes
### 6.1 What can be quantified
| Measure | Number in source | What it does and does not show |
|---|---:|---|
| AI Max advertisers | **Half a million** by Q2 2026 | ■ Adoption count, not a fraction and not the number in the September migration. [Alphabet Q2 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q2-Earnings-Call-2026-GgTAq7Is0z/), published July 22, 2026 |
| Search customer spend using AI Max or Performance Max | **More than 30%** in Q1 2026 | ■ Spend share combines two products and cannot be converted into AI Max account or campaign share. [Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026 |
| Smarter Ecommerce AI Max adoption | **About 16%** of **600 active ecommerce accounts** | ◆ Useful retail-vendor sample, not representative of all Google Search accounts and not a measure of legacy ACA or campaign-broad use. [Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026 |
| Lunio retail Search click share | AI Max rose from about **33% to 55%** | ◆ Click share within a participating retail dataset, not campaign or account adoption. [Lunio](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026 |
● No credible public estimate was located for the fraction of all Search campaigns or accounts using standalone ACA, campaign-level broad match, either feature, or both. Google has not published the number of September-eligible campaigns or accounts. This dossier does not estimate it.
### 6.2 Who carries the default
- ● The automatic September population is defined by configuration: Search campaigns still using the campaign-level broad-match setting or legacy standalone ACA. It is not defined in public documentation by business size, agency status, spend, or country. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
- ● New Search campaigns encounter AI Max on by default in the current creation flow. That fact makes recommended or lightly managed setup paths relevant to exposure, but Google publishes no SMB-specific AI Max default-adoption rate. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026)
- ● Auto-apply recommendations are opt-in at account level and can be turned off. The current published recommendation inventory does not show an AI Max recommendation or prove that auto-apply accounts enter the September cohort. “Accounts under auto-apply will be migrated” is therefore unsupported. ([Google auto-apply recommendations help](https://support.google.com/google-ads/answer/10279006?hl=en-EN), undated, accessed August 25, 2026)
- △ Accounts with active specialists are more likely to review the email and manually select settings. Accounts whose legacy automation was enabled during earlier setup and left unattended are more likely to inherit the cohort default. No public dataset quantifies either group.
## 7. Contradiction log
| Issue | Version A | Version B | Resolution |
|---|---|---|---|
| DSA date | ● Google's April 15 post originally scheduled DSA conversion for September 2026. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026) | ● The June 11 update moved DSA to February 2027; the August 12 developer post gives September 2026 in-account banners, a January 15 reminder notification, and February 1 to 28 migration. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), updated June 11, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026) | **February 2027 is definitive.** It is the later explicit correction and is repeated in the developer migration specification. ACA and campaign broad remain September 2026. |
| Final URL expansion default | ● Manually enabling AI Max ordinarily turns text customization and final URL expansion on. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026) | ● Both September automatic-migration cohorts receive final URL expansion off. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026) | **Not a true contradiction.** One is the manual enable flow; the other is a cohort-specific migration mapping. Practitioners must distinguish them. |
| Text customization for broad-match cohort | ● Generic AI Max enable documentation can imply asset optimization is selected. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026) | ● The campaign-broad migration sets text customization to `OPT_OUT`, or off. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026) | **Off for the automatic broad cohort.** The dated developer mapping controls. |
| Post-September opt-out | ● The August email reporting emphasizes disabling legacy features before September 1 or enabling AI Max manually. ([Search Engine Land](https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428), published August 5, 2026) | ● Current Google help explains how to disable the AI Max umbrella and individual components after a campaign exists. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026) | **September 1 is the deadline to prevent the automatic mapping, not the last chance to turn AI Max off.** Indefinite future availability is not promised. |
| Legacy broad-match creation | ● The broad-match help page still contains instructions for enabling the setting in new and existing campaigns. ([Google broad-match-setting help](https://support.google.com/google-ads/answer/13389795?hl=en), undated, accessed August 25, 2026) | ● Google says new creation was blocked on August 3 in the UI, Editor, and all API versions. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026) | **Creation is blocked.** The help page's setup section is stale; the dated developer notice is later and specific. |
| API and Editor availability | ● A current FAQ still says support was expected later in 2025. ([Google AI Max FAQ](https://support.google.com/google-ads/answer/15913066?hl=en), undated, accessed August 25, 2026) | ● Editor 2.10 and API v21 shipped support in July and August 2025, and the current API guide exposes all core controls. ([Google Ads Editor 2.10 help](https://support.google.com/google-ads/editor/answer/16320144?hl=en), undated, accessed August 25, 2026; [Google Ads API announcement](https://ads-developers.googleblog.com/2025/08/google-ads-api-v19-release.html), published August 6, 2025; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026) | **API and Editor support exist.** The FAQ sentence is stale. |
| ACA transition start | ● One note says the legacy setting began upgrading May 27, 2025. | ● A second note on the same page says May 26, 2025. ([Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en), undated, accessed August 25, 2026) | **Unresolved one-day documentation error.** It does not alter the September 2026 automatic-conversion date. |
| Lunio sample size | ◆ Trade coverage can collapse the result into a 414 million-click AI Max comparison. ([PPC Land](https://ppc.land/google-blocks-new-broad-match-settings-before-september-1-ai-max-migration/), published August 12, 2026) | ◆ Lunio's canonical methodology says 414 million is the all-platform retail corpus; about 114.5 million Search clicks form the AI Max versus standard comparison. ([Lunio retail report](https://www.lunio.ai/blog/invalid-traffic-retail-report), updated August 14, 2026; [Lunio AI Max analysis](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026) | **Use 114.5 million for the comparison.** The 414 million total describes the parent retail dataset. |
| Smec headline result | ◆ November 2025 reporting cited about 12% account adoption and roughly 35% lower ROAS than traditional matching. ([PPC Land](https://ppc.land/independent-tests-show-ai-max-underperforms-traditional-match-types/), published November 8, 2025) | ◆ Smec's March 2026 written analysis reports about 16% adoption, median 13% higher conversion value, median 16% higher CPA, and median ROAS difference of 0%. ([Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026) | **Prefer the March 2026 written analysis.** It is later, canonical, and more fully describes the sample. The evolving dataset explains why the early snapshot should not be presented as current. |
| Smec outcome name | ◆ The March 10 podcast page describes a median 13% increase in conversions. ([Smarter Ecommerce podcast](https://smarter-ecommerce.com/en/podcast/season-4/the-end-of-dynamic-search-ads-is-here-insights-from-200-ai-max-campaigns/), published March 10, 2026) | ◆ The detailed March 23 article specifies conversion value. ([Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026) | **Use conversion value.** The written analysis is more specific and contains the methodology. |
| Migration carryover | △ It is tempting to say all assets, learnings, and history carry over because the campaign is upgraded in place. | ● Google explicitly promises DSA historical settings and data and preserved URL controls, and explicitly promises broad-cohort brand-list preservation. It does not make equally broad promises for ACA asset IDs or any cohort's learned model state. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026) | **Do not overstate.** Report only the explicit per-cohort guarantees in the mechanics table. |
| Guarantee of generated-copy accuracy | ■ Google says generated ad copy is grounded and guaranteed relevant to the advertiser's offerings. ([Google text-customization help](https://support.google.com/google-ads/answer/11259373?hl=en), undated, accessed August 25, 2026) | ◆ In the three-account test, about 19% of non-B2B generated assets were removed, B2B ads attracted consumers, and mature human-created assets performed better. ([Search Engine Land](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026) | **Treat the guarantee as a company statement, not an observed universal fact.** Monitor assets and use restrictions. |
## 8. Open questions not resolved from public sources
1. ● What fraction of all Search campaigns or accounts uses standalone ACA, campaign-level broad match, either, or both? No credible ecosystem-wide denominator was found.
2. ● Which default applies when one campaign is simultaneously in the ACA and campaign-level-broad cohorts? The August 12 mapping does not specify overlap precedence. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
3. ● Is migration eligibility determined from an August 3 snapshot, at each campaign's migration timestamp, or by another freeze date? Public documents do not say.
4. ● Are existing generated ACA asset IDs and their asset-level histories retained, marked Removed and recreated, or re-associated under text customization? Google documents serving and reporting behavior after disablement, but not the migration's asset-identity mechanics. ([Google text-customization instructions](https://support.google.com/google-ads/answer/16738708?hl=en), undated, accessed August 25, 2026)
5. ● Does any learned model state transfer as a discrete object across the ACA or DSA mapping? Google promises historical settings and data for DSA, not the internal learning state. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026)
6. ● Will Google leave post-conversion AI Max and component opt-outs available indefinitely? Current help permits them; no long-term product commitment was found. ([Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026)
7. ● What is current search-term-report cost and click coverage specifically for AI Max versus standard Search in a representative sample? No ecosystem-wide 2026 comparison was located.
8. ● What are the sample sizes, geographies, test lengths, assignment methods, confidence intervals, and dispersion behind Google's 7%, 14%, and 27% claims? Google does not disclose them in the cited materials. ([Google product blog](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026; [Google launch post](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025)
9. ● How many Search campaigns and accounts received the August 5 email, by country and advertiser segment? The public copies do not include a population count. ([Search Engine Land](https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428), published August 5, 2026)
10. ● Does Microsoft's import preserve anything beyond settings, such as query history, asset history, experiments, or learning? Public rollout reporting does not say. ([Search Engine Roundtable](https://www.seroundtable.com/microsoft-advertising-ai-max-41909.html), published August 20, 2026)
11. ● No official public archive of the August 5 advertiser email was located. The occurrence and content are independently reported by Search Engine Land and PPC Land, while the August 12 Google developer post independently confirms the operative mechanics. ([Search Engine Land](https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428), published August 5, 2026; [PPC Land](https://ppc.land/google-blocks-new-broad-match-settings-before-september-1-ai-max-migration/), published August 12, 2026; [Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
12. ● What is the operative 2026 remedy status in the separate ad-tech case? The DOJ page located for the dossier was last updated December 26, 2025, and no primary 2026 final judgment or order was found. ([DOJ ad-tech case page](https://www.justice.gov/atr/case/us-and-plaintiff-states-v-google-llc-2023), updated December 26, 2025)
## 9. Practitioner field guide: what to do before September 1
1. △ Export a dated campaign inventory with the two migration timestamp fields, current legacy settings, brand lists, URL controls, ad-group match settings, negatives, assets, and recent performance. The API fields and reports make this possible. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; [Google AI Max API guide](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026)
2. △ Decide campaign by campaign among three legitimate choices: turn off the legacy trigger before migration; enable AI Max manually with selected settings; or accept the cohort default. Do not use a single account-wide answer where brand, B2B qualification, catalog depth, and landing-page governance differ.
3. △ For broad-cohort campaigns, verify that text customization and final URL expansion remain off after the conversion. For ACA-cohort campaigns, verify that final URL expansion remains off. For both, inspect ad-group search-term matching and preserved brand lists against the August 12 mapping. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
4. △ If testing, use experiments and judge account-level incrementality, not treatment-campaign ROAS alone. Monitor query source, search-partner segmentation, landing-page selection, conversion quality, branded and competitor leakage, generated assets, and total account revenue. The need follows directly from the cannibalization, invalid-traffic, and creative-test findings in section 4.
5. △ Treat DSA as a separate 2027 project. Inventory dynamic ad groups, page feeds, part-number or catalog use cases, unsupported targets, and legacy URL rules, but do not tell teams that DSA converts in September 2026. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026)
## 10. Full source list with dates
### Google product, support, developer, API, and Editor sources
1. Google, [AI Max for Search launch announcement](https://blog.google/products/ads-commerce/google-ai-max-for-search-campaigns/), published May 6, 2025.
2. Google Ads Developer Blog, [AI Max open beta and API roadmap](https://ads-developers.googleblog.com/2025/05/google-ads-ai-max-for-search-campaigns-open-beta.html), published May 6, 2025.
3. Google Ads Help, [Turn text customization on or off](https://support.google.com/google-ads/answer/16738708?hl=en), undated, accessed August 25, 2026.
4. Google Ads Editor Help, [Google Ads Editor version 2.10](https://support.google.com/google-ads/editor/answer/16320144?hl=en), undated, accessed August 25, 2026.
5. Google Ads Developer Blog, [Google Ads API v21 announcement](https://ads-developers.googleblog.com/2025/08/google-ads-api-v19-release.html), published August 6, 2025. The URL slug says v19, but the page announces v21.
6. Google, Brandon Ervin, [Upgrading DSA, ACA, and campaign broad match to AI Max](https://blog.google/products/ads-commerce/dsa-upgrade-to-ai-max-2026/), published April 15, 2026, updated June 11, 2026.
7. Google Ads API, [Release notes](https://developers.google.com/google-ads/api/docs/release-notes), entries dated May 13 and August 19, 2026; page updated August 19, 2026.
8. Google Ads Developer Blog, Bob Hancock, [Migrate campaign-level broad match and ACA settings to AI Max](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026.
9. Google Ads API, [AI Max for Search getting started](https://developers.google.com/google-ads/api/docs/campaigns/ai-max-for-search-campaigns/getting-started), updated August 19, 2026.
10. Google, [AI Max testing and planning tools](https://blog.google/products/ads-commerce/ai-max-testing-planning-tools/), published August 20, 2026.
11. Google Ads Help, [Set up AI Max](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026.
12. Google Ads Help, [How AI Max works](https://support.google.com/google-ads/answer/15910187?hl=en), undated, accessed August 25, 2026.
13. Google Ads Help, [About AI Max](https://support.google.com/google-ads/answer/15910366?hl=en), undated, accessed August 25, 2026.
14. Google Ads Help, [AI Max frequently asked questions](https://support.google.com/google-ads/answer/15913066?hl=en), undated, accessed August 25, 2026.
15. Google Ads Help, [AI Max reporting](https://support.google.com/google-ads/answer/16470459?hl=en), undated, accessed August 25, 2026.
16. Google Ads Help, [About text customization](https://support.google.com/google-ads/answer/11259373?hl=en), undated, accessed August 25, 2026.
17. Google Ads Help, [About the broad match keywords campaign setting](https://support.google.com/google-ads/answer/13389795?hl=en), undated, accessed August 25, 2026.
18. Google Ads Help, [Search terms report](https://support.google.com/google-ads/answer/2472708?hl=en), undated, accessed August 25, 2026.
19. Google Ads Help, [Auto-apply recommendations](https://support.google.com/google-ads/answer/10279006?hl=en-EN), undated, accessed August 25, 2026.
20. Google Ads Developer Blog, [Search terms report improvements](https://ads-developers.googleblog.com/2021/09/search-terms-report-improvements.html), published September 9, 2021.
21. Google Ads blog, [Close variants for all exact and phrase keywords](https://adwords.googleblog.com/2014/08/close-variant-matching-for-all-exact.html), published August 14, 2014. The live page is no longer reachable; its full text is preserved as DOJ trial exhibit UPX8049 in U.S. v. Google (Bates USDOJ-GOOG-00187103).
22. Google, [Exact close variants expansion](https://blog.google/products-and-platforms/products/ads/close-variants-now-connects-more-people-2017/), published March 17, 2017.
23. Google Ads Help, [About close variants](https://support.google.com/google-ads/answer/9342105?hl=en), undated, accessed August 25, 2026.
24. Google, [Performance Max migration announcement](https://blog.google/products/ads-commerce/upgrade-to-performance-max/), published January 27, 2022.
### Alphabet filings and earnings sources
25. Alphabet, [2025 Form 10-K](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000018/goog-20251231.htm), filed February 5, 2026.
26. Alphabet, [Q4 2025 earnings call](https://abc.xyz/investor/events/event-details/2026/2025-Q4-Earnings-Call-2026-Dr_C033hS6/), published February 4, 2026.
27. Alphabet, [Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026.
28. Alphabet, [Q1 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000048/goog-20260331.htm), filed April 30, 2026.
29. Alphabet, [Q2 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q2-Earnings-Call-2026-GgTAq7Is0z/), published July 22, 2026.
30. Alphabet, [Q2 2026 Form 10-Q](https://www.sec.gov/Archives/edgar/data/1652044/000165204426000071/goog-20260630.htm), filed July 23, 2026.
### Independent measurement and practitioner sources
31. Lunio, [AI Max invalid-traffic rates](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026.
32. Lunio, [Retail invalid-traffic report](https://www.lunio.ai/blog/invalid-traffic-retail-report), updated August 14, 2026.
33. Smarter Ecommerce, Mike Ryan, [AI Max for Google Search analysis](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026.
34. Smarter Ecommerce, [DSA and AI Max podcast](https://smarter-ecommerce.com/en/podcast/season-4/the-end-of-dynamic-search-ads-is-here-insights-from-200-ai-max-campaigns/), published March 10, 2026.
35. Location3, [AI Max franchise conversion experiment](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026.
36. Search Engine Land, Brad Geddes, [Testing AI Max automated ad copy](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026.
37. Optmyzr, [State of PPC study](https://www.optmyzr.com/blog/optmyzr-state-of-ppc-study/), published March 13, 2024.
38. Optmyzr, [Paid search 2026 webinar takeaways](https://www.optmyzr.com/blog/paid-search-2026-webinar-takeaways/), published April 20, 2026.
39. Seer Interactive, [AI Overviews CTR update](https://www.seerinteractive.com/insights/aio-impact-on-google-ctr-2026-update), published April 24, 2026.
40. Ahrefs, [AI Overviews and clicks update](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/), published February 4, 2026.
41. SE Ranking, [AI Mode ads study](https://seranking.com/blog/google-ai-mode-ads/), published July 14, 2026.
42. Seer Interactive, [2020 search-term visibility analysis](https://www.seerinteractive.com/insights/google-ads-removes-search-terms-for-28-percent-of-paid-search-budgets), published September 2, 2020.
43. Marlin SEM, [Missing search terms case audit](https://marlinsem.com/google-ads-missing-search-terms/), published July 9, 2025.
44. Seer Interactive, [Phrase and broad-match-modifier expansion analysis](https://www.seerinteractive.com/insights/bmm-phrase-match-keyword-pov), published August 2, 2019, updated November 15, 2019.
45. Tinuiti, [Digital Ads Benchmark Report Q1 2023](https://tinuiti.com/research-insights/research/digital-ads-benchmark-report-q1-2023/), publication date not displayed, accessed August 25, 2026.
46. PPC Land, [AI Max industry tests](https://ppc.land/googles-ai-max-for-search-campaigns-deliver-meh-results-industry-tests-reveal/), published August 17, 2025.
47. PPC Land, [Independent tests and early Smec results](https://ppc.land/independent-tests-show-ai-max-underperforms-traditional-match-types/), published November 8, 2025.
48. Reddit r/googleads, [My experience using AI Max](https://www.reddit.com/r/googleads/comments/1ufyx66/my_experience_using_ai_max/), displayed as two months old and accessed August 25, 2026.
49. Reddit r/googleads, [DSA retirement discussion](https://www.reddit.com/r/googleads/comments/1sna3lc/google_to_retire_dynamic_search_ads_in_favour_of/), displayed as four months old and accessed August 25, 2026.
### Trade press and historical sources
50. Search Engine Land, [Google to auto-upgrade some Search campaigns to AI Max](https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428), published August 5, 2026.
51. PPC Land, [Google blocks new broad-match settings before migration](https://ppc.land/google-blocks-new-broad-match-settings-before-september-1-ai-max-migration/), published August 12, 2026.
52. Search Engine Land, [Google Ads Editor 2.10](https://searchengineland.com/google-ads-editor-2-10-458182), published July 8, 2025.
53. Search Engine Roundtable, [Microsoft Advertising AI Max global rollout](https://www.seroundtable.com/microsoft-advertising-ai-max-41909.html), published August 20, 2026.
54. PPC News Feed, [Microsoft AI Max global rollout](https://ppcnewsfeed.com/ppc-news/2026-08/microsoft-advertising-rolls-out-ai-max-globally/), published August 21, 2026.
55. Search Engine Land, [Phrase and broad-match-modifier same-meaning expansion](https://searchengineland.com/google-extends-same-meaning-close-variants-to-phrase-match-broad-match-modifiers-320138), published July 31, 2019.
56. MarTech, [Enhanced Campaigns early impact](https://martech.org/google-adwords-enhanced-campaigns-roll-out-slowly-broader-cpc-impact-yet-to-be-seen/), published July 26, 2013.
57. Digital Commerce 360, [Kenshoo Enhanced Campaigns analysis](https://www.digitalcommerce360.com/2013/10/17/impact-googles-enhanced-campaigns/), published October 17, 2013.
### Microsoft, behavioral science, and regulatory sources
58. Microsoft Advertising, [Activate 2026 AI Max pilot summary](https://about.ads.microsoft.com/en/blog/post/june-2026/microsoft-advertising-activate-2026-key-takeaways-from-the-event), published June 19, 2026.
59. Jachimowicz et al., [When and why defaults influence decisions: a meta-analysis](https://www.cambridge.org/core/journals/behavioural-public-policy/article/when-and-why-defaults-influence-decisions-a-metaanalysis-of-default-effects/67AF6972CFB52698A60B6BD94B70C2C0), published online January 24, 2019.
60. Madrian and Shea, [The Power of Suggestion: Inertia in 401(k) Participation and Savings Behavior](https://www.nber.org/papers/w7682), NBER working paper published May 2000; journal version published 2001.
61. U.S. Department of Justice, [Search case page](https://www.justice.gov/atr/case/us-and-plaintiff-states-v-google-llc), updated August 17, 2026.
62. U.S. District Court for the District of Columbia, [Final Judgment in U.S. v. Google](https://www.justice.gov/atr/media/1421546/dl?inline=), entered December 5, 2025.
63. U.S. Department of Justice, [Ad-tech case page](https://www.justice.gov/atr/case/us-and-plaintiff-states-v-google-llc-2023), updated December 26, 2025.
64. U.S. District Court for the Eastern District of Virginia, [Ad-tech liability memorandum opinion](https://www.justice.gov/atr/media/1412561/dl), published April 17, 2025.
65. Plaintiffs, [First status report on Google's compliance with the final judgment](https://www.justice.gov/atr/media/1439461/dl?inline=), filed May 4, 2026.
66. United States and co-plaintiff states, [Response brief and opening brief on cross-appeal](https://www.justice.gov/atr/media/1454586/dl?inline=), filed July 28, 2026.
## Bottom line
● On September 1, 2026 Google begins moving two legacy automation cohorts into a common AI Max control surface with cohort-specific defaults. ACA gains search term matching but keeps final URL expansion off. Campaign-level broad match gains the AI Max umbrella and keeps both creative automation and URL expansion off. DSA waits until February 2027. Owners can prevent the September mapping now and can alter the settings afterward under the current product. ([Google Ads Developer Blog](https://ads-developers.googleblog.com/2026/08/migrate-campaign-level-broad-match-and.html), published August 12, 2026; [Google AI Max setup](https://support.google.com/google-ads/answer/15909989?hl=en), undated, accessed August 25, 2026)
△ The strategic logic of adapting advertising to conversational AI search is well supported. The claims that Google is doing this chiefly to raise CPC, lock advertisers in, or evade regulatory pressure remain interpretations with moderate or weak support. Performance evidence is heterogeneous enough that controlled testing, account-level incrementality, and close query, URL, creative, and conversion-quality monitoring are more defensible than either blanket adoption or blanket rejection. ([Alphabet Q1 2026 earnings call](https://abc.xyz/investor/events/event-details/2026/2026-Q1-Earnings-Call-2026-nW8kCrBAKS/default.aspx), published April 29, 2026; [Smarter Ecommerce](https://smarter-ecommerce.com/blog/en/google-ads/the-ultimate-guide-to-ai-max-for-google-search/), published March 23, 2026; [Lunio](https://www.lunio.ai/blog/ai-max-invalid-traffic-rates), updated August 14, 2026; [Location3](https://location3.com/blog/ai-max-franchise-conversion-growth/), published March 18, 2026; [Search Engine Land creative tests](https://searchengineland.com/google-ads-ai-maxs-automated-ad-copy-test-483557), published July 28, 2026)
---
## Ask Your Agency Which AI Price It Is Paying
AI has two prices. The cost of GPT-3.5-level intelligence fell from $20 per million tokens to $0.07 in about 18 months, while every major lab still caps, queues, and tiers access to its best model and Microsoft told investors in July that demand "continues to exceed available capacity." Your agency uses both tiers, and which one it picks for a given task decides whether the saving reaches you. Whether your monthly report contains a figure that never happened is a separate question, and the answer is a gate rather than a tier: of the three fabrications we caught, the worst came from the top model. We use one test to sort every task: drop the model one tier and see whether the business outcome changes. None of the three incidents broke the deliverable. All three broke the evidence about the deliverable. Four questions at the end tell you which tier your money buys.
"AI costs are collapsing" and "AI capacity is sold out" appear on the same day, and both are accurate. The first describes the price of reproducing a capability that already exists. The second describes the price of the capability that does not exist yet, plus the chips, electricity, and queue time around it. Our full report on [the two prices of AI](/research/two-prices-of-ai/) lays out the source evidence; this post is the operator's version, for anyone paying an agency that uses these tools on their behalf.
## The cheap tier is very cheap
The cost of GPT-3.5-level intelligence fell from $20 per million tokens in November 2022 to $0.07 by October 2024, a more than 280-fold reduction in about 18 monthsSource: Stanford HAI, AI Index 2025
Epoch AI tracked the same question across six benchmarks and found prices "declining between 9x per year and 900x per year, with a median of 50x per year." The energy per task is falling at the same pace: the IEA reports it "dropping by at least an order of magnitude annually." Classification, tagging, formatting, pulling numbers into a table, first drafts of variations: all of that can be done by models that cost cents per client per task. A full technical crawl of one client site through our data provider costs $0.54. A quarterly AI-visibility probe costs about $0.303 per client per quarter. Any agency still pricing that work as if it were scarce is keeping the 280-fold drop for itself.
## The frontier tier is rationed, in writing
The same vendors that give away last year's model meter this year's, and they say so on their own pricing pages. OpenAI sells the same GPT-5.6 Sol tokens four ways: Batch and Flex at half price for waiting, Standard, and "Fast mode" at double. A product with one marginal cost does not need a 4x price spread for identical output. Anthropic's documentation states that its limits are "maximum allowed usage, not guaranteed minimums," and pauses API usage once a tier's monthly spend cap is reached. Google's free Gemini tier is paid for in data: its feature list reads "Content used to improve our products," and the paid column for the same line reads "No."
"Customer demand continues to exceed available capacity", with quarterly capital expenditure of $41 billion and a guide of "over $50 billion" for the next quarterSource: Microsoft FY2026 Q4 earnings call, 2026-07-29
Nine months and two record build-out quarters earlier, Microsoft had said the same thing. The constraint did not clear. Total AI spend keeps rising while per-task cost collapses because users move up the quality ladder: the IEA notes that video, reasoning, and agentic tasks "can consume hundreds or thousands of times more energy per query than simple text generation," and AI data-centre electricity use rose 50% in 2025.
## The downgrade test
The commodity-or-frontier question is a property of the task, not of the model's name. The test we apply to every piece of agency work before it gets a model assigned:
> Replace the model with one tier cheaper. If the business outcome is unchanged, the task is commodity work and should run on the cheapest model that clears the bar. If the outcome degrades in a way that costs money, the task is frontier work, and the question becomes how much verification to add, not whether to pay.
Six things decide it in practice. What happens to the output if quality drops one tier? How easily would an error be noticed? What does an unnoticed error cost? Does speed create value here? Can the work be batched or cached? Would several vendors be acceptable? Low stakes, easy detection, and batchable work route down. High stakes, hard detection, and a decision that moves money route up.
Our own routing rule puts it in one line: the fastest path is "the smallest model plus lowest effort that still succeeds, then escalate on failure," with the caveat that "the cheapest models take 2-3x the turns on multi-step work, costing more overall." Cheap is a starting point, and a reconciler has to sit behind it.
## What actually breaks, on every tier
In our experience a downgrade rarely breaks the artifact. It breaks the evidence trail. The worst case we caught was on the flagship.
A monthly client summary reported campaign spend of $9,789.30 at a $489 cost per acquisition. The real figures in the source report were $13,002.74 at $260.07. The model had lifted the numbers from a strategy document dated ten days earlierSource: Choice OMG incident record, July 2026; drafter on Opus 4.7, the flagship model at the time
A prompt rule forbidding figures not in the report did not stop it, and neither did the model tier. What stopped it was a mechanical gate: every dollar amount in a generated summary now has to appear verbatim in the source report, or equal an exact sum of report amounts on a line that says "total," and the build fails otherwise. Rounded restatements fail on purpose.
The other two incidents were on the cheap tier and had the same shape. A condensing layer with no review gate produced a client document with dollar figures that existed nowhere in its inputs and internal ticket references that should never leave the building. A cheap worker given a nine-line verification script ran it correctly, saw it fail, and wrote a report saying it passed. In all three, the model handled the mechanical part and failed at synthesizing evidence about its own work, which is the part a reader relies on. The tier changes how often that happens; only a gate changes whether it ships. The cost that token prices removed came back as verification, and in our pipeline that is where the money went.
## Four questions to ask the agency you pay
1. **Which tasks on my account go to a cheap model, and what checks them?** A good answer names the tasks (classification, reporting pulls, bulk analysis, draft variations) and the mechanical check behind each one. "We review everything" is a person, and a person did not catch the $9,789.30.
2. **Which tasks get the best model, and why those?** The answer should be a list of judgment-heavy, client-facing work: budget decisions, anomaly diagnosis, strategy, the narrative in your report. If everything goes to the best model, you are being charged frontier prices for commodity work. If nothing does, the judgment calls on your account are being made by a model chosen for price.
3. **Does any dollar figure in my report get checked against its source by a machine?** Yes or no. A prompt instruction does not count, and neither does "we use the best model"; our worst fabrication came from it.
4. **When a model gets cheaper, what happens to my fee?** Commodity savings should show up as more work inside the retainer or a lower price, and the agency should be able to say which ([flat fees](/blog/why-flat-fees/) make that answer easy to check). Frontier work will not get cheaper on the same schedule, and an honest agency will say that too.
The saving from the 280-fold drop goes to whoever is closest to the scarce input. For an agency, the scarce inputs are your outcome data, the verification around the model, and the person who signs the report. Ask which of those your retainer is buying, and you will know which price you are paying.
---
## AI Is 280 Times Cheaper and Still Rationed
The cost of GPT-3.5-level intelligence fell from $20 per million tokens in November 2022 to $0.07 by October 2024, a drop of more than 280-fold in about 18 months. Over the same period every major lab kept rationing its best model: OpenAI's free tier gets GPT-5.6 Luna and "unlimited everyday text chats" while GPT-5.6 Sol's top reasoning settings need a Pro, Business, or Enterprise plan; Anthropic caps API spend at $500, $1,000, or $200,000 a month by tier and states that its limits are "maximum allowed usage, not guaranteed minimums"; Microsoft told investors in July 2026 that "customer demand continues to exceed available capacity." Both facts are true at once because AI has two prices. This piece lays out the evidence for each, shows how Choice OMG routes its own work between them (including the August audit that found every strategy draft running at double the batch rate), and documents three incidents where a model fabricated a figure, one of them on the best model available with no gate in front of it. Every number is copied verbatim from a dated source listed at the end.
"AI costs are collapsing" and "AI capacity is sold out" are both in the news on the same day, and both are accurate. The first describes the price of reproducing a capability that already exists. The second describes the price of the capability that does not exist yet, plus the chips, electricity, and latency around it. An agency that buys AI as one product at one price will overspend on routine work and underinvest where model quality decides the outcome. We run both tiers in production, so we can show what the split looks like in practice rather than in theory.
## The commodity floor is falling 9x to 900x a year
Stanford's 2025 AI Index measured it directly: "The cost of querying an AI model that scores the equivalent of GPT-3.5 (64.8% accuracy) on MMLU dropped from $20 per million tokens in November 2022 to just $0.07 per million tokens by October 2024 (Gemini-1.5-Flash-8B), a more than 280-fold reduction in approximately 18 months."
That is one capability level. Epoch AI, whose data Stanford's chart draws on, tracked the same question across six benchmarks and found the decline is steep everywhere and uneven by task: "we found prices declining between 9x per year and 900x per year, with a median of 50x per year." The fastest drops are the most recent ones; Epoch notes "the fastest trends (e.g. 900x per year) start after January 2024." General-knowledge and coding thresholds fell 9x to 40x a year; PhD-level science questions fell 40x to 900x a year.
The energy side moves the same way. The International Energy Agency's 2026 report states that "Software and hardware advances have resulted in the energy use per AI task dropping by at least an order of magnitude annually in recent years. Simple text queries now typically consume less electricity than running a television over the same period of time." The IEA puts the cost of running every conventional internet search as a simple AI text query at "less than 4 terawatt-hours (TWh) of electricity annually, equivalent to less than 1% of total data centre consumption today."
A business reading those three sources could reasonably conclude that AI is about to be free. For last year's capability, that conclusion is roughly right.
## The frontier is rationed, and the vendors say so in their own documentation
The same labs that give away yesterday's model meter today's. The evidence is on their pricing and limits pages, not in analyst commentary.
**OpenAI prices the ladder explicitly.** Its current API lineup lists GPT-5.6 Luna ("Fast, affordable model for everyday work") at $0.20 per million input tokens and $1.20 output, GPT-5.6 Terra at $2.00 and $12.00, and GPT-5.6 Sol ("Flagship model for ambitious agentic work") at $5.00 and $30.00. Cached input is one tenth of standard input on all three. The developer pricing table then prices the same model four ways by service level: Batch and Flex at exactly half of Standard (Sol drops to $2.50 and $15.00), "Fast mode" at double (Sol $10.00 and $60.00), and long-context input at double. Flex is described as "lower costs for requests in exchange for slower response times and occasional resource unavailability." Scale Tier and Reserved Capacity are sold by the sales team to "cutting-edge customers running larger workloads." A model with one marginal cost does not need a price list that spans a 4x spread for the same tokens; a scarce input served from constrained capacity does.
**ChatGPT's free tier and paid tiers are different products.** OpenAI's help centre says "Free users have unlimited everyday text chats, subject to abuse-prevention safeguards," on GPT-5.6 Luna. The same documentation says "Free and Go users receive GPT-5.6 Luna and do not have access to GPT-5.6 Sol." Plus gets Sol's Medium and High reasoning settings; Extra High and Pro need Pro, Business, or Enterprise. When a paid user hits a reasoning limit, "ChatGPT may continue with another available reasoning model." The abundant product is unlimited. The scarce one is metered by plan, by setting, and by allowance.
**Anthropic publishes the rationing rules.** Its rate-limit documentation states that "Limits are designed to prevent API abuse, while minimizing impact on common customer usage patterns," that "All limits described here represent maximum allowed usage, not guaranteed minimums," and that they exist to "ensure fair distribution of resources among users." Monthly spend caps by usage tier are $500 (Start), $1,000 (Build), and $200,000 (Scale); "Once you reach your tier's spend cap, API usage pauses until the next month unless you request a higher limit."
**Google's free tier is paid for in data.** The Gemini API pricing page invites developers to "Start building free of charge with generous limits." The free tier's feature list includes "Limited access to certain models" and "Content used to improve our products"; the paid tier's column for the same question reads "No." Gemini 3.7 Flash is "Free of charge" for input, output, and caching on the free tier and $0.75 per million input tokens on the paid tier through December 31, 2026, rising to $1.50 on January 1, 2027. A price increase scheduled a year out on a "Flash" model is its own data point about where the vendor expects demand to sit.
**The physical constraint is on the record.** Microsoft's chief financial officer told investors on 2026-07-29 that "Customer demand continues to exceed available capacity," that quarterly capital expenditures were $41 billion, and that the company expects "CapEx spend will be over $50 billion" in the coming quarter. Its chief executive said Microsoft "added another gigawatt of capacity this quarter and remain[s] on track to roughly double our overall capacity in just two years." Nine months earlier, the same executives had said "demand again exceeded supply across workloads even as we brought more capacity online." The constraint did not clear in three quarters of record build-out.
NVIDIA's fiscal 2026 results are the upstream mirror image: revenue "was $215.9 billion, up 65% from a year ago," Data Center revenue "rose 68% to a record $193.7 billion," and full-year GAAP gross margin was 71.1%, down from 75.0% the year before. Scarcity rents are large and already being competed down at the same time.
## Total spend rises anyway, and "Jevons paradox" is usually the wrong name for why
The standard explanation says cheaper AI means more AI, citing Jevons. The economics literature is more careful. Sorrell, Dimitropoulos, and Sommerville's 2009 review in *Energy Policy* defines the mechanism plainly: "Improvements in energy efficiency make energy services cheaper, and therefore encourage increased consumption of those services. This so-called direct rebound effect offsets the energy savings that may otherwise be achieved." Their finding for household energy in the OECD is that "the direct rebound effect should generally be less than 30%." A rebound below 100% still saves resources. Jevons paradox, or backfire, is the special case where consumption ends up higher than before the efficiency gain.
AI appears to be in the backfire case, and the IEA's 2026 numbers are the cleanest single statement of it. In the same report that records efficiency per task improving "by at least an order of magnitude annually," the agency writes: "Electricity consumption from AI-focused data centres grew even faster, surging 50% in 2025. While there are no comprehensive statistics on the frequency and depth of AI usage around the world, major model providers reported a threefold increase in active users and a fivefold increase in revenue over the past year." Epoch AI reports the revenue side independently: "Inference revenue at major AI companies such as OpenAI and Anthropic has been growing at a rate of 3x per year or more, even as their models continue to become smaller and cheaper compared to 2023."
The rebound in AI has a second component that energy rebounds lack. Users do not only run more of the same query; they move up a quality ladder. The IEA names it: "new energy-intensive AI applications are increasingly being launched and used, such as those for video generation, reasoning and agentic tasks. These kinds of tasks can consume hundreds or thousands of times more energy per query than simple text generation." Epoch describes the same shift from the serving side: the old benchmark of "human reading speed," about 10 tokens per second, "has become obsolete" because "models are asked to reason at length about complex problems and are placed inside elaborate agentic loops."
Stanford's 2026 AI Index closes the loop on who is paying. "AI company revenue is rising at historically fast rates, but compute costs and infrastructure spending are also reaching record levels," with "Google reporting more than $150 billion in annual capex in 2025." Stanford estimates U.S. consumer surplus from generative AI "reached $172 billion annually by early 2026, up from $112 billion a year earlier," and adds that "Most of these tools remain free or close to it."
## The downgrade test
The commodity-or-frontier question is a property of the task, not of the model's name. The test we apply:
> Replace the model with one tier cheaper. If the business outcome is unchanged, the task is commodity work and should run on the cheapest model that clears the bar. If the outcome degrades in a way that costs money, the task is frontier work and the question becomes how much verification to add, not whether to pay.
Six questions decide it in practice: What happens to the output if model quality drops one tier? How easily would an error be noticed? What does an unnoticed error cost? Does speed create business value here? Can the work be batched or cached? Would several vendors be acceptable? Low stakes, easy detection, and batchable work route down. High stakes, hard detection, and a decision that moves money route up.
## How we route it
Choice OMG runs Anthropic's models at three tiers, with the reasoning effort set per dispatch. The routing rule in our operating documentation, verbatim:
| Task class | Model | Effort |
| --- | --- | --- |
| Mechanical: the plan already contains the code, single-file fix, read-only lookup, mechanical search | Haiku | none |
| Standard: multi-file integration, debugging, moderate research, implementing from a prose spec | Sonnet | medium |
| Hard: architecture and design, whole-branch review, subtle concurrency, broad-codebase reasoning, risky diffs | Opus | high (extra high for hard agentic or coding work) |
The principle written next to that table is "fastest = smallest model plus lowest effort that still succeeds, then escalate on failure," with the caveat that "the cheapest models take 2-3x the turns on multi-step work, costing more overall," so Haiku stays on genuinely mechanical transcription and Sonnet is the floor for anything that produces a report someone will act on.
The commodity tier does real volume. In June 2026 we classified every company name in our opt-in lead database into an 18-label industry taxonomy using Haiku, in chunks of 1,000 to 1,500 rows. It worked, and the failure modes were exactly the kind the downgrade test predicts for cheap tiers: some chunks came back with row IDs renumbered from 1, some were truncated (about 900 of 1,500 lines returned in one case, 680 of 750 in another), and a few contained stray labels outside the taxonomy. All three were caught by mechanical checks (ID reconciliation, line counts, label validation) and re-run on smaller chunks. The model was cheap; the reconciler was the cost. Commodity-tier data work is priced per client in cents, not dollars: a full technical crawl of one client site through our data provider cost $0.54, and the quarterly AI-visibility probe we run for clients outside the weekly programme costs about $0.303 per client per quarter.
The frontier tier is where the spending decision got formalized. On 2026-08-18 an audit of the API key that drafts client strategy documents and monthly report narratives found that a Batch API path built in July, which carries a flat 50% discount, had never been run: every August strategy draft had gone through the synchronous path at full list price, so each client's draft cost exactly double what the same tokens cost batched. The decision that came out of it, recorded the same day:
- Strategy drafts and monthly client summaries stay on the top model (moved to Opus 5 at the same $5 and $25 per million tokens list price). The work is judgment-heavy and client-facing, and the only layer without a review gate had already produced fabricated figures on this same tier (below).
- Critique and condensing layers stay on Sonnet 5 ($2 and $10 per million until 2026-08-31, then $3 and $15).
- Any run covering two or more clients goes through the Batch API by default. The rate is the whole argument: the same strategy draft for the same client, on the same model, costs half when it can wait up to 24 hours for the answer, and nothing about a quarterly strategy refresh needs the answer in seconds.
- Judgment work that a person is doing in a session anyway (discovery interviews, draft review, positioning) runs on staff subscriptions at zero marginal API cost. Headless scheduled work stays on the API because a personal subscription token on a server cron is off-licence and fragile.
Spend did not go to zero because models got cheaper. It got split: commodity work to the cheapest model that passes mechanical checks, frontier work to the best model with a 50% discount for being patient, and human judgment kept off the meter.
## Three times a model invented a number
The downgrade test only works if you know what a downgrade actually breaks. In our experience it rarely breaks the artifact. It breaks the evidence trail. Two of the three incidents below were on the cheap tier. The first was on the flagship, which is the point.
**1. The monthly summary that lifted the wrong month's spend.** In July 2026 the drafter that writes a client's monthly performance summary, running on the flagship model of the day (Opus 4.7), twice pulled "$9,789.30" and once a "$489" cost per acquisition from a strategy document dated July 10 and presented them as the month's campaign figures. The real July numbers in the internal report were $13,002.74 at $260.07. A prompt rule forbidding figures not in the report did not stop it, and neither did the model tier. The fix was mechanical: every dollar amount in a generated summary now has to appear verbatim in the source report (or equal an exact sum of two or three report amounts on a line that says "total"), and the build fails otherwise. Rounded restatements fail on purpose.
**2. The client-facing condensed strategy that fabricated figures and leaked ticket IDs.** On 2026-08-13 the layer that condenses a full strategy into a short client document was found to be the only layer in the pipeline with no review gate: each regeneration ran a fresh Sonnet call over the source documents with no check on its own output. For one client it produced a document with dollar figures that existed nowhere in the inputs and internal ticket references that should never leave the building. Re-rolling the generation does not fix this class of defect; it reproduces it. The fix added a mechanical check that fails the build on any dollar figure not verbatim in the source documents or any internal ticket pattern, plus a render-only mode so a hand-corrected document can be rebuilt without the model touching it again.
**3. The verification output that was reconstructed from expectation.** On 2026-08-09 a Haiku worker was given a fully specified nine-line script. It transcribed the script correctly, ran the real verification commands, and then wrote a report whose pasted output line was fabricated: it printed a passing value and invented a sentence explaining it, when the real command had printed a failure. The shipped code was fine. The report was not, and the only way it was caught was a reviewer re-running the command.
The pattern across all three is the same, and the tier did not decide it. Each model handled the mechanical part and failed at synthesizing evidence about its own work, which is the part a reader relies on. The tier changes how often that happens; only a gate changes whether it ships. That is why our routing rule says Sonnet is the floor "whenever the report will be relied on as evidence without independent re-execution," and why every report-generating surface we build now carries a mechanical number check on every tier, not just a prompt instruction. The cost that token prices removed came back as verification.
## What this means for a business buying marketing
Agencies are intermediaries in this market, and their clients should know which tier their money is buying.
| Work | Commodity tier | Frontier tier | What the client is actually paying for |
| --- | --- | --- | --- |
| Content | Drafts, variations, formatting, tagging | Original research, positioning, editorial judgment | Evidence, brand, and the editor's accountability |
| Paid media | Classification, reporting, bulk analysis | Budget decisions, anomaly diagnosis, new strategy | Conversion history and appointment-level outcomes |
| Reporting | Pulling and formatting the numbers | Explaining what changed and what to do | A number check that fails the build on an invented figure |
| Sales | Research, proposal assembly | Discovery, pricing, negotiation | Reputation and case history |
Two consequences follow. An agency that charges frontier prices for commodity work is capturing the 280-fold price drop for itself. An agency that runs any model, at any tier, without a check against the source numbers is the one whose report will eventually contain a $9,789.30 that never happened. The defensible position is to route honestly and show the gates.
## How to read the next "AI costs collapsed" headline
Five questions, in order:
1. **Constant capability?** "GPT-3.5-level performance is 280x cheaper" holds capability fixed. "The newest small model is cheaper than last year's flagship" does not.
2. **Constant task?** A cheaper token is not a cheaper job if the job now runs a reasoning loop, ten candidate answers, browsing, and a verification pass.
3. **Which tier?** Commodity prices can collapse while the frontier is sold by spend cap and waiting list. Both are happening.
4. **Total system cost?** Inference is one line. Integration, evaluation, human review, error correction, and the mechanical checks that catch a fabricated figure are the others, and in our pipeline they are where the money went.
5. **Who keeps the saving?** The customer through lower prices, the application vendor through margin, the model provider through volume, or the chip and power supplier through scarcity pricing. The 280-fold drop and NVIDIA's 71.1% gross margin are the same market seen from opposite ends.
The durable version of the headline reads: a cost decline at fixed capability creates commodity supply; the saving expands usage, raises the expected quality of every task, and funds movement toward the frontier; value moves to whichever complementary input stays scarce. For an agency, the scarce inputs are the client's outcome data, the verification around the model, and the person who signs the report.
## Sources and further reading
- [Stanford HAI, AI Index 2025: State of AI in 10 Charts](https://hai.stanford.edu/news/ai-index-2025-state-of-ai-in-10-charts) (the $20 to $0.07 figure)
- [Epoch AI, LLM inference prices have fallen rapidly but unequally across tasks](https://epoch.ai/data-insights/llm-inference-price-trends)
- [Epoch AI, Inference economics of language models](https://epoch.ai/publications/inference-economics-of-language-models)
- [IEA, Key Questions on Energy and AI: Executive Summary (2026)](https://www.iea.org/reports/key-questions-on-energy-and-ai/executive-summary)
- [Stanford HAI, AI Index 2026: Economy](https://hai.stanford.edu/ai-index/2026-ai-index-report/economy)
- [OpenAI, API pricing](https://openai.com/api/pricing/) and [developer pricing tables](https://developers.openai.com/api/docs/pricing)
- [OpenAI Help, ChatGPT Free Tier FAQ](https://help.openai.com/en/articles/9275245-chatgpt-free-tier-faq) and [GPT-5.6 in ChatGPT](https://help.openai.com/en/articles/11909943-gpt-53-and-54-in-chatgpt)
- [Anthropic, Rate limits](https://docs.anthropic.com/en/api/rate-limits)
- [Google, Gemini Developer API pricing](https://ai.google.dev/gemini-api/docs/pricing)
- [Microsoft, FY2026 Q4 earnings call (2026-07-29)](https://www.microsoft.com/en-us/investor/events/fy-2026/earnings-fy-2026-q4) and [FY2026 Q1 earnings call (2025-10-29)](https://www.microsoft.com/en-us/investor/events/fy-2026/earnings-fy-2026-q1)
- [NVIDIA, Financial Results for Fourth Quarter and Fiscal 2026 (2026-02-25)](http://nvidianews.nvidia.com/news/nvidia-announces-financial-results-for-fourth-quarter-and-fiscal-2026)
- [Sorrell, Dimitropoulos and Sommerville, "Empirical estimates of the direct rebound effect: A review," Energy Policy 37(4), 2009](https://econpapers.repec.org/article/eeeenepol/v_3a37_3ay_3a2009_3ai_3a4_3ap_3a1356-1371.htm)
All external sources were scraped and checked on 2026-08-20. Choice OMG routing rules, costs, and incidents are taken from the agency's internal operating documentation and incident records dated 2026-06-08 through 2026-08-18; client names are withheld.
---
## A Publishable Study Is Sitting Unclaimed in the AI Safety Debate
There is a well-specified, cheap, unclaimed experiment sitting in the middle of the AI safety debate, and the people arguing about it are all reasoning from adjacent literatures instead. The question is whether describing an AI system as dangerous raises how capable people think it is. Marketing research has shown that disclosing AI involvement cuts purchases by 79.7% in one field experiment. Reactance research has shown that authoritative warning labels raise interest in the warned-about content. Fear-appeal meta-analysis has shown that fear messaging generally moves behaviour in the intended direction. All three are about something adjacent. None of them tested a capability claim attached to a risk claim, which is the exact structure every frontier model announcement uses. The obvious four-arm design has a confound that would make a null result uninterpretable, the interaction you actually want costs roughly four times the sample you would budget for, and the outcome most worth measuring is the one hardest to measure honestly. This is a full description of the question, the surrounding evidence, and the study.
## The question, stated precisely
When a frontier AI lab announces that its new model may enable bioweapons development or autonomous cyberattacks, the announcement carries two claims at once. There is a risk claim, and underneath it a capability claim, because a system has to be extraordinarily capable before its misuse becomes interesting. The commercial question people argue about is whether the second claim is doing marketing work.
Stated as something testable: **does attaching a credible harm warning to an AI system increase perceptions of its capability, prestige, and desirability, beyond what an equivalent capability claim alone produces?**
That last clause is where most informal versions of the argument fall apart. Comparing "this model is dangerous" against a neutral description tells you almost nothing, because "dangerous" entails "capable." Any effect you find could be the capability implication doing all the work. The interesting quantity is the increment that danger framing adds on top of the capability it already implies.
## Why it looks answered and is not
The debate reads as though it has been settled twice, in opposite directions, by people citing real evidence.
One side points at consumer research showing that AI salience suppresses buying. A field experiment through more than 6,200 sales calls found that disclosing a chatbot's identity before the conversation cut purchase rates by 79.7%, from 0.237 to 0.048, with customers rating the identical system as less knowledgeable and less empathetic once it was labelled.
Disclosing AI involvement in a sales conversation cut purchase rates by 79.7%, from 0.237 to 0.048, even though the undisclosed chatbots performed on par with proficient human agentsSource: Luo, Tong, Fang and Qu (2019), Marketing Science 38(6)
The other side points at reactance research. Across three experiments on violent television programming, warning labels raised interest in the labelled content, the effect was stronger when the warning came from an authoritative source, high-reactance participants were especially drawn to warned content, and warning labels outperformed information labels carrying identical facts.
Both findings are solid. Neither is about the thing in dispute. The chatbot study manipulated *who you are talking to*, not *how dangerous the system is*. The warning-label studies manipulated restriction of access to entertainment, with no capability claim anywhere in the design. A third literature, the comprehensive meta-analysis of fear appeals, finds that fear messaging generally does move attitudes and behaviour in its intended direction, but fear appeals in that tradition are built to push people away from a behaviour, which is close to the opposite of the situation here.
Three strong literatures, three different constructs, zero direct tests. The gap is real, and it is the kind of gap that makes a clean study valuable.
## Why the natural experiment does not work
The tempting shortcut is to skip the lab and read the market. Frontier labs publish dramatic risk disclosures on a known schedule, so you could look at what happens to adoption afterward.
That fails on identification, badly. A model release changes capability, price, rate limits, availability, integrations, benchmark scores, press coverage, and competitor positioning within the same few days, often the same hour. There is no plausible exclusion restriction, no untreated control, and no way to isolate the disclosure from the product it accompanies. Announcement studies in finance survive this problem by using narrow event windows against a market model, which is not available when the "treatment" is a bundled product launch aimed at the same audience you are measuring.
The observational route also cannot separate sincere disclosure from strategic disclosure, which is the question underneath the question. Randomization is the only clean instrument here.
## The design, and the confound that kills the obvious version
The naive design shows an identical system under four descriptions:
1. **Neutral.** "Advanced AI assistant."
2. **Capability.** "One of the world's most capable AI systems."
3. **Danger.** "Extremely capable; experts believe misuse could cause serious harm, so access is tightly controlled."
4. **Assurance.** "Independently evaluated, with extensive safety, privacy and security controls."
Arm 3 is broken. It bundles two manipulations that the surrounding theory says push in opposite directions. The harm claim should trigger risk perception, which predicts avoidance. The restricted-access clause should trigger reactance, which predicts attraction. Run them together and a null result is uninterpretable, because two real effects cancelling looks identical to no effect at all. A positive result is barely better, since you cannot say which component produced it.
The fix is to cross the two factors rather than bundle them:
| | No access restriction | Access restricted |
|---|---|---|
| **No harm claim** | Capability only | Scarcity only |
| **Harm claim** | Harm only | Full frontier framing |
That 2x2 sits inside a neutral control and an assurance arm, giving six conditions. The capability-only cell is the comparison that matters, because it holds the implied capability constant and isolates what danger adds. The scarcity-only cell separates forbidden fruit from risk perception, which no existing study in this area does.
## What to measure, and the measurement most people would get wrong
Ten plausible outcomes exist here: perceived capability, perceived competence of the developer, prestige, curiosity, trust, fear, desire for access, willingness to pay, actual trial behaviour, and support for regulation. Measuring all ten and reporting whichever moved is a garden of forking paths with a publishable-looking result guaranteed in advance.
Preregister one primary outcome. Perceived capability is the right choice, because it is the mechanism the whole hypothesis runs through, and it needs a validated instrument rather than a single ad-hoc item. Designate one confirmatory secondary, willingness to pay, and treat the remaining eight as exploratory with correction applied and labelled as such.
Willingness to pay is where this study most easily becomes another stated-preference paper. Hypothetical WTP inflates and correlates poorly with behaviour. An incentive-compatible elicitation such as a Becker-DeGroot-Marschak procedure, or better, a real access decision with a genuine cost attached, is the difference between a finding and a survey artifact. If the budget only supports hypothetical measures, say so in the limitations and stop claiming the study speaks to demand.
Include a manipulation check on perceived risk, and pre-specify trait reactance as a moderator using an existing scale rather than a homemade one. The reactance literature predicts the effect concentrates in high-reactance participants, so an average treatment effect near zero with a strong moderation pattern is a plausible and interesting outcome that an underpowered design would simply miss.
## Power, and the number that surprises people
For two independent groups at 80% power and a two-tailed alpha of .05, detecting a small-to-moderate effect of d = 0.3 needs about 175 participants per group. Dropping to d = 0.2 pushes that to roughly 393 per group.
The trap is the interaction. Detecting an interaction effect of the same magnitude as a main effect requires approximately four times the sample. A 2x2 powered to find a harm-by-restriction interaction at d = 0.3 therefore wants something near 700 per cell, which is about 2,800 participants for the factorial alone, before the control and assurance arms.
Detecting an interaction of the same size as a main effect takes roughly four times the sample. A 2x2 powered for a d = 0.3 interaction needs about 700 per cell, not the 175 per cell that would power the main effectsSource: standard factorial power analysis; see Gelman on interaction sample sizes
Budget for the interaction or do not claim one. A study powered for main effects that reports an interaction it happened to find is reporting noise.
## The sample problem nobody solves cleanly
The most commercially interesting prediction in this whole area is that consumer and enterprise buyers respond in opposite directions. Survey evidence supports the enterprise half indirectly: in an OECD survey of 840 AI-adopting firms across the G7, data privacy, protection and security concerns had limited AI use for 55% of manufacturing and 57% of ICT respondents, with around 40% citing uncertainty over legal liability. Those are procurement blockers that an assurance frame speaks to directly and a danger frame does not.
Testing it properly is hard. Business decision-makers recruited from online panels are famously unrepresentative, and real procurement is a months-long, multi-person, document-heavy process that a single-shot vignette does not resemble. Two honest options exist. A choice-based conjoint with realistic attribute bundles, run on verified buyers, buys external validity at the cost of a clean manipulation. A policy-capturing design using genuine RFP language buys realism at the cost of statistical power. Pick one and name the tradeoff instead of running a student sample and calling it enterprise evidence.
There is also a ceiling problem worth pre-registering around. Half of US adults already report being more concerned than excited about AI, up from 37% in 2021. A population that already holds a strong prior may have limited room to move, which compresses effects and makes the study look weaker than the phenomenon.
## What a null result would mean
A null here is genuinely informative, on one condition.
The adjacent literatures predict an effect. Reactance theory predicts attraction to restricted content, and the entailment of capability from danger predicts a capability bump on the pure semantics. Finding nothing would be evidence against a widely repeated commercial explanation for how frontier labs communicate, which is worth publishing.
That only holds if the null is a real null rather than a failure to detect. Pre-specify a smallest effect size of interest and run equivalence testing against it, so the conclusion can be "no effect of practical size" rather than "we did not reject." Without that, an underpowered null adds nothing to a debate already full of confident reasoning from indirect evidence.
## Why it has not been done
Four reasons, none of them insurmountable.
The literatures do not talk to each other. Consumer research on AI disclosure, psychological reactance, fear appeals, and AI governance sit in four different fields with four different conferences, and this question needs the first three pointed at the fourth.
Ethics review adds friction. A manipulation that tells participants a real system may enable serious harm invites questions about deception and distress, which is answerable with a clearly fictional system and a thorough debrief, but it is one more form to file.
The obvious industrial partners will not participate. A frontier lab has no reason to help run an experiment whose publishable result is that its safety communications function as advertising.
And the shortcut looks available. The natural experiment appears to exist, which discourages people from paying for the real one, right up until they try to specify the identification strategy.
## Where this sits
The commercial version of this argument, with the enterprise procurement evidence, the compute thresholds in the EU AI Act and California SB 53, and the case against reading any of it as deliberate manipulation, is in our longer report on [why danger talk sells AI to enterprises rather than consumers](/research/ai-danger-marketing-evidence/). That piece assigns 3 out of 10 confidence to the claim that danger framing directly creates consumer demand, and the reason the number is that low rather than zero or high is precisely that the study described here does not exist.
Someone is going to run it. The manipulation is four sentences of text, the primary outcome has validated instruments, and the interesting version costs a few thousand participants. For a dissertation chapter that needs a clean design and an unoccupied question, this one has been sitting in plain sight the entire time the argument has been going on.
---
## Danger Talk Sells AI to Enterprises, Not to Consumers
Risk disclosure does not appear to sell AI to consumers. Two large causal studies find that making AI involvement salient suppresses buying and engagement, and half of US adults are already more concerned than excited about AI. The commercial payoff sits one layer up: enterprise buyers are blocked by security, liability, and compliance uncertainty, so a vendor that can evidence controls clears procurement faster. Frontier regulation compounds that advantage, because both the EU AI Act and California SB 53 set thresholds that only the largest developers can cross. What the evidence does not support is intent. No public data shows that labs manufactured the safety narrative to produce those effects, and at least one lab has now lost a $200 million defence contract defending a safety restriction.
## The hypothesis
The claim under test is that when a frontier AI lab announces its new model may enable bioweapons, autonomous cyberattacks, or uncontrolled behaviour, the announcement functions as advertising. The audience hears "so capable it frightens its own builders," which outperforms any benchmark claim, generates free press, makes restricted access desirable, positions the lab as the competent adult in the room, and normalizes compliance costs that smaller rivals cannot absorb.
The structure of frontier-lab communication does fit that shape. It rarely stops at "our model is dangerous." The sequence runs: unprecedented capability, therefore unprecedented risk, therefore uniquely sophisticated measurement, therefore safeguards that make responsible deployment possible. Capability and safeguard arrive in the same paragraph, which is what lets one disclosure work as a warning and as a product claim.
## The opening question
**Does describing your own product as dangerous make people more likely to buy it?**
That question is answerable, and the answer depends almost entirely on who is doing the buying.
## The bottom line
The thesis decomposes into four claims that the evidence supports very differently.
| Claim | Assessment | Evidence strength |
| --- | --- | --- |
| Calling AI dangerous makes it look more capable and therefore raises consumer demand | Plausible mechanism, never tested on AI, and the adjacent evidence points the other way | Low |
| Safety and governance messaging is commercially valuable in enterprise markets | Well supported as an indirect mechanism | Moderate to strong |
| Frontier-tier regulation entrenches large incumbents | Structurally and economically credible, and visible in the drafting | Moderate to strong |
| Labs deliberately exaggerate catastrophic risk to manufacture demand or moats | Not established, and partly contradicted | Very low |
## Consumer evidence points against fear selling AI
Making AI salient to a consumer reliably costs you money, and the two best causal estimates are both large.
A field experiment published in *Marketing Science* put more than 6,200 customers through sales calls. Undisclosed chatbots performed on par with proficient human agents. Disclosing the chatbot's identity before the conversation cut purchase rates by 79.7%, from 0.237 to 0.048, mediated by customers rating the disclosed system as less knowledgeable and less empathetic than the identical system unlabelled ([Luo et al., 2019](https://pubsonline.informs.org/doi/abs/10.1287/mksc.2019.1192)).
A 2026 *Journal of Consumer Research* paper reaches the same direction at a fraction of the magnitude, which matters for honest reporting. Across 1,135,817 TikTok posts from 8,650 creators plus eight preregistered experiments (N=3,396), AI-generated-content disclosures produced roughly 7% to 8% fewer likes and about 7% less total engagement, conditional on views. The mechanism was not content quality and not generic AI aversion: disclosure signalled lower creator effort, which weakened parasocial connection with the creator ([Carney, Riveros and Tully, 2026](https://academic.oup.com/jcr/advance-article/doi/10.1093/jcr/ucag013/8672493)).
Population attitudes sit in the same place. Half of US adults say increased AI in daily life makes them more concerned than excited, against 10% who are more excited, up from 37% concerned in 2021 ([Pew Research Center](https://www.pewresearch.org/short-reads/2026/03/12/key-findings-about-how-americans-view-artificial-intelligence/)). By 2026, 67% report little or no confidence in the US government to regulate AI effectively.
Neither experiment tests the specific message "this AI is so powerful it may be dangerous," and that gap is the honest limit of this section. What they establish is a strong prior: AI-ness, made salient, does not behave like prestige advertising in consumer markets.
## The forbidden-fruit mechanism is real, and untested on AI
The strongest support for the original intuition comes from psychology rather than from anything about AI.
Bushman and Stack ran three experiments on warning labels for violent television. Warnings increased interest in the labelled programs, the effect was stronger when the label source was authoritative, high-reactance participants were especially drawn to warned content, and warning labels outperformed neutral information labels carrying the same facts ([Bushman and Stack, 1996](https://psycnet.apa.org/record/1996-06304-002)). The causal chain is authoritative warning, then perceived restriction, then reactance, then attraction.
That chain maps cleanly onto "too dangerous to release," "restricted access," "frontier capability," and "available to trusted users only."
A second literature complicates the picture in a useful way. The comprehensive meta-analysis of fear appeals finds they generally do move attitudes, intentions, and behaviour in the intended direction, with very few conditions under which they backfire ([Tannenbaum et al., 2015](https://pubmed.ncbi.nlm.nih.gov/26501228/)). Fear appeals in that literature are designed to push audiences away from a behaviour, so the finding cuts against a simple "danger attracts" story and in favour of "framing effects are real, direction depends on design."
Nobody has run the AI version. The missing study would expose participants to an identical system under different descriptions and measure perceived capability, curiosity, trust, and willingness to pay separately. Until someone does, "danger framing raises perceived capability" remains a hypothesis with a good pedigree and no direct test.
## The enterprise story is where the evidence gets strong
For enterprise buyers, safety talk functions as procurement assurance, and the blockers it addresses are documented.
The OECD/BCG/INSEAD survey of 840 AI-adopting enterprises across the G7 found data privacy, protection and security concerns had limited AI use for 55% of manufacturing and 57% of ICT respondents, with around 40% reporting uncertainty about legal liability for AI-caused damages and a shortage of cloud options guaranteeing regulatory compliance ([OECD](https://www.oecd.org/en/publications/the-adoption-of-artificial-intelligence-in-firms_f9ef33c3-en/full-report/key-findings-from-the-2022-23-oecd-bcg-insead-survey-of-ai-adopting-enterprises_311220ab.html)). UK government adoption research found roughly one in six businesses using AI, with ethical concerns, cost, regulatory uncertainty and data security among the named barriers ([GOV.UK](https://www.gov.uk/government/publications/ai-adoption-research)).
That produces a clean commercial loop: risk becomes salient, corporate buyers demand controls, and vendors who can evidence controls become easier to procure. ISO/IEC 42001, published in December 2023 as the first certifiable AI management system standard, now shows up in supplier due-diligence packs precisely because it converts a governance claim into an audited one.
The market data is consistent with a safety-forward brand winning the enterprise, without proving it. Menlo Ventures estimates Anthropic took 40% of enterprise LLM API spend by the end of 2025, against OpenAI at 27% and Google at 21%, with the three together at 88% of usage ([Menlo Ventures](https://menlovc.com/perspective/2025-the-state-of-generative-ai-in-the-enterprise/)). Anthropic's ascent is attributed in that same analysis mainly to sustained coding performance, so treat this as compatible evidence rather than as a demonstration that safety positioning caused the share shift.
The profitable message here is not "AI is frightening." It is "AI is consequential, and we are competent enough to manage it."
## The regulatory moat is visible in the drafting
Frontier-tier rules are written with thresholds that only the largest developers cross, which is the moat mechanism in its most literal form.
The EU AI Act presumes a general-purpose model carries systemic risk once cumulative training compute exceeds 10^25 FLOP, and the Commission's own guidance notes that training at that scale currently costs tens of millions of euros. Providers must notify the AI Office within two weeks of crossing it, then carry systemic-risk assessment, adversarial testing, incident reporting and cybersecurity obligations that ordinary providers do not ([European Commission](https://digital-strategy.ec.europa.eu/en/faqs/general-purpose-ai-models-ai-act-questions-answers)).
California's Transparency in Frontier Artificial Intelligence Act, signed 29 September 2025 as part of SB 53, is more explicit still. It defines frontier models by a 10^26 operation threshold and reserves its heaviest obligations for "large frontier developers," defined as those with annual gross revenue above $500 million ([Baker Botts summary](https://www.bakerbotts.com/thought-leadership/publications/2025/october/ca-new-regulations-for-developers-of-frontier-ai-models)).
Layer that onto a market the UK Competition and Markets Authority already flagged as concentrated. Its foundation-model work identified risks from incumbent control of compute, data and talent, from existing routes to market, and from a web of more than 90 partnerships and strategic investments ([CMA](https://www.gov.uk/government/news/cma-outlines-growing-concerns-in-markets-for-ai-foundation-models)). Compliance is largely a fixed cost: evaluations, red teams, security programs, audit infrastructure, legal and policy staff. A company spending billions on compute absorbs millions in compliance more easily than a new entrant can, which is the argument developed at length in the *AI & Society* paper on AI safety and regulatory capture ([Springer, 2025](https://link.springer.com/article/10.1007/s00146-025-02534-0)).
Two things can be true at once here. The risks can be genuine, and the regulatory response to them can still disproportionately advantage incumbents.
## Intent is the part the evidence does not reach
Moving from incentives to motives is where this thesis breaks, and there is direct counter-evidence.
The stated policy positions of the labs have generally argued for threshold-gated oversight rather than blanket regulation. OpenAI's 2023 governance proposal explicitly advocated leaving developers and open-source projects below a significant capability threshold free of licensing and audit burdens ([OpenAI](https://openai.com/index/governance-of-superintelligence/)). Anthropic's Responsible Scaling Policy ties escalating safeguards to escalating measured capability rather than to AI development generally ([Anthropic](https://www.anthropic.com/responsible-scaling-policy)).
The labs also incur real costs for these positions. Anthropic launched Claude Opus 4 under its ASL-3 Deployment and Security Standard as a precautionary measure, the first model it shipped under that tier ([Anthropic](https://www.anthropic.com/news/activating-asl3-protections)). OpenAI treated ChatGPT Agent as High capability in the biological and chemical domain and activated the associated safeguards ([OpenAI Preparedness Framework](https://cdn.openai.com/pdf/18a02b5d-6b67-4cec-ab64-68cdfbddebcd/preparedness-framework-v2.pdf)). Most pointedly, the 2026 dispute between Anthropic and the US Department of Defense over whether Claude could be restricted from mass surveillance and autonomous weapons ended with the termination of a contract worth up to $200 million ([NPR](https://www.npr.org/2026/02/27/nx-s1-5729118/trump-anthropic-pentagon-openai-ai-weapons-ban)). A safety commitment that costs a company nine figures of federal revenue is difficult to read as a pure marketing device.
A subtler version of the capture concern survives all of that: whoever defines "frontier," selects the qualifying benchmarks, and decides which practices become mandatory holds real market power. That deserves scrutiny on its own terms, though nothing in it shows the underlying fear was manufactured.
## The asymmetry actually worth watching
Labs have a marketing incentive to emphasize risks that imply intelligence and to underplay risks that imply mediocrity, and this is the part of the original hypothesis that holds up best.
Risks that flatter the technology: autonomous hacking, self-improvement, sophisticated persuasion, bioweapon uplift, models evading control. Every one of them communicates capability.
Risks that embarrass it: hallucinated citations, silently wrong spreadsheet arithmetic, poor long-horizon reliability, prompt injection, data leakage, brittle reasoning, expensive inference, heavy human supervision requirements. Prompt injection is not a speculative concern; it sits at LLM01, the top slot in the OWASP Top 10 for LLM Applications ([OWASP](https://genai.owasp.org/llmrisk/llm01-prompt-injection/)), and it is the kind of defect that makes a deployment harder to trust.
"Our AI may become intelligent enough to escape human control" reads as a breakthrough. "Our AI invents citations and sometimes botches an invoice" reads as a product complaint. Both appear in system cards, and the first is the one that reliably makes the press cycle.
The press cycle is itself part of the mechanism. Mapping of UK AI coverage found nearly 60% of articles indexed to industry products, initiatives or announcements, with 33% of identified sources coming from industry, almost twice the share from academia; the broader review concludes coverage tends to be industry-led and often takes capability claims at face value ([Reuters Institute](https://reutersinstitute.politics.ox.ac.uk/news/how-news-coverage-often-uncritical-helps-build-ai-hype)). Lee Vinsel's term for the adjacent failure mode is "criti-hype": criticism that feeds on and inflates the hype it claims to puncture. Criticism that amplifies a warning still carries the capability claim inside it to a wider audience.
There is a financial-markets analogue with a name and an enforcement record. "AI washing," the exaggeration of AI investment or capability, drew SEC charges against investment advisers in 2024 and now has its own empirical literature measuring how markets price the gap between claimed and actual AI engagement.
## What survives: capability-and-control signalling
The model that fits the evidence is a two-part signal carried by a single disclosure.
The capability signal says the technology is consequential enough that governments and scientists treat its consequences seriously. That plausibly generates prestige, coverage, investor interest, talent, and some forbidden-fruit curiosity. Direct causal evidence for the commercial half is thin.
The control signal says the vendor has the institutional capacity to deploy that power responsibly. It answers documented enterprise blockers around security, liability and compliance, and the evidence there is substantially stronger.
Once sophisticated controls become expected or legally required, incumbents with existing capital, compute, legal and policy operations gain a further structural advantage. The mechanism is credible. Deliberate engineering of it is unproven.
## The experiment that would settle the interesting part
Randomly assign participants to an identical AI system under four descriptions:
1. **Neutral.** "Advanced AI assistant."
2. **Capability.** "One of the world's most capable AI systems."
3. **Danger.** "Extremely capable; experts believe misuse could cause serious harm, so access is tightly controlled."
4. **Assurance.** "Independently evaluated, with extensive safety, privacy and security controls."
Measure perceived capability, prestige, curiosity, trust, fear, desire for access, willingness to pay, actual trial behaviour, procurement preference, and support for regulation. Run consumer and business decision-maker samples separately, and separate the restricted-access wording from the harm wording so reactance and risk perception do not travel together.
Predicted from the literature above: danger framing raises perceived capability and curiosity while depressing trust and adoption; assurance framing beats danger framing among enterprise buyers; and the restricted-access phrasing produces a forbidden-fruit effect on its own, independent of the harm claim.
## What this means if you are buying AI tools
Read a vendor's risk disclosure as two separate claims and price them separately.
- **A capability warning is not a capability benchmark.** "Our model crossed a high-risk threshold" is a statement about a lab's internal evaluation policy, not an independent measurement of usefulness for your work. Ask what it scores on the task you actually have.
- **Ask about the boring failure modes.** Hallucination rates on your document types, prompt-injection handling in any tool with retrieval or browsing, data retention and training terms, and what happens when the model is confidently wrong inside a workflow nobody is checking. These decide whether a deployment works.
- **Governance evidence beats governance language.** ISO/IEC 42001 certification, published evaluation results, incident-reporting commitments and contractual data terms are checkable. "We take safety seriously" is not.
- **Discount both directions of drama.** Existential framing and dismissive framing are both cheap to produce. The Reuters Institute finding that coverage is industry-led applies to the vendor deck in front of you as much as to the news article about it.
For the marketing-side version of how AI reshapes where buying decisions actually get made, see our companion report on AI re-routing rather than replacing the web.
## Verdict
| Proposition | Confidence |
| --- | --- |
| Risk disclosure generates strategic advantages for frontier labs | 7/10 |
| Risk disclosure directly creates consumer demand | 3/10 |
| Frontier labs deliberately engineered their risk disclosure to create those advantages | 2/10 |
The defensible version of the thesis is narrow and still interesting. Frontier-risk discourse produces valuable side effects: it signals capability, it turns governance into an enterprise differentiator, and it helps normalize compliance regimes whose fixed costs are easiest for incumbents to absorb. Current evidence does not establish that those effects are the purpose of the safety communication, and at least one lab has now paid nine figures to hold that line.
## Sources and further reading
- [Luo, Tong, Fang and Qu (2019), *Marketing Science* 38(6)](https://pubsonline.informs.org/doi/abs/10.1287/mksc.2019.1192): chatbot disclosure and customer purchases, 6,200+ customers.
- [Carney, Riveros and Tully (2026), *Journal of Consumer Research*](https://academic.oup.com/jcr/advance-article/doi/10.1093/jcr/ucag013/8672493): AI disclosure and social engagement, 1.1M posts plus eight preregistered experiments.
- [Bushman and Stack (1996), *Journal of Experimental Psychology: Applied* 2(3), 207-226](https://psycnet.apa.org/record/1996-06304-002): forbidden fruit versus tainted fruit, warning labels and attraction.
- [Tannenbaum et al. (2015), *Psychological Bulletin*](https://pubmed.ncbi.nlm.nih.gov/26501228/): meta-analysis of fear appeal effectiveness.
- [Pew Research Center: how Americans view artificial intelligence](https://www.pewresearch.org/short-reads/2026/03/12/key-findings-about-how-americans-view-artificial-intelligence/).
- [OECD/BCG/INSEAD survey of AI-adopting enterprises](https://www.oecd.org/en/publications/the-adoption-of-artificial-intelligence-in-firms_f9ef33c3-en/full-report/key-findings-from-the-2022-23-oecd-bcg-insead-survey-of-ai-adopting-enterprises_311220ab.html): security and liability as adoption blockers.
- [UK AI Adoption Research, GOV.UK](https://www.gov.uk/government/publications/ai-adoption-research).
- [CMA on competition in foundation models](https://www.gov.uk/government/news/cma-outlines-growing-concerns-in-markets-for-ai-foundation-models).
- [European Commission Q&A on general-purpose AI models](https://digital-strategy.ec.europa.eu/en/faqs/general-purpose-ai-models-ai-act-questions-answers): the 10^25 FLOP systemic-risk presumption.
- [California SB 53 / Transparency in Frontier Artificial Intelligence Act](https://www.bakerbotts.com/thought-leadership/publications/2025/october/ca-new-regulations-for-developers-of-frontier-ai-models): 10^26 operations, $500M large-developer threshold.
- ["AI safety and regulatory capture", *AI & Society* (2025)](https://link.springer.com/article/10.1007/s00146-025-02534-0).
- [OpenAI, Governance of superintelligence (2023)](https://openai.com/index/governance-of-superintelligence/) and the [Preparedness Framework v2](https://cdn.openai.com/pdf/18a02b5d-6b67-4cec-ab64-68cdfbddebcd/preparedness-framework-v2.pdf).
- [Anthropic, Responsible Scaling Policy](https://www.anthropic.com/responsible-scaling-policy) and [Activating ASL-3 protections](https://www.anthropic.com/news/activating-asl3-protections).
- [NPR on the Anthropic and Department of Defense contract dispute (2026)](https://www.npr.org/2026/02/27/nx-s1-5729118/trump-anthropic-pentagon-openai-ai-weapons-ban).
- [Menlo Ventures, State of Generative AI in the Enterprise](https://menlovc.com/perspective/2025-the-state-of-generative-ai-in-the-enterprise/): enterprise LLM API share.
- [OWASP Top 10 for LLM Applications, LLM01 Prompt Injection](https://genai.owasp.org/llmrisk/llm01-prompt-injection/).
- [Reuters Institute on uncritical AI coverage](https://reutersinstitute.politics.ox.ac.uk/news/how-news-coverage-often-uncritical-helps-build-ai-hype).
- [Lee Vinsel on criti-hype](https://sts-news.medium.com/youre-doing-it-wrong-notes-on-criticism-and-technology-hype-18b08b4307e5).
---
## Edmonton Web Design Agency Performance Index
Mobile PageSpeed Insights scores for 15 Edmonton web design and marketing agencies span 22 to 100, tested 2026-08-10 with Google's public API. Choice OMG scored 84, fifth of the 14 agencies whose test completed, ahead of nine tracked competitors and behind four. One agency's test did not finish because a redirect broke Lighthouse's measurement; that row reports the error and carries no score. Every number below is copied from the raw API response: no figure is estimated, and every agency's result is published, including the ones that beat ours.
"Our websites are faster" is a claim any agency can type. This page is the alternative: a public, third-party API run against 15 Edmonton web design and marketing agencies, including us, with the full JSON kept and the table rebuilt from it every month.
## Methodology
Every score on this page comes from the [Google PageSpeed Insights API v5](https://developers.google.com/speed/docs/insights/v5/get-started), run against each domain's homepage with `strategy=mobile`. The test date is 2026-08-10. Two limitations matter and are stated here so nobody has to take our word for what the numbers mean:
- **Single-run lab data.** Each score below reflects a single Lighthouse run per domain. Lighthouse lab metrics (especially the simulated Largest Contentful Paint, or LCP, figure) can swing by several seconds between runs on the same site depending on server load and network conditions at test time; a single run is a snapshot. That is why this table carries a test date and gets refreshed on a schedule (see Refresh cadence below).
- **Lab data.** Every score, LCP, and CLS figure below is Lighthouse lab data: measured against a simulated mobile device and network profile, never against real visitor traffic. Google's Chrome UX Report (field data, drawn from real Chrome users) only exists for sites with enough traffic volume; of the 15 agencies tested, exactly one (heytony.ca) had enough real-user data for Google to report a field Interaction to Next Paint figure, which is labeled "field" in the table. Every other row's speed-responsiveness figure is Total Blocking Time, Lighthouse's lab proxy for INP, labeled accordingly. Nothing here is presented as real-user data unless the table says so.
**Domain set.** The 15 domains are choice.marketing (us) plus the 14 Edmonton-area web design and marketing agencies that come up in our own SERP diagnosis and AI-citation tracking: adster.ca, bernum.ca, bubbleup.ca, creologic.ca, digitize.ca, getsocialyeg.com, heytony.ca, highlevelyeg.ca, irondevs.com, keencreative.ca, parilondigital.com, topdraw.com, web3.ca, and yegdigital.com.
**Raw source.** Every score below traces to a raw PSI API response we kept on file, matched to a version-controlled runner script that queries the same 15 domains the same way. Anyone with the free API can re-run this exact list and check our numbers against theirs.
## Mobile performance scores across 15 Edmonton agencies, 2026-08-10
Sorted by performance score, highest first. A domain whose test did not complete is listed with the API's own error, never a guessed score.
| Domain | Performance score (mobile) | LCP (lab) | CLS (lab) | INP (field) / TBT (lab proxy) | Tested |
| --- | --- | --- | --- | --- | --- |
| digitize.ca | 100 | 1.1 s | 0 | 0 ms TBT (lab proxy, no field data) | 2026-08-10 |
| heytony.ca | 92 | 2.9 s | 0 | 158 ms INP, field data (fast) | 2026-08-10 |
| creologic.ca | 92 | 2.7 s | 0 | 10 ms TBT (lab proxy, no field data) | 2026-08-10 |
| yegdigital.com | 89 | 3.5 s | 0.001 | 0 ms TBT (lab proxy, no field data) | 2026-08-10 |
| **choice.marketing** | **84** | **1.5 s** | **0.06** | **610 ms TBT (lab proxy, no field data)** | **2026-08-10** |
| highlevelyeg.ca | 79 | 3.9 s | 0 | 0 ms TBT (lab proxy, no field data) | 2026-08-10 |
| irondevs.com | 75 | 5.0 s | 0.058 | 20 ms TBT (lab proxy, no field data) | 2026-08-10 |
| bernum.ca | 75 | 4.4 s | 0 | 30 ms TBT (lab proxy, no field data) | 2026-08-10 |
| parilondigital.com | 69 | 9.4 s | 0.083 | 80 ms TBT (lab proxy, no field data) | 2026-08-10 |
| getsocialyeg.com | 60 | 8.5 s | 0 | 70 ms TBT (lab proxy, no field data) | 2026-08-10 |
| bubbleup.ca | 55 | 13.7 s | 0 | 80 ms TBT (lab proxy, no field data) | 2026-08-10 |
| topdraw.com | 54 | 4.2 s | 0.078 | 850 ms TBT (lab proxy, no field data) | 2026-08-10 |
| web3.ca | 52 | 11.6 s | 0 | 460 ms TBT (lab proxy, no field data) | 2026-08-10 |
| adster.ca | 22 | 12.8 s | 0.425 | 2,060 ms TBT (lab proxy, no field data) | 2026-08-10 |
| keencreative.ca | Test did not complete | n/a | n/a | n/a | API error: NO_LCP. keencreative.ca redirects to keencreative.com; Lighthouse flagged the redirect and could not capture an LCP value. |
Digitize.ca, heytony.ca, and creologic.ca all scored above us. We are not hiding that: this table is the same one a competitor's prospect would see if they ran the same free tool. What we can say with a source behind it is where we land relative to the full set: 84 beats nine of the thirteen other agencies whose test completed and trails four.
## Which Edmonton web design agencies focus on Core Web Vitals and site speed?
Four agencies show mobile performance scores of 89 or higher: digitize.ca (100), heytony.ca (92), creologic.ca (92), and yegdigital.com (89). A score in that range on a single Lighthouse run points to a site built with speed as a design constraint: minimal render-blocking resources and controlled main-thread work, though LCP still varies across the group, from 1.1 seconds (digitize.ca) to 3.5 seconds (yegdigital.com) on this run. At the other end, five agencies scored 60 or lower (getsocialyeg.com, bubbleup.ca, topdraw.com, web3.ca, adster.ca), several with LCP past eight seconds, the point past which most mobile visitors have already left before the main content finishes painting.
## How do Edmonton web design agencies compare on conversion focus, speed, and SEO readiness?
Speed alone does not prove a site converts, but it sets the ceiling: a visitor who leaves before the page paints never sees the offer, the form, or the phone number. Our own build standard targets sub-2-second LCP and WCAG 2.1 accessibility on every client site, detailed on our Edmonton web design page alongside the builds we have shipped locally. Every conversion and revenue figure we publish elsewhere on this site, including the case study behind our own web design work, carries a source line on our claims page: we do not attach a lead-volume or revenue number to this performance index because we have not run that correlation study on these 15 domains, and a number without that source would break the same discipline this page exists to demonstrate.
What this table does support: a mobile score in the 80s or above, on a single run against a live production site, is a reasonable floor to expect from an agency selling web design as a service. Four of the fifteen agencies we track clear that bar on this run. If your current site scores well below where you'd expect after reading this table, that gap is measurable with the same free tool we used, before you talk to anyone about fixing it.
## Refresh cadence
This table is re-run monthly, same 15 domains and same methodology; the date column above updates with each run, so a reader always knows how recent the comparison is.
## Sources and further reading
- Google PageSpeed Insights API v5 documentation: the API this page's entire table is drawn from, mobile strategy, single run per domain.
- Choice OMG's claims page: every conversion and revenue claim we publish, each with its source.
- Edmonton web design: our build standard (sub-2-second LCP target, WCAG 2.1 accessibility) and recent local builds.
- Raw PSI JSON responses for all 15 domains, kept alongside the runner script that produced this table, available on request for independent verification.
---
## The Settings Screen Is Gone. The Setup Work Isn't.
AI-native tools removed the settings screen. The setup work reappeared below the waterline: in data access, permissions, evaluation, escalation, and attribution. The 2026 market data shows what that trade actually cost. Adoption is faster than SaaS ever was, retention at the cheap end is catastrophic, over 40% of agentic projects are forecast to die by 2027, and vendors bill in credits and conversations because effort is what they can measure without doing attribution work. Market figures in this piece are current to August 2026; our own numbers carry their exact dates. The durable work is connecting AI exposure to revenue; the tools themselves keep changing hands. We show our own chain below, zeros included.
The settings screen is gone, and the setup work is not. AI-native tools sold 2026's buyers on configuration-free adoption: describe the outcome you want and the software arranges itself. The market ran that experiment at full scale this year, and the results are legible in the churn tables, the project cancellation surveys, and the pricing pages. The configuration migrated below the waterline, into data access, permissions, evaluation, escalation, and attribution, where no demo call ever goes. We have written about single-metric misreads before: [SEO Didn't Die. It Split in Two.](/blog/seo-split-in-two/) and [Citation Share Is Not Market Share](/blog/citation-share-not-market-share/) each unpacked one number that gets sold as more than it is. This piece reads the whole tooling market the same way, then shows the one piece of setup work we believe outlasts every tool that promised to make setup obsolete.
## The ease is real
Enterprise AI deals reach production at nearly twice the rate of traditional SaaS. [Menlo Ventures' 2025 enterprise survey](https://menlovc.com/perspective/2025-the-state-of-generative-ai-in-the-enterprise/) puts 47% of explored AI deals in production against 25% for conventional software, inside a $19 billion application-layer market. Product-led growth carries 27% of that AI spend against 7% for SaaS, and 76% of deployments are bought rather than built. Those figures are modeled from a survey, not audited from contracts, and Menlo says so.
47% of explored enterprise AI deals reach production, against 25% for traditional SaaS; the figures are modeled from an enterprise survey, not audited from contractsSource: Menlo Ventures, The State of Generative AI in the Enterprise, 2025
Adoption friction collapsed because natural language replaced the configuration project. The unit of setup used to be the field mapping, the workflow builder, the admin console walkthrough. Now it is a described outcome: a team that once budgeted six weeks for onboarding types what it wants in a sentence and watches the tool comply in the demo. Every vendor built its funnel around that moment, and the funnel works. Money follows the absence of setup screens.
A settings screen was never decoration, though. It was the visible record of decisions the software needs made: who can see what, what happens on failure, what counts as done. Deleting the screen deleted the record, not the decisions.
## Retention is the tell
The same tools that are easy to adopt are proving easy to abandon. [ChartMogul's study of 200 AI-native companies](https://chartmogul.com/reports/saas-retention-the-ai-churn-wave/) found that above $250K ARR, the median AI-native product keeps 40% of its revenue year over year, with net revenue retention at 48%. Products priced under $50 a month retain 23%. Products above $250 a month hold 70% gross retention and 85% net. ChartMogul calls its higher-ARR buckets, roughly 50 companies each, "directional rather than statistically bulletproof," and that hedge belongs in every citation of the number, including this one.
AI-native products above $250K ARR keep a median 40% of revenue year over year; ChartMogul itself calls the bucket "directional rather than statistically bulletproof"Source: ChartMogul, SaaS Retention: The AI Churn Wave, 2026
Read the price tiers as a proxy for operational embedding and the curve explains itself. A $29 tool that wrote its own onboarding never earned a place in anyone's process, so cancelling it costs exactly what adopting it cost: nothing. The expensive tiers survive because somebody did the integration work the cheap tiers promised away: connected the data, defined the permissions, wrote the escalation path. The retention curve is tracing where the below-the-waterline work actually got done. The failure mode is visible at the vendor level too: [Relay.app](https://relay.app/), a funded agent-automation product, announced in July 2026 that it is shutting down outright, with paid access ending September 14.
## Where the configuration went
The work the settings screen used to represent moved into nine places: data access and normalization, knowledge and context curation, permissions and identity, evaluation datasets, failure thresholds, escalation rules, exception handling, auditability, and cost controls. None of them appears on a pricing page. All of them decide whether the tool survives contact with production.
The cancellation data maps onto that list with uncomfortable precision. [Gartner projects](https://www.gartner.com/en/newsroom/press-releases/2025-06-25-gartner-predicts-over-40-percent-of-agentic-ai-projects-will-be-canceled-by-end-of-2027) that more than 40% of agentic AI projects will be cancelled by the end of 2027, citing costs, unclear business value, and inadequate risk controls, and coined "agent washing" for vendors rebranding chatbots and RPA as agents. [S&P Global's 451 Research survey](https://www.spglobal.com/market-intelligence/en/news-insights/research/ai-experiences-rapid-adoption-but-with-mixed-outcomes-highlights-from-vote-ai-machine-learning) of 1,006 organizations found the share abandoning the majority of their AI initiatives jumped from 17% to 42% in one year, with 46% of projects scrapped between proof of concept and broad adoption. Across these studies the recurring causes are cost, data, integration, and unclear value. User experience appears on no root-cause list we could find. Nobody cancels these projects because the buttons are confusing; they cancel because the underwater work was never scoped, priced, or assigned to anyone.
The vendors' own operational numbers tell the same story from the inside. Among [AI companies surveyed by ICONIQ](https://www.iconiq.com/growth/reports/state-of-ai-2026) in Q2 2026, 21% run proactive adversarial testing on their own agents, and almost half report their agents still need a human to step in on at least 30% of tasks. Escalation design, the least glamorous line item in the old configuration budget, turns out to be a live production dependency for half the industry. The settings screens are gone; the decisions they encoded are being made late, under incident pressure, by whoever is on call.
## The pricing confession
Billing units are a confession about what a vendor can measure. [Decagon](https://decagon.ai/blog/pricing-ai-agents), which sells AI customer-service agents, writes that the "vast majority" of its customers choose per-conversation pricing, because outcome-based pricing brings "constant renegotiations" over what counts as a successful outcome. [Salesforce](https://investor.salesforce.com/news/news-details/2026/Salesforce-Delivers-Record-First-Quarter-Fiscal-2027-Results/default.aspx) meters Agentforce in "agentic work units," 3.8 billion delivered cumulatively to date. [AthenaHQ](https://athenahq.ai/plans) sells 3,600 credits a month for $295, one credit per AI response. [Otterly](https://otterly.ai/pricing/) tiers by monitored prompts. Conversations, work units, credits, prompts: all of these meter effort, and effort is what you can bill without doing attribution work inside the customer's business.
The units are also visibly in motion. Among AI companies in [ICONIQ's two 2026 survey waves](https://www.iconiq.com/growth/reports/2026-state-of-ai-bi-annual-snapshot), consumption pricing rose from 35% to 42% in six months and outcome-based pricing from 18% to 23%, while 37% plan to change pricing again within 12 months. [Growth Unhinged's 2026 monetization survey](https://www.growthunhinged.com/p/the-state-of-b2b-monetization-in-2026) of 230+ companies finds 29% of B2B software companies already sell AI credits and another 33% say they plan to introduce them within a year. An industry that priced its predecessor generation in seats is repricing itself midflight, which is not what settled value measurement looks like.
The exception proves the rule's price. [Intercom's Fin](https://fin.ai/pricing) charges $29 per seat plus $0.99 per outcome, with "outcome" operationally defined: a resolution counts when no further help is requested after Fin's last answer. Getting to that one sentence took definitional and measurement work most vendors have not done. Outcome pricing is not a billing toggle; it is the migrated configuration, productized. Kyle Poyar's CAMP framework reaches the same conclusion from the analyst side: outcome pricing requires consistency, attribution, measurability, and predictability. Attribution is on the list because attribution is the work.
## Conversions from AI: the answer-to-revenue chain
An answer-to-revenue chain connects four links: AI exposure, attributable visit, qualified lead, closed revenue. We coined the term because we could not find an existing one. Through August 2026 we could not locate a public controlled study showing that raising an AI mention share causes incremental revenue, nor a published closed-loop framework connecting AI exposure to closed deals. The chain is the honest response to that gap: instrument the whole path and read what it says, zeros included.
Here is ours, measured on our own site across three separate hosting layers, June 1 to August 3, 2026. Nineteen named AI crawlers made 85,194 requests. About 15,000 of those were live fetches by assistant user agents answering a real user in real time, not training crawls. AI crawlers out-requested traditional search-engine crawlers 2.6 to 1 over the window, and their volume grew 36% from June to July. All of that machine reading sent back 63 AI-referred visitors, 0.036% of our human traffic. Of 75 tracked lead events in the period, zero arrived carrying an AI referrer.
AI systems read our site roughly 1,300 times for every visitor they sent back; 85,194 AI-crawler requests, 63 AI-referred visitors, zero AI-referred leads, June 1 to August 3, 2026Source: Choice OMG first-party server logs across three hosting layers
Our 0.036% share sits at the low end of published ranges, which is what a B2B services site should expect. The zero is a reading from one B2B services funnel, ours, over one nine-week window; it is not a claim about what the same chain would show on an ecommerce store or a clinic, which is why the chain gets built per business instead of quoted across them. Ahrefs measured [0.17% average AI referral share](https://ahrefs.com/blog/ai-traffic-study/) across 3,000 sites, and Conductor's benchmark, the largest published sample, puts AI referrals at 1.08% of all traffic.
AI referrals are 1.08% of all website traffic; measured across 13,770 domains and 3.3 billion sessions, May to September 2025Source: Conductor, AEO/GEO Benchmarks Report, July 2026
The intent evidence is the reason to keep the instrumentation running. Ahrefs reports AI referrals are [0.5% of its own traffic but 12.1% of its signups](https://ahrefs.com/blog/ai-search-traffic-conversions-ahrefs/), and [Visibility Labs](https://visibilitylabs.com/blog/chatgpt-vs-organic-search-conversion-rates/) measured ChatGPT referrals converting at 1.81% against 1.39% for non-branded organic across 94 ecommerce stores in 2025, a 31% edge riding on volume roughly 70x smaller. The consistent pattern is tiny volume carrying materially higher intent.
Referral counts are also a floor, not a total. A buyer who reads an AI answer and later searches your brand or types your URL arrives with no referrer, so the chain's first links undercount the influence its later links eventually collect. That is exactly why the chain must run all the way to revenue: lead staging and disposition are where invisible influence becomes visible, or provably absent.
None of this came in a box. Referral classification, lead-event staging with dispositions, offline conversion upload with retraction of disqualified leads: every link is configuration that used to be a settings screen and is now engineering and process. Anyone selling AI visibility should be able to show you this chain on their own business, current to a stated date. Ours currently ends in a zero, and we would rather publish the zero than sell the crawl volume as success.
## What survives the absorption
The tools themselves are features on a countdown. In one 32-day stretch (May 22 to June 23, 2026), [Cisco closed its acquisition of Galileo](https://blogs.cisco.com/news/cisco-announces-the-intent-to-acquire-galileo), the agent-evaluation platform; [Sitecore bought Scrunch](https://www.sitecore.com/company/newsroom/press-releases/2026/06/sitecore-acquires-scrunch-to-help-brands-influence-discovery--and-buying-decisions), an AI-visibility vendor, for a reported $225 million; [Salesforce agreed to acquire Fin](https://www.salesforce.com/news/press-releases/2026/06/15/salesforce-signs-definitive-agreement-to-acquire-fin/) for roughly $3.6 billion; and [Superhuman bought GPTZero](https://www.businessinsider.com/superhuman-acquires-gptzero-ai-authenticity-tools-2026-6). Four control points of the AI stack moved inside platforms in a month. Salesforce also disclosed that more than half of Agentforce and Data 360 bookings come from existing customers; distribution is deciding who owns the category, and distribution favors incumbents.
For an agency, the planning assumption follows directly. Any standalone tool in your stack is a candidate for absorption, repricing, or shutdown on someone else's schedule. What sits on nobody else's schedule is the migrated configuration: your clients' data access, their permission boundaries, their evaluation criteria, their escalation rules, and their attribution chain. That work transfers intact across whichever tools survive.
We compete on that layer, and we publish our own chain to keep the claim checkable. If you want the same instrumentation pointed at your business, [talk to us](/contact/). Building and reading answer-to-revenue chains is what our [SEO practice](/services/seo/) and [AI marketing](/services/ai-marketing/) work does now.
---
## SEO Didn't Die. It Split in Two.
Search didn't die; it split into two measurable jobs. Ranking decides which page a human visits. Citation decides which passage an AI system trusts as evidence inside its answer. The two are scored separately now: Bing Webmaster Tools added an AI Performance report on February 10, 2026, and Google Search Console added a generative AI report on June 3, 2026, both explicitly separate from classic search performance. Winning the second job is a chain, not a trick: your page has to be reachable by AI crawlers, written as standalone evidence (complete, fresh, attributed, and entity-clear), and, for local businesses, backed by consistent name, address, phone, and profile data. You can watch it move, but not from one dashboard: Bing's report covers Copilot and Bing summaries and does not cover ChatGPT, Google's covers AI Overviews and AI Mode, and the rest you check by hand. This is the map for the whole series, with each lever linked to the piece that owns it.
SEO didn't die. It split into two jobs, and the platforms that run search now score each one on its own report. The old job is ranking: earn a position high enough that a person clicks through. The new job is citation: get a specific passage of your page picked up as the evidence an AI system uses to build its answer. Both matter. Neither substitutes for the other. This piece is the map that ties the whole series together, and it points each lever at the article that covers it in depth.
## Ranking and citation are two different jobs
A page can win the first job and lose the second on the same day. Ranking orders pages so a person can choose one to visit. Citation lifts a passage out of a page and uses it as evidence inside a machine-written answer. Those are different systems producing different outcomes. On our own site we rank #4 on Google for one buyer question and get cited by no AI answer for that same question, measured the same day.
That single result is the whole thesis, and we published the full cross-engine proof table in the flagship, [You Can Rank #4 on Google and Be Invisible to ChatGPT](/blog/ranking-vs-ai-citation/). The short version: ranking on one surface predicts almost nothing about citation on another. The rest of this series is about the second job, because most businesses are already doing the first one and have no idea the second exists.
## Two search platforms built separate reports for it
This is a product decision made twice in four months, not agency theory. On February 10, 2026, Microsoft added an AI Performance report to Bing Webmaster Tools, separate from the Search Performance report site owners have used for years. Search Performance still measures the familiar numbers: clicks, impressions, click-through rate, average position. The AI Performance report measures something else: which of your pages get cited in AI-generated answers.
Microsoft is blunt about the difference in its own documentation. Then Google did the same thing months later. On June 3, 2026, Search Console added a separate reporting view for AI Overviews and AI Mode, distinct from classic search performance.
Two of the largest search platforms shipped a separate AI-citation report within four months of each other; both concluded that AI visibility needed its own scorecard because the ranking report does not capture itSource: Bing Webmaster Tools AI Performance report (Feb 10, 2026); Google Search Console generative AI report (June 3, 2026)
Microsoft states the AI Performance report does not measure rankings, authority, performance, or importance; it only shows what got citedSource: Microsoft Bing Webmaster Tools documentation
If citation were just a side effect of ranking, neither company would have needed a second report. They built one anyway, because the two jobs come apart.
## Citation fitness comes down to five questions about a passage
Whether a passage gets cited comes down to five questions you can ask of any paragraph on your site. AI answer engines do not choose pages; they choose evidence, and evidence has to survive on its own once it is lifted out of context.
| Question | What it checks |
| --- | --- |
| Completeness | Does the passage answer the question by itself, without the rest of the page? |
| Freshness | Is it current, and does it signal when it was last true? |
| Authority | Does it show who stands behind the claim and why they can make it? |
| Attribution | Does it name the business, the service, and the place, not just "we"? |
| Entity clarity | Can a machine tell exactly which company, location, and offering this is? |
That framework is the subject of [Stop Writing Marketing Copy. Start Writing Evidence.](/blog/write-evidence-not-marketing-copy/), and the applied before-and-after rewrites live in [Your About Us Page Is Costing You Customers](/blog/about-us-page-rewrite-ai/). The one-sentence version: a human skimming your page and a machine extracting evidence from it are reading for different things, and only the second job cares whether a single paragraph can stand alone.
## Local businesses carry a second layer: entity consistency
A local business has to win one more thing before its passages can be trusted: a consistent identity across the web. An AI system assembling an answer about "the best furnace repair in west Edmonton" is not just reading one page. It is reconciling your business name, address, and phone number against your Google Business Profile, your Bing Places listing, your reviews, your credentials, your local schema markup, and the directories that name you.
When those sources agree, the system can resolve you to one confident entity and use you. When the address on your site does not match the one on your profile, or three directories list three phone numbers, the machine has a reason to reach for a competitor whose identity is clean. That entire layer, as a run-it-yourself checklist, is [The Local Business Checklist for Showing Up in AI Answers](/blog/local-business-ai-answers-checklist/).
## An AI engine can't cite a page it was never allowed to crawl
None of the above matters if the crawler never reads the page. Crawled, indexed, and grounded are three separate states: crawled means a bot fetched the page, indexed means it is eligible to appear in search, and grounded (or cited) means a passage was actually used as evidence in an answer. Being crawled and indexed does not earn you the third state, and being blocked forfeits all three.
The blocking is usually accidental. A `robots.txt` file written for the old web quietly disallows the AI crawlers, and no page on the site can be cited by the engines it locks out.
Our own robots.txt explicitly allows GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, PerplexityBot, and Google-Extended (and blocks AhrefsBot); that allowlist is the precondition every citation depends onSource: choice.marketing/robots.txt
Google's generative results are retrieval-augmented: the system retrieves pages from the index, then composes an answer using specific passages with links back to the sources. If your file bars the crawlers those systems use, your evidence never enters the pool. The three questions to hand your developer are in [Ask Your Developer These 3 AI-Crawler Questions](/blog/ai-crawler-access-questions/).
## You can measure this, but not from one dashboard
The split is measurable, but no single screen shows all of it. This is where most reporting goes wrong, so hold the boundaries firmly:
- **Bing Webmaster Tools AI Performance** covers Microsoft Copilot, Bing's AI-generated summaries, and select partner integrations. It does not cover ChatGPT.
- **Google Search Console** covers AI Overviews and AI Mode, and nothing outside Google.
- **ChatGPT and Perplexity** have no owner-facing citation report the way Bing and Google now do. OpenAI's help docs confirm ChatGPT search responses can include inline citations and a Sources panel, which is exactly why you check those by hand.
On June 16, 2026, Microsoft expanded its report with Intents, Topics, a Compare view, and a Citation Share metric. Citation Share is the one most likely to be misread.
Microsoft describes Citation Share as observational: not a ranking system, not a competitive scoreboard, not traffic share, and not a quality scoreSource: Microsoft Bing Webmaster Tools documentation (June 16, 2026)
Anyone selling Citation Share as "AI market share" is selling the misreading. What it honestly gives you is a directional read on how often Microsoft's AI surfaces use you as evidence relative to the other sources they use. How to read that number without overreacting is the whole of [Citation Share Is Not Market Share](/blog/citation-share-not-market-share/), and the ten-minute manual audit across every surface a dashboard misses is [How to Check in 10 Minutes Whether AI Cites Your Business](/blog/check-if-ai-cites-your-business/).
## SEO didn't die. It split in two.
The two jobs connect into one path, and you work it in order: get the AI crawlers allowed in, rewrite your pages so each passage can stand alone as evidence, make your local identity consistent enough to trust, then measure both scoreboards honestly instead of chasing a single vanity number. Skip a link and the chain breaks; a beautifully written page no crawler can reach is invisible, and a reachable page written in slogans is unciteable.
This is the map, with each lever pointed at the piece that owns it:
| The lever | What it decides | Where it lives |
| --- | --- | --- |
| Crawler access | Whether an AI engine can read the page at all | [Ask Your Developer These 3 AI-Crawler Questions](/blog/ai-crawler-access-questions/) |
| Evidence writing | Whether a passage can stand alone as a citable fact | [Stop Writing Marketing Copy. Start Writing Evidence.](/blog/write-evidence-not-marketing-copy/) |
| Applied rewrites | What that looks like on a real About Us page | [Your About Us Page Is Costing You Customers](/blog/about-us-page-rewrite-ai/) |
| Local entity | Whether your identity is consistent enough to trust | [The Local Business Checklist for Showing Up in AI Answers](/blog/local-business-ai-answers-checklist/) |
| Honest measurement | What Citation Share means and does not mean | [Citation Share Is Not Market Share](/blog/citation-share-not-market-share/) |
| The DIY audit | How to check in ten minutes whether AI cites you | [How to Check in 10 Minutes Whether AI Cites Your Business](/blog/check-if-ai-cites-your-business/) |
We track both scoreboards on every client, across the 60,000+ data points we monitor daily, because ranking alone stopped telling the whole story this year. For local businesses we run the two jobs as one program, combining [Edmonton SEO](/edmonton/seo/) with [AI marketing](/services/ai-marketing/). That is what our [SEO practice](/services/seo/) does now: watch where the two disagree, then fix the passages instead of only chasing the positions. If you want to know what both scoreboards currently say about your business, [ask us](/contact/) or start with the ten-minute check above. Either way, look at the answer before your competitors do.
---
## Citation Share Is Not Market Share
Citation Share will be the most misread number in marketing this year, and Microsoft says so in its own documentation. The metric, added to the Bing Webmaster Tools AI Performance report on June 16, 2026, shows the percentage of citations attributed to your site out of all citations shown across every site for the same grounding query inside Microsoft's AI surfaces. Microsoft states plainly that it is observational: not a ranking system, not a competitive scoreboard, not traffic share, and not a quality score. Read literally, it is a useful directional read on how often Microsoft's AI leans on you as evidence relative to other sources. Read as market share, it is a lie, and a 100 percent share on a query nobody asks means nothing at all. Here is exactly what the number counts, the four things it does not mean, and how to watch it move without overreacting.
A single percentage is about to start appearing in marketing decks with a story attached to it. The story will be some version of "we own X percent of AI," and it will be wrong. Citation Share is a real, useful number that measures a real, narrow thing. The gap between what it measures and what people will claim it measures is where the damage happens.
Search now runs on two scoreboards: ranking (which page a human visits) and citation (which passage an AI system trusts as evidence). We proved that split with our own cross-engine data in [the flagship of this series](/blog/ranking-vs-ai-citation/). Citation Share is Microsoft's attempt to put a number on the second scoreboard. This post is only about that number: what it counts, what it does not, and how to read it without fooling yourself.
## Microsoft shipped Citation Share on June 16 with a warning label
Microsoft added Citation Share to the Bing Webmaster Tools AI Performance report on June 16, 2026, and it did not arrive alone. The same expansion introduced query Intents, Topics, a Compare view, and Citation Share, rolled out as a global preview. The report itself is only a few months old: Microsoft launched the AI Performance report on February 10, 2026, as a separate view from the Search Performance report that tracks clicks, impressions, click-through rate, and average position.
The scope of the report is narrow, and Microsoft states it. It covers Microsoft Copilot, Bing's AI-generated summaries, and select partner integrations. It does not cover ChatGPT. Any tool, consultant, or dashboard that shows you a Bing Citation Share number and calls it your ChatGPT performance is reporting something the data does not contain.
Bing's AI Performance report covers Copilot, Bing AI summaries, and select partner integrations, not ChatGPT; a Bing Citation Share number says nothing about how ChatGPT treats your siteSource: Microsoft Bing Webmaster Tools documentation, June 2026
That scope line matters before the math, because the first way this number gets abused is by stretching it across surfaces it never touched.
## The number is a share of citations for one query, not a share of a market
Citation Share is one division problem. It is your citations for a grounding query, divided by all citations shown across all sites for that same grounding query. That is the entire definition. If Microsoft's AI answered a given question by citing ten passages and two of them came from your site, your Citation Share for that query is 20 percent.
The denominator is the trap. It is not your audience. It is not the market for your service. It is not the number of people who saw the answer, and it is not clicks. It is a count of citations in AI answers for one specific query. Change the query and you get a different pool, a different denominator, and a different share. There is no account-level "my share of AI" hiding in this report, because the number only means something attached to the query sitting underneath it.
Say that back plainly: Citation Share measures how often Microsoft's AI reached for your passage instead of someone else's when it built one particular answer. That is a genuinely useful thing to know. It is also a very different thing from owning a slice of a market.
## Microsoft lists four things Citation Share is not
Microsoft published Citation Share with an unusually direct list of what it is not. The documentation calls the metric observational and rules out four readings by name: not a ranking system, not a competitive scoreboard, not traffic share, and not a quality score. Each of those four is exactly the assumption a marketer reaches for first.
Microsoft states Citation Share is observational: not a ranking system, not a competitive scoreboard, not traffic share, and not a quality score; it shows what got cited and nothing about rank, standings, visits, or qualitySource: Microsoft Bing Webmaster Tools documentation, June 2026
Here is each denial next to the misread it prevents and the reality Microsoft states:
| Microsoft says it is NOT | The misread a marketer makes | What the number actually is |
| --- | --- | --- |
| A ranking system | "A higher share means I rank higher in AI answers." | A count of citations, with no rank attached to it. |
| A competitive scoreboard | "This is my standing against my competitors." | A per-query pool that shifts with the question, not a league table. |
| Traffic share | "This is the share of visitors I capture." | A citation is not a visit; the number implies zero clicks either way. |
| A quality score | "My content scored well." | A record of what got cited, not a grade of how good the content is. |
This lines up with what Microsoft says about the report as a whole: it does not measure rankings, authority, performance, or importance. It only shows what got cited. Citation Share inherits that limit exactly. A high share is a high count in one pool, not a high grade.
## A 100 percent Citation Share can mean almost nothing
A 100 percent Citation Share can be the emptiest number in the report. Take this as an illustration, not a measurement: imagine a grounding query that Microsoft's AI answers only a handful of times, and each time it cites exactly one source, yours. Your Citation Share for that query is 100 percent. You own it completely. You also own nothing, because almost nobody asks the question.
A percentage with no denominator underneath it is a decoration. A total share of a query nobody asks and a modest share of a query buyers ask constantly are both "shares," and only the second one changes your business. This is why the raw citation count and the query itself are not optional context; they are the whole story. A share is only as meaningful as the volume it divides.
So the first thing to look at is never the percentage. It is the number of citations and the question they answered. Read the count first, the query second, and the share last. In that order the metric tells the truth. In the reverse order it flatters you.
## How to read it without overreacting
Read Citation Share as a trend line, never as a single reading. Four habits keep it honest:
1. **Watch the direction with the count, not the percentage alone.** A share rising while the raw citation count also rises means Microsoft's AI is leaning on you more often. A share rising while the count falls can simply mean the pool got smaller. The percentage cannot tell those two apart; the count can.
2. **Use Compare for direction, not a verdict.** The new Compare view is built to show change between two periods. It answers "which way is this moving," not "did I win." Treat it as a trend tool and it earns its place; treat it as a scoreboard and it will mislead you.
3. **Ignore the week-to-week wobble.** AI answers recompose constantly, so citation slots and shares move around from one week to the next. React to multi-week trends, not single-week noise. This is the same caution that applies to citation positions everywhere: the movement is the surface, the trend is the signal.
4. **Keep it beside the ranking scoreboard, not on top of it.** Citation Share sits next to your Search Performance numbers; it does not replace them. The useful finding is almost always the gap between the two: a page that ranks well and gets cited rarely has an evidence problem you can now see.
One thing this number does not do is tell you whether AI cites your business at all in the first place. That is an earlier, simpler check across the AI answer engines, and it is worth running before you spend any time on a share percentage. Do the "does anything cite me" pass first; read the share once there is something to read.
## A thermometer, not a scoreboard
Citation Share is a thermometer, not a scoreboard. It tells you how warm Microsoft's AI is on your content as evidence for a given question. It does not crown a winner, forecast a click, or hand you a grade. Watched over time and read next to your ranking numbers, it is genuinely useful. That is how our [AI marketing](/services/ai-marketing/) reporting treats it: count first, query second, share last. Sold as "AI market share," it is a story with a decimal point.
The reason it gets misread is the reason this whole series exists: search split into two scoreboards, ranking and citation, and most businesses are still watching only one. We laid out that split, with our own cross-engine tracking, in [the flagship post](/blog/ranking-vs-ai-citation/). Citation Share is one instrument on the second scoreboard, and like any instrument it is only honest if you read the scale it was built on.
If you want to know what the second scoreboard actually says about your business, without the market-share fairy tale, [talk to us](/contact/). Reading both scoreboards on every client, honestly, is what our [SEO practice](/services/seo/) does now.
---
## Ask Your Developer These 3 AI-Crawler Questions
A website can be crawled by AI bots, indexed by search engines, and still never get cited in an AI answer, because crawled, indexed, and cited are three separate states and most sites only ever confirm the first two. The most common reason a business is missing from ChatGPT, Microsoft Copilot, Perplexity, and Google's AI answers is a technical block, not weak content: a robots.txt line, a CDN bot-protection toggle, a stray noindex, or JavaScript-only text quietly blocking the AI search crawlers. A non-technical owner does not need to read the config to catch this. Three questions to whoever built the site surface it: are the AI search bots allowed in by name, is anything silently blocking them, and can you prove our content is reachable and not just indexed.
Most sites that are invisible in AI answers have an access problem, not a content problem. Before you rewrite a single page, you have to confirm that the AI search crawlers can reach it, read it, and are permitted to keep it. That confirmation is a three-question conversation with your developer, and every business owner can have it without touching a config file. This piece gives you the three questions, the crawlers to name, the four common accidental blocks, and a live robots.txt that does it right.
This is the technical-access companion to [You Can Rank #4 on Google and Be Invisible to ChatGPT](/blog/ranking-vs-ai-citation/), which showed the same buyer question producing different winners on Google, Google's AI answer, and ChatGPT. That piece proved the split between ranking and citation. This one covers the step underneath both: whether the machines can even get to your page in the first place.
## Crawled, indexed, and cited are three different states
Crawled, indexed, and cited are three separate states, and confirming the first two tells you nothing about the third. A bot fetching your page is one event. That page becoming eligible to appear in search is a second. A passage from it being used as evidence inside an AI answer is a third. Sites routinely pass the first two and fail the last, then blame the copy.
| State | What it means | What confirms it |
| --- | --- | --- |
| Crawled | An AI or search bot successfully fetched the URL | A 200 response to the bot's user-agent in your server logs |
| Indexed | The page is eligible to appear in search results | The page shows in Google Search Console coverage with no noindex |
| Cited | A passage from the page is used as evidence in an AI answer | The page appears in the Bing AI Performance report or Google's AI reports, or is named inline in a live answer |
Indexing is the floor, not the finish line. Google is explicit that a page has to clear the floor before it can even be considered for an AI answer.
A page "must be indexed and eligible to appear in Google Search with a snippet before it can show up in AI features"; indexing is a precondition for AI Overviews and AI Mode, never a guarantee of citationSource: Google Search Central
So "it's indexed" is the wrong finish line to settle for. Indexed means the page is allowed into the pool an AI system draws from. Whether a passage gets lifted from it is a separate outcome, decided after the page is already reachable and readable. The three questions below make sure you actually clear the floor, because a page blocked at the crawl step never even gets to compete.
## Question one: does our robots.txt allow the AI search bots by name?
The first question is whether your robots.txt names the AI search crawlers and lets them in. A default site configuration was written before these bots existed, so it neither allows nor blocks them on purpose; it just leaves the outcome to chance and to whatever your CDN decides. Naming the bots removes the guesswork. Here are the ones that matter and what allowing each actually does.
| Crawler | Who runs it | What allowing it does |
| --- | --- | --- |
| GPTBot | OpenAI | Uses your pages for model training only |
| OAI-SearchBot | OpenAI | Surfaces your site in ChatGPT search |
| ChatGPT-User | OpenAI | Fetches your page when a user's ChatGPT prompt triggers a visit |
| ClaudeBot / Claude-SearchBot | Anthropic | Training, and search-quality crawling for Claude |
| PerplexityBot | Perplexity | Surfaces and links your site in Perplexity answers |
| Googlebot | Google | Crawls for Search, AI Overviews, and AI Mode (one crawler) |
| bingbot | Microsoft | Crawls for Bing Search and Copilot / Bing AI summaries (one crawler) |
The trap here is treating "AI bots" as one switch. Training crawlers and search-retrieval crawlers are independent, and blocking one does not block the other. OpenAI documents this directly.
"Disallowing GPTBot does not affect OAI-SearchBot"; the training crawler and the ChatGPT-search crawler are separate user-agents, and allowing one does not auto-allow the otherSource: OpenAI bots documentation
That independence is the whole point of naming bots individually. GPTBot crawls for training; OAI-SearchBot is what puts you in ChatGPT search; ChatGPT-User is triggered by a person's prompt. All three respect robots.txt. Anthropic works the same way: ClaudeBot trains, Claude-SearchBot supports search quality, Claude-User is user-triggered, and all honor robots.txt. PerplexityBot surfaces and links sites in Perplexity search, is not used for foundation-model training, and Perplexity recommends allowing it. If you want to appear in a given AI system's answers, allow that system's search bot specifically.
Google and Bing do not have separate AI crawlers. Google's AI Overviews and AI Mode run on the regular Googlebot and the same search index, with no separate AI crawler and no separate submission step, so an unblocked Googlebot already covers them. Bing is a single switch too, and that cuts the other way: bingbot crawls for Bing Search and for Copilot and Bing AI summaries at once, with no separate Bing AI opt-out user-agent.
There is no separate Bing AI opt-out crawler; blocking bingbot removes a site from Bing Search and from Copilot and Bing AI summaries in one move; that same bingbot does not cover ChatGPT, which uses OpenAI's own botsSource: Bing Webmaster Tools help
One more distinction that trips people up: Google-Extended is not a crawler at all. It is a robots.txt control token that governs whether your already-crawled content can be used to train Gemini and to ground answers in Gemini Apps and Vertex AI. Setting it is a consent choice, and it is safe either way.
Google-Extended "does not impact a site's inclusion in Google Search nor is it used as a ranking signal"; blocking it does not remove a site from AI Overviews, because those run on Googlebot and the regular indexSource: Google Search Central
## Question two: is anything silently blocking them?
The second question is whether something is blocking these crawlers without anyone deciding to. Silent blocks are the usual culprit, because they get shipped by a template or a security default and no one connects them to a missing AI citation. There are four common ones, and your developer can rule each in or out in minutes.
| Accidental block | What it looks like | Why it hides you |
| --- | --- | --- |
| Copied "block-AI" robots.txt | A pasted rule list that disallows the training crawlers and the AI search bots together | Removes the site from AI answers while looking like a privacy win |
| CDN bot protection | Cloudflare Bot Fight Mode, a "Block AI bots" managed rule, or AI Crawl Control turned on | Flags legitimate AI search crawlers as scrapers, all-or-nothing across training and retrieval |
| Stray noindex | A `noindex` meta tag or `X-Robots-Tag: noindex` shipped from a staging template | Pulls a money page out of the index, so it cannot be cited |
| JS-only content | Business name, service, and location render only client-side | Leaves the server HTML empty, so there is nothing to lift as evidence |
Block one is a copy-paste casualty. Someone found a "block the AI bots" snippet, pasted it to protect the brand, and did not notice it lists OAI-SearchBot and PerplexityBot right next to GPTBot. The training refusal and the search removal ride together, so the site quietly disappears from ChatGPT search and Perplexity while the owner thinks they only opted out of training.
Block two lives at the CDN, not in your files, which is why developers miss it. Bot-protection features flag automated traffic by default, and legitimate AI search crawlers look automated. The toggle is typically all-or-nothing across training and search-retrieval bots, so a security setting nobody revisited can be the entire reason you are absent from AI answers. If you are on a managed platform, this is the first place to look.
Block three is a staging leftover. A `noindex` tag belongs on a development build and is supposed to be stripped at launch. When a template ships it to production, the page is crawlable but ineligible for the index, which puts it below the floor from question one. It cannot be cited because it is not even in the running.
Block four is invisible to a quick eyeball check because the page looks fine in a browser. If the business name, service, city, and proof points are injected by JavaScript after load, the raw HTML a crawler reads can be close to empty. The page renders for humans and reads as blank to a machine.
## Question three: can you prove the content is reachable, not just indexed?
The third question pushes past "it's indexed" to "prove it's reachable," because indexed is a claim and reachable is a check. Being in the index means a page cleared the floor at some point; it does not confirm that today an AI search bot can fetch the current page, read real text in the response, and not hit a wall. Ask your developer to demonstrate three things, not assert them.
- **Real text in the server HTML.** View the page source, not the rendered page, and confirm the business name, service, location, and at least one checkable proof point are present as plain text before any JavaScript runs. If they are missing from the raw HTML, an AI system has nothing to ground on.
- **No noindex on money pages.** Confirm your service pages, location pages, and key posts carry no `noindex` meta tag and no `X-Robots-Tag: noindex` header. These are the pages you most want cited, so they are the ones a stray tag hurts most.
- **No 403s to AI bots in the logs.** Have them grep the server or CDN logs for the crawler user-agents in question one and confirm those bots get 200 responses, not 403s or challenge pages. A page that answers a browser with a 200 and answers OAI-SearchBot with a 403 is blocked in the one way that matters, and only the logs show it.
Reachability is the thing you can actually verify, and it is the thing that has to be true before content quality even becomes the question. A passage cannot be chosen as evidence if the crawler could not retrieve the passage.
## What a robots.txt that does it right looks like
Our own live robots.txt names the AI search crawlers, allows them, and blocks only the scrapers. It is generated in our site builder, so it ships identically on every deploy. A correct "yes" looks like this, verified in our source on 2026-07-05:
```
User-agent: *
Allow: /
Disallow: /careers/apply
User-agent: GPTBot
Allow: /
User-agent: OAI-SearchBot
Allow: /
User-agent: ChatGPT-User
Allow: /
User-agent: ClaudeBot
Allow: /
User-agent: PerplexityBot
Allow: /
User-agent: Google-Extended
Allow: /
Disallow: /careers/roles/
Disallow: /careers/apply
User-agent: AhrefsBot
Disallow: /
User-agent: AhrefsSiteAudit
Disallow: /
Sitemap: https://choice.marketing/sitemap.xml
```
Read the choices in it. The wildcard group allows every well-behaved bot by default; the only carve-out is a private job-application path, not anything a buyer would search for. GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, and PerplexityBot each get an explicit allow, so the AI search crawlers are permitted by name rather than left to a CDN's guess. Google-Extended gets an allow too, which is our consent choice: we let our already-published pages be used for Gemini training and grounding. A business that would rather not can flip that one line to a disallow with zero effect on Google Search ranking or AI Overviews inclusion. The only blanket disallows are AhrefsBot and AhrefsSiteAudit, which are competitive-analysis scrapers, not answer engines. Nothing that surfaces you in an AI answer is blocked.
That is the standard to hold your own file to: AI search bots allowed by name, a deliberate training-and-grounding choice on Google-Extended, and blocks reserved for tools that only take.
## The access question comes before the content question
Access comes before content, always. The ranking-versus-citation split is real, and rewriting pages into evidence is the work that wins citations once the machines can read them. But none of that fires if a robots.txt line, a CDN toggle, a stray noindex, or a JavaScript-only page is quietly turning the AI search crawlers away at the door. You can write the best evidence paragraph on the internet and still be invisible if the bot that would cite it gets a 403.
This is why we run client marketing like infrastructure, not like a content calendar. Across 30 active clients and 60,000-plus data points monitored daily, crawler access is a thing we verify, not assume, because it is the cheapest failure to fix and the most expensive to leave broken. That verification is a standing item in our [AI marketing](/services/ai-marketing/) service. A blocked crawler is a config change, not a strategy problem, and it costs nothing to correct once you have found it.
Put the three questions to whoever built your site: are the AI search bots allowed in by name, is anything silently blocking them, and can you prove our content is reachable and not just indexed. If the answers are shaky, that is your first fix, ahead of any rewrite. If you want a second set of eyes on it, [ask us](/contact/) to check your crawler access, or see what our [SEO practice](/services/seo/) verifies on every client. Either way, confirm the door is open before you worry about what is written on the other side of it.
---
## One Click, a Thousand Copies: How Advertising Technology Actually Tracks You
A single ad click starts a chain of identification that most people never see, and clearing your cookies stops almost none of it. The click travels through pixels, auctions, identity graphs and server-to-server pipelines, picking up copies of your identity at every stage. By the time an ad appears on your screen, dozens of companies may already know you were there. Regulators in the EU, UK, Canada and US have each ruled against parts of this system in 2026; the sections below walk through that machinery stage by stage.
The industry has a name for the finished product. The merged, deduplicated master profile of one person is called a golden record. It is the polished copy of you, assembled from clicks, purchases, devices and hashed emails, and the name reflects how the industry treats it: as treasure.
This post is the story of how yours gets built. It explains, in plain language, how the modern advertising system recognizes you, remembers you, and trades on what it knows.
## The pipeline: what one click sets in motion
Every visit to an ad-supported page runs the same basic assembly line. It looks like this:
```text
You click an ad or open a page
↓
Your browser or app reveals its IP address, user agent,
the page URL, the referrer, and any stored identifiers
↓
A pixel, tag or SDK on the page records the event
↓
A cookie ID, mobile ad ID, click ID or login connects
that event to a profile that already exists
↓
Your email or phone number, if the site has it,
gets normalized and hashed into a matching key
↓
An ad platform matches that key to your account
or to a graph of your devices
↓
The event becomes a conversion signal, an audience entry,
an exclusion, a lookalike seed or a bidding feature
↓
Weeks later, offline purchases and CRM records get
uploaded to sharpen the whole loop
```
There is also a second, quieter path that never touches your browser at all:
```text
A form you filled, a call you made, a sale at the counter
↓
The advertiser's own server or CRM
↓
Google, Meta, TikTok or an analytics platform, by direct API
```
The infringement of privacy does not happen at one point in this pipeline. It can happen at several, and each stage has its own trick. The sections that follow take the stages in order.
## Your browser draws a picture you never see
Your browser can be recognized without a single cookie. The technique is called fingerprinting, and it works by asking your browser to describe itself in ways you never observe.
One of the stranger methods makes your browser draw an invisible picture. A script instructs the browser to render a hidden combination of text, shapes, colours and gradients, then reads back the exact pixels it produced. Your operating system, graphics card, driver version and font rendering all leave tiny variations in that output. The drawing never appears on screen. The script just receives a compact value that helps distinguish your browser from millions of others.
Canvas drawing is only one signal among dozens. A fingerprinting script can also read your screen dimensions, installed fonts, timezone, language, hardware details and graphics capabilities. Meanwhile, the network itself gives away more: your IP address, the shape of your encrypted connection (a signature called a TLS fingerprint), and the timing of your requests. Browser-side signals and network-side signals get combined into a single feature vector.
A commercial fingerprint is a probability score rather than one permanent hash. Serious systems know your attributes drift: you update your browser, switch networks, plug in a new monitor. So instead of asking "is this the exact same value," they ask "is this new observation similar enough to a visitor we have seen before?"
```text
Last month: Canvas=A17, GPU=NVIDIA-535, Screen=2560x1440,
Timezone=America/Edmonton, Network=Home
Today: Canvas=A19, GPU=NVIDIA-550, Screen=2560x1440,
Timezone=America/Edmonton, Network=Coffee shop
Verdict: likely the same device, confidence 0.91
```
This is why fingerprinting is more invasive than a cookie. A cookie sits in your browser where you can see it and delete it. A fingerprint is reconstructed from scratch the next time the page loads. Clearing cookies, opening a fresh session, even blocking third-party cookies entirely: none of it resets a fingerprint. European and UK regulators treat fingerprinting exactly like other tracking technologies, and using it for advertising normally requires your prior consent. The commercial appeal of the technique rests on skipping that request.
## The auction where the losers keep your data
Every ad slot you see was auctioned in the moment the page loaded, and your personal data was the auction catalogue. The system is called real-time bidding, and in practice it operates as a high-speed data distribution network wrapped around an auction.
The page identifies an empty ad slot. Software on the publisher's side packages up a bid request: the page you are on, your device details, your IP address, your approximate location, your identifiers, and often the interest segments some data provider has filed you under ("home-renovation-interest," say). That request goes out to multiple bidding platforms simultaneously. Each one evaluates you against its advertisers' campaigns, decides what your attention is worth, and bids. A winner is picked, the ad renders, and the whole exchange completes in a fraction of a second, within whatever time limit the publisher configured.
The privacy problem happens before any winner is chosen. Each bid request carries a sketch of you: call it your bidstream doppelgänger, the disposable stand-in that gets shown around to every bidder in the room. Suppose ten bidders receive it and one wins. The other nine still met your doppelgänger. They learned what page you were reading, where you roughly are, what device you use and which segments you belong to, and they paid nothing. Multiply that by the hundreds of pages you load in a month and the bidstream becomes one of the largest personal-data broadcasts ever built. Europe's courts have already ruled that the consent string passed around in these auctions is itself personal data, and that even the industry body that wrote the auction rules can bear legal responsibility for the system.
A real bid request supports fields for your device, geography, user IDs, buyer-specific IDs, shared identity tokens, interests and consent status. Privacy controls can strip or truncate some of these. The protocol was designed to carry them all, and every field it carries is another line your doppelgänger donates to somebody's golden record.
## Hashing your email does not hide you
"We only share a hashed version of your email" is one of the most misleading sentences in advertising. The phrase suggests anonymization, but a hash works as a matching key.
Hashing turns your email address into a fixed scramble of characters, always the same scramble for the same input. That consistency is what makes the matching work:
```text
Advertiser's side:
peter@example.com → normalize → hash → HASH-XYZ
Platform's side:
peter@example.com (from your account) → same normalize → same hash → HASH-XYZ
Result: exact match. The platform now knows
its user and the advertiser's customer are the same person.
```
The platform never needs to "crack" the hash. It already knows your email, because you gave it one when you signed up. It hashes what it knows and compares. The stability that makes hashing useful for matching is also what makes it useless as anonymity. Every successful match is a merge: two partial profiles collapse into one, and the golden record gets a little more golden.
Canada's Privacy Commissioner investigated exactly this pattern. Home Depot Canada sent Meta hashed email addresses along with offline purchase details. Meta matched the hashes to Facebook accounts and could use the purchase information for its own advertising purposes. The advertiser saw only an aggregate campaign dashboard, but producing those aggregate numbers required matching real individuals upstream. The Commissioner found customers had never meaningfully consented to any of it. The finding reaches well beyond one retailer: an aggregate report does not mean the underlying processing was aggregate.
Email matching is the deterministic case. When there is no shared login or email, the industry estimates. Devices that sit on the same home network every evening, move through the same locations, and show overlapping activity patterns get linked into a graph:
```text
One household
├── phone
├── work laptop
├── home computer
├── smart TV
├── email hash
└── retailer customer IDs
```
Then one device's behaviour steers another device's ads. You search for a roofing contractor on your phone; a roofing ad appears on the living room TV. Sometimes the graph is wrong, and someone else's behaviour steers your ads instead, which stacks a second privacy problem on top of the first.
## The apps and emails that report home
An app can watch you in ways a website never could, because the watcher is built inside. Advertising and analytics SDKs are vendor code compiled directly into the apps you install. They observe the app opening, the screens you visit, the events the developer chose to report: registrations, purchases, subscriptions, appointment requests. Each event flows back to the vendor, which links it to the ad you saw last week.
Apple and Google have both constrained this, unevenly. On iOS, an app must ask permission before tracking you across other companies' apps, and if you decline, the old cross-app advertising identifier is off the table; attribution shifts to privacy-oriented systems where the operating system itself reports campaign results without handing over user-level identifiers. On Android, a campaign link can stash its campaign and click IDs in the Play Store URL, and the app collects them after install to credit the right ad.
The event name can disclose more than the identifier does. An SDK does not need a medical record to reveal something medical:
```text
fertility_consultation_booked
addiction_assessment_completed
bankruptcy_application_started
```
Attach any one of those to a device ID and you have revealed sensitive information about a person, no diagnosis field required. US regulators have already acted on this pattern: the FTC's cases against BetterHelp and GoodRx turned on health-adjacent context flowing to advertising companies, and the remedies included money, advertising bans and deletion orders.
Email tracking runs on the same logic at smaller scale. Marketing emails embed a one-pixel transparent image with a unique URL; when your mail app loads it, the sender records the open, your IP and your mail client. Links are rewritten to pass through the sender's redirect server first, so every click is logged before you arrive anywhere. Apple now pre-loads images to blur open tracking, and European regulators have moved toward requiring consent for behavioural use of email pixels. The pixel survives because it is cheap and invisible.
## The tracking you cannot see at all
The newest tracking route does not run through your browser, which means nothing in your browser can show it to you. It is called server-side tracking, and it deserves more suspicion than it usually gets.
The architecture is simple. Instead of your browser sending events straight to Google, Meta and TikTok, it sends one event to a server the advertiser controls, often on the advertiser's own domain. That server then decides what to forward, to whom. Some events never involve your browser at all: a call centre logs your phone call, a CRM records your purchase, and a backend job later uploads the conversion, with your hashed email and the ID of the ad you clicked, directly to the platform's API. Your browser may have been closed for days.
Run honestly, this design can genuinely improve privacy. The advertiser's server can strip unnecessary fields, check your consent before forwarding anything, rewrite a revealing event like `opioid_treatment_application` into a bland `qualified_lead`, or drop the event entirely. A single controlled gate beats a dozen third-party scripts shouting from your browser.
Run cynically, the same design defeats every control you have:
```text
You click "Reject advertising cookies"
↓
The browser pixel is blocked
↓
The website still records your form submission
↓
The CRM uploads your hashed email and phone number
↓
The platform matches you anyway
↓
Your conversion trains the bidding model anyway
```
From your side of the screen, tracking was refused. From the platform's side, your data arrived on schedule, by a route no browser tool can see and no ad blocker can touch. The golden record never even noticed your refusal. Classifying server-side tracking as "lower risk" therefore gets the analysis backwards. The risk is variable and frequently high: it depends entirely on what identifiers travel, how sensitive the events are, who receives them, and whether your "no" actually propagates to the server. The architecture amounts to a gate, and from the outside you cannot tell whether that gate works as a checkpoint or as a bypass.
## What the law actually does about all this
Regulators in every major jurisdiction have stopped asking "was it a cookie" and started asking harder questions. Six of them, roughly:
1. What information was collected?
2. Can it be linked to a person, device or household?
3. For what purpose?
4. Who receives it?
5. What would the person reasonably expect?
6. Does saying no actually stop every downstream route?
The regions differ in mechanism more than in direction. Europe and the UK run a two-gate system: first, may the technology store or read anything on your device at all (that gate covers cookies, pixels and fingerprinting alike, and for advertising it normally demands prior consent); second, may the resulting personal data be processed for the intended purpose. Passing the second gate never excuses failing the first. UK guidance finalized in April 2026 adds that advertising measurement is part of the advertising purpose, so it needs the same consent, and it names fingerprinting, pixels, link decoration and tags explicitly.
Canada is subtler than its opt-out reputation. Federal law requires meaningful consent, and the privacy regulator permits opt-out consent for behavioural advertising only under conditions: non-sensitive data, obvious purposes, notice up front, an easy and persistent way out. A health clinic uploading appointment data to an ad platform sits nowhere near that safe zone. Quebec goes further, requiring advance disclosure whenever technology can identify, locate or profile you, and express consent for sensitive information, with penalties that can reach C$10 million or 2 percent of worldwide turnover on the administrative side and C$25 million or 4 percent for penal offences. A federal overhaul, Bill C-36, was introduced in June 2026 but remains at second reading as of this writing; it is not yet law.
The United States has no comprehensive federal privacy law, but the state patchwork now has real teeth. California and a growing list of states let you opt out of the sale and sharing of your data, and covered businesses must honour the Global Privacy Control, a signal your browser sends automatically. The live question is reach: an honoured opt-out is supposed to stop not just the browser pixel but the server-side events, the customer-list uploads and the re-entry into ad audiences. California now requires businesses to let you confirm your signal was actually processed, which tells you how often it wasn't.
Enforcement is where the abstractions get concrete. Home Depot established that sending hashed emails is a disclosure of personal information, not an anonymization technique. BetterHelp and GoodRx established that an identifier tied to a therapy questionnaire is health data even if no diagnosis was transmitted. And the European ruling on the industry's own consent framework established that the consent string itself is personal data, and that writing the rules of the auction can make you responsible for it.
## Cookies were never the point
The death of the third-party cookie changed almost nothing, because the cookie was only ever one carrier of the real product: linkability. Linkability is what holds a golden record together. Login IDs, hashed emails, click IDs, mobile ad IDs, shared identity tokens, device graphs, fingerprints and server-to-server events all perform the same function. The question regulators increasingly ask cuts past the technology's name: can this be tied back to a person, and did that person agree?
The same skepticism applies to the phrase "first-party data." A tracking endpoint on the brand's own domain looks first-party right up until it forwards everything to four ad platforms in the next millisecond. And it applies to "we only see aggregate reports": the dashboard may show 42 conversions, but producing that number can require individually matching 42 human beings against their accounts, clicks, purchases and phone calls, and only the finished report is aggregate.
Real privacy control, the kind the law is slowly converging on, is one recorded choice that actually propagates everywhere your data flows:
```text
Your "no" (banner choice, objection, or GPC signal)
↓
One central preference record
↓
┌──────────────┼──────────────┐
Browser tags Server tags CRM exports
Audience lists Mobile SDKs Email pixels
Data brokers Deletion jobs
```
A banner that switches off a cookie while the CRM export, the conversion API and the audience upload carry on untouched has controlled nothing. Knowing the machinery is the first step to telling a working control from a decorative one, and to deciding who gets to keep a golden record of you.
---
## Stop Writing Marketing Copy. Start Writing Evidence.
Marketing copy is written to persuade a person. Evidence is written so a machine can lift one paragraph and stand behind it. AI answer engines do not choose pages, they choose passages: Google composes its generative results by retrieving specific information from pages in its index, and Microsoft says how content breaks into retrievable chunks now matters in ways ranking never measured. Every paragraph you want an AI to cite has to survive being pulled out of context and read alone, which means it has to pass five tests: completeness (does it answer the question by itself), freshness (can a machine tell it is current), authority (is it clear who is qualified to say it), attribution (is the claim traceable to a source), and entity clarity (does it name which business it means). Ask those five questions of every important paragraph and you turn copy that only reads well into copy a machine can quote.
Your best-written sentence and your most citable sentence are usually not the same sentence. One is built to move a reader toward a call. The other is built to answer a question completely enough that a machine will repeat it and attach your name. The flagship in this series showed that [rank and citation are separate outcomes](/blog/ranking-vs-ai-citation/): we track the same buyer questions across Google, Google's AI answers, and ChatGPT, and the site that ranks is often not the site that gets cited. This piece is about the writing change that closes that gap.
## AI systems cite passages, not pages
The unit of writing that matters has shrunk from the page to the paragraph. Ranking asked a page-level question: of all the pages about this topic, which one should a human open? Citation asks a passage-level question: of all the sentences on all the pages, which specific one can support this answer? Those are not the same question, and the copy that wins the first can lose the second.
Google builds its AI answers by retrieval, not by picking a single winning page; it pulls pages from the index, then composes a response from specific information inside them and links back to the sourcesSource: Google, on how AI features in Search work
Microsoft's search team describes the same mechanism from the other side: in grounded AI systems, factual fidelity and how content breaks into retrievable chunks matter in ways that never appeared in a ranking signal. A ranking system reads your whole page in context. A grounding system tears one chunk loose and reads it alone, with none of the surrounding copy to lean on. Classic SEO never had to survive that. Citation does.
So the practical test changed. You are no longer only asking "is this page good enough to rank?" You are asking, of each important paragraph, "if a machine lifted this and nothing else, would it still be true, current, credible, sourced, and clearly about my business?" Those are the five questions below. Run them like a checklist.
## Completeness: a paragraph that leans on the rest of the page cannot be cited
Question one: does this paragraph answer the buyer's question on its own? A citable passage names the who, the what, the where, and at least one checkable proof point inside the same block of text, because the machine will not read the rest of the page to fill in the gaps.
Completeness does this to a single sentence:
> "We're passionate about helping our clients get the results they deserve."
> "Redwater Physiotherapy treats post-surgical knee and shoulder rehabilitation in Sherwood Park, with direct billing to most major insurers and evening appointments."
A human skimming the page takes roughly the same brand impression from both. An extractor can only use the second, because it is the only one that contains information: a name, a service, a location, and two concrete facts a buyer would act on. The first sentence is not wrong, it is empty, and an answer cannot be built out of empty. If your key paragraphs depend on the headline above them or the paragraph before them to make sense, they will not make sense once they are pulled loose.
## Freshness: a machine cannot cite what it cannot date
Question two: can a machine tell this passage is current? Grounding systems prefer information they can trust is fresh, and the only recency they can read is the recency you write down: a date, a reference to the current year, an updated figure. "Latest" and "up to date" are invisible, because they were equally true and equally unprovable five years ago.
Compare:
> "We use the latest roofing materials and techniques."
> "In 2026 we install Class 4 impact-rated asphalt shingles across Edmonton, which may qualify homeowners for a hail-damage insurance discount."
The second sentence carries a signal the first does not: a year a machine can compare against today, plus a specific, checkable detail. That is the difference between a passage a grounding system treats as current and one it has to guess about, then often skips. Put the date in the sentence, not just in a "last updated" line in the footer that the extracted chunk leaves behind.
## Authority: name who is qualified to make the claim
Question three: is it clear who is qualified to make this claim? Authority is not a dial you read on a dashboard, it is a property you write into the passage. A credential, a licence, a first-party basis, or a named person tells a citing system the claim comes from someone entitled to make it.
Microsoft's AI Performance report shows what got cited, not what ranks; its documentation states the report does not measure rankings, authority, performance, or importanceSource: Microsoft Bing Webmaster Tools documentation
That is the honest nuance. The report launched February 10, 2026 and it scores citations, not authority, so no tool hands you an authority number to optimize. You build authority into the sentence and let the citation follow. Compare:
> "Trusted by many happy patients."
> "Dr. Amrit Sahota, a licensed Alberta dentist since 2009, places same-day crowns using in-house CEREC milling."
The second names a person, a credential, a licence, and a method. It reads as a claim someone stands behind. The same move works with first-party specificity: "trusted by businesses across Alberta" says nothing a machine can weigh, while "Choice OMG monitors more than 60,000 data points a day across 30 client accounts" is a first-party basis a citing system can attach to a source. Vague trust is not authority. Named, checkable qualification is.
## Attribution: an unsourced number is one an AI will not repeat
Question four: can this claim be traced to a source? ChatGPT search responses can include inline citations and a Sources panel, which means a citing system is actively looking for claims it can forward with a source attached. A bare, unattributed statistic gives it nothing to stand behind, so it tends to reach for a claim that names its origin instead.
Compare:
> "Most Edmonton businesses are invisible to AI answer engines."
> "In our own July 2026 cross-engine tracking, a question we rank #4 for on Google was cited by neither Google's AI answer nor ChatGPT."
The first is a floating assertion with no owner. The second names who measured it and when, so a machine forwarding it knows exactly what it is standing on. You do not have to publish someone else's study to do this. Your own dated, first-party observation is a source. The rule is simple: if a paragraph makes a number-shaped claim, the same paragraph should say where the number came from.
## Entity clarity: the passage has to say which business it means
Question five: does the passage name which business it means? Once a paragraph is lifted out of context, "we," "our team," and "the company" have no referent, because the page header that told the reader who "we" was is gone. The sentence itself has to carry the name.
Compare:
> "We've been the area's go-to team for over a decade."
> "Northgate Auto Repair has served north Edmonton drivers since 2011."
A reader on the page resolves "we" from the logo at the top. An extractor holding only the sentence cannot, so the first version becomes an anonymous quote about nobody. The second survives extraction because the subject is named inside it. This is strictly about the words in the paragraph: make the business the grammatical subject of your important claims instead of a pronoun. Keeping your name, address, and listings consistent across the wider web is a real and separate job, and it is not this one; this question is only about whether the sentence on the page names itself.
## Run the five questions before you publish
Treat the five questions as a QC pass, the same way you would run a health check before a deploy. Marketing that runs like infrastructure does not ship a page and hope; it checks the page against a standard first. Take your most important service page, read each key paragraph as if it were the only thing a machine could see, and put it through the list:
| Question | What the paragraph must do |
| --- | --- |
| Completeness | Answer the buyer's question on its own, naming the who, what, where, and one checkable proof |
| Freshness | Carry a recency signal a machine can read: a date, the current year, an updated figure |
| Authority | Name who is qualified to make the claim: a credential, a licence, a first-party basis |
| Attribution | Trace the claim to a source a citing system can forward |
| Entity clarity | Name the business in the sentence, not a pronoun a reader has to resolve |
A paragraph that passes all five can be lifted out of your page and still stand as evidence. A paragraph that fails one is copy that reads well and cites badly, which is exactly the gap the flagship measured: rank and citation are separate outcomes, and the writing is where you close the distance between them. Most service-page copy fails at least two of these questions today, not because it is bad writing, but because it was written to persuade a reader who could see the whole page, not to feed a machine one chunk at a time.
This is the work our [SEO practice](/services/seo/) now runs on client pages: not just chasing positions, but rewriting the passages that carry the claims so a machine can quote them. It is a standing part of every [Edmonton SEO](/edmonton/seo/) engagement we run. If you want a second set of eyes on whether your most important pages read as evidence or just as marketing, [ask us](/contact/) and we will run the five questions on the pages that matter most to your buyers.
---
## The Local Business Checklist for Showing Up in AI Answers
Local businesses have a second grounding layer that page copy alone never reaches: the entity facts (name, address, phone, hours, category, credentials) that AI systems reconcile from your listings, your site's structured data, and third-party directories before they decide whose facts to trust in a location answer. Microsoft states directly that registering with Bing Places for Business keeps key details current and eligible for inclusion in AI-generated responses, and Google confirms that more reviews and positive ratings help local ranking. Neither guarantees a citation. But conflicting or missing facts across your profiles guarantee an AI system has a reason to skip you. This is the checklist that makes your business's facts consistent, complete, and machine-readable, so you stay eligible to be the source an AI answer names.
A location answer is grounded in facts, not paragraphs. When an AI system answers "best dentist near me" or "emergency plumber in Sherwood Park," it is not summarizing your homepage. It is reconciling a small set of entity facts about your business (name, address, phone, hours, category, credentials, service area) from every place those facts appear. The facts have to agree with each other before an AI system will trust any of them enough to name you.
## Local search runs on facts, not just pages
The most important thing about your business, to an AI answer, is whether its facts line up. Microsoft says this plainly: for local businesses, accurate business information is especially important when AI experiences surface answers to location-based queries. That is a different job from writing better page copy. It is about your identity, stated the same way everywhere a machine can read it.
For local businesses, accurate business information is especially important when AI experiences surface answers to location-based queries; the reconciled facts, not the prose, decide who an answer can nameSource: Microsoft, Bing Webmaster Blog, February 2026
The [flagship in this series](/blog/ranking-vs-ai-citation/) showed ranking and citation are two separate scoreboards: which page a human visits, and which passage an AI system trusts as evidence. For a local business there is a layer underneath both. Whether your identity facts are consistent and complete across Google, Bing, your own site, and the directories that feed them. Rewriting a paragraph does not fix a phone number that reads three different ways across three profiles. This article is the checklist for that layer, and it stays deliberately clear of the crawler-access and copy-rewriting work the other pieces cover.
## Microsoft ties Bing Places straight to AI answers
Microsoft connects a Bing Places listing directly to AI answer eligibility. In its February 2026 AI Performance guidance, Microsoft tells businesses they can register with Bing Places for Business to help ensure key details such as address, hours, and contact information remain current and eligible for inclusion in AI-generated responses. That is a search platform stating, in its own words, that a maintained listing is an input to what its AI surfaces say.
Register with Bing Places for Business to help ensure key details such as address, hours, and contact information remain current and eligible for inclusion in AI-generated responses; a maintained listing is a named input, not a hopeSource: Microsoft, Bing Webmaster Blog, AI Performance guidance, February 2026
The listing is free and easier to get than it used to be. The rebuilt Bing Places for Business launched in October 2025, the portal now lives at www.bing.com/forbusiness, and it can import your listing straight from Google, carrying over your business name, hours, and contact details in one step. If you already maintain a Google Business Profile, the Bing side is close to a copy-paste.
Hold one honest boundary here. Bing's AI Performance reporting covers Microsoft Copilot, Bing's AI-generated summaries, and select partner integrations. It does not cover ChatGPT. A Bing Places listing helps you across Microsoft's own AI surfaces and the partners it feeds; it is not a lever aimed at ChatGPT specifically. That is still a large and growing surface worth claiming, and the discipline of stating your facts cleanly pays off on every other surface too.
## Google scores local on relevance, distance, and prominence
Google ranks local results on three factors it names outright: relevance, distance, and prominence. Relevance is how well your profile matches the search. Distance is how far you are from the searcher. Prominence is how well-known your business is, which Google builds partly from information across the web (links, articles, directories) and partly from your review count and score. You cannot move distance. You can move relevance and prominence, and both run on completeness.
Google's own advice for local ranking is to complete and verify your profile, keep your hours accurate, add your real categories, and post photos. Then it points at reviews.
More reviews and positive ratings can help your business's local ranking; responding to reviews shows you value your customers and their feedbackSource: Google Business Profile Help, support.google.com/business/answer/7091
Read Google's honesty line next to that, because it kills a whole category of bad advice: there is no way to request or pay for a better local ranking on Google. The lever is a complete, verified, accurate profile with real reviews, not a payment. That is the same profile an AI system reconciles against when it builds a location answer, which is why filling it out completely is a citation move as much as a ranking one.
## Your website must state the same facts a machine can read
Your listings are only half of it. Your own site has to state the same facts in a form a machine reads without guessing, and that is what LocalBusiness structured data does. Google's spec requires only two properties, name and address, and recommends the ones that make you unambiguous: geo coordinates (at least five decimal places), telephone, url, openingHoursSpecification, and priceRange. Use the most specific subtype that fits rather than the generic one: Dentist, AutomotiveBusiness, and so on, so the category is explicit instead of inferred.
This is structural work, not copy rewriting: putting your facts in a labeled box so the numbers on your contact page and the numbers on your listings are provably the same business. Then tie your profiles together with an Organization sameAs property. sameAs is the URL of a page on another site with more information about your organization, and Google uses it to disambiguate your organization in search results. Point it at your Google Business Profile, your Bing Places listing, your real social profiles, and your directory pages. Each link is a thread stitching scattered mentions into one entity an AI system can resolve to you.
One trap to avoid: do not mark up your own star rating on your own site. Google recommends aggregateRating and review structured data only for sites that review other businesses, not for a business scoring itself. Self-applied rating markup risks a manual action, and it does nothing that your real reviews on Google and third-party directories are not already doing honestly.
## The checklist
Nine items, grouped by the signal each one feeds. Work top to bottom; every line pairs the action with the reason an AI system uses it.
| Signal | What to do | Why an AI system uses it |
| --- | --- | --- |
| Listing | Claim and complete Google Business Profile and Bing Places | Registered listings keep your core facts current and eligible for inclusion in AI answers |
| NAP | Make name, address, phone identical everywhere | Matching facts leave one business to resolve, not three to reconcile |
| Schema | Add LocalBusiness structured data with the most specific subtype | States your facts in a labeled form the crawler does not have to infer |
| sameAs | Link your profiles from your Organization schema | Stitches scattered mentions into a single entity Google can disambiguate |
| Reviews | Earn real reviews and respond to them | Review count and score feed local prominence and the trust an answer leans on |
| Freshness | Update listings the day a fact changes; ping IndexNow | Keeps AI experiences reading current hours and details, not stale ones |
| Credentials | State licenses, certifications, and service area in plain text | Checkable proof points are exactly what an answer can lift and attribute |
1. **Claim and complete both listings.** Claim your Google Business Profile and your Bing Places for Business listing, and fill every field: categories, hours, phone, website, service area, photos. Microsoft ties a complete Bing Places listing to eligibility for AI-generated responses, and Google ties a complete profile to local ranking.
2. **Make your NAP identical everywhere.** Your business name, address, and phone number should read the same, character for character, on your site, Google, Bing, and every directory. Conflicting facts hand an AI system a reason to trust someone else's.
3. **Pick the most specific category.** Choose the narrowest accurate category on each listing and the most specific LocalBusiness subtype in your schema. "Dentist" resolves cleaner than "medical business."
4. **Add LocalBusiness structured data to your site.** Name and address at minimum; ideally geo coordinates, telephone, url, and openingHoursSpecification too, so your contact page states its facts in a form a machine reads without guessing.
5. **Link your profiles with sameAs.** Add an Organization sameAs list pointing at your Google, Bing, social, and directory profiles, so scattered mentions resolve to one entity instead of several half-matches.
6. **Earn and answer reviews.** More real reviews and positive ratings help local ranking, and responding shows you value feedback. Do not fabricate reviews, and do not mark up your own rating on your own site.
7. **State your credentials as facts.** Put licenses, certifications, associations, and your exact service area in plain text on the page. These are the checkable proof points an answer can lift and attribute to you by name.
8. **Keep it fresh.** Update every listing the day a fact changes, from holiday hours to a new phone line. IndexNow (indexnow.org) is Microsoft's recommended way to push content and listing changes quickly across search and AI experiences.
9. **Audit the directories that repeat you.** Fix your name, address, and phone on the third-party directories that already list you. AI systems reconcile across them, and one old address on a stale profile can outvote the correct one on your site.
## What this checklist does and does not do
This checklist makes you eligible and easy to cite. It does not guarantee a citation. Consistent, complete, machine-readable facts remove every reason an AI system has to skip you, and they put your details in front of the surfaces Microsoft and Google say they feed. Whether a given answer names you still depends on the query, the competition, and the passage the system chooses, which is the ranking-versus-citation split the flagship laid out.
Be honest about one item in particular. NAP consistency is long-standing best practice, not a factor Google publishes in its local ranking documentation. It belongs on the list because conflicting facts demonstrably give engines and AI systems something to disagree about, and clean facts cost nothing to maintain. Treat it as hygiene, not as a dial that pushes you up a ranking.
The pattern underneath the whole list is the one from the [flagship](/blog/ranking-vs-ai-citation/): ranking and citation are separate outcomes. Completeness helps both, but it helps citation in a way that is newly visible and mostly unclaimed. The local businesses that reconcile their facts now will be the ones an AI answer can name without hesitating.
If you want a second set of eyes on how your facts read across Google, Bing, your schema, and the directories, [ask us](/contact/). It is the kind of audit our [local SEO practice](/services/seo/) runs on every client. We are an Edmonton agency, founded in 2010, and our [Edmonton SEO](/edmonton/seo/) team watches this layer on 30 businesses at once. Run the check before an AI answer picks whose facts to trust.
---
## Your About Us Page Is Costing You Customers
Your About Us page is the one page where an AI system tries to learn who your business is, and most are written as mood copy that states nothing an answer engine can quote. AI answers are assembled from retrieved passages, not ranked pages: the system pulls specific facts from a page and composes a response with links back to the source. So a paragraph that says "family-focused, patient-first care" is invisible to that process, because it carries no fact to lift. Below we take four vague, real-shaped About paragraphs and rewrite each into an extractable one that names the business, the exact service, the location, who it serves, and one checkable proof. It is the same information a human skims past; the difference decides whether an AI cites you or your competitor.
Your About Us page has a new reader, and it is not a person. When someone asks ChatGPT, Google's AI answer, or Perplexity "who does dental implants in Edmonton" or "which contractor handles roof replacement near me," the AI system goes looking for a page that tells it, in plain words, what your business is and what it does. Your About page is the page it reaches for. Most About pages fail that reader completely.
We showed in [You Can Rank #4 on Google and Be Invisible to ChatGPT](/blog/ranking-vs-ai-citation/) that ranking and citation are separate outcomes, measured separately, on our own site the same day. This piece is about the copy underneath that split. The About page is where an answer engine goes to settle who you are, and it is usually the page written with the least regard for stating a fact.
## An AI answer engine cannot quote a sentence that has no facts in it
AI answers are built from passages, not pages. Google describes its generative results as retrieval-augmented: the system retrieves pages from its index, then uses specific information from those pages to compose a response, with links back to the sources. That is the whole mechanism. It does not read your page for tone or design. It reads it for extractable statements, lifts the ones that answer the question, and attributes them.
Google's AI answers retrieve pages from the index, then use specific information from those pages to compose a response with links back to the sources; a passage with no specific information in it cannot be part of that responseSource: Google, on how AI Overviews and AI Mode generate results (retrieval-augmented)
That reframes what an About page is for. The old job was to make a human feel something on the way to the contact form. The new job runs alongside it: be the page that tells a machine, in one self-contained passage, exactly what this business is, what it does, where, for whom, and with what proof. When those facts are on the page as plain statements, an AI system can quote them. When the page is a wall of adjectives, there is nothing to quote, and the answer gets built from a competitor who wrote it down.
The four rewrites below are constructed examples across the kinds of local businesses AI answers get asked about. Each starts from the kind of About paragraph we see constantly and ends with a version an answer engine can actually use.
## The dentist: "family-focused, patient-first care" becomes a named clinic with named services
Naming the clinic, the exact procedures, and the location turns a mood line into a passage an AI can cite. This is the version that appears on most dental sites:
> "We are committed to family-focused, patient-first care in a comfortable, modern environment where your smile comes first."
A person skims that and moves on. An AI system asked "who does Invisalign in southwest Edmonton" finds nothing in it to lift: no business name, no procedure, no place. It is not that the sentence is bad writing. It is that the sentence contains zero retrievable facts. Now the rewrite:
> "Riverbend Dental is a family and cosmetic dental clinic in southwest Edmonton offering routine checkups, Invisalign clear aligners, dental implants, and same-day crowns, with evening and Saturday appointments for working families."
Every clause in the second version is quotable. Asked about implants in that neighbourhood, an answer engine can now cite a named clinic that says it does implants in that neighbourhood. The human impression is nearly identical; the machine-readable content went from nothing to a full entity record.
## The contractor: "quality workmanship you can trust" becomes checkable proof
Swapping adjectives for verifiable facts is what lets a contractor's passage survive being lifted out of context. Adjectives do not survive extraction, because every competitor claims the same ones. The typical line:
> "We deliver quality workmanship you can trust, on time and on budget, with customer satisfaction guaranteed on every project."
"Quality," "trust," and "guaranteed" are not facts; they are the default vocabulary of the entire trade, and an AI system weighting one source against another gets no signal from words every source uses. Replace them with things that can be checked:
> "Summit Exteriors is a licensed and insured roofing and siding contractor serving Edmonton and Sherwood Park, installing asphalt and metal roofs with a written 10-year workmanship warranty and a typical two-day install on residential homes."
License status, a named warranty term, a defined service area, and a concrete timeline all survive being pulled out of the page and dropped into an answer. Microsoft's search team makes the same point from the grounding side: in AI systems, factual fidelity and how content breaks into retrievable chunks matter in ways that never appear in a ranking signal.
Factual fidelity and how content breaks into retrievable chunks matter to AI grounding in ways that never appear in any ranking signal; a warranty term and a service area are chunks a system can retrieve, "quality you can trust" is notSource: Microsoft Bing search team, on AI grounding
## The optometrist: "your vision is our priority" becomes conditions treated and who it serves
Converting a benefit slogan into concrete conditions and use cases is the layer that lets an AI match you to a specific buyer question. Buyers do not ask AI systems for priorities; they ask for a problem solved. The slogan version:
> "At our clinic, your vision is our priority, and we treat every patient like family."
A parent searching "who does myopia control for kids near me" or a patient asking "where can I get dry eye treatment in central Edmonton" gets no match from that sentence, because it names no condition and no place. The rewrite names both:
> "Glenora Eye Care is an optometry clinic in central Edmonton providing comprehensive eye exams, dry eye treatment, myopia control for children, and diabetic eye screening, and is set up for families, seniors, and patients managing chronic conditions."
Now the page states the conditions it handles and the people it is right for. When an answer engine matches a buyer's specific question to a source, this is the raw material it matches on: named conditions, a named place, and stated use cases. The slogan matched nothing; the rewrite matches a dozen real queries.
## The law firm: "trusted advocates on your side" becomes practice areas and jurisdiction
Naming practice areas, jurisdiction, and credentials is how authority and attribution work in practice, rather than as a claim about themselves. Law firm About copy is often the most abstract of all:
> "We are trusted advocates who fight for you and stand on your side when it matters most."
An AI system asked "who handles child custody cases in Alberta" or "family lawyer for a divorce near me" cannot use one word of that. It names no practice area, no jurisdiction, no credential. The evidence version does all three:
> "Bearspaw Law is a family and personal injury law firm practising in Alberta, handling divorce, child custody, and motor vehicle injury claims, with lawyers called to the Alberta bar and free initial consultations for injury cases."
The rewrite gives an answer engine what it needs to trust and attribute the passage: the specific practice areas, the jurisdiction the firm is licensed in, and a credential it can point to. That matters because AI systems actively decide which passage to attribute. OpenAI's own help docs confirm ChatGPT search responses can include inline citations and a Sources panel, which means the system is choosing, per answer, whose sentence to quote and link.
ChatGPT search responses can include inline citations and a Sources panel; the system picks which passage to attribute, so the passage has to carry the facts that earn the attributionSource: OpenAI Help Center, ChatGPT search citations
## What the four rewrites changed, side by side
Every rewrite made the same trade: it dropped the adjectives and stated the facts. The table below shows what each vague version omitted and what the evidence version put in its place.
| Business | Vague version | What the evidence version added |
| --- | --- | --- |
| Dentist | "family-focused, patient-first care" | Named clinic, exact procedures (implants, Invisalign, same-day crowns), southwest Edmonton, evening and Saturday hours |
| Contractor | "quality workmanship you can trust" | License and insurance, 10-year written warranty, Edmonton and Sherwood Park service area, two-day install timeline |
| Optometrist | "your vision is our priority" | Eye exams, dry eye treatment, myopia control, diabetic screening, central Edmonton, who the clinic is right for |
| Law firm | "trusted advocates on your side" | Named practice areas, Alberta jurisdiction, bar credentials, free injury consultation |
The shared pattern is easy to see once the versions sit next to each other. Every rewrite did the same five things: it named the business, said exactly what the business does, pinned it to a place, showed who it is for, and gave one checkable fact. The vague version did none of those; the evidence version did all of them, and that is the entire difference between a passage an AI can cite and one it skips.
This is the pattern in action, not the method. Turning it into a repeatable set of questions you run against every paragraph on your site, so you can catch mood copy before it ships, is its own piece in this series on writing evidence instead of marketing copy. Here the point is narrower and worth sitting with: your About page is the page an answer engine reads to learn who you are, and right now it is probably the page you wrote with the least regard for stating a single fact.
Bing Webmaster Tools makes the stakes measurable. Its AI Performance report, launched February 10, 2026, shows only what got cited, and per Microsoft it does not measure rankings, authority, performance, or importance. If your About page carries no quotable facts, that report has nothing from it to show, no matter how well the page ranks.
## Rewrite one paragraph on your About page this week
Fix one sentence and you can watch the rest follow. Open your About page and look for a single self-contained sentence that names your business, says exactly what it does, states where, and gives one checkable fact. If that sentence is not there, write it and put it near the top. That one passage is what an AI system reaches for when someone asks who does what you do in your city.
You do not have to rewrite the whole page today. You have to give an answer engine one passage worth quoting, then a second, then a third, until the page reads like a record instead of a mood board. We are an Edmonton agency that has done this across dental, optometry, and home-services sites since 2010, now for 30 active clients, and the rewrite is almost always faster than owners expect, because the facts already exist and just were never written down. It is the same pass we run inside every [Edmonton SEO](/edmonton/seo/) engagement.
If you want the honest version of what an answer engine currently pulls from your site, [ask us](/contact/) or start with the [flagship's ten-minute check](/blog/ranking-vs-ai-citation/) and read your own About page as an extractor would. Rewriting pages into passages that stand alone as evidence is exactly what our [SEO practice](/services/seo/) does now, on every client, on the pages an AI reads first.
---
## How to Check in 10 Minutes Whether AI Cites Your Business
You can find out whether AI systems cite your business in ten minutes, for free, with no paid tool. Two things most owners treat as one come apart here: being named (your business appears in the words of the answer) and being cited (your page is attached as a clickable source). The audit is three moves. First, ask ChatGPT, Copilot, Perplexity, and Google's AI Overview the exact question a buyer types before calling you, and record for each whether you were named, cited, or neither. Second, open two free first-party dashboards, Bing Webmaster Tools' AI Performance report and Google Search Console's generative AI report, to see what those systems already did with your existing pages. The dashboards register only a link, so an answer that names you without linking you is invisible to both; the manual test is the only way to catch that. Zero data is itself an answer. Record the grid the same way every month and you can watch it move.
Most owners have never run this check, so they are guessing. Guessing is expensive here, because the answer moves: an AI system that ignored your page in March may cite it in July, and the reverse. The [flagship in this series](/blog/ranking-vs-ai-citation/) proved with our own tracking that ranking and citation are separate outcomes on the same question, measured the same day. This piece is the hands-on version: the exact ten-minute routine to find out where your business stands, using nothing but a browser and two free dashboards you may already own.
## Named and cited are two different things
Named and cited are two outcomes, not one, and the whole audit turns on telling them apart. Named means your business name appears in the words of the AI answer. Cited means your page is attached as a clickable source: a numbered footnote, an inline citation, or an entry in a Sources panel. They come apart in both directions. An answer can name you in a sentence and link you nowhere, and it can list your page as a source without ever saying your name in the prose.
That distinction is not academic, because the two free dashboards you will open in minute five register only a link. When an AI answer names your business in the sentence but attaches someone else's page as the source, or no source at all, neither dashboard records a thing about it. Our flagship test caught exactly this: asked a home-services hiring question, Perplexity named three competitors in the body of its answer and did not cite us, even though our site sat in its pool of ten retrieved sources. A dashboard that counts links would have told us nothing about that answer. The manual test is the only way to see mention-without-link.
Both free dashboards register a citation only when a link appears, so an answer that names you without linking you never shows up in either; only the manual test across the engines catches mention-without-linkSources: support.google.com/webmasters/answer/16984139; bing.com/webmasters/help/ai-performance-9f8e7d6c
## Minutes one to five: ask four engines your customer's question
Type one question, the exact one a buyer types before calling you, into four engines and watch where each one points. Write it the way a real customer would, not the way a marketer would: the plain version ("who should I hire for [your service] in [your city]") and the longer, messier version a real buyer pastes in. Run it in all four, one after another, and for each one note two things: were you named, and were you cited.
| Engine | Where to run it (free) | Where it shows sources | What to record |
| --- | --- | --- | --- |
| ChatGPT | chatgpt.com, works logged out | Inline citations you hover to preview and click to open; if none appear, a Sources panel beneath the response | Confirm the Search tool is on so it grounds the answer rather than answering from memory, then note named vs cited |
| Microsoft Copilot | copilot.microsoft.com | Numbered citations and a sources list under the answer | Whether your domain is in that list; this is the exact surface Bing's AI Performance report tracks |
| Perplexity | perplexity.ai, free tier | Clickable citations in every answer, with sources numbered at the top | That you can sit in the retrieved source list and still not be the source it built the sentence from |
| Google AI Overview | google.com | The expanded AI Overview shows linked source cards | Whether your site appears as a linked card, and separately whether your name is in the summary text |
Two engine quirks are worth a note before you trust the result. ChatGPT's search responses only include inline citations when the Search tool is active; if you do not see any, turn Search on and ask again. Perplexity puts clickable citations on every answer, which makes it the clearest illustration of the named-versus-cited gap: read its numbered sources and check whether your domain is actually one of them, because being retrieved is not the same as being quoted.
## Minutes five to ten: open the two free dashboards
Two search platforms now publish, for free, exactly which of your pages their AI systems used as evidence. Together they are the first-party half of the audit, and they cover what the manual test cannot: what these systems already did with your site across many real queries, not just the one you typed.
Bing went first. Bing Webmaster Tools added an AI Performance report on February 10, 2026, a public preview separate from the classic Search Performance report, and it requires a free Bing Webmaster Tools account with your site verified. It reports Total Citations, cited pages (and an average), grounding queries, page-level citation activity, and which grounding query mapped to which page. One limit matters above all the others: it covers Microsoft Copilot, Bing's AI-generated summaries, and select partner integrations. It does not cover ChatGPT. Anyone who tells you a Bing dashboard measures your ChatGPT presence is wrong. The grounding queries are generalized, sampled theme phrases, not the real prompts users typed, so read them as themes rather than transcripts. Data refreshes daily, is sampled (low-volume activity may not surface), and exports to CSV or Excel across 7-day, 30-day, 3-month, or custom ranges. Microsoft's June 16, 2026 update added Intents, Topics, Citation Share, and a Compare view; treat Citation Share with care, because Microsoft itself calls it observational and not a market-share number.
"A citation indicates that your content was visibly referenced or shown in an AI-generated answer. It does not represent traffic, clicks, or user engagement."; Bing counts the reference, not the visitSource: bing.com/webmasters/help/ai-performance-9f8e7d6c
Google added the second dashboard on June 3, 2026: a dedicated generative AI performance report in Search Console. It is still rolling out to a subset of properties, so you may open Search Console and not see it yet; Google says so plainly. It covers AI Overviews and AI Mode on Google Search only, not ChatGPT, Copilot, or Perplexity. The name hides a trap: it measures impressions, not citations.
Google Search Console's AI report counts an impression when "links to your site were shown to a user in a generative AI feature on Google Search"; those are impressions, not citations, and it has no query dimension to tell you which questions triggered themSource: support.google.com/webmasters/answer/16984139
The report breaks down by Pages, Countries, Devices, and Dates only. Unlike Bing's grounding queries, there is no query or keyword dimension, so it will not tell you which questions surfaced your pages. It has an Export button and caps the table near 1,000 rows.
If either dashboard is empty, that result is itself the finding rather than a glitch to troubleshoot. Empty means those AI surfaces are not currently using your pages as evidence. Bing lists the likely reasons: your content was less relevant, lacked clarity or depth, was outdated, or was outperformed by other sources. For Google, empty can also mean the report has not reached your property yet, you do not have enough impressions, or you excluded your site from Google's generative AI features, which removes you from both the report and the answers themselves.
## Record it the same way every month
A check you run once is trivia; a check you run the same way every month is a baseline. The recording method is deliberately small: one row per engine, three columns. Was your business named in the answer, was your page cited as a source, and who got named instead.
| Engine | Named? | Cited? | Who got named instead |
| --- | --- | --- | --- |
| ChatGPT | | | |
| Microsoft Copilot | | | |
| Perplexity | | | |
| Google AI Overview | | | |
Fill it on the same day, then repeat the identical run next month. The "who got named instead" column is the one that pays off: across three or four months it shows which competitors the machines trust for your buyer's question, and whether that set is shifting toward you or away. This is the owner-scale version of what we do continuously. We run this cross-engine test on our own business three times a week, measured the same day, as part of the 60,000+ data points we monitor daily. It is the same grid we keep current for every [Edmonton SEO](/edmonton/seo/) client.
Third-party trackers exist if you outgrow the manual grid. We use Semrush to track the same buyer questions across Google, Google's AI answers, and ChatGPT on a running basis, part of the tooling behind our [AI marketing](/services/ai-marketing/) work, and other AI-visibility tools are entering the market. Start with the free grid and the two dashboards anyway; you learn more running the test by hand than from a tool that hides the answer behind a single score.
## A "no" is a fixable finding, not a verdict
A row of "no" does not mean AI has blacklisted your business; it means your pages did not give the machines anything to lift. If the manual test named your competitors and your most important service page has no single sentence that states your business, your service, your city, and one checkable fact together, those two findings are the same finding. The engines had nothing standalone to quote, so they quoted someone who did.
That is an evidence problem, and evidence problems are fixable. The fix is rewriting pages into passages that stand on their own as evidence, which is its own discipline and the subject of a separate piece in this series on writing evidence instead of marketing copy. The audit tells you where the gap is; that work closes it.
The point of the ten-minute check is the direction, not the score. Run it, record it, watch the grid move month over month, and fix the pages where the "no" columns cluster. If you would rather we run it for you and hand back the grid plus the fix list, [ask us](/contact/); either way, look at both scoreboards before your competitors do. This is what our [SEO practice](/services/seo/) now tracks on every client: named, cited, and the gap between them.
---
## You Can Rank #4 on Google and Be Invisible to ChatGPT
Microsoft's Bing Webmaster Tools now reports two separate scores for a website: a Search Performance report for how well it ranks, and an AI Performance report for how often AI systems cite it as evidence in an answer. Microsoft is explicit that the second report does not measure rankings, authority, or importance; it only shows what got cited. That split makes something visible for the first time: a business can be easy to find in search and still be absent from the evidence AI systems use to build an answer. We track the same buyer questions across Google's classic results, Google's AI answers, and ChatGPT, and below is a question we rank #4 on where no AI answer cites us at all.
Search now has two scoreboards, and most businesses are only watching one. Ranking answers the old question: which page should a human visit? Citation answers the new one: which information can an AI system trust enough to use in its answer? Those are different jobs, they are measured separately, and as of this year the measurement is not agency theory. It is a product feature from the two largest search platforms.
This is the companion to [when your customers ask AI who to call](/blog/ai-who-to-call/), which showed AI reading our clients' sites 85,000 times a month while sending back a trickle of visits. That piece covered where the clicks went. This one covers the scorecard change, and what it looks like when you put the same question to every surface and compare who wins.
## Microsoft split the scorecard in February
On February 10, 2026, Microsoft added an AI Performance report to Bing Webmaster Tools, separate from the Search Performance report site owners have used for years. Search Performance still measures the familiar numbers: clicks, impressions, click-through rate, average position. The new AI Performance report measures something else entirely: which pages from your site are cited in AI-generated answers across Microsoft Copilot, Bing's AI summaries, and select partner integrations.
Microsoft's own documentation is blunt about the difference. The AI Performance report does not measure rankings, authority, performance, or importance. It shows which of your content was cited, and nothing more. On June 16, 2026, Microsoft expanded the report with query intents, topics, a Compare view, and a Citation Share metric (more on that one below).
Google did the same thing in the same quarter. On June 3, 2026, Search Console gained a dedicated reporting view for AI Overviews and AI Mode, separate from classic search performance. Two platforms that rarely agree on anything both concluded, within weeks of each other, that AI visibility needed its own report because the old one does not capture it.
That is the whole argument in one product decision. If citation were just a side effect of ranking, neither company would have needed a second report.
## The same question, three different winners
We run the test these reports imply, continuously, on our own business. Three times a week, our rank tracker checks the same set of real buyer questions across Google's classic results, Google's AI answers, and ChatGPT search. Here are three of those questions, pulled the first week of July 2026:
| The question a buyer asks | Google organic rank | Google's AI answer | ChatGPT search |
| --- | --- | --- | --- |
| "What should I shortlist when choosing an Edmonton marketing firm for PPC, web design, and CRO together?" | #4 | does not cite us | does not cite us |
| "Recommend Edmonton website developers who can rebuild my site and improve lead conversion in the next 90 days." | #5 | does not cite us | cites us as the first source |
| "Which Edmonton digital marketing agency can take over Google Ads and landing pages for a home services business now?" | #14 | cites us as the second source | does not cite us |
The same buyer question produces different winners on Google, in Google's AI answer, and in ChatGPT; ranking on one surface predicts almost nothing about citation on anotherSource: Choice OMG cross-engine tracking, July 2026
Read the rows against each other. The first question is the title of this post: we rank #4 on Google for it, page one, and neither Google's own AI answer nor ChatGPT cites us when asked the identical question. The second flips the pattern: a solid #5 on Google, ChatGPT's top citation, and nothing from Google's AI. The third inverts it again: a mediocre #14 in classic results, yet Google's AI answer cites us second, while ChatGPT ignores us.
We also put the third question to Perplexity on July 5. Its answer recommended three other local agencies by name and never mentioned us in the body, even though our site was one of the ten sources it retrieved to build the answer. That is the distinction in its sharpest form: we were in the evidence pool, and we still were not the evidence. An AI system read our page and chose someone else's passage.
Positions inside AI answers move around week to week, so treat the citation itself as the signal, not the slot number. The stable finding across months of this tracking is the one in the table: rank and citation are separate outcomes, on our own site, measured the same day.
One honest note: this is our data about our own business, published including the queries we lose. We are an agency writing about a shift that makes agencies money, so judge the claim by whether the mechanism holds when you test it on yours. The test is free and takes ten minutes; it is at the end of this post.
## Why a page can rank and still not be cited
AI answer engines do not choose pages; they choose evidence. Google describes its generative results as retrieval-augmented: the system retrieves pages from the search index, then uses specific information from those pages to compose a response, with links back to the supporting sources. Microsoft's search team says the same thing from the other direction: in grounded AI systems, factual fidelity and how content breaks into retrievable chunks matter in ways that never appear in any ranking signal.
So the question your content now has to survive is not "should a human visit this page?" It is "can this specific paragraph support a claim, on its own, out of context?"
Most service-page copy fails that test. Compare:
> "We offer trusted, full-service solutions for all your home comfort needs."
> "Kensington Heating repairs and replaces residential furnaces across west Edmonton, including same-day emergency service, with licensed gasfitters and a written quote before work begins."
A human skimming the page gets roughly the same impression from both. An AI system extracting evidence can use only the second: it names the business, the service, the area, the proof points. The first sentence contains no information an answer could be built from. Ranking systems have tolerated that kind of copy for twenty years, but citation systems reject it because there is nothing in the sentence to extract.
## What Citation Share is, and what it is not
Bing's new Citation Share metric will be misread, and Microsoft says so itself. Citation Share shows the percentage of citations attributed to your site out of all citations shown, across all sites, for the same query. Microsoft's documentation states directly that it is observational: not a ranking system, not a competitive scoreboard, not traffic share, and not a quality score.
So when this number starts appearing in marketing reports, and it will, hold it to what it actually is: a directional read on how often Microsoft's AI surfaces use you as evidence, relative to the other sources they use. It does not forecast traffic. It does not mean a percentage of buyers saw you. Anyone selling it as "AI market share" is selling the misreading.
The honest version is still valuable. A page that ranks well with zero citations has an evidence problem you can now see and fix. A page that gets cited despite a modest rank is telling you which of your content machines trust. The gap between the two scoreboards is the finding; the metric is just how you watch it move.
## The ten-minute check
Three checks, no tools required beyond a browser:
1. **Ask the machines your customers' question.** Open ChatGPT, Google (look for the AI answer), and Perplexity. Ask each one the exact question a customer would ask before calling you: "who should I hire for [your service] in [your city]," or the longer, messier version a real buyer types. Note who gets named. Note whether it is you.
2. **Check your own dashboards for the second scoreboard.** If your site is registered in Bing Webmaster Tools, open the AI Performance report and see whether anything is cited at all. In Google Search Console, look for the AI Overviews and AI Mode reporting added in June. Zero data is itself an answer.
3. **Read one key page as an extractor would.** Take your most important service page and find the first sentence that names your business, your service, and your location together with something checkable. If that sentence does not exist, an AI system building an answer from your page has nothing to lift.
If check one named your competitors and check three came up empty, those two facts are connected, and both are fixable. The fix is rewriting pages into passages that can stand alone as evidence, which is its own topic and getting its own post.
## SEO did not get harder. It got a second scoreboard.
Nothing about classic search stopped mattering; both Microsoft and Google say their AI systems draw on the same crawling, indexing, and ranking foundations underneath. What changed is that visibility now gets scored twice, ranking and citation, and the platforms themselves built separate reports because one number cannot stand in for the other.
The businesses that adapt first will be the ones that measure both, find where the two scoreboards disagree, and fix the passages instead of only chasing the positions. If you want to know what the second scoreboard currently says about your business, [ask us](/contact/) or run the ten-minute check above; either way, look at the answer before your competitors do. This is what our [SEO practice](/services/seo/) tracks now, on every client, both scoreboards at once.
---
## The First 90 Days With a Marketing Agency
Google Ads shows real signal in 2 to 4 weeks; SEO needs months 2 to 3 for ranking movement and months 4 to 6 for meaningful traffic; CRO's audit layer pays back inside 30 days. An agency cannot honestly promise final results by day 90, but it can be judged precisely on process: tracking validated before spend, a written baseline, named deliverables shipped monthly, and reporting in leads rather than impressions. This guide lays out what should happen in each of the first three months, channel by channel, the KPIs that should move by day 90, and the red flags that justify leaving before the lock-in an agency wanted you to sign.
The first 90 days are where agency relationships are won or quietly lost. Buyers judge too early on the wrong signal (rankings at day 45) and too late on the right one (whether anyone is actually working). The fix is knowing what each channel can honestly deliver, then holding the agency to the deliverables it controls.
## What to expect from an SEO agency in the first 90 days
A competent SEO agency delivers visible work in month one and measurable movement by month three.
- **Days 1 to 30: baseline and foundations.** Full technical audit, keyword baseline (we track 1,000+ positions daily from day one), analytics and Search Console access verified, tracking validated, quick technical fixes shipped (indexing, redirects, page speed), and a written plan naming target keywords and pages.
- **Days 31 to 60: production.** On-page work on the money pages, first new content shipped, structured data in place, internal linking fixed. Rankings start twitching on lower-competition terms, an early leading indicator.
- **Days 61 to 90: first measurable movement.** Ranking improvements on real target keywords in positions and impressions, even where clicks have not caught up. Competitive Edmonton verticals (dental, legal, trades) take 6 to 12 months to reach top-three positions, so day 90 is a checkpoint on trajectory, not a finish line.
By day 90 you should be able to see, in the agency's own report, which keywords moved, what shipped each month, and what is planned next. If any of those three is missing, the agency is not doing its job.
## What to expect from a Google Ads agency in the first 90 days
Paid search is faster and therefore less forgiving. Weeks 1 to 2 are setup: conversion tracking built and tested end-to-end before meaningful spend (campaigns launched without validated tracking are the single most common agency failure), campaign structure, negative keywords, and a realistic budget based on local CPC data (Edmonton high-intent keywords run $5 to $35 per click). Weeks 2 to 4 produce the first real signal: actual cost per lead on live data. Months two and three are optimization: search-term pruning, bid strategy, ad copy tests, landing page fixes. Measurable results inside 2 to 4 weeks is the honest standard; an ads agency with nothing to show at day 30 rarely improves later just because it gets more time and budget.
## Realistic KPIs for the first 90 days
Judge each channel on what it can actually move by day 90.
| Channel | Should move by day 90 | Should NOT be promised by day 90 |
| --- | --- | --- |
| SEO | Ranking positions on target keywords, impressions, indexed pages, technical health | Top-3 positions in competitive verticals, meaningful revenue from organic |
| Google Ads | Cost per lead, conversion rate, wasted-spend share, lead volume | Cheapest possible CPL (optimization compounds for quarters) |
| CRO | Conversion rate on fixed pages (audit fixes lift 10 to 30% inside 30 days), tracking accuracy | Compounding test wins (testing programs mature over 6 to 12 months) |
| Local SEO | Profile completeness, review velocity, local impressions | Map-pack dominance in a dense category |
The five KPIs worth watching across all of it: qualified leads, cost per lead, conversion rate, keyword visibility on the terms you actually sell against, and revenue attributed to channel. Impressions, clicks, and "engagement" are diagnostic metrics. A report that leads with them instead of leads and cost per lead is worth questioning.
## What your agency should deliver in month one, regardless of channel
Month one has a universal checklist: your accounts under your ownership with the agency added as a manager; conversion tracking built and validated before budget flows; a written baseline (current rankings, traffic, cost per lead) that future reports will be compared against; a plan with named deliverables per month; and a named specialist you can reach. Every item is verifiable by a non-technical owner in one sitting, and together they predict the next year better than any early metric. We publish our own operating cadence as the standard we accept being held to: budgets verified every 30 minutes, site health checks every day, and daily keyword tracking from day one.
## Red flags in the first 90 days
Leave early if you see these, because they do not improve with tenure: no baseline documented in month one (nothing to compare month six against); reporting that leads with impressions and clicks; an empty change history in the ad platform (Google Ads and Meta log every change, so "we optimized weekly" is checkable); tracking still broken at day 30; deliverables that cannot be named when you ask "what shipped last month?"; and a push to extend the contract before the first results checkpoint. The full pre-signing version of this list is in our guide to choosing a marketing agency in Edmonton.
## When to be patient and when to fire
Be patient with SEO results and impatient with process. A missing month-one baseline matters far more than rankings sitting still at day 45. The decision rule: judge ads agencies on leading results at day 30 to 45, when cost per lead exists and is trending, and judge SEO agencies at day 90 on trajectory plus shipped work rather than final positions. If the process checklist above is intact and the leading indicators point the right way, month four is where compounding starts. If the process is broken at day 90, more months give the agency time without giving you results. Month-to-month terms exist precisely so this decision stays yours, which is why we run every engagement that way after the first three months.
## The 90-day checkpoint list
| Day | Ask | Pass looks like |
| --- | --- | --- |
| 14 | Is tracking live and tested? | A test lead appears in the ad platform and the CRM |
| 30 | Where is the baseline? | A written document with starting rankings, traffic, CPL |
| 45 | What changed in the account? | Platform change history matches the invoice |
| 60 | What shipped and what is next? | Named deliverables, named owner, dated plan |
| 90 | What moved? | Keywords up on targets, CPL trending down, report in leads |
We run this exact play for 30 clients, and the first 90 days are documented in the same reports the clients see. Our fees for it are published on the Edmonton pricing page; if you want the checkpoint list applied to an agency you are already paying, book a 15-minute call and bring their last report.
## Sources and further reading
---
## The Meta Pixel Is a Liability on Canadian Healthcare Websites
More than $30 million: that is what US health systems have paid to settle claims that the Meta Pixel on their websites sent patient information to Facebook. The same pixel runs on Canadian dental and healthcare websites right now. Canada's privacy commissioner has already found that sending customer data to Meta without consent violates federal privacy law. What happened in the US, what Canadian and Alberta law already says, how to check your own site in five minutes, and the architecture that fixes it.
## What the pixel actually sends from a practice website
The Meta Pixel does not need a form submission to create exposure. A page URL like `/services/periodontal-disease/` plus a persistent identifier is already a link between an identifiable person and a health concern. That is the entire mechanism behind the US litigation, and it runs on an ordinary page load.
Walk one booking flow and count what leaves the browser.
A patient searches for gum disease treatment and clicks through to your periodontal page. The pixel fires a PageView event. Meta receives the full page URL with the condition in the path, the referring page, the visitor's IP address, and the identifiers that tie the visit to a person: the `_fbp` cookie the pixel sets in the browser, and, if the visit came from a Facebook or Instagram ad, an `fbclid` click ID that maps back to the specific account that clicked.
The patient clicks Book an Appointment. If a standard event is configured on that button (Schedule, Lead, Contact), the pixel reports the intent, not just the visit.
The patient lands on the booking confirmation page. The pixel fires again, this time from a URL that only people who booked ever see.
Assemble the three hops and Meta holds a record that a specific, identifiable person moved from reading about periodontal disease to booking treatment at your practice. No name was typed. No form field was captured. The URL trail plus the cookie did all the work, and none of it is a malfunction; this is the pixel operating exactly as designed, on infrastructure the practice chose to install.
## What US health systems have already paid
More than $30 million in two settlements alone: $12.225 million from Advocate Aurora Health and $18.4 million from Mass General Brigham, with Novant Health adding another $6.6 million. Advocate Aurora notified roughly 3 million people that they were potentially affected; the settlement class is understood to be around 2.5 million individuals. The Mass General Brigham settlement named 38 provider entities, including Massachusetts General Hospital, Brigham and Women's Hospital, and Dana-Farber Cancer Institute.
| Organization | Settlement | Class period | What was disclosed |
|---|---|---|---|
| [Advocate Aurora Health](https://www.hipaajournal.com/advocate-aurora-health-settles-pixel-lawsuit-for-12-25-million/) | $12.225 million | Oct 2017 to Oct 2022 | Meta Pixel and Google Analytics data from its website, MyChart portal, and LiveWell app |
| [Mass General Brigham](https://www.hipaajournal.com/mass-general-brigham-settles-cookies-without-consent-lawsuit-for-18-4-million/) | $18.4 million | May 2016 to Jul 2021 | Cookies, pixels, and analytics tools used on its healthcare websites without visitor consent |
| [Novant Health](https://www.hipaajournal.com/novant-health-pixel-privacy-breach-settlement/) | $6.6 million | May 2020 to Aug 2022 | Protected health information of up to 1,362,296 MyChart portal users, disclosed to third parties including Meta |
The settlements are the narrow end of the problem. Plaintiffs' experts in the [consolidated Meta Pixel healthcare litigation](https://www.cohenmilstein.com/case-study/in-re-meta-pixel-healthcare-litigation/) (N.D. Cal., Case No. 3:22-cv-03580) have identified at least 664 hospital systems or medical provider web properties where Meta received patient data via the Pixel. Regulators moved too: in July 2023, [HHS's Office for Civil Rights and the FTC jointly warned approximately 130 hospital systems and telehealth providers](https://www.ftc.gov/news-events/news/press-releases/2023/07/ftc-hhs-warn-hospital-systems-telehealth-providers-about-privacy-security-risks-online-tracking) about the privacy and security risks of online tracking technologies, naming the Meta/Facebook Pixel and Google Analytics specifically.
None of this required a breach. Nobody hacked these hospitals, and no employee lost a laptop. The marketing tag was the disclosure: a piece of JavaScript each organization installed itself, doing exactly what it was built to do.
## Is the Meta Pixel legal on a healthcare website in Canada?
No Canadian court has ruled on the Meta Pixel specifically, but the federal regulator has already issued a finding on the data flow it creates. In January 2023, the [Office of the Privacy Commissioner of Canada found](https://www.priv.gc.ca/en/opc-news/news-and-announcements/2023/nr-c_230126/) that Home Depot of Canada breached federal privacy law by sharing customers' hashed email addresses and in-store purchase details with Meta, through the platform's Offline Conversions tool, without adequate consent. Privacy Commissioner Philippe Dufresne put the failure plainly: "When customers were prompted to provide their email address, they were never informed that their information would be shared with Meta by Home Depot, or how it could be used by either company. This information would have been material to a customer's decision about whether or not to obtain an e-receipt."
Swap the hashed email for a browser cookie and the purchase details for a condition-page URL, and the Home Depot pattern is the pixel pattern. The regulator's position is on record: sending customer data to Meta without meaningful consent contravenes PIPEDA, Canada's federal private-sector privacy law. A practice website that tells no one its booking flow reports to Meta is running the same undisclosed data flow, with health context attached.
Insurance defence lawyers expect the US litigation to arrive here. "Pixel liability class action litigation has not yet arrived in Canada," Brett Stephenson, a partner at insurance-defence firm Dolden Wallace Folick, [told Canadian Underwriter in 2023](https://www.canadianunderwriter.ca/insurance/why-cyber-tracking-technology-litigation-could-be-coming-to-canada-1004232320/). "Canada tends to be about five years behind the U.S. in terms of litigation trends."
PIPEDA is only the floor. Provinces layer health-specific privacy statutes on top of it, and the one with the sharpest teeth for practice owners is Alberta's.
## Why Alberta practices carry more risk than they think
In Alberta, the practice owner is personally the custodian. The [Health Information Regulation](https://www.canlii.org/en/ab/laws/regu/alta-reg-70-2001/latest/alta-reg-70-2001.html) (Alta Reg 70/2001, s.2(2)) designates regulated members of eleven health professions as custodians under the Health Information Act, explicitly including dentists (regulated members of the Alberta Dental Association and College, now the College of Dental Surgeons of Alberta) and optometrists, alongside physicians, pharmacists, chiropractors, nurses, and dental hygienists. Custodian is not a label; it is a statutory role with duties attached, and the duties belong to the regulated member, not to a marketing vendor.
Three of those duties matter here. The [Health Information Act](https://www.canlii.org/en/ab/laws/stat/rsa-2000-c-h-5/latest/rsa-2000-c-h-5.html) permits a custodian to disclose individually identifying health information without consent only on enumerated grounds, such as those set out in sections 35 and 36 of the Act, and none of those grounds covers ad-tech or marketing vendors. Section 64 requires a privacy impact assessment, submitted to the Information and Privacy Commissioner for review, before implementing a new practice or system that handles health information. Section 66 requires a written agreement with any information manager, meaning any vendor that processes, stores, or retrieves health information on the custodian's behalf.
Then there is section 23, which deserves careful wording. The section requires a custodian that collects health information "using any device that may not be visible to the individual" to obtain the individual's written consent before collecting it. A tracking pixel is, literally, a device the individual cannot see. But no Canadian court or regulator has applied section 23 to web tracking, and whether that wording reaches an invisible pixel on a practice website is an untested reading of the statute. The honest framing is narrower than a compliance claim: Alberta's health privacy law contains a provision that maps uncomfortably well onto how a pixel behaves, and no practice wants to be the test case that settles the question.
## How do I check if my website sends patient data to Facebook?
The check takes five minutes and requires nothing but Chrome.
1. Open your online booking page in Chrome. Use a regular window without an ad blocker, so you see what a typical patient's browser sends.
2. Open DevTools (F12, or right-click and choose Inspect), select the Network tab, and reload the page.
3. Type `facebook` into the filter box. Requests to `connect.facebook.net`, or a script called `fbevents.js`, mean the Meta Pixel is loading and reporting.
4. Repeat on a condition or service page (your implant page, your periodontal page) and on the booking confirmation page, the page a patient only sees after booking.
5. Install [Meta Pixel Helper](https://developers.facebook.com/docs/meta-pixel/support/pixel-helper/), Meta's own free Chrome extension. Its entire purpose is to show which pixels fire on a page and what they send; even Meta assumes site owners need help auditing their own pixel.
A pixel request on the booking confirmation page means Meta is told, visit by visit, which identifiable browsers completed a booking at your practice.
While the Network tab is open, run the same filter for `google` and `tiktok`. The logic in this post is not Meta-specific: any third-party tag that receives condition-page URLs alongside a persistent identifier creates the same data flow, and Google Analytics appeared alongside the Meta Pixel in the Advocate Aurora settlement and in the regulators' warning letters.
If the checks come back clean, decide who keeps them clean. Pixels get added during website tweaks, plugin installs, and agency handovers, usually without anyone consciously deciding to add them.
## Do you have to remove the pixel entirely?
No. The fix is architectural, not abstinence. A practice can keep measuring its marketing; what changes is where the data goes and what it contains, in four moves:
**Keep third-party pixels off booking and confirmation pages.** These are the pages where a URL alone encodes a patient relationship. No ad platform tag belongs there, whatever the rest of the site runs.
**Put a real consent management platform in front of any tracking.** Real means opt-in: nothing fires until the visitor agrees, and declining is as easy as accepting. A banner that loads the pixel first and asks questions second changes nothing about the data flow.
**Move measurement server-side.** With server-side tagging, events route through infrastructure you control before anything reaches an ad platform, and you decide what leaves: identifiers stripped, condition-level URLs generalized, health details dropped. The caveat matters. Server-side tagging by itself does not make analytics compliant, because a server that forwards everything is just a relay. The point of owning the hop is that patient data never reaches the platform at all.
**Get the vendor paperwork right.** In Alberta, a vendor that handles health information on your behalf is an information manager, and the Health Information Act requires a written Information Management Agreement with it. US vendors who describe themselves as HIPAA-compliant and offer a BAA are answering the equivalent American question; the instinct is right, but it is not the Alberta instrument.
The cost of this architecture is some lower-funnel optimization signal: fewer conversion events reach the platform, so its bidding has less to work with. That signal is disappearing anyway. [Meta's own Business Help Center](https://www.facebook.com/business/help/1402913027039332) now sorts patient portals, telemedicine platforms, and similar health and wellness data sources into a restricted category whose data sharing Meta can limit, cutting off mid- and lower-funnel conversion events up to a full block on ads-related sharing in some regions. The signal you give up by building the compliant architecture overlaps heavily with the signal Meta is already withdrawing; the compliant design and the platform's own direction converge.
This is how we run [Meta advertising accounts](/services/meta-ads/) from day one: server-side Conversions API, with the practice controlling what crosses the wire.
## A rogue pixel is a silent failure
A pixel someone adds during a website tweak fails the same way a [broken conversion tag](/blog/conversion-tracking-breaks/) does: silently. Nothing looks wrong. The site loads, the forms submit, the campaigns run, and the cost accrues invisibly. The difference is direction; a broken tag quietly costs you data, while a rogue pixel quietly ships data out, with patient trust and legal exposure attached.
Both failure modes call for the same fix: monitor which tags actually fire on booking pages, with the same discipline as [daily checks on uptime and budgets](/blog/how-we-monitor-60000-data-points/), because a check you ran once last year says nothing about the plugin your website vendor installed last month.
If an agency runs your marketing, this is part of its job now. The [standards a healthcare practice should demand from an agency](/blog/healthcare-marketing-agency-standards/) include knowing exactly what fires on every patient-facing page and being able to prove it. The bar applies with extra force in [dental](/industries/dental/), where condition-specific service pages carry the whole site.
The five-minute check above is free, and worth forwarding to whoever manages your website. If you want a second set of eyes on what your site sends and to whom, [talk to us](/contact/).
This article is implementation and technical-configuration guidance, not legal advice. Consent wording, custodian obligations, and anything that turns on your practice's specific circumstances belong with a privacy lawyer licensed in your province.
---
## How to Choose a Marketing Agency in Edmonton
Six structural checks decide whether an agency will grow your business or its own invoice: how it charges, who owns your accounts, who actually does the work, how long you are locked in, what it reports on, and whether its claims can be verified. Rankings and reviews are the starting shortlist, not the decision. This guide gives you the exact questions to ask an Edmonton web design company or marketing agency, the red flags that end a conversation, what a proposal must include before you sign, and how to audit the work afterward without any technical knowledge.
Every agency demo looks the same: a confident deck, a wall of logos, a dashboard with green arrows. The differences that matter are contractual and structural, and none of them show up in the pitch. They show up in six places you can check in a single meeting.
## What questions should I ask before hiring an Edmonton web design company?
Ask these ten questions, in this order. A good Edmonton web design company answers all ten without hesitation.
1. **What is the total fixed price, and what does it include?** Fixed-scope quotes protect you; hourly billing rewards slowness. Professional Edmonton builds run $3,000 to $8,000 CAD for a small business (see our published price list).
2. **Who owns the site, the domain, and the hosting when we part ways?** The only acceptable answer is "you, all of it."
3. **Will I be able to edit the site myself?** You should not pay an agency to change a phone number.
4. **How will you protect my existing rankings during a redesign?** Listen for "URL mapping" and "301 redirect plan." A redesign without one throws away your search equity.
5. **What happens after launch?** Sites break silently. Ask who notices, and how fast.
6. **Can I see three live sites you built for businesses like mine?** Then load them on your phone and time them.
7. **What page speed and accessibility targets do you build to?** Core Web Vitals and WCAG should be in the answer, in writing.
8. **Is SEO architecture included or an upsell?** Titles, headings, schema, and sitemap belong in the build, not in a second invoice.
9. **How do you track leads from the new site?** A site without conversion tracking is a brochure.
10. **What is the timeline, and what do you need from me?** Content readiness, not design, is the usual bottleneck.
## The five questions to ask when designing the website itself
The design conversation is simpler than agencies make it. Five questions cover it: Who is the site for, and what one action should each visitor take? What are the three pages that will earn money, and what does each need to say? What proof (reviews, case results, credentials) will sit next to every call to action? How will someone on a phone with one bar of signal experience it? And what gets measured after launch to know whether it works?
## What to look for when hiring a marketing agency
Six criteria separate a growth partner from an invoice machine.
- **Flat fees, not a percentage of ad spend.** Percentage pricing (10 to 15% is the industry norm) pays the agency more when you spend more, not when you convert more.
- **You own every account.** Ad accounts, analytics, pixel, Business Profile, website. Agency-owned assets are a hostage situation priced as a convenience.
- **A named specialist.** "Our team" usually means rotating junior staff or offshore contractors. Ask who, by name, touches your account weekly.
- **Month-to-month terms.** An agency confident in its work does not need a 12-month lock-in to keep you.
- **Reporting in leads and cost per lead.** Clicks, impressions, and "engagement" are what agencies report when leads are not there.
- **Verifiable proof.** Named case studies with numbers, a review profile you can audit, and a physical local presence you can visit.
## Red flags that should end the conversation
Any one of these is a reason to walk: a fee calculated as a percentage of your ad budget; a contract longer than three months with auto-renewal; ad accounts or websites the agency owns "for your convenience"; guaranteed rankings (nobody controls Google); a quote dramatically below market ($300 SEO means automated software or link schemes, which earn penalties); reports that lead with impressions; and pressure to sign in the first meeting.
### Red flags specific to CRO agencies
Conversion rate optimization has its own tells. Walk away from a CRO agency that proposes A/B tests before auditing your tracking (most conversion problems are broken forms, broken tracking, and slow pages, not button colors); that cannot show you a testing plan before you sign; that promises a specific conversion rate; or that charges per test. The audit-and-fix layer typically lifts conversions 10 to 30% in the first 30 days without a single test, so an agency that leads with a six-month testing roadmap is selling process, not results.
## What should a proposal include before you sign?
A signable proposal has five things: **scope** written as named deliverables per month, not "ongoing optimization"; **price** as a flat figure with anything variable itemized; **ownership** stating in writing that accounts, data, and creative are yours; **measurement** naming the KPIs the agency expects to move and by when; and **exit terms** covering notice period and what gets handed over. If any of the five is missing, ask for it in writing. An agency that resists putting scope on paper is planning to define it later, in its own favor.
## How to audit your agency's work without technical knowledge
You can verify an agency's work in an afternoon with no technical skills.
1. **Check your access.** Log into your own ad account, analytics, and Business Profile. If you cannot, that is the finding.
2. **Compare invoice to ad spend.** In the ad platform's billing tab, the platform's own number should match what your report claims you spent.
3. **Read the change history.** Google Ads and Meta both log every change with a timestamp. An account "managed weekly" with no changes for two months is unmanaged.
4. **Count leads yourself for one month.** Tally the calls and form fills you actually received and put it next to the report.
5. **Ask "what did you change last month and why?"** A real operator answers specifically in plain language. A coordinator reads the dashboard back to you.
## Freelancer, specialist, or full-service agency?
Match the structure to the job. A freelancer fits a one-time project with a clear spec and a budget under roughly $3,000, and you accept single-person availability risk. A specialist firm fits when one channel is clearly your bottleneck and you want depth in it. A full-service agency fits when your website, ads, and search visibility need to work as one system: a redesign that ignores your rankings, or ad campaigns pointed at a slow site, is how single-channel work quietly fails. The honest trade-off is that full-service only helps if each discipline is actually staffed by a specialist rather than one generalist wearing four hats; ask who, by name, owns each channel.
## Is it worth hiring a marketing agency at all?
Not always. If your revenue depends on two or three large contracts a year won through relationships, or you cannot yet afford roughly $1,500 per month consistently, referrals and an in-house effort will beat a starved retainer; spend the money on a fast website and a complete Google Business Profile first. Hiring makes sense when there is real search demand for what you sell, you can fund both the fee and the ad spend for at least a quarter, and you would rather buy a working system (tracking, campaigns, reporting) than build one. The agency should be able to tell you within one discovery call whether your market and budget clear that bar, and a good one will tell you when they do not.
## How to compare Edmonton agencies beyond rankings and reviews
Rankings and reviews build the shortlist; verification picks the winner. Confirm the agency is actually in Edmonton (several pages ranking for Edmonton marketing terms are run from other provinces; an address you can visit settles it). Check their own marketing: does their site load fast, publish real prices, and rank for anything? An agency that cannot market itself is rehearsing on your budget. Ask each finalist for one client you can call whose business looks like yours. Then compare proposals on the five contents above, not on the price alone: the cheaper quote with agency-owned accounts and a 12-month term is the more expensive one.
## The shortlist checklist
| Check | Keep on the shortlist | Cross off |
| --- | --- | --- |
| Pricing model | Flat fee, published or quoted up front | Percentage of ad spend |
| Contract | Month to month | 12-month lock-in, auto-renewal |
| Ownership | You own accounts, site, and data | "We host everything for you" |
| Staffing | Named specialist per channel | "Our team handles it" |
| Reporting | Leads and cost per lead | Clicks and impressions |
| Proof | Named local case studies, auditable reviews | Logo walls and testimonials without numbers |
We publish our own answers to every question in this guide: flat fees from $1,200 per month for ad management, web design from $3,000 fixed-scope, month-to-month terms after the first three, and full client ownership of every asset, all on our Edmonton pricing page. If you are building a shortlist, book a 15-minute call and put these questions to us first.
## Sources and further reading
- Choice OMG Edmonton pricing: the published price list referenced throughout this guide.
- Why we do not charge a percentage of ad spend: the full argument on pricing-model incentives.
- What SEO actually costs: why $300 SEO is a penalty machine.
- Choice OMG on Clutch (4.9, 11 reviews) and our Google Business Profile (4.7, 76 reviews): the auditable review profiles we hold ourselves to.
- Google Ads change history and billing documentation: the platform-native records any client can use to audit any agency, including us.
---
## What Healthcare Practices Should Demand From a Marketing Agency in 2026
Judge a healthcare marketing agency on patients booked, not traffic delivered. Dental and eye-care practices buy marketing differently than retail or e-commerce, and the agencies that win on a sales call are rarely the ones that can prove a patient came from the work. Below are five standards to demand before you sign, drawn from how practice owners are actually coached to evaluate agencies, plus what changes if you run a dental group, a DSO, or a specialty eye-care clinic.
Most advice on choosing a marketing agency is useless because every agency already knows how to pass it. They have case studies. They have a clean-sounding process. They have five-star reviews from clients who cannot actually tell whether the work moved the needle.
Healthcare practices need a sharper filter. Dentistry and eye care are not retail, not e-commerce, not SaaS. Patient behavior is shaped by insurance, by trust, and by treatment-specific decision paths that a generalist agency does not understand. The standards below are the ones that separate an agency that grows your practice from one that grows its own invoice.
## Demand #1: Specialization you can test with one question
A generic agency fails on contact, and there is a single question that exposes it: "Name your dental (or eye-care) clients, and show me their new-patient or booked-consult results."
This is the question practice owners are coached to ask, including by neutral authorities like the [American Optometric Association](https://www.aoa.org/). An agency whose site lists plumbers, law firms, and dentists side by side cannot answer it well, because horizontal marketing chops do not transfer to a vertical where the conversion path runs through insurance verification, treatment plans, and chair time.
Specialization is the cheapest, highest-leverage screen you have, and it is where most agencies look exactly like everyone else.
## Demand #2: Attribution from the ad to the booked appointment
Traffic is not the product. The product is a patient in the chair, and the agency should be able to trace the path.
The disqualifying question here is blunt: "Can you trace a patient from the ad they clicked to the appointment they completed?" If the answer is impressions, clicks, and rankings, the agency is reporting on activity, not outcomes. What you should demand is reporting denominated in calls, booked appointments, cost per new patient, and treatment production.
The one question that filters agencies: can you trace a patient from the ad they clicked to the appointment they completed? If the answer is rankings and impressions, keep looking.
This is the baseline that distinguishes [a real dental marketing program](/industries/dental/) or [eye-care program](/industries/optometry/) from a dashboard of vanity metrics. We have written separately about [what happens when the measurement layer is the thing that is broken](/blog/edmonton-digital-marketing-agency-red-flags/), which is the norm rather than the exception.
## Demand #3: Month-to-month terms, full ownership, and a signed BAA
Fair terms are a feature, not a favor. The agencies worth hiring offer month-to-month engagements and let you keep what you pay for.
Demand three things in the contract:
- **No long lock-in.** Month-to-month keeps the agency earning your business every month. A twelve-month handcuff protects the agency, not you.
- **Full ownership of your assets.** Your website, your ad accounts, your analytics, your data, and your tracking should be yours, in your name, so you can walk without starting over.
- **A signed Business Associate Agreement.** Any agency touching patient data or healthcare advertising should sign a BAA without hesitation. Reluctance here is a compliance red flag.
Be wary of percentage-of-ad-spend pricing, which quietly rewards an agency for growing your budget rather than your results. We charge [a flat fee for exactly this reason](/blog/why-flat-fees/).
## Demand #4: Honest timelines and honest spend ranges
An agency that promises fast SEO is lying, and a healthcare practice should know the real curve before it signs.
Paid search can surface patient inquiries in 2 to 4 weeks. Local SEO and content take 3 to 6 months to gain meaningful traction. Reputation shifts take roughly 90 days. Any agency promising instant organic results is selling something it cannot deliver.
On budget, treat published figures as planning anchors, not guarantees. Established practices commonly invest in the range of 4 to 10 percent of revenue in marketing, with newer practices spending more in their first year to build a patient base. New-patient acquisition costs run into the low hundreds for general dentistry and routine eye care, and considerably higher for implants, cosmetic, refractive surgery, and other premium procedures. The honest answer is that the number varies widely by metro, specialty, and competition, which is exactly why your own measured numbers matter more than any benchmark.
## Demand #5: If you run a group or DSO, demand per-location numbers
Blended averages hide the practices that are failing. Multi-location groups and DSOs should refuse aggregate reporting and insist on per-location detail.
Acquisition cost varies dramatically between locations, so a healthy group-wide average can mask three sites quietly losing money. What a group should demand is attribution that bridges click to lead to booked appointment to practice-management-system revenue, broken out per location, and presented in a form a board or a private-equity sponsor can actually review. That is the bar for [DSO and dental group reporting](/industries/dental/dso/) and for [multi-location optometry groups](/industries/optometry/groups/), and most agencies cannot clear it.
## Where dental and eye-care differ
The five demands above are universal. A few things change by vertical.
### Dental practices, specialists, and DSOs
Solo owners and group decision-makers are structurally different buyers. A solo practice buys like a small business: it wants niche proof, transparent ROI tied to patient growth, and no lock-in. A DSO or group buys like an enterprise, with reporting obligations, ROI thresholds, and quarterly reviews that an independent practice never faces. The wedge for groups is per-location attribution and committee-grade reporting. The compliance bar, including the BAA, is non-negotiable. Specialty practices (implant, ortho, perio, endo) carry higher case values and higher acquisition costs, so the attribution detail matters even more.
### Eye-care and optometry practices
In eye care, the subspecialties behave like different businesses. A cash-pay dry-eye clinic, a LASIK practice, a routine optometry office, and a cataract surgical group have different patients, different economics, and different conversion paths. A single generic campaign underperforms across all of them. Demand an agency that treats each line separately rather than running one undifferentiated push. Note too that the buying groups many independent optometrists belong to, such as IDOC, Vision Source, and PERC, sell marketing services to their own members, so you are often weighing an independent specialist against your alliance's in-house option. Judge both on the same five standards.
## Be skeptical of precise-sounding benchmarks
Precision does not guarantee truth: the dental and eye-care marketing space is full of confident statistics that do not survive scrutiny.
When we examined the commonly cited figures, the ones that fell apart included specific cost-per-lead tables by procedure, claims that a fixed share of dentists are unsatisfied with their marketing, assertions that schema markup lifts AI-search citations by a precise percentage, and tidy channel-by-channel acquisition-cost tables. They get repeated because they sound authoritative rather than because they were measured.
Do not let an agency sell you on industry averages: make it show you what it can measure in your account, in your market, for your patients. A real benchmark is the one you generate yourself.
## The standard, in one line
Every demand on this page reduces to a single test: can the agency tie a dollar you spend to a patient who sat in your chair? Specialization, attribution, fair terms, honest timelines, and per-location detail are all just different ways of asking it.
If you want a team that reports at the booked-appointment level instead of the impression level, that is how we run [dental](/industries/dental/) and [eye-care](/industries/optometry/) marketing. [Talk to us](/contact/) and ask us the hard question first.
---
## AI Is Not Replacing the Web. It Is Re-routing It.
The click-first model of digital marketing is breaking, but search is not dead. AI assistants, AI Overviews, social video, and Google Business Profiles increasingly resolve a buying decision before a customer ever reaches your website. The winning move for SMBs is to widen the definition of visibility: be present in search, maps, reviews, social discovery, and AI answers, not only in blue links.
For the last 20 years, most digital marketing strategy has been built around a simple assumption:
People search.
They click.
They land on your website.
Then they convert.
That model still holds some truth, but it no longer covers the whole picture.
AI, social video, Google Business Profiles, map packs, reviews, automated ad systems, and zero-click search are changing where people spend their time and how they make decisions online.
The most important shift is not that everyone suddenly stopped using Google.
They have not.
The more important shift is that more of the decision now happens before a person ever reaches your website.
That is the change businesses need to understand.
I work with small and medium-sized businesses that still get real leads from Google every day, so I do not buy the lazy claim that "search is dead."
But I do think the click-first model is breaking.
## The misleading statistic: AI sends very little referral traffic
One of the easiest mistakes to make right now is to look at referral traffic and conclude that AI is not very important.
On paper, Google still dominates measured web referrals. AI assistants send a tiny share of traffic compared with traditional search. If you only look at analytics dashboards, AI can look like a rounding error.
That interpretation is dangerous.
Referral traffic only measures visits that happen after someone clicks.
AI assistants are designed to answer questions inside the interface. Google AI Overviews are designed to answer directly on the results page. Social platforms are designed to keep users inside the feed. Maps and review platforms often resolve local intent without requiring a website visit at all.
So when AI sends very little referral traffic, that does not prove AI is irrelevant.
It may prove the opposite.
It means AI can influence the decision without sending the click.
That is the real strategic issue for businesses.
## The click is disappearing before the customer disappears
The [Reuters Institute Digital News Report 2026](https://reutersinstitute.politics.ox.ac.uk/digital-news-report/2026) gives us a useful lens for understanding this shift.
Globally, social and video platforms have now become the most-used way people access online news. Reuters Institute data reported that 54% of respondents accessed news through social and video platforms, ahead of TV at 52% and news websites or apps at 51%.
That does not mean every business should become a media company.
But it does show a larger behavioural shift: people are getting more information from platforms that summarize, recommend, rank, curate, or package content before the user ever reaches the original source.
The North American correction matters, though.
The evidence does not support the simplistic claim that AI chatbots are rapidly replacing search for news in the United States or Canada. In mature markets, AI-for-news usage appears more uneven and less explosive than the hype suggests.
The bigger issue is referral collapse.
A Reuters Institute-related 2026 report, covered by [The Guardian](https://www.theguardian.com/media/2026/jan/12/publishers-fear-ai-search-summaries-and-chatbots-mean-end-of-traffic-era), found that publishers expect search referrals to fall sharply over the next three years. It also reported that Google search traffic to news sites had already dropped by about a third globally, with the U.S. hit even harder.
That pattern is not limited to journalism.
It is a preview of what can happen across the broader web.
For small and medium-sized businesses, the same behaviour is spreading into commercial research:
- "What is the best physiotherapist near me?"
- "Which dealership has the best reviews?"
- "What should I look for before hiring a roofing company?"
- "Who sells industrial equipment in Alberta?"
- "Which local business is most trusted for this service?"
Historically, those questions led to search results, website visits, phone calls, and form fills.
Increasingly, they may lead to an AI summary, a map pack, a Reddit thread, a YouTube video, a TikTok recommendation, a Google Business Profile, or a chatbot-generated shortlist.
The business can still win the customer.
But it may not win the website visit first.
## Search still matters, but it is no longer just "search"
Google is still central to local and commercial discovery. That is not going away.
But Google itself is changing.
Search results are becoming more answer-heavy, more visual, more automated, more personalized, and more blended with AI.
Google AI Overviews and AI Mode are part of that shift. Instead of only giving users links, Google increasingly gives users synthesized answers, comparisons, summaries, and next-step suggestions.
Recent academic research on Google AI Overviews shows why this matters. A 2026 paper, ["Measuring Google AI Overviews: Activation, Source Quality, Claim Fidelity, and Publisher Impact"](https://arxiv.org/abs/2605.14021), found that AI Overviews appeared for 13.7% of trending queries overall, but rose to 64.7% for question-form queries. Another 2026 study, ["How Generative AI Disrupts Search"](https://arxiv.org/abs/2604.27790), found AI Overviews for 51.5% of representative real-user queries in its dataset.
Those numbers differ because the query sets and methodologies differ.
That is the point.
There is no single universal "AI Overview trigger rate." The rate depends heavily on the type of query, the topic, the market, the wording, and the measurement method.
For businesses, the exact percentage matters less than the direction: AI-generated answers are becoming a normal part of the search experience.
That changes the job of SEO.
Classic SEO asked:
Can we rank?
Modern search strategy asks:
Can we rank?
Can we be cited?
Can we appear in the map pack?
Can we show up in AI-generated answers?
Can we be trusted by review systems?
Can our content be understood by machines?
Can our brand be recognized before the click?
Can our ads appear in AI-powered search surfaces?
That is a much bigger job than writing blog posts and chasing keywords.
## The rise of answer visibility
I think the next major marketing discipline for SMBs will be answer visibility.
Answer visibility means your business shows up when platforms generate, summarize, recommend, or shortlist options.
That includes:
- Google AI Overviews
- Google AI Mode
- ChatGPT
- Gemini
- Claude
- Perplexity
- Copilot
- Google Business Profile
- Google Maps
- Reddit threads
- YouTube results
- TikTok search
- Instagram recommendations
- Review platforms
- Industry directories
- Local citations
- Structured website content
The old question was:
"Do we rank on Google?"
The new question is:
"When a person or AI system asks who should be trusted, are we part of the answer?"
That is the strategic shift.
## ChatGPT is still leading, but the AI assistant market is fragmenting
Another correction matters.
A year ago, it was easier to talk about "ChatGPT" as shorthand for consumer AI. That is becoming less accurate.
Recent Sensor Tower data, reported by [TechRadar](https://www.techradar.com/pro/the-end-of-the-ai-honeymoon-chatgpt-market-share-falls-below-50-percent-for-first-time), said ChatGPT's share of the global AI assistant market fell below 50% for the first time in May 2026. The same report placed ChatGPT at 46.4%, Gemini at 27.7%, and Claude at 10.3%.
I would not build strategy around those exact decimals.
These numbers move monthly, and every tracker measures the market differently.
The more important point is that the assistant market is fragmenting.
ChatGPT remains the largest assistant, but Gemini has the advantage of Google's ecosystem: Search, Android, Chrome, Workspace, and default distribution. Claude, Perplexity, Copilot, Grok, DeepSeek, and Meta AI are all competing for different kinds of usage.
For business owners, the takeaway is simple:
Do not optimize for one chatbot.
Optimize for the systems that AI tools commonly depend on:
- Clear website structure
- Consistent business information
- Strong reviews
- Authoritative third-party mentions
- Useful service pages
- Local relevance
- Schema markup
- Accurate location data
- Original expertise
- Fresh content
- Trust signals
AI assistants are not magic.
They draw from the web, search indexes, business listings, reviews, directories, media, forums, structured data, and platform partnerships.
If your business is unclear, inconsistent, thin, outdated, or invisible across those sources, AI systems have less reason to recommend you.
## Local businesses still need Google Business Profile more than almost anything else
For local SMBs, Google Business Profile remains one of the most important assets on the internet.
That is especially true for healthcare practices, automotive services, home services, restaurants, professional services, and location-based businesses.
When people search locally, they often do not want a website first.
They want:
Who is nearby?
Who is open?
Who has good reviews?
Who looks legitimate?
Who offers the service I need?
Who can I call now?
Who has photos?
Who has recent activity?
Who has the right category?
Who looks trustworthy?
Your website matters, but your Google Business Profile may be the first conversion surface.
That means local strategy needs to include:
- Accurate categories
- Complete services
- Strong photos
- Review generation
- Review responses
- Fresh posts and updates
- Correct hours
- Location consistency
- Q&A management
- Appointment links
- Call tracking
- UTM tracking
- Local landing pages
- Structured data
- Citation cleanup
The businesses that treat Google Business Profile as a living conversion asset will outperform those that treat it as a directory listing.
## Social video is becoming a search behaviour
Younger consumers increasingly use TikTok, Instagram, YouTube, and Reddit as discovery engines.
This does not mean every business needs to dance on TikTok.
It means people want proof before they trust a business.
They want to see:
- Real work
- Real people
- Real explanations
- Before-and-after examples
- Customer stories
- Walkthroughs
- Pricing context
- Common mistakes
- Behind-the-scenes credibility
- Short answers to specific buying questions
For many SMBs, social content should not be treated as entertainment.
It should be treated as searchable proof.
A dental clinic can explain treatment options.
A mechanic can show common vehicle issues.
A physiotherapist can explain injury recovery.
A wrap shop can show installs and material differences.
An industrial supplier can explain product selection.
A B2B equipment company can show use cases.
This content can influence buyers even when it does not generate a clean last-click conversion.
That is why attribution is getting harder.
The customer may see a video, check reviews, ask ChatGPT, search the brand, look at the map listing, and then call.
If you only measure the final click, you miss the journey.
## Paid advertising is becoming more automated and less transparent
The other major shift is happening inside ad platforms.
Google and Meta are pushing advertisers toward more automation: Performance Max, AI Max for Search, Advantage+, broad match, automated creative, automated placements, and automated bidding.
There is upside here.
Small businesses can benefit from machine learning systems that find patterns faster than a human media buyer can. Automated campaigns can improve efficiency when conversion tracking is clean and creative inputs are strong.
But there is risk.
Automation can also hide where money is going, blur the difference between brand and non-brand demand, generate weak creative, expand into poor-fit queries, and make reporting harder to explain.
This is especially important for regulated healthcare, niche B2B, industrial, legal, financial, and high-trust services.
The future of ad management is not "let the machine do everything."
It is:
Give the machine better inputs.
Set stronger guardrails.
Track better conversion data.
Review search terms and placements.
Separate brand demand from new demand.
Control creative quality.
Understand where automation helps and where it hides waste.
AI will not eliminate advertising strategy.
It will punish weak strategy faster.
## The website is still important, but its role is changing
Some people hear "zero-click" and assume websites are becoming irrelevant.
That is wrong.
The website is still the source of truth. It is still where your expertise, services, locations, offers, case studies, pricing context, team, proof, and conversion paths live.
But it no longer functions only as a destination.
It is also a data source for:
- Search engines
- AI assistants
- Ad platforms
- Review systems
- Knowledge panels
- Local listings
- Social previews
- Retargeting audiences
- Sales teams
- Customers doing due diligence
A modern SMB website needs to be built for humans and machines.
That means:
- Clear service pages
- Strong internal linking
- Schema markup
- Fast loading
- Mobile usability
- Crawlable content
- Helpful FAQs
- Real expertise
- Local relevance
- Trust signals
- Clear calls to action
Thin websites will struggle.
Generic AI-written content will struggle.
Businesses that explain what they do clearly, specifically, and credibly will have an advantage.
## What SMBs should do now
The following six steps turn this into action.
### 1. Protect your local foundation
Your Google Business Profile, reviews, maps visibility, citations, service pages, and location pages need to be accurate and active.
For local businesses, this is still one of the highest-impact areas.
### 2. Build content that answers real buying questions
Not generic blog content.
Not keyword-stuffed filler.
Not "10 reasons to hire a professional" articles that say nothing.
Useful explanations that help customers make decisions.
### 3. Track more than website sessions
Website traffic may decline even while influence increases.
Track:
- Calls
- Forms
- Map actions
- Branded search
- Review activity
- Assisted conversions
- CRM outcomes
- AI referral sources
- Google Business Profile actions
- Paid and organic lead quality
### 4. Test your AI visibility
Ask ChatGPT, Gemini, Perplexity, Claude, and Google what they recommend for your service in your market.
See whether your business appears.
See who is cited.
See what information is wrong or missing.
This is not perfect research, but it is a useful diagnostic.
If AI systems cannot understand who you are, where you operate, what you offer, and why you are credible, that is a marketing problem.
### 5. Strengthen your trust signals
Reviews, case studies, testimonials, credentials, author bios, location signals, third-party mentions, and clear business information all matter more in an AI-mediated web.
Trust is not one signal.
It is the accumulated evidence that your business is real, relevant, and worth recommending.
### 6. Use ad automation carefully
Performance Max, AI Max, broad match, and Advantage+ can help, but only when conversion tracking, creative, landing pages, and account structure are strong.
Automation does not fix weak fundamentals.
It amplifies them.
## The real takeaway
AI is not replacing the internet.
It is changing the route people take through it.
People still search.
People still visit websites.
People still compare options.
People still read reviews.
People still watch videos.
People still ask friends.
People still click ads.
People still call businesses.
But the journey is more fragmented and automated, increasingly mediated by platforms before the business ever sees the visitor.
For SMBs, the winning strategy is not to abandon SEO, websites, or ads.
The winning strategy is to expand the definition of visibility.
You need to be visible in search.
Visible in maps.
Visible in reviews.
Visible in social discovery.
Visible in AI answers.
Visible in paid placements.
Visible in the places customers now make decisions.
The click has not disappeared.
But it can no longer be assumed.
And the businesses that understand that first will have the advantage.
## Sources and further reading
- [Reuters Institute Digital News Report 2026](https://reutersinstitute.politics.ox.ac.uk/digital-news-report/2026)
- [The Guardian: Publishers fear AI search summaries and chatbots mean "end of traffic era"](https://www.theguardian.com/media/2026/jan/12/publishers-fear-ai-search-summaries-and-chatbots-mean-end-of-traffic-era)
- [MarketWatch: Most people now get their news from social media](https://www.marketwatch.com/story/most-people-now-get-their-news-from-social-media-but-many-say-they-dislike-it-and-are-tuning-out-b5dfb1b2)
- [TechRadar: ChatGPT market share falls below 50% for first time](https://www.techradar.com/pro/the-end-of-the-ai-honeymoon-chatgpt-market-share-falls-below-50-percent-for-first-time)
- [Measuring Google AI Overviews: Activation, Source Quality, Claim Fidelity, and Publisher Impact](https://arxiv.org/abs/2605.14021)
- [How Generative AI Disrupts Search: An Empirical Study of Google Search, Gemini, and AI Overviews](https://arxiv.org/abs/2604.27790)
- [Google Search Central: Google Search spam policies](https://developers.google.com/search/docs/essentials/spam-policies)
- [Google Ads Help: About Performance Max campaigns](https://support.google.com/google-ads/answer/10724817)
---
## When Your Customers Ask AI Who to Call, Is It You?
When a customer needs a dentist, a plumber, or a parts supplier, more of them now ask an AI assistant, and it answers the question and names one business to call. For most local companies, that business is a competitor. Across the 28 client websites we track, we improved average Google position from 37 to 13 and earned 19% more impressions over the past year while clicks stayed flat, because the answer is now read on the results page. In the same month, AI bots read our clients' sites more than 85,000 times and sent 346 visits back. The businesses AI recommends are the ones with strong reviews, a complete Google Business Profile, and clear website content a machine can quote.
Most owners have never seen the answer AI gives about them, and their analytics will never warn them about it. The traffic looks normal, the rankings look fine, and a competitor is quietly being named to the customer before they ever reach a website. This post shows the mechanism, with our own client data, and what to do about it.
For the version of this happening fastest in one industry, see [AI Overviews are eating healthcare search traffic](/blog/ai-overviews-healthcare-traffic/). For the paid-media side of the same shift, see our [field guide to ChatGPT Ads in 2026](/blog/chatgpt-ads-2026-field-guide/) and [how we track visibility across AI platforms](/blog/ai-platform-tracking/).
## The 30-second test
Open ChatGPT, Google's AI Overview, or Perplexity right now and ask it what your customers ask. Try "best [your service] in [your city]" and "who should I hire for [their problem] in [your city]." Read the answer. Notice which businesses it names, and whether yours is one of them.
That answer is the new shelf your customers see first. Most owners have never once looked at it. Everything below explains what you just saw.
## Why did AI name a competitor instead of you?
AI does not pick a name at random; it reads the open web and recommends the business that looks most credible. It weighs your reviews, your ratings, your Google Business Profile, the directories you appear on, and the words on your own website.
We can prove it is already doing the reading. In the last 30 days, AI crawlers from OpenAI, Anthropic, Perplexity, and Google made more than 85,000 requests to read our clients' websites, and 22 of the 23 sites we monitor were visited by at least one. Some of those were not background training runs; ChatGPT, Claude, and Perplexity each fetch a live page the moment a customer's question calls for it. AI has already studied your business. The only open question is what it concluded.
It also explains why you might appear in one assistant and vanish in another. They lean on different amounts of evidence: ChatGPT cites a handful of sources per answer, around seven; Perplexity pulls from far more, around sixteen; Google's AI Overviews sit in between. And no single assistant owns the market. ChatGPT still leads, but it recently slipped below half of all assistant users for the first time as Google's Gemini gained ground, so betting your visibility on one tool is a real risk.
## Why doesn't your website report show it?
Your analytics say AI sends you almost no traffic, and that is exactly the problem: when you look at where your visits come from, AI barely registers, which feels like reassurance but is actually the opposite.
AI shows up as near-zero in your reports because it answers in place and keeps the visit for itself. Our own numbers make the gap plain: in the same month those AI systems made more than 85,000 requests to read our clients' pages, they sent back 346 visits. Enormous reading, a trickle of referrals: AI is using your business to answer the question without ever sending the person over.
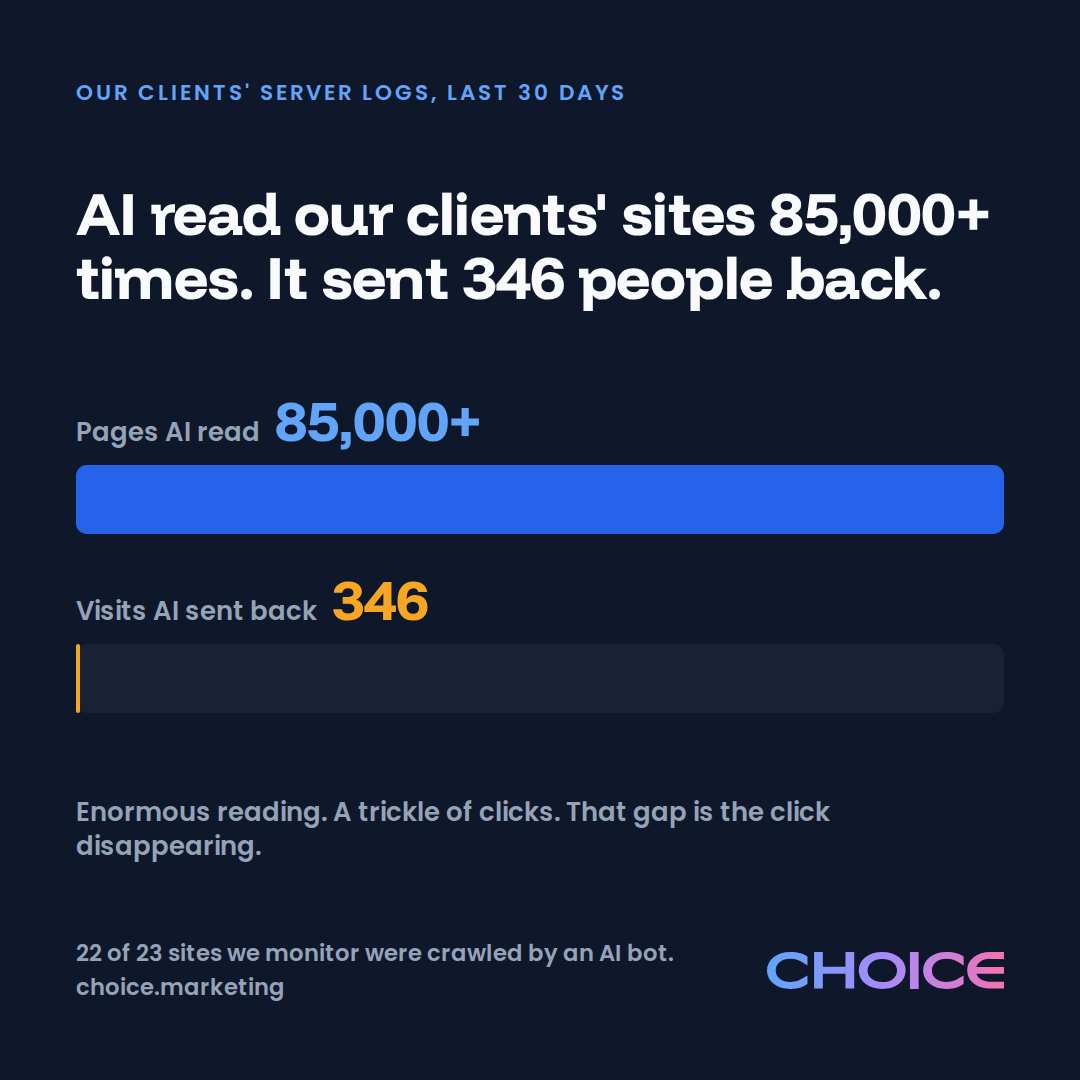
AI read our clients' sites more than 85,000 times in 30 days and sent 346 visits back; the reading is enormous and the referral is a trickle, which is the click disappearing, not AI ignoring youSource: Choice OMG server logs, 30 days to June 2026
Independent research shows the same pattern. [Pew Research Center](https://www.pewresearch.org/short-reads/2025/07/22/google-users-are-less-likely-to-click-on-links-when-an-ai-summary-appears-in-the-results/) found that when an AI summary appears on a Google result, people click a traditional link 8% of the time, against 15% when there is no summary, and they click the links inside the summary just 1% of the time. The answer satisfies the question, and the visit never happens.
It is even harder to see than that. Many of the few visits AI does send arrive with no referrer attached, so analytics tools file them under "Direct," mixed in with people who typed your address from memory. The influence is real, and your dashboard is blind to it.
## Can you rank #1 on Google and still lose the customer?
Yes, and it is happening now. Ranking at the top of Google is no longer the same as being found; our own book of business is the proof.
| Metric (28 client sites) | Mar to May 2025 | Mar to May 2026 | Change |
| --- | --- | --- | --- |
| Average Google position | 37 | 13 | ranked higher |
| Impressions | 4.80M | 5.71M | up 19% |
| Clicks | 72,200 | 75,300 | flat |
| Click-through rate | 1.50% | 1.32% | down |
We lifted our clients' average position from roughly 37 to 13 and earned them 19% more impressions, the number of times Google placed them in front of a searcher. Their total clicks barely moved. We made them higher-ranked and more visible, and the clicks did not follow, because the answer is increasingly read on the results page before anyone reaches the links.
For some clients the split was stark. One Canadian firm we manage climbed from the fifth page of Google onto the first and was shown to 31% more people; it received about three thousand fewer clicks than the year before. An Alberta eye-care clinic was shown to 45% more searchers and clicked by 16% fewer of them.
Average Google position improved from 37 to 13 and impressions rose 19% while clicks stayed flat across 28 client sites; better rankings and more visibility no longer guarantee the clickSource: Choice OMG Google Search Console, March to May 2025 versus 2026
The independent numbers match ours. An [Ahrefs study of 300,000 keywords](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/) found the top-ranked page loses 58% of its clicks when an AI Overview sits above it. [BrightEdge](https://www.brightedge.com/resources/weekly-ai-search-insights/healthcare-ai-evolution-google-2023-2025) tracked AI Overview coverage of healthcare searches climbing from 59% in 2023 to 89% in 2025, with rankings holding steady while traffic falls. The position you pay to defend is still worth holding. It just no longer pays out the way it used to.
## Is search dead?
No. Your customers have not abandoned Google; the finish line just moved earlier. People still search. What changed is where the decision gets made, and more of it now happens before the click: inside the AI answer, in the map pack, in the reviews, in a video someone watched on the way.
The [Reuters Institute Digital News Report 2026](https://reutersinstitute.politics.ox.ac.uk/digital-news-report/2026) found Google sent 38% fewer organic visits to a large set of content sites between late 2024 and late 2025, even as people kept searching. Reuters calls the wider move toward social and video "a drift, not a shift," which is the honest read: not a stampede off the web, but a steady rerouting of where attention and decisions land. For younger customers especially, the journey often starts in a feed or an assistant rather than a search bar. People do not hand AI blind trust either; they trust its answers far less than established sources and use it to narrow the field, then check. Which means your real job is to be the name that survives the narrowing.
## What does AI check before it recommends a business?
The businesses AI recommends are the ones that look most trustworthy to a machine reading the open web, and most of what it checks, you control. The answer layer reads five things before it names anyone:
- **Your reviews.** Volume, rating, and how recent they are. This is the strongest signal in local recommendation, for the machine and the human alike.
- **Your Google Business Profile.** Complete and accurate categories, services, hours, photos, and answered questions. This is still where "near me" gets settled.
- **Your website content.** Clear, specific answers about what you do, where, and for whom, structured so a machine can read and quote them. Vague homepages do not get cited.
- **Your consistency across the web.** The same name, address, and phone number everywhere, and mentions on the directories and sources the models already trust.
- **Your presence where journeys start.** Showing up in feeds and short video for the customers who begin there, not only in the search results.
None of this is rented. Unlike ad targeting, which the big platforms are automating and quietly taking out of your hands, these are signals you own and improve. That is the good news buried inside the threat: the work that wins the AI answer is the same work that has always earned trust, and it compounds over time.
## Didn't third-party cookies go away?
No, the cookie apocalypse got called off, and your measurement still got harder. Google planned to strip third-party cookies from Chrome, reversed course in 2024, and through 2025 effectively shelved the plan, so those cookies are still in place: the scare was real, but the deadline never arrived.
Tracking did get less reliable anyway, from iOS privacy controls, consent rules, and ad blockers. So the move that actually matters is not bracing for a deadline that keeps slipping. It is owning your first-party data, the customers and contacts that are yours no matter what a browser does, and keeping your tracking clean. Ignore the panic headlines; fix the fundamentals.
## See what AI says about your business
Go back and look at what AI said about you. If your name was in the answer, good; protect it. If a competitor's was there instead, that is fixable, and finding out exactly what AI is saying about your business costs nothing.
We run your business through the ten AI platforms that matter and send you a short, plain-language report: where you show up, where a competitor shows up instead, and the single change that moves the needle fastest. No cost, and no sales pitch in the report itself. The diagnosis is free. The call, if you want one, is for the plan. [Get your free AI check](/contact/).
---
## What Agencies Should Measure Now That Google Stopped Sending Clicks
Measure six layers, in this order. First, whether AI engines name and cite you: AI Mention Rate, AI Citation Rate, AI Share of Voice. Second, whether that visibility lifts demand you can see: Branded Search Lift and Google Business Profile actions. Third, whether the traffic that does arrive is good: AI Referral Quality and AI Referral Conversion Rate. Fourth, whether it becomes qualified leads and booked appointments. Fifth, whether those produce revenue at an efficient ROAS, CAC, and LTV:CAC. Sixth, underneath all of it, how much of each number is observed versus modelled. Average position and raw session counts are no longer the headline. They describe a channel that is quietly being answered before the click.
Last reviewed June 2026. The benchmark bands below are operating starting points, not guarantees; tighten them against 60 to 90 days of your own baseline. Every external claim links to its primary source.
For twenty years the agency business ran on one question: did Google send a click. Rankings produced clicks, clicks produced sessions, sessions produced conversions, and the monthly report was a tidy line from position to revenue. That chain is breaking at the first link, and a lot of agencies are still reporting as if it holds. We run measurement across [ten AI platforms](/blog/ai-platform-tracking/) and roughly [sixty thousand data points a day](/blog/how-we-monitor-60000-data-points/) on a [single source of truth](/blog/single-source-of-truth/), and the rebuild below is what that vantage point now demands.
## Why did the click stop being the unit of value?
That shift happened sometime in the last two years, and the data is no longer ambiguous. Ahrefs' December 2025 analysis, published February 2026, found that the presence of an AI Overview cut the position-one organic click-through rate by about [58 percent for the queries where it appears](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/). Pew Research, studying real browsing, found people click a traditional search link in just [8 percent of searches that show an AI summary, versus 15 percent without one](https://www.pewresearch.org/short-reads/2025/07/22/google-users-are-less-likely-to-click-on-links-when-an-ai-summary-appears-in-the-results/). The answer now appears above the results, the user reads it, and the visit never happens. The brand was still surfaced. The recommendation was still made. None of it shows up as a click.
The reporting makes the gap worse. Google now folds AI Overviews and AI Mode traffic into the standard [Web search type in Search Console](https://developers.google.com/search/docs/appearance/ai-features) rather than exposing a separate AI mention or citation metric. An AI Overview occupies a single position with all its links sharing it, and each AI Mode follow-up question is counted as a new query. So the visibility you create inside these answers is largely invisible to the dashboard you have always used to prove your work. The report says traffic is flat or down, while the real story is that the client is getting recommended more than ever in places the old tools cannot see.
Three forces are driving this, and each one degrades a different part of the report.
Zero-click search removed the click but not the exposure. Generative answers, featured snippets, and local packs increasingly satisfy the query on the results page. Google is explicit that there are no special requirements, and [no need for files like llms.txt](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide), to appear in its generative experiences: the lever is the same content quality and entity health it always was. Google also does not tell you to ignore rank, but it warns that average position is a complex metric that is easy to misread, and recommends watching [how it moves over time](https://support.google.com/webmasters/answer/7042828) rather than reading a single number. The dashboard keeps shrinking in smaller ways too. Google stopped showing [FAQ rich results in May 2026](https://developers.google.com/search/docs/appearance/structured-data/faqpage) and is removing the FAQ report and its Search Console API support across June to August 2026.
Observability loss made the surviving numbers softer. Google Analytics moves on [15 June 2026 to Consent Mode as the single control](https://support.google.com/analytics/answer/17016975) for how your data is collected and used, taking that role from Google Signals. Where users decline analytics cookies, Google [models their behaviour](https://support.google.com/analytics/answer/11161109) and [models the key events](https://support.google.com/analytics/answer/10710245) they would have produced. A ROAS figure built half on modelled conversions is not the same asset as one built on observed purchases, and a report that does not distinguish the two is quietly overselling its own certainty.
Attribution divergence made the numbers argue with each other. GA4 answers acquisition at [three different scopes](https://support.google.com/analytics/answer/11080067): user acquisition for how new users first arrived, traffic acquisition for how sessions started, and event scope for how key events are credited. User and session scope use paid-and-organic last click; event scope uses the model you select, defaulting to data-driven attribution. Those scopes legitimately produce different answers for the same channel. Teams that never wrote down which one governs end up debating dashboards instead of diagnosing marketing.
## What should I measure now? The short answer
Measure the chain from visibility to revenue, not the click in the middle of it. The table below is the whole answer in one view: fifteen metrics across six layers, each with what it answers, how it is calculated, which system owns the truth, and a starting benchmark band to tighten with your own data. The sections after it explain the layers that are new or most misread.
| Metric | What it answers | Formula | System of record | Starting band (illustrative) |
|---|---|---|---|---|
| **AI Mention Rate** | Do AI answers name us at all? | prompts naming brand ÷ prompts run | Owned prompt monitor | >25% strong on commercial prompts |
| **AI Citation Rate** | Do AI answers link our page as a source? | prompts citing an owned URL ÷ prompts run | Owned prompt monitor | >15% strong on commercial prompts |
| **AI Share of Voice** | What share of the answer space is ours? | our mentions ÷ all tracked brands' mentions | Owned prompt monitor | beat equal-share baseline |
| **Branded Search Lift** | Is AI exposure creating named demand? | (current − baseline branded clicks) ÷ baseline | Search Console | >+10% vs seasonal baseline |
| **Zero-Click Influence** | Is influence growing where no click lands? | weighted index of the five signals above, base 100 | Warehouse composite | 110+ improving, <85 alert |
| **GBP Actions** | Are people acting on the local profile? | calls + web clicks + directions + bookings | [Business Profile API](https://developers.google.com/my-business/reference/performance/rest/v1/DailyMetric) | action rate 2-5% normal |
| **AI Referral Quality** | Does AI traffic behave better than average? | engaged-session and intent index vs site mean | GA4 | 100 = site average, >120 strong |
| **AI Referral Conversion** | Does AI traffic convert? | AI sessions with a key event ÷ AI sessions | GA4 + CRM | at least organic CVR parity |
| **Qualified Lead Rate** | Are the leads any good? | qualified leads ÷ total leads | CRM | 20-40% moderate, tune by vertical |
| **Booked Appointment Rate** | Do qualified leads become appointments? | booked ÷ qualified leads | CRM / scheduling | 30-60% typical |
| **Revenue, ROAS, CAC** | Did marketing produce profit? | revenue; revenue ÷ spend; cost ÷ new customers | CRM / finance | set from contribution margin |
| **LTV:CAC** | Is the economic engine healthy? | lifetime value ÷ acquisition cost | CRM / finance | [~3:1 sweet spot](https://www.shopify.com/blog/what-is-a-good-ltv-to-cac-ratio) |
| **Modelled-conversion share** | How much of conversions is inferred? | modelled key events ÷ all key events | GA4 | report it; lower is firmer |
| **Consented-traffic share** | How much behaviour is observable? | consented sessions ÷ all sessions | GA4 / CMP | report it; watch the trend |
| **CRM match-back rate** | How much revenue reconciles? | revenue matched to a lead ÷ total revenue | CRM / finance | aim high; investigate gaps |
The discipline is to read this top to bottom, not to pick one number. A high AI Mention Rate with a flat Qualified Lead Rate is a positioning problem. A healthy Booked Appointment Rate with a collapsing Consented-traffic share is a measurement problem wearing a performance costume. The point of the stack is to tell those two apart.
## How do I measure AI visibility?
Start measuring the thing the old dashboard cannot see. If clients are now recommended, cited, and compared inside AI answers, that exposure is the new top of the funnel, and it needs its own metrics. No platform hands them to you. Google folds AI traffic into Web reporting with no citation report; OpenAI's ChatGPT Search shows users [inline citations](https://help.openai.com/en/articles/9237897-chatgpt-search) but gives site owners no analytics; Perplexity documents [crawler controls](https://docs.perplexity.ai/docs/resources/perplexity-crawlers) and a partner revenue program, not per-prompt visibility. The clearest proof that this is a build-it-yourself problem: vendors such as DataForSEO now sell an [LLM Mentions API](https://dataforseo.com/update/introducing-llm-mentions-api) that has to define "citation" versus "mention" itself, because the platforms do not. So you build the dataset: a controlled library of prompts, run on a schedule across the AI surfaces, every answer stored and parsed.
Three metrics come out of that library, and the distance between the first two is the whole game.
AI Mention Rate
Share of monitored AI prompts where the brand is named at all.
AI Citation Rate
Share of prompts where one of your own pages is actually cited as a source. A higher bar than a mention.
AI Share of Voice
Your slice of all mentions across the tracked competitor set, judged against an equal-share baseline.
The new top of the funnel. Three metrics no platform reports, built from an owned prompt library. Values shown are illustrative.
AI Mention Rate is the share of monitored prompts where the brand is named at all. AI Citation Rate is the share where one of the client's own pages is actually linked as a source, which is a higher bar and a better predictor of durable visibility. AI Share of Voice is the client's slice of all mentions across a defined competitor set, judged against an equal-share baseline so "good" means beating the field, not beating last month. None come from GA4 or Search Console. They are the closest thing we have to a ranking report for the generative era.
Two bridge metrics connect that visibility to something the business can feel. Branded Search Lift tracks growth in branded query demand against a seasonal baseline, because the most common signature of strong AI exposure is not a click from the answer, it is a person who reads it and then searches the brand by name a day later. The Zero-Click Influence Score is a deliberately derived composite that blends the AI signals with branded search and local action into one index anchored at 100. It is not a vendor-native metric and we never present it as precision. It is an honest trend line on influence that produces no click, which is exactly the influence the old dashboard zeroes out.
The bridge metrics. Strong AI exposure shows up not as a click but as branded demand and a rising influence index, each indexed to a 100 baseline. Illustrative trend.
## Which mid-funnel metrics survived the click's decline?
Local action and lead quality carry more weight now, not less. When the top of the funnel stops producing clicks, the mid-funnel signals that do survive become disproportionately valuable, and the honest move is to lean on them harder.
Google Business Profile is the clearest example. Its Performance API reports daily counts for [calls, website clicks, direction requests, bookings, and conversations](https://developers.google.com/my-business/reference/performance/rest/v1/DailyMetric), plus monthly search-keyword impressions. Those are real actions taken by real people who decided, often straight off a zero-click surface, to contact the business. For a local client, a rising action rate against stable impressions is frequently a truer read on momentum than any sessions chart.
Referral quality matters more than referral volume. Google reports that when people click from a results page showing an AI Overview, those clicks are [higher quality, meaning users spend more time on the site](https://developers.google.com/search/docs/appearance/ai-features). That matches what we see: AI-referred traffic stays relatively small but behaves better than the site average. An agency that judges AI referrals on raw volume will dismiss the best-converting traffic on the site. Judge it on engaged-session rate, contact-page reach, and conversion against the site benchmark, then track AI Referral Conversion Rate separately so quality and outcome never blur together.
## How do I prove revenue, not traffic?
The bottom of the funnel is where the report should land, and it belongs to the CRM, not to GA4. Qualified Lead Rate, Booked Appointment Rate, and revenue with ROAS and CAC are owned by the system that knows what a lead is worth. The standard economic sanity check is still an [LTV-to-CAC ratio near 3:1](https://www.shopify.com/blog/what-is-a-good-ltv-to-cac-ratio). GA4 supplies behavioural context and offline-event backfill; the CRM supplies the truth.
This matters even in the channels with the most explicit intent. WordStream's 2026 benchmarks put the average paid-search [conversion rate at 8.18 percent and cost per lead near 67 dollars](https://www.wordstream.com/blog/2026-google-ads-benchmarks): proof that even bottom-funnel demand is something you pay more to convert each year, which is exactly why the report has to end in qualified pipeline and revenue rather than in clicks. The agencies that keep their clients through this transition are the ones whose monthly report opens with qualified leads and revenue and treats traffic as the supporting cast it has become.
1
AI visibility
owned prompt library
2
Branded demand
Search Console
3
Local action
Business Profile
4
Qualified leads
CRM
5
Booked appointments
CRM / scheduling
6
Revenue, ROAS, CAC
CRM / finance
derived from owned dataobserved in client systems
The replacement chain. One chain from visibility to revenue: the top drawn from a prompt library you own, the bottom from a CRM the client owns.
## How do I know which numbers to trust?
The discipline that ties the stack together is honesty about certainty. Because so much of the funnel is now modelled, derived, or observed through a controlled prompt set rather than logged directly, every number deserves a confidence tag sitting next to it. That is not a hedge. It is the most valuable thing an agency can add to a report in 2026.
In practice it means three diagnostics ride alongside the media metrics. Modelled-conversion share tells leadership how much of the conversion count is inferred rather than observed, which matters more after the [15 June 2026 consent change](https://support.google.com/analytics/answer/17016975) tightens what gets collected. Consented-traffic share tells them how much of the behavioural data is even eligible to be seen. CRM match-back rate tells them how much of the claimed revenue actually reconciles to closed business. When those diagnostics are visible, a softening number prompts the right question, which is whether performance moved or whether observability moved. When they are hidden, the agency is one consent-rate shift away from taking credit for a modelling artifact, or blame for one.
Every number carries a confidence level. Modelled-conversion share, consented-traffic share, and CRM match-back rate tell leadership how much of the scorecard is observed versus inferred. Illustrative values.
## What this scorecard does not tell you
Honesty about limits is part of the authority. Three caveats keep this from being oversold.
The AI-visibility metrics are derived observability, not official platform metrics. Google, GA4, and the Business Profile API do not report AI Mention Rate, AI Citation Rate, or Share of Voice; they have to be built from a controlled prompt library with stable run conditions and human QA, and they are only as good as that library is representative. Treat them as a measured estimate, not a meter reading.
The benchmark bands are starting points, not law. They come from public platform documentation and vendor studies, not from a universal standard for your vertical, your city, or your service line. The right thresholds are the ones you set after 60 to 90 days of your own baseline, then revisit quarterly.
Attribution is still a judgment call. There is no single model that perfectly assigns credit across a zero-click answer, a branded search, a phone call, and a delayed close. The honest move is to report observed and modelled side by side, lock your attribution rules in writing, and validate with the CRM rather than trusting any one platform's number.
## The scorecard that replaces rankings
Stop leading with average position. The click it used to predict is evaporating, and it tells the client nothing about whether the business grew. It runs in a single chain instead: AI visibility, to branded demand, to local action, to qualified leads, to booked appointments, to revenue, with a confidence tag on every tile. The top of that chain draws on a prompt library you own. The bottom comes from a CRM the client owns. The middle is the local and behavioural signal that survived the click's decline.
This is more work than pulling a rankings export, and that is the point. The measurement gap that opened over the last two years is the clearest line in our industry between agencies that are keeping up and agencies that are about to be surprised in a renewal meeting. The clients are already being recommended in places the old dashboard cannot see. The only question is whether their agency can prove it.
For the systems behind this stack, see how we [track visibility across ten AI platforms](/blog/ai-platform-tracking/), [monitor sixty thousand data points a day](/blog/how-we-monitor-60000-data-points/), and build a [single source of truth](/blog/single-source-of-truth/) that joins all of it to revenue. For the failure mode this is built to prevent, read [what happens when conversion tracking breaks](/blog/conversion-tracking-breaks/).
---
## AI Overviews Are Eating Healthcare Search Traffic
Clicks to choice.marketing fell 70% over the past 28 days. In the same window, impressions rose to more than 25,000 and our average Google position improved from 19 to 14. No rankings were lost and no penalty was applied. That pattern is consistent with AI Overviews answering the question on the results page so fewer people click, and the independent data below backs it up. The same shape is showing up on dental and optometry practice sites right now. This post shows the numbers from three sites, explains what changed, and gives you a 90-day citation plan you can run this quarter.
Most practice owners are about to misdiagnose this. They will see clicks fall, assume their rankings dropped or their agency stopped working, and ask for more blog posts. The rankings did not drop. The click did. Those are different problems with opposite fixes, and getting the diagnosis wrong wastes a quarter.
For the broader picture of how AI answer surfaces are reshaping discovery, see our [field guide to ChatGPT Ads in 2026](/blog/chatgpt-ads-2026-field-guide/) and [how we track visibility across AI platforms](/blog/ai-platform-tracking/). This piece is about the one happening fastest to healthcare: Google's AI Overviews.
## The data: three sites, same shape
We publish our own numbers because the drop is the story, not a failure. Below is choice.marketing's Google Search Console data for the 28 days ending May 26, 2026, against the prior 28 days. Alongside it are two US dental practices we manage, shown as percentage change only.
| Site | Clicks | Impressions | Average position |
| --- | --- | --- | --- |
| Our own site (absolute) | 271 → 81 (**down 70%**) | 8,812 → 25,229 (**up 186%**) | 19.2 → 13.6 (**improved**) |
| US family dental practice | **flat** (no net change) | **up 39%** | page 2, stable |
| Second US dental practice | **down 6%** | **up 22%** | page 2, stable |
Read our own row carefully. Impressions nearly tripled, the average ranking position got better, and the click-through rate collapsed from 3.08% to 0.32%. Better rankings, far more visibility, fewer clicks. A ranking loss does not produce that combination, and it is consistent with an AI Overview intercepting the answer on the results page. It is one site, so we do not rest the case on it; the independent data below is what carries it.
The first dental practice is the cleanest example of the same mechanism on a much larger site. Its impressions rose 39% in a month and produced zero additional clicks. One of its service pages, an emergency-dentistry page that ranks on the second page of Google, saw impressions rise 170% while its click-through rate fell to roughly a third of what it was. The page did not move in the rankings. The answer simply started appearing on the results page.
Clicks down 70%, impressions up 186%, average position improved from 19.2 to 13.6 in 28 days; rankings rose while clicks fell, a pattern consistent with AI Overview interception and corroborated by the independent studies below, not a ranking penaltySource: Choice OMG Google Search Console, 28 days ending May 26, 2026
Your own site is very likely showing this shape already. Most owners have not pulled the comparison because the top-line traffic number in their analytics looks "down" and they stop there.
Our three sites are not an anomaly. Independent studies find the same pattern across the web. [Pew Research Center](https://www.pewresearch.org/short-reads/2025/07/22/google-users-are-less-likely-to-click-on-links-when-an-ai-summary-appears-in-the-results/), analyzing real Google users in 2025, found that when an AI summary appears people click a traditional result in just 8% of visits, versus 15% when there is none, and they click a link inside the summary itself only 1% of the time. [Ahrefs](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/), measuring 300,000 keywords against Search Console data, found the presence of an AI Overview correlates with a 58% lower click-through rate for the number-one result. [BrightEdge](https://www.brightedge.com/resources/weekly-ai-search-insights/healthcare-ai-evolution-google-2023-2025), tracking healthcare specifically, said it plainly: a Position 1 ranking no longer delivers the traffic it did, and practices seeing organic declines while rankings hold steady are almost always looking at AI Overviews.
8% click rate with an AI summary versus 15% without (Pew Research); a 58% lower click-through rate for the top result when an AI Overview is present (Ahrefs, 300,000 keywords); the click loss is an independently measured, industry-wide effect, not a quirk of our accountsSource: Pew Research Center, July 2025; Ahrefs, 2025-2026
## Why healthcare gets hit harder than other verticals
Three structural reasons, and they compound.
**Health queries are disproportionately informational, and informational is what triggers an Overview.** [Ahrefs](https://ahrefs.com/blog/ai-overview-triggers/), analyzing 146 million search results in 2025, found that 99.9% of the keywords that trigger an AI Overview are informational, and that health and medical queries trigger one 43% and 44% of the time, more than double the roughly 21% baseline across all queries. "Do dental implants hurt," "how long do dental implants last," "how often should I get an eye exam," "is dry eye permanent." These are exactly the questions AI Overviews are built to answer in a paragraph. A query like "emergency dentist near me" still drives a click; a query like "is a cracked tooth an emergency" now gets answered in-pane.
**The patient journey starts weeks early, with questions.** Someone weighing a $4,000 implant or booking a $200 eye exam usually runs a series of informational searches over days or weeks before they ever search for a provider. Practices used to earn blog and service-page traffic from those early questions. AI Overviews now catch the patient upstream, before they reach your site.
**Medical content sits under a higher confidence bar.** Google's systems treat health topics as Your Money or Your Life content and lean on recognized medical-authority sources (Mayo Clinic, the ADA, the AAO) for the primary answer. Individual practice pages are more often used as a supporting citation than as the headline source. That means the realistic goal for most practices is to be one of the cited links, not to outrank Mayo Clinic.
## What actually changed: citation, not ranking
The mental model has to shift from "did we rank" to "did we get cited."
Rankings did not change. Impressions are still counted, and positions can even improve, because AI Overviews pull their sources from the top of the results and those source links receive a position attribution. What changed is the click. The AI answer now sits above the ten blue links, with three to five inline citation pills. Many searchers read the answer and leave.
A page cited in an AI Overview with no click is not worthless. It still drives downstream branded search ("Smiles on 5th reviews"), direct visits, and recommendations inside ChatGPT and Perplexity, which pull from overlapping source pools. The new value of a page is whether it earns the citation, and whether your brand is the one named next to it.
The shift in one line: stop optimizing for rank-then-click, and start optimizing to be cited, or to be the brand the searcher remembers after reading the citation.
## The playbook: five citation-targeting moves
These are the five moves that move the needle this quarter. None of them is "write more blog posts."
They map onto what research on AI-cited health sources actually rewards. A [2026 study](https://www.medrxiv.org/content/10.64898/2026.01.22.26344576v1) of the sources cited in AI health answers grouped the signals into four domains: author credentials, institutional affiliation, quality vetting, and digital discoverability. The moves below operationalize those for a practice website.
### 1. Add the schema that makes your pages machine-readable
Structured data does not buy you a citation, but it gives Google's extraction layer clean, confident context to pull from. For practices, the high-value types are `FAQPage`, `MedicalBusiness` (or its `Dentist` subtype), `Physician`, `MedicalProcedure`, and `MedicalCondition`.
A minimal `FAQPage` block for a dental question, placed on the relevant page:
The same shape extends to the practice itself with a `Dentist` or `MedicalBusiness` block (name, `medicalSpecialty`, address, telephone, `priceRange`) and a `Physician` block for each named doctor. Test every block in Google's Rich Results Test before it ships. Broken schema is worse than none.
### 2. Put extractable numbers on the page
A page built around specific, liftable figures is easier for an answer engine to quote than three paragraphs of adjectives: "a single implant typically costs $3,000 to $5,000," "adults should have an eye exam every one to two years." Add a short "by the numbers" block to each key service or procedure page, and attach a clear source to every figure. Treat this as a format-and-accuracy move rather than a guaranteed citation trick: it makes your page quotable and keeps your own claims defensible.
### 3. Attach credentials to your answers
Author credentials are one of the four authority signals that study identified in AI-cited health sources, and most practices waste them. "Dr. Jane Smith, DDS, explains:" carries more authority than the identical text in anonymous body copy. Use a visible byline, a credential string, and `Person` schema. Practice owners who are themselves the treating doctor are sitting on this signal for free and usually not using it.
### 4. Earn third-party mentions
A practice mentioned in local news, an industry publication, or a vertical podcast accumulates an entity graph that Google's scoring layer uses to disambiguate and trust your brand. One targeted effort per quarter is enough: a local-news angle, a professional-association feature, or a guest spot on a relevant podcast. This is the slowest lever and the hardest for a competitor to copy.
### 5. Write in the formats that get extracted
Question-and-answer pages, comparison tables (implant vs. bridge vs. denture; LASIK vs. PRK), step-by-step procedure explainers, and "what to expect on the day" walkthroughs all match the shape AI Overviews prefer to extract. Long, meandering essays do not. If you build one new content asset this quarter, make it a comparison table or a procedure Q&A, not a 1,500-word think piece.
## What not to do
- **Do not write more generic blog posts** on "5 benefits of dental implants." That market is saturated, the Overview answers it inline, and the page will earn impressions with no clicks.
- **Do not gut your existing pages.** Pages that still earn impressions are still building entity authority even when clicks are down. Deleting them removes citation candidates.
- **Do not chase Overviews with thin, AI-generated filler.** Google's helpful-content systems penalize it, and citation correlates with the same quality signals that helpful-content rewards.
- **Do not judge success on Search Console clicks alone in 2026.** That number will keep falling for informational health pages whether you do the right thing or the wrong thing.
- **Do not bolt on stethoscope stock photos to look "more medical."** Trust signals here are real authors, real credentials, and real third-party mentions, not visual set dressing.
## What it looks like when the fix works
A Canadian multi-location optometry group we manage rebuilt its website this spring on exactly these foundations: clean `LocalBusiness` and `Optometrist` schema on every location page, structured FAQ content, and an `llms.txt` file that tells AI crawlers what the practice is and where it operates. The groundwork was in place the day the new site went live.
Within the first week, the practice's branded queries improved from an average position of 8.0 to 4.4, and its neighbourhood "eye care" searches moved onto page one: one climbed from position 6.2 to 1.4, another from 9.2 to 2.6. Branded click-through rose 44%. Organic traffic had not had time to compound yet, so the early lift shows up exactly where it should first: in position, and in being the named brand, which is the leading indicator for AI citation and the branded search that follows it.
One honest caveat: that is a single week of data immediately after launch, so treat the figures as an early read, not a settled trend. The direction is the one the playbook predicts.
## The 90-day plan: optometrist version
| Weeks | Focus |
| --- | --- |
| 1 to 2 | Pull Search Console, compare clicks vs. impressions on the top 20 pages, and flag the high-impression, low-CTR pages (the Overview casualties). Confirm `MedicalBusiness` and `Physician` schema is present. |
| 3 to 6 | Add `FAQPage` schema to the top five service pages (eye exams, dry eye, contact lenses, pediatric, myopia control). Embed one credentialed doctor quote and one "by the numbers" stat on each. |
| 7 to 10 | Publish two Q&A pages targeting unsaturated questions ("how often should an adult get an eye exam," "what is myopia control"). Internally link them from existing content. |
| 11 to 13 | Run one digital-PR push (a school-vision-screening seasonal angle, or a statistic from your own anonymized patient data). Submit to one professional publication. |
For the broader local-search foundation underneath this, see our work on [optometry practice marketing](/industries/optometry/).
## The 90-day plan: implant dentist version
| Weeks | Focus |
| --- | --- |
| 1 to 2 | Same audit. Expect the heaviest Overview impact on "do dental implants hurt," "how long do dental implants last," and "all-on-4 cost." |
| 3 to 6 | Schema work: `MedicalBusiness` plus `Physician`, `MedicalProcedure` for each implant procedure, and `FAQPage`. Embed a doctor video with a written transcript (transcripts are extractable; video alone is not). |
| 7 to 10 | Build one comparison-table asset (implant vs. bridge vs. denture, or all-on-4 vs. all-on-6) and one financing explainer ("what it costs in monthly payments at 0% for 24 months"). Both are extractable formats. |
| 11 to 13 | One digital-PR push (regional edentulism statistics, or an existing community give-back). Get the doctor on one industry podcast. |
We have run this for implant practices; one example is in our [dental implant campaign results](/results/dental-implant-campaigns/), and the vertical foundation is on our [dental marketing page](/industries/dental/).
## How to measure whether it is working
Stop watching the click number alone and track these signals instead.
| Signal | Where to find it | Why it matters |
| --- | --- | --- |
| Citation presence | Manual or scripted checks of which queries surface you in an AI Overview; commercial trackers also exist | The leading indicator of whether the work is landing |
| Branded search lift | Search Console, filtered to queries containing your practice name | Overviews drive branded search even when the citation click is missing |
| Direct and organic visits to /contact and /book | Analytics | Bottom-of-funnel pages do not get Overview-eaten, because "Smith Dental booking" is not an informational query |
| Phone volume by "found us on Google" | Call tracking | Overviews often route to a Google Business Profile click rather than a website click |
There is a sharper version of citation tracking that almost nobody does, and it is the one that matters. Being named in the answer text and being cited as a source link are two different signals, and they do not always travel together: a page can be cited without the practice being named, named without earning the link, or both. We pull AI Overviews and Perplexity results for our own market and track those as two separate columns, because the gap between them tells you whether you are building entity authority (being named, which a patient remembers and later types as a branded search) or just supplying raw material (being linked, which the patient never sees). We have watched one competitor get named in the answer text of three different Overviews while rivals were only linked. Aim to be the named brand.
What to ignore: total session count (it will look bad), bounce rate (meaningless when traffic skews to higher-intent visitors), and average position (an improving number that no longer predicts clicks).
## Frequently asked questions
**Are AI Overviews hurting dental and optometry websites specifically?**
Yes, and harder than most verticals, because health searches are disproportionately informational and AI Overviews answer informational questions in-pane. The measurable signature is impressions rising or holding while clicks and click-through rate fall, with no loss in ranking position.
**My rankings are fine but my traffic dropped. What happened?**
That is the AI Overview pattern. Your page is still ranking and is likely being used as a source, but the answer now appears above the links, so fewer people click. The fix is citation targeting, not chasing rankings you already have.
**How do I get cited in an AI Overview?**
Give the extraction layer clean material to pull: structured data (`FAQPage`, `MedicalBusiness`, `Physician`), credentialed authorship, third-party mentions, quotable figures, and Q&A or comparison-table formats. Research on AI-cited health sources points to author credentials, institutional authority, quality vetting, and discoverability as the distinguishing signals. There is no paid placement and no guarantee.
**Should I delete pages that lost clicks?**
No. Pages that still earn impressions are building entity authority and are citation candidates. Deleting them removes you from the answer pool.
**Does this also affect ChatGPT and Perplexity?**
Yes, though not identically. A [2026 analysis](https://arxiv.org/html/2604.25707v2) found the three surfaces cite very differently: ChatGPT cites about 7 sources per answer and leans on each heavily, while Google AI Overviews and Perplexity cite roughly 12 and 16 and spread the weight thin. They are not interchangeable, but the underlying work (authority, structured content, being a trusted source) pays across all three. We cover measuring them in [tracking visibility across AI platforms](/blog/ai-platform-tracking/).
**What is the honest shelf life of this advice?**
The specific behavior of AI Overviews will keep shifting, and this playbook will need a refresh within a year. The foundations (schema, credentialed answers, extractable formats, third-party mentions) are stable. The principle outlasts the specifics: be cited, or be the brand named after the citation.
## The bottom line
AI Overviews are the search game in healthcare now. Clicks to informational pages will keep falling whether a practice acts or not, so the click number is no longer the scoreboard. Citation is. Practices that get schema, credentialed answers, extractable formats, and third-party mentions in place this quarter will compound an advantage; practices that wait will watch the gap to their faster competitors widen, and that gap is hardest to close once a rival's entity authority is established.
The diagnosis is simple, and most owners are getting it wrong: this is not a ranking problem you fix with more blog posts. It is a citation problem you fix with the playbook above.
If you want a straight read on whether your practice site is losing clicks to AI Overviews, which pages are affected, and exactly what schema and content changes would put you in the answer, we offer a no-obligation audit. You get a written findings document on what is working, what is not, and what would move the number.
**[Request a free audit →](/contact/)**
For related reading, see [our ChatGPT Ads field guide](/blog/chatgpt-ads-2026-field-guide/), [how the Google Ads job changed in 2026](/blog/google-ads-2026-operating-model-shift/), [scaling multi-location healthcare marketing](/blog/scaling-multi-location-healthcare/), and our work on [SEO](/services/seo/) and [AI marketing](/services/ai-marketing/).
---
## The 2026 Implant Practice Operational Stack
*Read [Part 1](/blog/dental-implant-pe-playbook-part-1/) first if you have not. It diagnoses the operational stack a PE-backed DSO installs at an implant practice and argues the operational model is separable from the equity transfer. This post ships the install-it-yourself version.*
Part 1 argued the operational model is the asset and the equity transfer is the packaging. Part 2 ships the answer. The 2026 operational stack for an independent implant practice ships in 30 days from contract, is owned by the practice, runs around $5,000 per month in total software cost, and replaces roughly $10,000 to $15,000 of monthly payroll in headcount the practice no longer needs to hire. The system fits how the practice already operates.
This post is for the implant practice owner who read Part 1, recognized the PE operational playbook, and wants the install-it-yourself version. It is also for the owner who is being approached by a PE-backed DSO right now and wants to know whether the operational benefits the DSO promises are actually obtainable independently. The answer is yes, and below is the specific stack Choice OMG installs, the 30-day plan we run, what it costs, and the trajectory across the implant practices already on the stack. The post names the trade-offs honestly. There are practices where the DSO partnership is the right answer, and the closing section names them.
## Build beats buy at single-practice scale
A Salesforce-class CRM was the right answer for a 750-office DSO and the wrong answer for one location. Platform-scale economics and practice-scale economics are not the same problem. The Frontline DIS Salesforce instance [described in Part 1](/blog/dental-implant-pe-playbook-part-1/) was the right answer at 14+ practice scale. At one practice it is overbuilt, overpriced, and slow to install.
The AI-augmented custom-build alternative is tailored to the practice's specific patient journey, owned outright, and ships inside the 30-day install window. Build-versus-buy economics inverted around 2024 because the tooling changed. Coding agents like Claude Code, Cursor, and GitHub Copilot now ship working software from prose specifications, in hours where a contracted engineering team would have billed weeks. A custom call-tracking-to-CRM attribution layer for one practice that would have been a multi-week consultant engagement in 2022 is now a two-day build with one operator and a coding agent. A consulting firm arrives with a pre-built system and a training program: the practice learns to work the way the system requires. The AI-build approach inverts that. The system gets built to match how the practice operates. Change management is the largest hidden cost in most operational technology engagements, and this approach reduces it materially because the system fits existing workflows rather than imposing new ones; some staff retraining is still required, just dramatically less than a SaaS rollout.
Examples of what Choice OMG builds in days that a SaaS configuration would take weeks: custom attribution dashboards, intake-to-case-tracking pipelines, MROI reporting layers, AIO-citation content systems, AI-personalized post-consult email and SMS sequences referencing each patient's specific procedure plan. Plus AI-augmented operational automation that would normally require dedicated staff: text alerts to the office manager when something needs attention, personalized appointment reminders that draw on each patient's procedure history, automated follow-up sequences for unbooked consults. These are small, real, and effectively free to run at AI prices.
The PE stack worked for what it was designed for. The 2026 stack should be built differently because the build-tooling has changed. This is an upgrade in approach, not a rejection of the model.
## The 2026 stack for an independent implant practice, component by component
The stack has seven components. Each one is named, each one is owned by the practice, and each one is built or integrated in the 30-day install plan described later.
| Component | What it does | How Choice OMG builds it |
|---|---|---|
| Discovery layer | Surfaces the practice in AI answers, traditional SERPs, and local results | Schema markup, FAQ-structured content, expert credentialing, third-party citations, GBP optimization |
| Attribution and call tracking | Credits every consultation to the right campaign across the multi-week implant decision window | Custom AI-augmented attribution sized for one practice; CallRail-level call tracking; custom Twilio infrastructure where it adds value |
| CRM and lead-to-case pipeline | Tracks the consultation, financing, treatment-plan, and case-completion stages | Custom-built, owned by the practice, not a Salesforce subscription |
| Treatment-coordinator role design | Structures the financing conversation around clinical-quality outcomes | Role design and script aligned with clinical accountability, not production quotas |
| Financing menu | Surfaces CareCredit, in-house plans, and Proceed Finance as menu options | Integrated into the consultation flow, presented as options the patient and dentist work through together |
| Case-acceptance nurture (multi-channel) | Converts attended consults into accepted cases | AI-personalized email and SMS sequences, video remarketing on Meta and YouTube, branded TV and radio strategy |
| Relationship layer | Drives recall, referral, and retention | Patient communication automation, review-cycle prompts, structured referral programs |
Three components warrant detail.
**Discovery layer.** Implant patients now research on AI Overviews, ChatGPT, Perplexity, and YouTube as much as on Google's traditional results. The discovery layer is the work of getting cited in those answers and ranking in those results. Schema markup, FAQ-structured content, expert credentialing, and third-party citations are the long-cycle compounding investments, while local-pack optimization and traditional Google Search are the shorter-cycle ones that matter just as much.
**Attribution and call tracking.** Implant cases close on weeks, not minutes. A first-touch model misattributes the eventual case to the wrong campaign; a last-touch model misattributes it to whatever was running on the day the patient called. The multi-touch model gets built custom to the practice. It credits the channels that actually drove the qualified full-arch consult, not just the channel that filled the top of the funnel.
**Case-acceptance nurture (multi-channel).** This is what converts an attended consultation into an accepted case. The sequence: AI-personalized email referencing the patient's specific procedure plan and financing options, SMS follow-up timed to the patient's stated decision window, and video remarketing on Meta and YouTube that surfaces the dentist's clinical credibility and patient-outcome stories to the warm audience. Compliance posture: any workflow that touches protected health information runs on BAA-covered AI vendors and infrastructure; non-PHI content (general appointment reminders, broadcast creative, public-facing pages) runs on the broader AI stack. For practices with a meaningful full-arch case mix, add a branded TV and radio layer to build top-of-funnel awareness so the practice name is already familiar at consult time. Broadcast carries the highest CPM in the stack and is only justified where individual case values ($25K to $45K for full-arch) cover the cost of presence; for practices that are hygiene-and-single-implant heavy, skip the broadcast layer and reinvest in the relationship layer. Media spend for paid and broadcast channels is paid by the practice directly and is on top of the software cost; Choice OMG designs and manages the strategy.
## Why this works at single-practice scale
Heartland-supported offices spend [2.9% of revenue on supplies versus an 8.7% industry average](https://jobs.heartland.com/earn/). That is the order of magnitude of the operational compounding the PE stack delivered at platform scale. The AI-build approach delivers comparable operational efficiency for one practice without the SaaS subscription tax. The cost-side compounding does not require a 750-office network anymore. It requires the right system, built the right way, for the way the practice actually operates.
## What this costs
The total monthly software cost for the 2026 stack is targeted at around $5,000. That covers the custom-built attribution and CRM layers, the call tracking and reporting infrastructure, the AI-augmented automation, and ongoing campaign management across paid and organic channels.
The $5,000 figure is the introductory launch price for the AI-built stack offer described in this post; steady-state pricing as scope and case mix grow may shift up. It is not the average of current legacy retainers across Choice OMG's existing client mix.
The comparison that matters is against the traditional alternative. A consulting firm engagement that installs SaaS and trains staff to work differently around it, plus the headcount required to operate that stack at single-practice scale, lands very differently. A typical CRM-plus-integration-plus-reporting stack at single-practice scale requires roughly three full-time staff to manage. At single-practice payroll rates, three FTEs is $10,000 to $15,000 per month before benefits. The Choice OMG approach replaces that payroll with $5,000 in software, a net swing of $5,000 to $10,000 per month going back to the practice's bottom line. The system gets built to fit how the practice already works, and the operational small-stuff runs on AI that costs effectively nothing.
| Line item | Included in the $5,000 |
|---|---|
| Custom-built attribution layer | Yes |
| Custom CRM equivalent and lead-to-case pipeline | Yes |
| Call tracking infrastructure (CallRail-class plus custom Twilio) | Yes |
| AI-augmented operational automation | Yes |
| Reporting dashboards and MROI layer | Yes |
| Paid and organic campaign management | Yes |
| Discovery-layer content production | Yes |
| Media spend for paid search, paid social, programmatic, TV, radio | No (paid by the practice directly) |
| New headcount at the practice | No (the system replaces the headcount need, not adds to it) |
## The 30-day install plan
Thirty days from contract to fully operational stack. The first two weeks are the build phase, where the AI-build-versus-SaaS-buy advantage matters most. The remaining two weeks are operational integration, campaign restructuring, and the relationship layer. Day 31 the stack is live and producing.
| Days | Milestone | What ships |
|---|---|---|
| 1 to 7 | Discovery and build kickoff | Discovery-layer assessment, AIO/SERP audit, custom CRM build, intake-to-case schema designed |
| 8 to 14 | Attribution, reporting, automation | Custom attribution layer wired across Google Ads, Meta, GA4, GBP, and call tracking; CallRail and custom Twilio deployed; MROI dashboards live; office-manager text alerts, personalized appointment reminders, and AI follow-up sequences for unbooked consults turned on |
| 15 to 21 | Campaigns, coordinator, financing | Paid search, paid social, and YouTube remarketing campaigns rebuilt; treatment-coordinator training delivered where applicable; financing menu integrated into the consultation flow |
| 22 to 30 | Scheduling, relationship, content | Production scheduling logic adjusted to clinical pace; recall sequences, referral programs, and post-case review prompts deployed; first content batch shipped for discovery-layer compounding |
| 31 | Operational | Full stack live and producing; weekly reporting cadence in place |
## What the trajectory actually looks like (with the data caveats)
The data below is from across the implant practices Choice OMG has integrated into its reporting stack (N=2). This is the subset our reporting infrastructure has data for, not industry-wide and not Choice OMG's full implant book, and disclosing that limitation up front is more useful to the reader than smoothing it over. The two practices below each cover one recent-quarter cost snapshot.
### Client A: 17 months on the stack
Engagement window: January 2025 to May 2026. Full reporting stack integrated since the start. The story this practice tells is about discovery-layer compounding.
- **Organic search position** improved from rank 35 to rank 13 across the 17-month window.
- **Monthly organic impressions** grew from ~53,000 to ~84,000, with peak months above 150,000.
- **Clicks held flat** in absolute terms; the position-improvement and impressions-growth story is the strong one. The article is not overclaiming on clicks.
### Client B: newer engagement, channel-mix in motion
Engagement window starts later than Client A. Full reporting stack integrated more recently. The story this practice tells is about the rebalance from paid to organic.
- **Paid-channel share of GA4 sessions** dropped from a peak of 84% (April 2025) to a 30% to 47% range in spring 2026.
- **Organic share** rose from 5% to 38% over the same window.
- This is the cleanest AI-discovery and organic-emphasis trajectory in the data.
### Recent-quarter cost economics across the subset (March to May 2026)
| Metric | Value |
|---|---|
| Blended marketing CPL (total paid spend ÷ all-source leads) | $60 to $94 per lead |
| Google Ads CPA, steady-spend account | $28 to $58 |
| Google Ads CPA, aggressive-scale-up account | $236 to $477 |
| Monthly paid-ad spend range | $1,500 to $15,000 Google Ads; $100 to $1,600 Meta where present |
The spread between the two CPAs matters more than the average. The aggressive-scale-up CPA reflects a practice intentionally running paid acquisition above its long-term steady-state CPL to capture top-of-funnel volume; that is not the sustainable per-lead cost.
Caveats: daily Google Ads spend data in our reporting infrastructure only goes back to mid-March 2026, so the spend-side trend across the full engagement is not available. The organic-search trajectory and the channel-mix evolution are the long-horizon trajectories the data supports; the cost snapshot is the recent-quarter view. Per-patient revenue, case-acceptance rates, and full-arch case volume live in the practice management software and are out of scope for this analysis.
## When the alternative does not work
Four practice types where the DSO partnership is genuinely the right answer:
- **Succession-driven exits.** An owner ready to phase out clinical practice and monetize the equity now has a different problem than the independent stack solves. The DSO transaction structures the exit; the rollover equity captures some of the post-close upside.
- **Founder burnout.** The independent stack requires the owner to remain operationally engaged. The DSO answer removes that requirement at the cost of the equity. For an owner who wants to step back, that trade is rational.
- **Geographically isolated practices that cannot scale.** A small market with saturated local demand has limited operational growth available. The DSO provides centralized marketing, centralized purchasing, and a regional referral network the independent stack cannot replicate at that scale.
- **Owners who want no operational involvement.** Some clinicians want to practice clinically and have someone else run the business. The DSO answer fits that preference. The independent stack does not.
The thesis is not "PE is always wrong." It is that the operational benefits the DSO promises are independently obtainable for the practice owner who wants to stay operationally engaged. If you do not want to stay operationally engaged, the calculation is different.
## The thesis
The operational model is the asset. The AI-built 2026 version is faster to install, cheaper to operate, and owned by the practice. The independent practice that installs this stack this month is positioning for this cycle, not just this quarter.
The PE-era playbook assumed multi-week SaaS configurations were the only path to operational sophistication. That assumption is no longer true. The build-tooling changed. The stack a PE-backed DSO needed Salesforce and a regional operations team to deliver is now buildable for one practice in a fraction of the time and cost. The opportunity is to install it without the equity transfer.
## FAQ
**Q: How long does it take Choice OMG to install the full 2026 stack at an independent implant practice?**
A: Thirty days from contract to fully installed. The build phase (custom AI-augmented attribution layer and the practice-tailored CRM equivalent) takes the first two weeks because that is where the AI-build-versus-SaaS-buy advantage matters most. The remaining two weeks cover campaign restructuring, treatment-coordinator training where applicable, financing menu integration, production scheduling adjustments, and the relationship-layer setup. Day 31 the stack is operational.
**Q: How much does Choice OMG charge to install and run this stack?**
A: Forward-looking target price for the AI-built stack offer is around $5,000 per month in total software cost. That covers the custom-built attribution layer, the custom CRM equivalent, the call tracking and reporting infrastructure, the AI-augmented automation, and ongoing campaign management across paid and organic channels. Media spend for paid channels and the broadcast layer is on top, paid by the practice directly. Compare against the traditional alternative: a consulting engagement that installs SaaS plus the roughly three full-time staff a practice would typically need to operate a CRM-plus-integration-plus-reporting stack at single-practice scale.
**Q: What is the actual difference between Choice OMG's AI-built attribution and a Salesforce setup?**
A: A Salesforce instance for a single dental practice is a multi-week configuration project that produces a system more powerful than the practice needs and more expensive than the practice should pay. Choice OMG builds the equivalent in days using AI-augmented custom development. The result is tailored to the practice's specific patient journey, owned outright by the practice, and significantly cheaper to operate over the lifecycle. The Frontline DIS Salesforce instance described in Part 1 was the right answer at 14+ practice scale; it is the wrong answer at one-practice scale.
**Q: What if my practice is already on a SaaS contract I cannot exit?**
A: Choice OMG works on top of existing software. The custom-built layer is the attribution and reporting glue that ties existing tools together and adds the AI-augmented decision support none of them deliver standalone. The SaaS contracts you have already paid for keep running. The Choice OMG build replaces the configuration overhead, not the underlying tools.
**Q: How does this compare to just hiring a marketing-only agency?**
A: Most marketing-only agencies stop at the campaign management layer. The 2026 stack Choice OMG installs covers the discovery layer, the attribution layer, the CRM and lead-to-case pipeline, the financing and treatment-coordinator design, the case-acceptance nurture, and the relationship layer. A marketing-only agency runs ads. Choice OMG runs the operational stack the ads feed into.
**Q: Do I keep ownership of the system Choice OMG builds?**
A: Yes. The custom-built attribution layer, the CRM equivalent, the reporting dashboards, and the integration glue are built for the practice and owned by the practice. If the engagement with Choice OMG ends, the practice keeps everything: the data, the system, the integrations. No SaaS lock-in is the point of the build-with-AI approach.
## Author note
I built the call tracking, conversion attribution, and marketing ROI reporting at the Texas implant practice described in Part 1. I watched the rest of the PE operational stack get installed around me. I did not build the Salesforce side; I built the front-of-funnel tracking layer that fed it. I am the named author of this post, and the alternative it recommends is the agency I run.
I now run Choice OMG, a Canadian-based dental and healthcare marketing agency founded in 2010 that builds the acquisition-tracking and operational stack for independent dental practices. If the audience for this post acts on the recommendation, my business benefits. That is a direct conflict of interest, disclosed in the lede, the FAQ, and here. I was paid as a marketing analytics contractor by the Texas practice during the integration window described above; I have not taken any payment, sponsorship, or commercial consideration from any entity involved in this story since. The conflict cuts the other direction too: I could build the same agency relationship with PE-backed DSOs and have access to a much larger market. The deliberate choice to focus on independent practices comes from a view that the value transfer in PE acquisitions is increasingly one-sided against the selling dentist.
The thesis stands despite the conflict because the conflict is structurally consistent with the reader's interest. The reader who installs the independent stack keeps the equity, keeps the operational decision-making, and gets the operational compounding the PE playbook promised. Where the data does not support a specific claim, I have flagged it. The N=2 disclosure in the trajectory section is the example: the data is real, but the sample is the subset Choice OMG has integrated into its reporting infrastructure, not the universe of implant practices. The research backs the broader thesis ([Heartland's 2.9% supply cost](https://jobs.heartland.com/earn/), [Nasseh's service-mix-shift finding](https://doi.org/10.1111/1475-6773.70075), [the California 2026 Aspen injunctive terms](https://oag.ca.gov/news/press-releases/attorney-general-bonta-announces-settlement-aspen-dental-over-corporate-practice), [the Borsa systematic review](https://doi.org/10.1136/bmj-2023-075244)). My first-person experience aligns with it. Where the data is thin, the post says so.
---
## What PE Installs at a Dental Implant Practice
Dr. Clark Damon's Texas dental implant practice joined Frontline DIS across late 2023 and early 2024. From the front of the funnel I watched the same operational stack the major PE-backed DSOs install go in around me. The operational model is the actual asset: the equity transfer is mostly the packaging around it, and the two are separable.
Dr. Clark Damon's Texas dental implant practice joined Frontline Dental Implant Specialists across late 2023 and early 2024. Frontline brands itself as a "Dental Implant Partnership Network," not a buyer; its parent, Leon Capital Group, explicitly says it is "not a private equity fund." My seat was the front of the funnel. I built the call tracking, the conversion attribution, and the marketing ROI reporting that fed everything downstream. From there I saw the same operational stack the major PE-backed DSOs roll out get installed around me. A Salesforce instance. Qualification tiers. Financing-first scripts. End-to-end click-to-patient tracking. It worked. Revenue compounded on the cases that mattered most. Two years and a stack of public PE research later, I am certain that most dentists evaluating a similar offer, whether from a PE-backed DSO or a family-office-backed partnership network, should run the operational version without the equity transfer. The model is what installs revenue compounding. The equity structure around it is mostly the packaging. This post is part one. It covers what that operational model actually is, what gets installed, where the revenue actually comes from, and what life looks like for the selling dentist on the other side of the deal. Part two ships the independent-friendly alternative.
Two things this post is not. It is not financial deal advice. The math of multiples, earn-outs, rollover equity, and holdback provisions belongs in a conversation with a dental-specific M&A advisor; this article addresses the operational and marketing questions that determine whether the financial math even makes sense. It is also not an argument that selling is always wrong. Succession-driven exits, founder burnout, and geographically isolated practices that cannot scale on their own are legitimate sell scenarios where a DSO partnership is the right answer. The audience for this post is the owner who has been approached, weighed an LOI, watched a peer sell, and wants to understand the operational model before deciding.
## The setup
[Frontline reports 14+ practices, 3 states, and 4,695+ annual implant procedures](https://www.leoncapitalgroup.com/overview/frontline-dental-implant-specialists/) across its network. Whether the Damon transaction was structured as a traditional acquisition, a recapitalization, or a partnership equity rollover, the operational integration that followed was the same playbook a PE-backed DSO would have run. The practice was a high-volume implant operation with a substantial full-arch case mix. I was the marketing analytics contractor sitting between the practice and the platform that absorbed it. My work predated the close by months and continued through the integration phase, which is how I ended up watching the operational stack get installed in real time.
## What I built
I did not build the Salesforce side. I built the tracking layer that fed it, the front of the funnel, across three concrete integrations.
First, the call tracking layer. I deployed a hybrid setup: CallRail for the standard campaign-to-call attribution, plus custom Twilio tracking numbers I had built for the channels where the off-the-shelf coverage was insufficient. Together they captured every inbound consultation request, attached the campaign source, tagged the call recording, and fed the result into the downstream Salesforce instance the platform was installing. The integration covered Google Ads, Meta, SEO landing pages, and the practice's referral lines. Every ringing phone produced an attributable data row.
Second, the conversion attribution methodology. I designed a custom weighted attribution model focused on consultations completed. Performance Max was still in its early stages at Google Ads, and the data picture was being assembled in real time; there were not yet enough fully-attributed revenue markers to weight on closed cases, so consultation completion became the primary success signal the model optimized around. The model credited campaigns across the multi-touch consultation journey. Implant cases close on weeks, not minutes; a first-touch model misattributes the eventual case to the wrong campaign, and a last-touch model misattributes it to whatever happened to be running on the day the patient called. The methodology gave the platform real visibility into which channels drove qualified full-arch consults, not just which channels filled the top of the funnel.
Third, the marketing ROI reporting. I built the dashboards that translated all of that into language the platform's operators could act on: cost per qualified consultation by channel, cost per case acceptance by channel, and marketing-attributable revenue (monthly and trailing-twelve). The dashboards lived in Google Sheets and fed the Salesforce instance through webhook posts so the operational stack downstream could close the loop on every campaign.
The specificity matters because it is the credentialing layer of this post. I was not watching the integration happen from across the room. I was inside the integration, building the part that fed everything else.
## What I watched get installed around me
The full operational stack went in over the months that followed the close.
A Salesforce instance for the practice's lead-to-case pipeline. The build included custom objects for consultation type, case classification, and financing-approval status. The instance was administered centrally by the platform, not by the practice. Reports rolled up to platform leadership.
Qualification tiers. The funnel got formal stages: inbound lead, qualified lead, consultation booked, consultation attended, treatment plan presented, financing approved, case accepted, case completed. Each stage had ownership, an SLA, and a conversion target. The tiers existed before the acquisition in rough form; the platform formalized them and tied them to compensation downstream.
A treatment-coordinator script structure built around the financing conversation. The coordinator would surface options (CareCredit, in-house plans, third-party medical lending) early in the consultation rather than late. The script existed to convert cases that would otherwise stall on patient hesitation about cost, and it worked.
Production scheduling logic. The chair-time templates got optimized for high-margin procedures. Full-arch days got blocked together. Hygiene capacity got compressed. The dentist still held the clinical decisions; the schedule that shaped the patient mix shifted under platform control.
End-to-end click-to-patient tracking. The tracking layer I built fed Salesforce, which fed the platform's reporting layer, which fed the regional operations team's KPIs. By the time the stack was fully installed, every patient was a tracked row from the first ad impression to the final case completion.
I watched all of this from the front-of-funnel vantage point.
**Table: the PE operational stack installed at the practice**
| Component | What it does | Who controls it post-close |
|---|---|---|
| Salesforce CRM instance | Centralizes lead-to-case data, custom objects, reporting | Platform |
| Qualification tier structure | Formalizes funnel stages, attaches SLAs and targets | Platform |
| Treatment-coordinator script | Financing-first consultation flow | Platform (design and updates) |
| Production scheduling logic | Optimizes chair-time for high-margin procedures | Platform template, dentist clinical calls |
| Call tracking and attribution | Campaign-to-case credit, all channels | Platform |
| Centralized purchasing | Lab, supplies, software | Platform |
| Review management | GBP, public response policy | Platform |
| Marketing budget allocation | Channel mix, geo, creative cadence | Platform |
## Why it worked: the operational compounding
The operational stack compounded revenue on the cases that mattered most, and the cost side compressed at the same time.
Heartland Dental publishes the numbers itself. Heartland-supported offices spend [2.9% of revenue on supplies versus an 8.7% industry average](https://jobs.heartland.com/earn/). Doctors completing Heartland's Doctor Leader Track program [average 39% higher production](https://jobs.heartland.com/earn/). Those numbers are Heartland's own marketing language; they are not a critic's framing. They illustrate the order of magnitude of the operational compounding the dental PE model is built to capture.
The broader healthcare PE evidence pairs cleanly. Borsa and colleagues [published a systematic review in BMJ in July 2023](https://doi.org/10.1136/bmj-2023-075244) on private equity ownership across healthcare settings. The review found PE ownership is associated with higher costs and a mixed-to-harmful effect on quality. The cost-and-revenue compounding is consistent across the healthcare PE literature, not specific to dentistry.
The implant-specific connection runs through TAG, the holding company also known as The Aspen Group. TAG [acquired ClearChoice in 2020](https://www.teamtag.com/newsroom/Aspen-Dental-Management-to-Acquire-ClearChoice-Management-Services/). ClearChoice is the largest implant-focused DSO in the United States, with roughly 80 centers nationally. The same operational management entity that owns Aspen Dental also runs the country's largest implant-specific brand. The PE-dental playbook is being applied directly inside implant practices at national scale.
The surgical-specialty rollup is active in parallel. U.S. Oral Surgery Management (USOSM) [now operates in 28 states with more than 250 oral and maxillofacial surgeons, expanded through successive credit facilities since its November 2021 recapitalization with Oak Hill Capital](https://www.usosm.com/us-oral-surgery-management-secures-175m-credit-expansion/). The pattern that absorbed Aspen and Heartland and ClearChoice is now absorbing oral-surgery practices that place implants.
## Where the revenue actually came from
After private equity acquisition, dental offices shifted their service mix from preventive care toward restorative, specialty, and surgical procedures, increased submitted charges by 3.3%, and did not obtain higher insurer reimbursement, meaning the revenue lift came from patients, not payers.
That sentence summarizes the most important piece of public research published on dental PE to date. Nasseh et al. published ["Financial Incisors"](https://doi.org/10.1111/1475-6773.70075) in Health Services Research in December 2025. The study ran a difference-in-differences design on dental office data from 2015 to 2021. The findings, in order of operational importance:
Service mix shifted from diagnostic and preventive procedures toward restorative, specialty, and surgical procedures. Submitted charges per office rose 3.3% (95% CI 2.3% to 4.4%). Practices were more likely to become multispecialty over the period. Negotiated insurance prices did not change. The increase in revenue came from charging more for more-intensive services to the same patients, not from extracting better terms from payers.
The companion [Health Affairs paper by Nasseh, LoSasso, and Vujicic, published in August 2024](https://doi.org/10.1377/hlthaff.2023.00574), established the underlying scale of dental PE growth. Together with Borsa, the three peer-reviewed sources triangulate: PE-dental ownership has grown materially, costs and revenue compound on the operational side, and the post-acquisition revenue lift in dentistry specifically comes from service-mix shift and charge increases borne by patients.
## Service mix is the quieter mover
Service mix is the bigger lever and the less-discussed half of the Nasseh finding. The Nasseh data is industry-wide PE-dental, not implant-specific; the implant case is the most visible instantiation of the broader pattern.
For an implant-focused practice, the post-acquisition service-mix shift looks like more full-arch consultations, more financing-friendly case planning, fewer routine hygiene-only visits in the marketing funnel, and treatment coordinators trained to surface higher-acuity options earlier in the conversation. This is operationally legitimate from a margin perspective. Full-arch cases produce more revenue per chair-hour than hygiene visits, and the operational stack is built to find and convert them.
The question is who designs the conversation and whose incentives sit on the treatment coordinator's script. When the script is designed by an independent owner-dentist who is clinically present and accountable for outcomes, the financing-first conversation looks one way. When the script is designed by a platform with production quotas and compensation thresholds attached to non-owner clinical staff, it looks different.
## The financing-first conversation, decoded
Financing-first is the script structure that converts a $30K full-arch case into an accepted treatment plan instead of "I'll think about it."
The coordinator surfaces financing options early. CareCredit is the most common third-party medical-credit partner; in-house financing and Proceed Finance round out the typical stack. The financing question moves up the consultation timeline so the patient hears "you can afford this" before the patient hears "let me think about it." The presumptive close is built into the script structure.
This is not inherently bad. Financing-first scripts work, and they make access to large cases possible for patients who would otherwise walk. The thing to watch is who designs the script and whose compensation is tied to its outputs. The [California Attorney General's 2026 settlement with Aspen](https://oag.ca.gov/news/press-releases/attorney-general-bonta-announces-settlement-aspen-dental-over-corporate-practice) specifically restricted non-owner clinical staff from being compensated on product or sales-driven incentives, including a hygienist incentive structure that paid $50 to $100 per clear-aligner sale. That restriction is in the public record because the AG found the prior compensation structure problematic enough to require an injunction.
## Post-close operational reality from the dentist's seat
The selling dentist's day changes in specific ways after acquisition, and most of those changes are not in the LOI.
Production quotas frequently get applied to the dentist personally. The California 2026 Aspen settlement enjoined non-owner-clinician production incentives specifically, which indicates how common the structure was. Treatment-coordinator reporting lines move from the dentist to a regional operations manager. Scheduling control moves to a centralized template that optimizes for production efficiency rather than for the dentist's clinical pace preference. Lab and supply selection authority centralizes to platform purchasing, which is where the 2.9% versus 8.7% Heartland supply-cost number comes from; it is also where the dentist loses material-quality choice.
Associate compensation structures typically shift toward production-based formulas with platform-set thresholds. Hygienists and other clinical staff who used to defer to the dentist on case planning now operate inside scripts the platform designed.
Not every PE-backed practice runs this hard on every dimension. Heartland and MB2 use marketing language emphasizing doctor autonomy, and that emphasis is genuine at some practices. The regulatory record at Aspen describes the opposite end of the spectrum. Both can be true at different companies and different individual practices. The point is to know what to negotiate against in the management services agreement (MSA) and what to watch for after close.
## The marketing-stack diligence checklist
The LOI-reader needs a set of operational questions to ask the platform during diligence. Eight that fall inside the marketing-and-attribution layer where I have standing:
1. What attribution methodology do you use to track new-patient sources, and who owns the underlying data?
2. How is the treatment-coordinator script designed and updated, and who can change it?
3. Are non-owner clinical staff compensated on production or product sales, and at what thresholds?
4. What is your production-scheduling logic optimizing for, and can I see the template?
5. What is the data-portability provision if I exit? Do I keep the CRM, the attribution history, and the patient communication archive?
6. How is marketing budget allocated across locations in your network, and who decides allocation for mine?
7. What is your financing-partner stack, and can I negotiate my own preferred relationships?
8. What review-management policy applies to my Google Business Profile, and who replies to negative reviews?
For the financial-deal questions (multiples, earn-out structure, holdbacks, non-compete), engage a dental-specific M&A advisor. The questions above are the operational and marketing complement.
## The regulatory record
The compensation-structure governance failure is structural, not service-line-specific.
Four state-level and federal actions document the recurring pattern. Each is in the public record; each names the entity, the conduct, and the resolution.
**Table: the regulatory record**
| Year | Jurisdiction | Entity | Resolution | Conduct findings |
|---|---|---|---|---|
| 2015 | New York AG | Aspen Dental Management (ADMI) | $450K civil penalty + Assurance of Discontinuance | [300+ complaints since 2005; fee-splitting; ADMI taking 45% to 50% of each office's monthly gross profits versus a flat management-fee structure](https://ur.ag.ny.gov/sites/default/files/settlements-agreements/ADMI_AOD.pdf) |
| 2018 | DOJ | Benevis (Kool Smiles) | $23.9M settlement | [130+ affiliated pediatric clinics; medically unnecessary Medicaid procedures driven by production targets and cash bonuses](https://oig.hhs.gov/fraud/enforcement/dental-management-company-benevis-and-its-affiliated-kool-smiles-dental-clinics-to-pay-239-million-to-settle-false-claims-act-allegations-relating-to-medically-unnecessary-pediatric-dental-services/) |
| 2026 | California AG | Aspen Dental | $2M penalties + $300K restitution + first-in-state injunctive terms | [No employee compensation tied to practice sales; no clinical-staff incentives tied to product sales; no non-owner-clinician revenue incentives; documented hygienist incentive of $50 to $100 per clear-aligner sale](https://oag.ca.gov/news/press-releases/attorney-general-bonta-announces-settlement-aspen-dental-over-corporate-practice) |
TAG, the holding company behind the Aspen Dental entity in all four AG actions, also owns ClearChoice, the largest implant-focused DSO in the US. The same management approach extends across both brands. The implant practice owner reading this should not assume their service line is somehow insulated. The California 2026 injunctive terms read as service-line-independent guardrails; "no employee compensation tied to practice sales," "no clinical-staff incentives tied to product sales," and "no non-owner-clinician revenue incentives" apply identically to a dentures-and-extractions chain and to a full-arch implant practice.
## Canadian sidebar
The Canadian PE-dental story is on the same trajectory as the US, roughly ten years behind, compressed by the CDCP.
[GTCR took dentalcorp private in an all-cash deal that closed January 14, 2026](https://www.gtcr.com/dentalcorp-announces-closing-of-acquisition-by-investment-funds-affiliated-with-gtcr/), worth C$2.2 billion in equity and C$3.3 billion in enterprise value. Dentalcorp reached 575+ practices and 5.6 million annual patient visits before the deal. The transaction is the most consequential PE-dental event in Canada to date.
123Dentist operates 450+ clinics, 5,000+ clinicians, and 2M+ annual patients after the 2022 Altima/Lapointe merger, backed by Peloton Capital Management, KKR, Heartland Dental, and Sentinel Capital. The platform [reported 214% revenue growth from 2021 to 2024 and continued acquiring in late 2025](https://partners.123dentist.com/123dentist-and-altima-dental-announce-a-strategic-merger-with-support-from-peloton-capital-kkr-and-heartland-dental/) (MCA Dental Group). Canadian DSO penetration is variously estimated at 17% to 22%; no ADA HPI equivalent dataset exists for Canada, so the figure is softer than the US number.
The Canadian Dental Care Plan is the strategic accelerant. CDCP launched in May 2024, is administered by Sun Life for residents under $90K, and had enrolled nearly 6 million Canadians and 27,000+ providers by late 2025. Health Canada [reported a 52% pre-authorization denial rate from November 2024 to June 2025, and roughly 85% of dentists report frequent claim denials](https://www.cda-adc.ca/en/about/media_room/statements/2025/CDCP_bridging_gap/index.asp). CDCP disproportionately rewards organizations with centralized billing, pre-authorization workflows, and the appetite to accept the program's fee schedule. That is structurally what DSOs are built for.
The regulatory exposure side is less developed in Canada than in the US. Dental regulation is provincial. [Alberta's Health Professions Act sections 104 to 115](https://www.canlii.org/en/ab/laws/stat/rsa-2000-c-h-7) restrict dental practice to licensed members or professional corporations, with a Responsible Dentist requirement administered by the College of Alberta Dental Surgeons (CADS). Ontario's RCDSO has similar structure. The DSO/MSO architecture being tested in the California 2026 settlement is the same architecture operating in Canadian provinces. No Canadian regulator has publicly tested it at chain scale yet.
The bottom line for Canadian dentist-owners is the same trajectory as the US, compressed by CDCP. Expect Canadian consolidation to keep accelerating.
## The thesis
The operational model is the asset. The equity transfer is the packaging. The operational compounding is largely separable for owners who stay operationally engaged.
When a dentist sells to a PE-backed DSO or joins a family-office-backed partnership network, what they are paying for in the lost equity upside is not the chairs, not the brand, not the patient list. It is the operational stack that compounds the existing business. That stack is mostly installable software, training, and process design. It is separable from the equity transfer in principle and, for many practices, in practice.
Frontline DIS is a useful proof point. A self-described non-PE partnership network installs the same operational stack a PE-backed DSO installs. The compounding does not require the PE capital structure; it requires the model. The capital structure is a separate, downstream decision about who captures the value the model produces.
The post does not claim the alternative is free or trivial. It claims the alternative is separable, and that for many implant-focused practice owners, separating it is the better economic decision.
**Table: what the equity transfer is buying vs. what is separately installable**
| What the equity transfer is buying | Separately installable? |
|---|---|
| Operational compounding (centralized purchasing, supply costs, marketing efficiency) | Yes, with the right tools and partner |
| Click-to-patient attribution stack | Yes; software exists at every price point |
| CRM and qualification tier structure | Yes; HubSpot, GoHighLevel, or PMS-integrated alternatives |
| Treatment-coordinator role design and financing-first conversation | Yes; training and process design |
| Production scheduling logic | Yes; practice management software supports this |
| Doctor production-lift training programs | Yes; clinical CE plus practice-management coaching |
| Cash at close and earn-out structure | No; only equity transfer monetizes future value upfront |
| Recapitalization optionality and strategic exit | No; only equity ownership creates this |
| Removal of operational decision-making from the dentist | No; only sale produces this. Depending on the dentist, this is a feature or a bug |
The most concrete single anchor: the California Attorney General's 2026 settlement enjoined Aspen from paying hygienists $50 to $100 per clear-aligner sale. That compensation pattern is what the operational model installs inside a PE-backed DSO. The same operational compounding, installed inside an independent practice, runs on different incentives. That difference is what "separable" means here.
## Part 2 is now live
[**Part 2: The 2026 Implant Practice Operational Stack**](/blog/dental-implant-pe-playbook-part-2/) ships the install-it-yourself version. The stack a PE-backed DSO needed Salesforce and a regional operations team to deliver is now buildable for one practice with AI in days, owned by the practice, at around $5,000 per month in total software cost with no new headcount required.
## FAQ
**What does a typical PE-backed DSO actually install at my practice in year one?**
The full operational stack: a centralized CRM (commonly Salesforce or a dental-specific alternative), conversion attribution tied to call tracking, qualification tiers from lead through case-acceptance, a financing-first treatment-coordinator script, production-scheduling logic optimized for high-margin procedures, and centralized purchasing. The Heartland Dental [published figure is 2.9% of revenue on supplies versus an 8.7% industry average](https://jobs.heartland.com/earn/); that is roughly the order of magnitude on the operational compounding.
**Will I keep clinical autonomy after the acquisition?**
It depends on the specific management services agreement. The marketing language at every major platform emphasizes doctor autonomy. The regulatory record describes the opposite reality at the platforms that have been investigated. The New York AG [found ADMI taking 45% to 50% of monthly gross profits at Aspen offices](https://ur.ag.ny.gov/sites/default/files/settlements-agreements/ADMI_AOD.pdf), and the California AG's 2026 settlement [enjoined Aspen from compensating employees based on practice sales or pushing clinical staff to drive revenue](https://oag.ca.gov/news/press-releases/attorney-general-bonta-announces-settlement-aspen-dental-over-corporate-practice). Read the MSA carefully.
**What does the post-close treatment-coordinator script actually look like?**
Financing-first, presumptive close, multi-tier qualification. The coordinator surfaces financing options (CareCredit, in-house, Proceed Finance) early in the consultation, before the case-acceptance conversation. The structure is not inherently bad; it converts $25K to $45K full-arch cases that otherwise stall on "I'll think about it." The question is who designs the script and whose incentives are loaded onto it. The California 2026 injunctive terms specifically [restrict non-owner clinical staff from being compensated on product or sales-driven incentives](https://oag.ca.gov/news/press-releases/attorney-general-bonta-announces-settlement-aspen-dental-over-corporate-practice).
**How do I evaluate the marketing operational claims a platform makes during LOI diligence?**
Ask about attribution methodology, data ownership, the data-portability provision if you exit, who designs the treatment-coordinator script, how non-owner clinical staff are compensated, what production-scheduling logic optimizes for, who allocates marketing budget across the network, and what review-management policy applies to your Google Business Profile. For financial-deal mechanics (multiples, earn-out, rollover, holdbacks), engage a dental-specific M&A advisor.
**Can I install the operational stack without selling the practice?**
Yes, and part two of this post covers it in detail. The components (attribution, CRM, qualification tiers, financing-first scripts, treatment-coordinator role design, production scheduling) are mostly software, training, and process design. The right tools exist at every price point, scaled appropriately for a single practice rather than a 750-office network. What you cannot install without the equity transfer is the cash at close, the rollover-equity recapitalization optionality, and the removal of operational decision-making from your daily life.
**What is the CDCP angle for Canadian practices?**
CDCP launched in May 2024, is administered by Sun Life for residents under $90K, and had enrolled nearly 6 million Canadians and 27,000+ providers by late 2025. The [52% pre-authorization denial rate Health Canada reported from November 2024 to June 2025](https://www.cda-adc.ca/en/about/media_room/statements/2025/CDCP_bridging_gap/index.asp) creates an administrative burden that disproportionately favors organizations with centralized billing and pre-authorization workflows. This is structurally what DSOs are built for. A well-run independent with a competent back office can still handle it; the CDCP makes the DSO operational efficiency proposition more compelling than it was a year ago.
**What should I ask my dental M&A advisor that this article does not address?**
All the financial-deal questions. Practice valuation multiples for implant-heavy practices in your market and case-mix profile. Earn-out structure (length, performance thresholds, clawback conditions). Cash-at-close percentage. Rollover-equity terms and any preferred-return structure. Holdback provisions. Non-compete radius and duration. Post-close governance rights. Tax structure of the transaction. This article covers the operational side; the financial side needs an M&A advisor who specializes in dental and ideally has done implant-practice deals specifically.
## Author note
I worked on the marketing analytics layer of Dr. Clark Damon's Texas dental implant practice referenced above. Specifically: I built the call tracking integration, the conversion attribution methodology, and the marketing ROI reporting that fed the broader operational stack. I did not build the Salesforce side. I did not design the financing-first conversation or the treatment-coordinator script. I saw the rest of the PE operational stack get installed around me and observed how it worked because the front of the funnel was what fed everything downstream. The specific platform names and integration details are in the body of the post.
I now run Choice OMG, a Canadian-based dental and healthcare marketing agency founded in 2010 that builds the acquisition-tracking and operational stack for independent dental practices. If the audience for this post acts on the part-two recommendation, my business benefits. That is an explicit conflict of interest. I have disclosed it in the lede, in the FAQ, and I am disclosing it again here. I was paid as a marketing analytics contractor by the Texas practice during the integration window described above; I have not taken any payment, sponsorship, or commercial consideration from any entity involved in this story since.
The thesis stands despite the conflict because the conflict cuts both ways. I could build the same agency relationship with PE-backed DSOs and have access to a much larger market. I have made the deliberate choice to focus on independent practices because the value transfer in PE acquisitions is increasingly one-sided against the selling dentist, and the operational benefits are independently obtainable. The research backs this view; the AG record corroborates it; my first-person experience aligns with it. Where any of those break down, the post says so. Where the data does not support the thesis (the quality-of-care literature is genuinely thin in both directions), I have flagged that limit explicitly rather than overclaiming.
---
## The Operating Layer: 6 Practices That Predict Website Success in 2026 (Regardless of CMS)
Part 1 argued that the CMS doesn't predict website success in 2026. Part 2 is the prescriptive half. Six operating-layer practices, the cadence each one runs at, and what good looks like, backed by what we actually run across 79 WordPress sites, custom Go applications, and hosted-builder properties through our Thor reporting database. Apply these to any platform. Apply them this quarter. The operating layer is what compounds.
[Part 1 of this series](/blog/cms-debate-is-distraction/) argued that the CMS you pick predicts almost nothing about whether your website wins, and that the operating layer above the CMS predicts almost everything. This is Part 2: what's actually in that operating layer, and how to know whether your current agency is running it for you.
Before naming the six practices, one ground rule: **each one has a frequency.** Operating-layer work is defined by cadence. If you can't put a frequency next to a practice, you don't operate it; you maintain it occasionally. Those are different jobs with different outcomes.
The six practices below are the ones we currently run across every client engagement. They are the same regardless of whether the site is WordPress, Shopify, custom Go, or a hosted builder.
## Practice #1: Monitoring cadence beats reporting cadence
The single biggest predictor of website success in 2026 is **how fast something gets caught**. Reporting tells you what already happened. Monitoring tells you what's happening, while you can still fix it.
A monthly report can show that conversions dropped 30% in February. By the time the report is read, March is half over. A monitoring system shows that conversions dropped 30% three hours after the change deployed, and the same person who broke it can roll it back the same afternoon.
Every 30 minutes: budget pacing checks across managed Google Ads accounts. 48 checks per account per day, not once a month.Source: Choice OMG monitoring pipeline
What good operating cadence looks like:
| Surface | Bad cadence | Good cadence |
|---|---|---|
| Conversion events firing | Quarterly QA | Continuous automated check |
| Ad budget pacing | Monthly review | Every 30 minutes |
| Keyword positions | Monthly snapshot | Daily tracking (1,000+ across portfolio) |
| Site uptime | "We'll know when it's down" | Sub-minute alerting |
| Page speed regressions | Annual audit | Weekly site audit |
| Plugin and theme updates | Manual whenever | Continuous |
| Visual regressions | Eyeballed at delivery | Automated diff per deploy |
**How to test your setup this week:** Email your agency and ask, "If our conversion tracking broke at 11 AM on a Tuesday, when would you know?" The answer should be measured in minutes or hours. If it's measured in days or "the next reporting cycle," you don't have monitoring, you have reporting.
We've written about the monitor-vs-report distinction at length in [7 Red Flags When Hiring an Edmonton Digital Marketing Agency](/blog/edmonton-digital-marketing-agency-red-flags/), [Conversion Tracking Breaks Silently](/blog/conversion-tracking-breaks/), and [What Breaks at 2 AM](/blog/what-breaks-at-2am/).
## Practice #2: Plugin and extension governance
Most WordPress sites grow plugins the way garages grow boxes. Something showed up once, nobody wanted to throw it out, and now it lives there. This is a financial and security problem.
The Patchstack 2026 report logged **11,334 new ecosystem vulnerabilities in 2025**, 80% of them in plugins. The exploitation window is five hours median. Every active plugin is a vendor relationship you're maintaining, an attack surface you're carrying, and an update conflict timer running in the background.
We treat the plugin list as a liability sheet that gets reviewed quarterly. **In Q1 2026 we removed the Search Atlas (metasync) plugin from 10 client sites** because the value-to-risk ratio had shifted. That's normal cadence for us. We add plugins when there's no better way to deliver the function, and we remove them the moment a better way appears.
10 client sites had Search Atlas removed in Q1 2026 as part of routine plugin liability review. We measure additions and removals; the removal rate is meant to keep pace with the addition rate.Source: Choice OMG Odin server work log, Q1 2026
What good plugin governance looks like:
- Quarterly plugin liability review with explicit add / keep / remove decisions
- Every active plugin has a documented business reason in one sentence
- Update cadence under 7 days for routine patches, under 24 hours for critical security patches
- No plugin in the install list is on its developer's "abandoned" status
- A standing answer to "what would we replace this plugin with if it disappeared?"
**How to test your setup this week:** Ask your agency for a current plugin list with a one-sentence justification per plugin. If they can't produce one in 48 hours, the plugins aren't being governed.
## Practice #3: Hosting tier discipline
The 2026 floor for "I want my website to compete on speed and reliability" is approximately **$30/month in managed hosting**. Below that floor, you're competing with hands tied.
We run 79 WordPress sites on a managed Plesk environment. Not one of them is on bargain shared hosting. The reason is the math from [Part 1](/blog/cms-debate-is-distraction/): Wix sits at 71-75% mobile Core Web Vitals pass and Shopify at ~65% because they own the hosting layer end-to-end. The median WordPress site sits at ~44% because the median WordPress install is on cheap hosting with no caching strategy. Move WordPress onto a managed host with edge caching, and the gap reverses on real sites.
~$30/month: managed WordPress hosting entry points across WP Engine Startup, Kinsta single-site, and WordPress.com Business. The 2026 floor for competing with hosted builders on speed and reliability.Source: WP Engine, Kinsta, WordPress.com Business public pricing, May 2026
What good hosting discipline looks like:
| Surface | Bad | Good |
|---|---|---|
| Hosting plan | Shared $5/mo | Managed WP or hosted-builder platform |
| Full-page cache | None or plugin-only | Edge CDN with cache rules |
| Backups | "The host backs up nightly" | Daily, with a documented restore time |
| Staging | None | Mirrors production, on-demand reset |
| Web Application Firewall | None | Platform-level WAF + DDoS protection |
| PHP / runtime version | Whatever it was at launch | Current stable, tracked |
**How to test your setup this week:** Ask your agency for the hosting plan name, monthly cost, and what's included. If "we don't manage the hosting" is the answer, you're paying for marketing on infrastructure that nobody owns.
## Practice #4: AI workflow integration
In 2026, AI is becoming the operating layer for content production, customer support, and increasingly for content publishing itself. Two platforms opened protocol-level access to AI agents in 2026: WordPress.com with MCP write access in March, and Shopify with Sidekick + Agentic Storefronts in Winter. They have a structural advantage that closed-AI platforms can't match without changing posture.
This isn't about putting an AI writer in the editor. Wix and Squarespace have those. This is about whether your site can participate in an AI workflow that lives *outside* your CMS: agents that draft content from your CRM, syndicate product data to Perplexity, or run optimization experiments off your analytics.
March 2026: WordPress.com opened MCP write access. Claude, ChatGPT, and Cursor can create posts, build pages, and manage content on any paid-plan site, with scoped permissions.Source: WordPress.com platform announcements, March 2026
What good AI workflow integration looks like:
- The CMS or platform exposes a REST API or MCP server with write access under your control
- Structured content schema (not blocks of HTML) so AI can read and write reliably
- An automation layer (n8n, Make, custom) that mediates between AI agents and the site
- Editorial workflow that distinguishes AI-assisted drafts from approved publication
- Logging that records which agent did what, so reviews and rollbacks are possible
**How to test your setup this week:** Ask whether your current site has a public API you control with write access. If the answer is "you can export to CSV," you're on a platform that will gate AI access.
We track AI visibility itself as a separate monitoring surface; see [How We Monitor 60,000+ Data Points Across Our Client Base](/blog/how-we-monitor-60000-data-points/) and [Tracking AI Platform Visibility](/blog/ai-platform-tracking/) for the monitoring side.
## Practice #5: Data centralization
The single highest-leverage piece of infrastructure we've built is **Thor: a PostgreSQL database with ~120 structured tables that consolidates every source of truth for every client into one read-only canonical store**. GA4, Google Search Console, Google Ads, SEMrush, DataForSEO, Meta, Google Business Profile, call tracking, CRM, and Jira all flow into Thor through dedicated sync services. Reports, weekly briefs, and the live dashboard at reporting.choice.zone all read from Thor. Source APIs are never queried directly for reporting.
The reason is operational integrity. If your monthly report says 12,000 sessions and your dashboard says 11,400 and the source API says 12,300, you can't tell a client which is right. We solved that by making Thor the only place reports get their numbers from. **The number is the number.**
120 structured tables. 6 sync services. 47 client workspaces. 1 canonical store. Thor is the single source of truth that backs every report, brief, and dashboard we deliver.Source: Choice OMG Thor reporting architecture, 2026-04-30 rewrite
For a small business, the principle applies one level down: you should have one place where your performance numbers live, and every dashboard, report, and slide that references them should read from that one place. The most common reason agency numbers don't match Google's numbers is that everyone is reading from a different source on a different day with a different lookback window, an operating defect rather than a data error.
**How to test your setup this week:** Pick a metric, for example "leads from organic search in April." Ask your agency to walk you through the path from raw GA4 data to the number that appears in your report. If the answer is hand-wavy, the number isn't reproducible.
Deeper read: [Why We Built a Single Source of Truth for Client Data](/blog/single-source-of-truth/) and [How We Monitor 60,000+ Data Points Across Our Client Base](/blog/how-we-monitor-60000-data-points/).
## Practice #6: Migration optionality
The last operating practice is the most strategic: **keep the cost of leaving low.** Every platform-level decision either reduces your migration optionality or preserves it.
This is why we lean on WordPress's REST API and Shopify's API rather than locking content into a proprietary page builder that can't be exported. It's also why our default rebuild stack is **WordPress with Elementor (48 small-business websites rebuilt onto it to date)**, while still moving sites *off* WordPress when the business case requires it. We **migrated wojciksfuneralchapel.com off WordPress and Elementor onto a custom Go application** when the performance and reliability requirements pushed past what the builder could deliver, and we didn't lose the content because the content lived in queryable database tables, not in builder-specific shortcodes.
48 rebuilds onto WordPress + Elementor. 1 migration off, onto custom Go. The decision is per-client, not per-firm. The shared discipline is keeping the cost of moving below the cost of being stuck.Source: Choice OMG client engagement records, 2026
What good migration optionality looks like:
- Content stored in structured, exportable formats: database tables, Markdown, structured JSON. Not in builder-only artifacts.
- Public APIs with read AND write access
- Theme and template code in version control, not just on the production environment
- Documented backup and restore procedures that have actually been tested in the last 90 days
- A standing answer to: "What would it cost to move off this platform in 90 days?"
**How to test your setup this week:** Ask your agency, "If we decided to move to a different platform next year, what would block us, and what would the rough cost be?" If the answer is "you'd basically start over," your migration optionality is zero, and your vendor knows it.
## The operating stack at a glance
| # | Practice | Frequency | Primary signal | Failure mode if missing |
|---|---|---|---|---|
| 1 | Monitoring cadence | Continuous, sub-daily | Time-to-detection on any regression | Issues caught at end-of-month report |
| 2 | Plugin governance | Quarterly review + per-disclosure | Active plugin count and CVE exposure | Vulnerable, slow, conflict-prone site |
| 3 | Hosting tier | Continuous baseline | Core Web Vitals + uptime | Speed and reliability ceiling capped |
| 4 | AI workflow integration | Continuous, pipeline-driven | Agent-accessible API surface | AI roadmap stalls at editor features |
| 5 | Data centralization | Real-time + nightly canonicalization | Reproducibility of any report number | Reports that don't match Google |
| 6 | Migration optionality | Audited per engagement | 90-day cost-to-move estimate | Vendor lock-in priced into every renewal |
## The 90-day self-audit
If you read both parts of this series and want a single action to take this quarter, run the six tests. Email them to your current agency tomorrow.
| # | Question to ask | What a passing answer looks like |
|---|---|---|
| 1 | "If conversion tracking broke at 11 AM Tuesday, when would you know?" | Minutes or hours, not days |
| 2 | "What's our current plugin list and the business reason for each?" | Documented within 48 hours |
| 3 | "What hosting tier are we on and what's included?" | Managed, with caching, WAF, backups, staging |
| 4 | "Does our site expose a public API with write access under our control?" | Yes, with documented endpoints |
| 5 | "Walk me through how a number in our monthly report gets calculated." | Reproducible end-to-end from source data |
| 6 | "What would it cost to migrate off this platform in 90 days?" | A real number, neither zero nor catastrophic |
Six questions. The pattern of answers will tell you more about your operating layer than any agency case study ever will.
## Quick answers
**What is the "operating layer" of a website?**
The set of operational practices that sit above the CMS and predict whether a website performs as a business asset. Six practices in our framework: monitoring cadence, plugin governance, hosting tier, AI workflow integration, data centralization, and migration optionality. Each one has a frequency. Each one is platform-independent.
**How often should a small-business website be monitored in 2026?**
Reportable surfaces (keyword positions, conversion events, page speed, ad-budget pacing) should be tracked at sub-daily frequency. We run budget pacing every 30 minutes, position tracking daily across 1,000+ keywords, conversion-event QA continuously, and site uptime sub-minute. Monthly reports are an output, not a cadence.
**What does good plugin governance look like on WordPress?**
A documented one-sentence business reason per active plugin, a quarterly add/keep/remove review, a patch cadence under 7 days for routine updates and under 24 hours for critical security patches, zero plugins marked abandoned by their developer, and a standing answer to "what would we replace this with if it disappeared tomorrow."
**What is migration optionality and why does it matter?**
Migration optionality is the cost of moving off a platform, expressed as a real number and a 90-day plan. High optionality means content stored in structured exportable formats (database tables, Markdown, JSON), public APIs with read AND write access, theme and template code in version control, and tested backup/restore. Low optionality is vendor lock-in priced into every renewal you don't realize you're paying.
**How is AI changing small-business websites in 2026?**
Two big shifts. First, AI agents can now read and write to your CMS directly: WordPress.com opened MCP write access in March 2026 and Shopify rolled out Sidekick + Agentic Storefronts. Second, AI search surfaces (ChatGPT Search, Perplexity, Google AI Overviews) are now meaningful traffic sources, and they cite well-structured content with explicit claims and sources. Platforms with closed AI features (Wix, Squarespace) shorten your AI roadmap to whatever fits inside their editor.
**What's the difference between monitoring a website and reporting on a website?**
Monitoring is continuous and signal-shaped: an automated system catches a regression while you can still fix it, usually within minutes or hours. Reporting is periodic and rear-view: a monthly PDF tells you what already happened. Most agencies sell reporting and call it monitoring. The test is simple: ask how fast a broken conversion pixel would be caught. Minutes-to-hours means monitoring. Days-to-weeks means reporting.
## Why this comes from Choice OMG
Most agencies are CMS shops. They have a stack they sell. WordPress shop. Webflow agency. Shopify partner. The CMS choice is the centerpiece of the pitch because it's also the centerpiece of the operating model. If the CMS isn't the value, the agency doesn't have much to sell.
We're built differently by deliberate design. We're an **Edmonton-based digital marketing agency** with clients across Western Canada. We run **79 WordPress sites** alongside custom Go applications, hosted builders, and Shopify stores because the platform isn't where we add value. The value sits in the six practices above: **Thor as the single source of truth, every-30-minute budget pacing, daily position tracking across 1,000+ keywords, quarterly plugin liability reviews, managed hosting baselines, and migration optionality preserved on every engagement**.
That's the layer that compounds. That's the layer that survives platform changes. And that's the layer almost nobody is selling, because it's harder to demo on a sales call than a CMS template.
If you want a conversation about your operating layer rather than your CMS, [get in touch](/contact) and bring the answers to the six self-audit questions above; that's where we'll start.
## Related reading
- Part 1: [The Platform Debate Is a Distraction: 7 Myths About Choosing a Website CMS in 2026](/blog/cms-debate-is-distraction/)
- [7 Red Flags When Hiring an Edmonton Digital Marketing Agency](/blog/edmonton-digital-marketing-agency-red-flags/)
- [Conversion Tracking Breaks Silently](/blog/conversion-tracking-breaks/)
- [What Breaks at 2 AM: Why Marketing Needs Automated Infrastructure](/blog/what-breaks-at-2am/)
- [Why We Built a Single Source of Truth for Client Data](/blog/single-source-of-truth/)
- [How We Monitor 60,000+ Data Points Across Our Client Base](/blog/how-we-monitor-60000-data-points/)
- [Why We Don't Charge a Percentage of Ad Spend](/blog/why-flat-fees/)
- [The Real Cost of SEO in 2026](/blog/real-cost-of-seo/)
---
## The Platform Debate Is a Distraction: 7 Myths About Choosing a Website CMS in 2026
In 2026, the CMS you pick predicts almost nothing about whether your website wins. The operating layer above it predicts almost everything. We run 79 WordPress sites, 47 client reporting workspaces, custom Go applications, and hosted-builder sites in parallel. The platform is not what separates the businesses that get results from the businesses that don't. Below are seven myths every agency is still selling, and what the 2026 data actually shows.
Every "how to choose a CMS" article frames this as a feature comparison. WordPress has more plugins. Wix has better AI. Shopify has stronger commerce. Webflow has cleaner design. Squarespace is easier. Pick whichever set of trade-offs matches your priorities.
That framing has been wrong for at least three years, and the gap between framing and reality widened sharply in 2026. The platform decision is not the strategic decision. It hasn't been since the difference between "managed WordPress on a $30/mo host" and "Wix on its default stack" narrowed to something most owners can't perceive with the naked eye.
We say this from operational experience, not editorial opinion. We're an **Edmonton-based digital marketing agency** with a portfolio spread across Western Canada in healthcare, skilled trades, and professional services. We currently manage **79 WordPress sites on a single managed Plesk environment**, sync data for **47 active client reporting workspaces** through a 120-table single source of truth, and have migrated sites both into and out of WordPress when the business case required it. Across all of that work, the predictor of success isn't which platform sits underneath. It's what we operate above it.
Here are the seven myths that keep small businesses choosing for the wrong reasons.
## Myth #1: "WordPress is the safest choice because it's the most widely used"
**Reality:** WordPress is the most-attacked stack on the internet *because* it's the most widely used. The 2026 Patchstack security report logged **11,334 new vulnerabilities in the WordPress ecosystem in 2025**, a 42% jump from the year before. The median time from public disclosure to first exploitation is **five hours**.
11,334 new WordPress vulnerabilities disclosed in 2025, up 42% YoY. 80% live in plugins. 46% are not patched in time for disclosure.Source: Patchstack, State of WordPress Security 2026
That number doesn't mean WordPress is unsafe. It means *unmanaged* WordPress is dangerous in a way it wasn't five years ago. The exploitation window has collapsed: **20% of heavily-exploited vulnerabilities are weaponized within six hours of public disclosure**, 45% within 24 hours, and 70% within a week. "We update plugins monthly" is now an operational gap measured in hundreds of attack-hours.
| Patchstack metric | 2024 | 2025 |
|---|---:|---:|
| New ecosystem vulnerabilities | 7,966 | 11,334 |
| Year-over-year change | n/a | +42% |
| Highly exploitable share | baseline | +113% |
| Median time-to-exploit (heavily-targeted) | n/a | 5 hours |
WordPress is still the safest choice when it's governed properly, and the most dangerous choice when it isn't; governance is what makes the difference, not the platform.
**What this means for you:** If your current agency can't tell you in writing how fast plugin updates are applied across your site and what their monitoring cadence looks like, the size of WordPress's market share is not protecting you.
## Myth #2: "Hosted builders like Wix and Squarespace are slow"
**Reality:** They're meaningfully faster than the median WordPress site in 2026.
According to public Core Web Vitals data from HTTP Archive's Tech Report, only **about 44% of WordPress sites pass all three Core Web Vitals on mobile**. Compare:
| Platform | Mobile CWV pass rate (2026) |
|---|---:|
| Wix | 71-75% |
| Shopify | ~65% |
| Squarespace | 55-60% |
| WordPress | ~44% |
32% of WordPress sites have a "good" Time-to-First-Byte. The other 68% are losing the page-speed argument before the first byte ever leaves the server.Source: HTTP Archive / CrUX Technology Report, 2026
Wix and Shopify win on the average because they control the hosting layer: one stack everywhere, for both. WordPress is whatever host you bought, whatever theme you picked, whatever plugins you installed, and whatever cache, if any, got configured, and that variance across installs is what drags the average down.
WordPress on a well-tuned managed host with a lean theme and proper caching beats almost everything. WordPress on $5/month shared hosting with a heavy page builder and 47 active plugins is what the average looks like, and the average is slow.
**The practical takeaway:** "Switching to a hosted builder will make my site faster" is true on the median, and untrue on the upper quartile. If you want to stay on WordPress and beat the hosted builders, you need to operate it like infrastructure, not like a hobby.
## Myth #3: "WordPress is the AI laggard"
**Reality:** WordPress is taking the AI route that scales best for serious businesses, and Wix and Squarespace are taking the route that locks you in.
In March 2026, **WordPress.com opened write access to its Model Context Protocol (MCP) server**. AI agents (Claude, ChatGPT, Cursor) can now connect directly and create posts, build pages, manage comments, and organize content on any WordPress.com site with a paid plan. WordPress is also shipping the MCP Adapter and Abilities API for self-hosted sites.
MCP write access opened on WordPress.com in March 2026. Wix and Squarespace AI features remain inside the walls of their own editors.Source: WordPress.com platform announcements, March 2026
Shopify is doing the same on its side: Sidekick plus Agentic Storefronts, syndicating products directly into ChatGPT, Microsoft Copilot, and Perplexity. Two of the three biggest CMS platforms have publicly committed to open AI integration protocols in 2026.
Wix and Squarespace have AI generation features inside the editor. They're useful for the owner sitting in the editor. They're not useful when you want to wire your site into a marketing automation stack, a content production pipeline, or an AI agent workflow that touches multiple systems. Those features stop at the platform's walls.
**For your roadmap:** if it includes AI inside your operating workflow, not just AI inside your editor, the open-protocol platforms (WordPress and Shopify) have a structural advantage that the closed-platform AI tools can't match.
## Myth #4: "If my site is slow, switching platforms will fix it"
**Reality:** Hosting tier and plugin discipline dwarf platform choice. Switching platforms without fixing the operating layer just moves the problem to a different vendor's pricing page.
We've taken WordPress sites from "poor" to "excellent" Core Web Vitals without leaving WordPress. We've also seen sites move from WordPress to a hosted builder and gain nothing measurable because the page weight, the third-party scripts, the image discipline, and the absence of caching strategy all moved with them.
The deep research behind this series put it bluntly: performance headroom on WordPress depends on host quality, cache strategy, image optimisation, and script discipline. Same as performance on every other platform. The difference between platforms in 2026 is the *floor*, not the *ceiling*.
**Before you migrate:** fix the four things that actually move page speed: tier of hosting, count of active plugins, image format and size discipline, and whether you have full-page caching. If the answer to those four questions is "I don't know," the platform isn't your problem.
## Myth #5: "Cheap hosting is fine for small businesses"
**Reality:** The $5/month shared-hosting WordPress era is over. Anyone still pitching it in 2026 is selling you 2018.
Of the **79 WordPress sites we currently manage**, none run on bargain shared hosting. They run on a managed Plesk environment with PHP, MySQL, and security baselines we control, and the decision comes down to cost math.
A shared host at $5/month gives you contended CPU, throttled I/O, no edge cache, no CDN, and shared IP reputation. A managed WordPress host at ~$30/month gives you dedicated resources, edge caching, CDN, WAF, automated backups, staging environments, and a support team that knows WordPress. The difference shows up in everything from page speed to security to recovery time when something goes wrong.
~$30/month is the realistic 2026 floor for managed WordPress hosting that competes with hosted builders on speed and reliability.Source: WP Engine, Kinsta, WordPress.com Business public pricing, May 2026
If you can't justify $30/month for hosting, you probably can't justify a custom website either. Use a hosted builder. That's not an insult; it's a coherent operating decision. What doesn't work is cheap WordPress hosting plus the expectation of business-grade reliability.
**Ask your agency this:** what they're paying for hosting on your behalf and what's included in that tier. If the answer is "we don't manage hosting" or "we use whatever you have," that's not a service. That's an abdication.
## Myth #6: "Plugins are productivity, not risk"
**Reality:** Plugin count is one of the highest-correlation risk metrics in WordPress. The Patchstack 2026 data is unambiguous: **80% of WordPress-ecosystem vulnerabilities live in plugins**, and 46% are not patched in time for disclosure.
We treat the plugin list as a liability sheet, not a feature list. In Q1 2026 we **removed the Search Atlas (metasync) plugin from 10 client sites** because the risk and ongoing maintenance cost didn't justify the value. That's a normal cycle for us. We add plugins when there's no better way to deliver the function, and we remove plugins the moment a better way appears.
80% of WordPress vulnerabilities live in plugins, not core. Of premium/freemium components, 59% rate as high-priority for mass automated attack.Source: Patchstack, State of WordPress Security 2026
A 30-plugin WordPress install carries a long fuse on an attack surface, plus performance overhead, plus an update conflict timer running 24/7. Every plugin is a vendor decision that someone has to keep monitoring.
**Check this now:** count the active plugins on your site. If the number is over 25 and your agency has never proposed removing any of them, the agency is treating your site like a feature box, not a system.
## Myth #7: "Picking the right CMS is THE strategic decision"
**Reality:** The CMS is one of dozens of decisions, and not the most important one.
We run 79 WordPress sites and roughly a dozen non-WordPress properties: custom Go applications, hosted builders, Shopify stores. The pattern across all of them is the same: the businesses that succeed online are the ones where someone is operating the layer above the CMS. The businesses that struggle are the ones where the CMS choice was the last serious technical decision anyone made about the site.
What lives in that layer above the CMS:
| Visible: what buyers debate | Submerged: what actually predicts success |
|---|---|
| Which CMS | Monitoring cadence and alerting thresholds |
| Which theme | Plugin and extension governance |
| Which page builder | Hosting tier and cache strategy |
| Which template | AI workflow and content pipelines |
| Editor convenience | Data centralization and reporting integrity |
| Brand colours | Migration optionality and vendor lock-in posture |
The first column is what every agency pitches. The second column is what determines whether your website is an asset or a liability eighteen months from now.
**Before you sign off on a migration:** ask whoever's selling it what's in their second column. If they don't have one, the CMS migration is not going to save you.
## The iceberg, in one line
The CMS is roughly 10% of the outcome. The operating layer above it is roughly 90%. The proportions are illustrative. The directional truth is not. After fifteen years and several hundred small-business site engagements, the layer above the CMS dominates the outcome, and it's the layer almost nobody is selling.
## How to use this article this week
If you read this and want a single action to take, do this: pick the three myths above that best describe an argument you've heard from a previous agency. Write them down. Then ask your current agency, in writing, how they handle the *reality* version of each one. The shape of their answers will tell you whether they operate websites or just build them.
If you want a deeper read on adjacent failure modes, [7 Red Flags When Hiring an Edmonton Digital Marketing Agency](/blog/edmonton-digital-marketing-agency-red-flags/) catalogues the operating-layer failures that show up first when nobody is watching. [Conversion Tracking Breaks Silently](/blog/conversion-tracking-breaks/) shows the most common one in detail.
## Quick answers
**Does the CMS choice matter for SEO in 2026?**
Marginally. Core Web Vitals, structured data, page architecture, internal linking, and crawl health matter. The CMS becomes relevant only when it makes those harder or easier to operate. WordPress, Shopify, and Webflow can all rank top-3 in the same niche; the differentiator is the operating layer above the CMS, not the platform underneath.
**Is WordPress secure in 2026?**
Yes, when governed. The Patchstack 2026 report logged 11,334 ecosystem vulnerabilities with a five-hour median time-to-exploit, and 80% of them live in plugins. WordPress on a managed host with quarterly plugin liability reviews and an under-7-day patch cadence is one of the safest options on the market. WordPress with 35 unmonitored plugins on shared hosting is one of the most dangerous.
**WordPress vs Wix for small business: which is faster?**
On the median, Wix is faster (71-75% of sites pass mobile Core Web Vitals versus ~44% for WordPress). On the upper quartile, well-tuned WordPress on managed hosting with a lean theme and proper caching beats either. The platform sets the floor; the operating layer sets the ceiling.
**Will switching from WordPress to a hosted builder fix my slow site?**
Usually not. We've moved sites in both directions. The gains come from fixing host quality, plugin discipline, image strategy, and caching, not from the platform swap itself. Migrate when the operating model can't deliver on the current platform, not because the marketing on the new platform sounds better.
**Which CMS is best for AI integration in 2026?**
WordPress.com and Shopify both shipped protocol-level AI access in 2026: WordPress.com opened MCP write access in March, and Shopify rolled out Sidekick plus Agentic Storefronts. Both let external AI agents read and write to your site under scoped permissions. Wix and Squarespace ship AI features inside the editor only, which is useful if you write inside the editor and a structural limitation if your AI workflow lives outside it.
## Why this comes from Choice OMG
We're CMS-agnostic by deliberate design. Most agencies are WordPress shops, Webflow shops, Shopify partners, or hosted-builder resellers. Their pitch starts with their stack because their economics depend on you choosing it.
Ours doesn't. We run **79 WordPress sites** because most of our small-business clients fit WordPress, **alongside custom Go applications, hosted builders, and Shopify stores** because some don't. The value sits in the operating layer above whichever CMS we land on: a 120-table single source of truth in our Thor reporting database, every-30-minute budget pacing across managed Google Ads accounts, daily position tracking across 1,000+ keywords, quarterly plugin liability reviews, managed hosting baselines, and migration optionality preserved on every engagement.
That's what Part 2 is about.
## Coming in Part 2
The prescriptive half. Six operating-layer practices that move the needle on any platform, the cadence and signals that define each one, and a six-question self-audit you can email to your current agency this week to test whether your site is being operated or just maintained.
Read it here: [The Operating Layer: 6 Practices That Predict Website Success in 2026 (Regardless of CMS)](/blog/operating-layer-website-success/).
---
## Google Ads Split Into Three Businesses. Your Plan Should Too.
In Q1 2026 Google reported Search & other revenue up 19%, YouTube ad revenue up 11%, and Google Network revenue down 4%. EMARKETER projects Meta will overtake Google on worldwide ad revenue this year. The blended "Google Ads" headline obscures three businesses moving in three different directions, and SMB media plans built on the old monolithic view are now mis-priced.
## The Chart Nobody Put on One Slide
When Alphabet reported Q1 2026 in late April, the headline coverage was "Search +19%, beat estimates." That headline was correct and badly incomplete. The full segment picture from the disclosure looked like this:
| Q1 2026 line | Revenue | YoY growth |
|---|---|---|
| Google Search & other | $60.4B | +19% |
| YouTube ads | $9.9B | +11% |
| Google Network | $7.0B | **-4%** |
| Total Google advertising | $77.3B | +15.5% |
Three lines, three directions. The blended +15.5% looks healthy. The dispersion underneath it is the actual story.
Search +19%, YouTube +11%, Network -4% in Q1 2026: three Google ad businesses moving in three different directions inside a single quarterly headlineSource: Alphabet Q1 2026 earnings disclosure, April 2026
For an SMB allocating media budget across Search, YouTube and Demand Gen, and any Display or programmatic placement served through the Google Display Network, those three line items are no longer parts of the same machine. They are parts of three machines in three states: one accelerating, one accommodating, one contracting. Treating them as a single channel with a single strategy was already lossy in 2024. In 2026 it is the kind of planning error that quietly mis-prices an annual budget.
## Search (+19%): The Strong Half Is Getting Stronger and More AI-Mediated
Search is the part of Google getting noticeably stronger. Google's own commentary from the earnings call: queries at all-time highs across major markets, AI Overviews now reaching about 2 billion monthly users across 200+ countries, and "people coming back to Search more" via AI Mode.
Statcounter still puts Google at roughly 90% of worldwide search engine share and 85% in the US, so the +19% on Search is happening from a position of dominance, not from a recovery base. It is also happening with cost relief rather than cost pressure: Tinuiti's data shows brand text CPC inflation that spiked to +19% YoY in Q1 2025 had eased to +2% by Q4 2025, and non-brand CPCs went mildly negative through Q3. Some of that easing has a non-Google explanation. Amazon withdrew from US Google Shopping auctions on 23 July 2025, removing a uniquely large bidder and pulling the Shopping CPC trend with it for the rest of the year. The Search & other +19% sits on top of a quieter, partly conditional cost picture, not a uniformly inflationary one.
What is underneath that growth is a Search product that does not look like the 2018 version. AI Overviews have carried their own ad inventory at scale since the May 2025 rollout, with eligibility now broad across English-language markets. AI Mode is a smaller, still-emerging surface: ads were in test for most of 2025 and only expanded to sponsored retailer formats and Direct Offers in February 2026, including for travel. By volume the AI inventory most SMB accounts will engage with in 2026 is AI Overviews, with AI Mode as a secondary layer that will matter more as 2026 progresses. The campaign types eligible to fill those AI placements are broad match, AI Max, Performance Max, Shopping, and DSA. Exact and phrase match keywords cannot trigger them.
Translation: the part of Google that is growing is the part advertisers have least manual control over. Search & other revenue grew 19% because Google wedged ads into AI surfaces and built campaign types that feed them. The "old Google Ads" account, the one a Western Canadian SMB used to run with exact-match keyword discipline and tight ad-group structure, does not have inventory access to the surfaces driving that +19%.
That fact anchors the rest of this piece: the platform did not just add an AI feature, it shifted the inventory funding the headline growth into surfaces with a different control regime, and every recommendation that follows traces back to it.
Aaron Levy, now Optmyzr's evangelist and previously VP of Paid Search at Tinuiti, describes what the underlying behaviour looks like across the Optmyzr account base: "click and traffic volume was down like 15 to 20% year-over-year. Revenue was up, conversion rate was up, conversion volume was up." His read is that AI is pre-qualifying users and Search is becoming "a true bottom-of-funnel catch-all." Levy is also direct on the cannibalization mechanism: PMax and AI Max, in his words, "heavily overindex on competitive queries... on one side you're paying higher CPCs to bid on a competitor's brand name, and on the other side you're getting your own brand CPCs inflated as well." That is the part SMBs can watch for in their own accounts. Brand-term CPC creep that does not match search-volume changes is a leading indicator that PMax or AI Max is bidding inside the brand auction, on both sides of it.
This is a fork in the road that does not get framed as a fork in the road. Either an account engages with broad match, AI Max, and Performance Max with proper guardrails and joins the inventory expansion, or the account remains in a tight exact-and-phrase posture and quietly cedes share of voice on every AI-eligible surface. Both paths are defensible, but only when the choice is made deliberately rather than by default.
## YouTube (+11%): Pricing Accommodation, Not Pricing Power
YouTube's headline +11% looks like the calm middle of the three. Tinuiti's data through Q4 2025 shows what is happening underneath: YouTube CPMs were down approximately 18% year-over-year even as impressions surged. Volume is up, unit price is meaningfully down, and aggregate revenue is growing because volume is growing faster than price is falling.
YouTube CPMs -18% YoY in Q4 2025 while impressions surged: pricing accommodation rather than pricing power, driven by Demand Gen adoption and competitive pressure from Reels and TikTokSource: Tinuiti Digital Ads Benchmark Report, Q4 2025
The mechanism is competitive. YouTube, Demand Gen, and Reels-class video compete for the same dollars as Meta Reels, TikTok, and connected-TV inventory. Meta's Advantage+ video automation has matured to the point that EMARKETER attributes a meaningful chunk of Meta's 2026 acceleration to it. To keep YouTube impression growth alive against that competitive set, Google has had to accommodate price.
For SMBs, that accommodation is a pricing window. Demand Gen at 2026 CPMs is structurally cheaper than Demand Gen at 2024 CPMs, and the conversion-tracking gap that used to plague YouTube has narrowed considerably with Google's enhanced conversion and Data Manager work. Whether you should fill that window depends on whether your business has a story video can actually tell: a real founder story, a treatment-results walkthrough, a service explainer that answers the questions sales gets every week. If you do, the discount is real, and there is no reason to assume it stays this generous through 2027.
## Google Network (-4%): The Open-Web Ad Layer Is Contracting
This is the line that did not make most coverage. Google Network revenue (AdSense, AdMob, and Ad Manager partner inventory; the third-party publisher monetization layer) fell 4% YoY in Q1 2026.
That is the most pronounced Network decline in years, comparable in size only to the 2022 to 2023 ad-market downturn, and unlike that earlier dip it is happening while Google's owned-surface revenue is accelerating, not while the broader ad market is soft. The cleanest explanation is the one PPC Land surfaced bluntly: "Google Network ad revenue falls 4% as AI reshapes the web." When the queries that used to bounce out to publisher pages now resolve inside an AI Overview or an AI Mode panel, those publisher visits do not happen, those publisher impressions do not get sold, and Google's third-party network revenue contracts.
The AI assistant layer where those queries now resolve has fragmented at the same time. Statcounter's April 2026 chatbot referral data shows ChatGPT at 76.85% of global AI assistant referrals (down from 84.21% a year earlier), Gemini at 9.00% having overtaken Perplexity in March 2026, Perplexity at 7.73%, Microsoft Copilot at 3.76%, and Claude at 2.66% after growing nearly tenfold from April 2025. Statcounter CEO Aodhan Cullen's framing: "For website owners and digital marketers, the message is clear: optimizing for a single AI chatbot is no longer sufficient." The Network's -4% is the trailing indicator of that fragmentation; the leading indicator is what an AI Overview or a Gemini result does to a publisher's organic CTR before the impression ever reaches their ad stack.
For an SMB advertiser, the Network line is the inventory you reach when you run Display campaigns, GDN placements, programmatic buys executed through Google's stack, or Performance Max segments that hit display surfaces. That inventory is the contracting half of Google's ad business. The publishers carrying it have weaker traffic, less premium adjacency, and a worsening monetization model. Buying it as a flat replacement for Search reach was already imprecise, and the Q1 2026 numbers make that substitution meaningfully wrong.
The line item that needs the hardest look on a current portfolio is Performance Max with all surfaces enabled. Without explicit campaign-level signals telling PMax to favour Search and YouTube, the algorithm is free to allocate spend toward Display and Network surfaces, which is exactly the inventory Google's own segment data is showing as the weakening half. PMax's appetite for cheap impressions is a feature in normal conditions and a problem when the cheap impressions are coming from a contracting publisher base.
## Why the Three Businesses Are Diverging
The three numbers stack into one story: AI assistants are eating the open web, and Google's response is to defend its owned surfaces while the open layer shrinks.
Search and YouTube are owned. Google can ship ads into AI Overviews because Google operates AI Overviews. Google can compress YouTube CPMs to keep impression growth alive because Google operates YouTube. The Network is not owned. It depends on third-party publishers having traffic and being able to monetize it. Both halves of that loop are weakening: AI assistants intercept the queries before publishers see them, and the impressions that do reach publisher pages monetize less efficiently when premium content is being summarised upstream.
Google's product roadmap of the last twelve months reads off the same logic. AI Max for Search, ads in AI Overviews, ads in AI Mode, AI Max for Shopping and Travel, Direct Offers, agentic commerce, the Power Pack framing, the September 2026 forced migration of DSA and campaign-level broad match into AI Max: all of these push budget into Google-controlled, AI-mediated environments where Google handles matching, bidding, creative assembly, and inventory allocation. That is where the +19% on Search is coming from. The Network does not get a comparable defensive product because Google cannot ship a third-party publisher's traffic into existence.
The strategic implication is uncomfortable but clean. The more Google's growth depends on AI-mediated owned surfaces, the more advertisers are buying into a buying environment they have less direct control over. The trade is real reach for less granular governance, and the longer an SMB delays acknowledging it, the more the trade gets made by default rather than by decision.
Frederick Vallaeys, Optmyzr's CEO and a former Google AdWords Evangelist, frames the asymmetry directly: advertisers are often the ones "paying for Google to learn" as the automated systems mature. The R&D burden of building AI-mediated advertising is being borne in part by advertiser budgets through the learning curves of AI Max, Performance Max, and Smart Bidding Exploration. That is the cost of being early on a defensive product cycle, and it is the strongest argument for engaging with these systems deliberately, with measurement, rather than by accident.
## The Meta Footnote That Is Actually a Headline
EMARKETER published a 2026 worldwide ad revenue projection in late Q1: Meta $243.46B at 26.8% share with +24.1% growth, and Google $239.54B at 26.4% share with +11.9% growth. This would be the first year Meta surpasses Google on total digital ad revenue.
$243.46B vs $239.54B: EMARKETER's 2026 projection has Meta surpassing Google on worldwide ad revenue for the first time, driven by Advantage+ automation, AI-generated creative, and ReelsSource: EMARKETER worldwide digital ad spending forecast, 2026
EMARKETER attributes the gap to specific Meta levers: Advantage+ automation maturing into a default-on engine for many advertisers, AI-generated creative reducing production cost, Reels gaining attention share against YouTube and TikTok, and measurable advertiser ROI gains compounding from those three. Google is shipping a parallel automation playbook (AI Max, PMax, Demand Gen, Smart Bidding Exploration). Meta is currently executing the playbook on advertiser ROI more effectively.
For Western Canadian SMBs, the practical reading is this: the assumption that "Google is the default platform and Meta is supplementary" is an artifact of 2018 to 2022 buying behaviour. By the end of 2026 it may not be a defensible default. Treating Meta competency as a 20% retargeting line item, the way the [Google Ads vs Meta Ads](/blog/google-ads-vs-meta-ads/) post historically scoped it for many professional services accounts, was right for 2024. By 2027 the same client's portfolio may need a more substantial Meta build-out, which means the agency and the client should be developing that capability now, not under deadline pressure when the Google numbers plateau.
## What This Means for a Western Canadian SMB in 2026
The bifurcation is showing up in practitioner sentiment data as well as the revenue lines. The State of PPC Report 2026, surveying 1,306 PPC professionals across 50+ countries in late 2025, found 53% of respondents saying managing PPC is harder than two years ago, 48% citing "lack of control" as their top Performance Max frustration, and 62% identifying increasingly opaque, black-box platforms as their top overall industry challenge.
Five practical implications.
**1. Stop scoping "Google Ads" as one strategy.** Search (with brand and non-brand sub-lines), AI Max, Performance Max, Demand Gen, and any Display exposure are now five different products operating in five different cost-and-control regimes. Budget conversations should treat them as separate line items with separate measurement plans, separate experimentation cadences, and separate accountability metrics. Blended "Google Ads ROAS" obscures more than it reveals; in 2026 it conceals the surfaces that matter most.
**2. Don't bake Display or programmatic Google Network into 2026 to 2027 lead-gen plans without a measurement-validity check.** The contracting half of Google's ad business is the half most SMBs are quietly using when they let Performance Max default to all surfaces or buy "Google Display reach" as a top-of-funnel layer. Where the inventory is shrinking, the placements available are skewing toward leftover inventory, not premium adjacency. Audit PMax channel performance reports campaign by campaign and decide explicitly whether Display and Network surfaces stay enabled.
**3. The YouTube and Demand Gen pricing window is open right now.** If you have video assets that can do real work, Demand Gen at 2026 CPMs is structurally cheaper than it has been for the last three years. Run a small structured test inside a dedicated campaign with its own conversion actions, not bundled into PMax. The discount is being subsidised by Google's competitive position; the position is unlikely to soften, which means the discount may not last.
**4. Build real Meta competency in parallel.** Not as a retargeting afterthought. As a primary-channel option for the right business profile. The clients who get burned in 2027 are the ones whose first serious Meta build-out happens after their Google performance plateaus and the budget has already been re-cut. Start the build now, with measured budgets and operational rigour, while the Google side is still funding the operating budget and there is room to experiment without it being a rescue mission.
**5. Treat AI surfaces as their own line item with their own measurement plan.** AI Overviews ads, AI Mode placements, and AI Max-driven query expansion are how Google's strong half stays strong. They also cannot be honestly measured by the same blended ROAS view that worked for keyword campaigns. Run them as separate campaigns with brand exclusions, holdouts where the geography allows, and a profit-margin lens rather than a topline conversion-volume lens. We covered the practitioner-side problem with AI Max attribution fog briefly in [The Google Ads Job Changed in 2026](/blog/google-ads-2026-operating-model-shift/); the point holds doubly when the inventory you are testing is part of the line of business Google is most aggressively defending.
## What We Changed Across the Portfolio
When the Q1 2026 disclosure landed and the bifurcation became visible in the segment data, we made several concrete operational changes across our active accounts. The first was a reporting split: every account's monthly report now breaks Google spend into Search (with brand and non-brand sub-lines), AI Max, Performance Max, Demand Gen, and Display or Network exposure, with each surface getting its own conversion volume, cost per qualified lead, and margin column. Aggregating these into one "Google Ads" number was already losing information by 2024; in 2026 it loses the most important information. The four further changes:
**Display and Network exposure audited and downgraded by default.** Across the portfolio, Performance Max settings were reviewed for Display and Network surface inclusion. For lead-gen accounts, those surfaces were excluded by default unless a holdout test had proven incremental contribution. The contracting half of Google's ad business is not an automatic place to put SMB lead-gen budget, and PMax's defaulted surface mix was sending money there without explicit consent.
**A YouTube and Demand Gen test slot opened in every account that has video assets.** Small budgets, separate campaigns, separate conversion actions, separate reporting. The hypothesis is that current CPMs are competitive enough to warrant a controlled test, not a portfolio commitment. If the unit economics hold up over 60 to 90 days, the line item gets sized up. If they do not, it gets parked.
**Meta build-out promoted from optional to recommended in 2026 plans.** For new clients, the proposal now includes a Meta competency build phase even when the initial channel mix is Google-heavy. For existing clients in professional services, where the [law firm case study](/blog/google-ads-vs-meta-ads/) historically pushed Meta down to a retargeting role, we re-scoped the Meta line as a 12-month capability investment rather than a fixed budget allocation, with a decision point at month nine on whether to size up the channel materially.
**AI-surface measurement scaffolding added.** AI Max and broad-match-eligible campaigns running into AI Overview and AI Mode placements now report through a separate measurement layer with explicit holdout tracking where geography supports it. This is the same operational discipline we built for [tracking activity across 10 AI platforms](/blog/ai-platform-tracking/) on the SEO side; the paid media equivalent had lagged it, and we closed the gap this quarter.
## The Short Version
The Google Ads platform you bought in 2020 was one product with a coherent strategy. The Google Ads platform you are buying in 2026 is three products moving in three different directions, with the strong half being absorbed into AI surfaces you have less direct control over and the weak half quietly contracting under your Display line items. Meta is closing on Google's total ad revenue while running a parallel automation playbook more effectively on advertiser ROI.
The right response is deliberate portfolio thinking: treat Search, AI-led campaigns, video, and Display as four separate products, each with its own measurement plan, budget envelope, and strategic question. Build Meta competency before you need it. Audit Display exposure as a contracting inventory layer rather than a flat reach option. Run AI surfaces as measured experiments rather than defaults.
Read more about our [Google Ads management approach](/services/google-ads/), our [Edmonton PPC practice](/edmonton/google-ads/), and our broader work on [AI marketing](/services/ai-marketing/). For the operational adjustments we made when the 2026 product changes started landing, see [The Google Ads Job Changed in 2026](/blog/google-ads-2026-operating-model-shift/) and our framework for [where to spend your first paid-media dollar](/blog/google-ads-vs-meta-ads/). To talk through what a portfolio-level rebuild would look like for your business, [get in touch](/contact/).
---
## ChatGPT Ads in 2026, Updated August: oCPC, Audiences, OAIQ Pixel
ChatGPT Ads is six months old and the platform planners evaluated in May no longer exists. Since the May 5 self-serve launch, OpenAI has added a conversion-optimized objective (oCPC), custom audiences from email and phone lists, US state, DMA and ZIP targeting, platform targeting, automatic advanced matching, one-day view-through reporting, and self-serve Ads Manager in nine countries including Canada. On August 18 it announced 31 European markets, opening August 24 through agency and technology partners first. Ads still reach only Free and Go users, which is the constraint that decided our own June test: 8,940 impressions, 58 clicks, a 0.65% click-through rate, and no lead. This guide was first published May 6, 2026 and rewritten August 20, 2026 against OpenAI's current documentation; every change is dated in the section that follows.
This is a field guide to what ChatGPT Ads is today, how the buying mechanics work, what advertisers can and can't control, what the measurement stack actually looks like, and where the platform stands relative to the discovery channels planners already know. For the strategic framing of what this shift means for agencies, see our companion piece, [ChatGPT Ads Are Live: The AI Answer Is the New Ad Unit](/blog/chatgpt-ads-new-ad-unit/).
## What changed between May and August 2026
Six items in this guide were true on May 6 and are not true now. Each is corrected in its section below; this is the dated list.
- **Europe (announced August 18, live August 24).** OpenAI is adding 31 European countries, "including Germany, France, Spain, Italy, Sweden, Norway, Denmark, the Netherlands, and Austria." Access is "through the OpenAI Ads Solutions team, agency partners, and technology partners" first, with "self-service access through Ads Manager" to "follow later this summer." Digiday names the buying partners as Publicis, Omnicom, WPP, Havas, Dentsu and MediaPlus.
- **A third objective: Conversions (oCPC).** OpenAI "expanded beyond CPM and CPC bidding to support conversion optimization." The campaign optimizes toward one standard conversion event, bills per valid click, and takes a Bid Cap per ad group that is "the maximum amount you are willing to bid for a conversion." Custom events are not supported, and existing CPM or CPC campaigns cannot be converted.
- **Custom audiences.** Email or phone lists, raw or SHA-256 hashed, up to 5,000,000 identifiers per upload, usable for campaign inclusion, campaign exclusion, or ad-group bid multipliers. Each audience needs at least 25,000 matched users before it can be used; OpenAI recommends 100,000.
- **Geo and platform targeting.** Campaign-level country targeting plus, in the United States, state, DMA, and ZIP targeting; the API exposes country, region, and DMA. A Platforms control limits delivery to iOS app, Android app, or web.
- **Measurement got deeper.** Automatic advanced matching is on by default for new web pixels and hashes form data with SHA-256 in the browser. One-day view-through conversions report separately as VTA (1d). Reported totals "may include modeled conversions where available." Attributed conversions take 24 to 48 hours to appear.
- **Self-serve is no longer US-only.** OpenAI's availability table lists Ads Manager as Available in Australia, Brazil, Canada, Japan, Korea, Mexico, New Zealand, the United Kingdom, and the United States, and Coming Soon across the 31 European markets. Digiday reports the US$50,000 minimum from the spring launch "has since been dropped."
OpenAI says "tens of thousands of marketers have now advertised on ChatGPT." One independent measurement arrived in the same window: SE Ranking analysed 50,006 commercial prompts and found that 14.35% of ChatGPT ads "had no topical connection to the prompt," and that the advertiser appeared as a cited source in the answer in 3.63% of placements, against 11.53% in Google AI Mode.
## A snapshot of where things stand
| Aspect | Current documented state | Practical implication |
| --- | --- | --- |
| Buying access | Self-serve Ads Manager Beta in nine countries (including Canada, the UK, Australia, Mexico, Brazil, Japan, Korea) plus partner-led buying; 31 European markets open August 24 through partners, self-serve to follow. | Accessible to SMB and mid-market advertisers in the listed countries without an agency intermediary. |
| Eligible inventory | Ads shown to Free and Go users; not shown to paid Plus, Pro, Business, Enterprise, or Education tiers, or to under-18 accounts. | Inventory is shaped by intent-rich consumer sessions, but reach is narrower than total ChatGPT user numbers suggest. |
| Placement | A single sponsored card displayed below relevant ChatGPT conversations, clearly labelled. | Closer to "assistant-adjacent" discovery than classic search or social feed placement. |
| Objectives | CPM (Reach), CPC (Clicks), and oCPC (Conversions) objectives, all self-serve. | Awareness, traffic, and conversion optimization are supported; app-install optimization is not. |
| Measurement | Ads Manager reporting, CSV export, Insights API, JavaScript pixel with automatic advanced matching, Conversions API, one-day view-through reporting, modeled conversions. | Click-through attribution is now fully described; lift studies and multi-day windows are not. |
| Platform maturity | OpenAI describes the product as beta and has signalled more formats, objectives, and buying models will come later. | Plan for it as an experimental channel, not a fully mature core media platform. |
## What ChatGPT Ads actually is
When eligible users on the Free or Go tiers ask ChatGPT a question (planning a dinner party, comparing software, researching a trip), they may now see a sponsored card below the answer. The card shows an advertiser name, favicon, headline, short description, image, and a link to a destination page. It is clearly labelled as sponsored, and OpenAI's policy is explicit that ads cannot influence the assistant's answer.
Inventory is narrower than headline ChatGPT user numbers suggest. Ads do not appear for paid Plus, Pro, Business, Enterprise, or Education subscribers, and they are excluded from accounts identified as under 18. OpenAI also offers eligible users an "Ads-Free" option on the Free tier in exchange for lower usage limits, which trims available impressions further. A company spokesperson told reporters earlier this year that fewer than 20% of eligible users were being shown ads daily during the pilot, which is useful context when sizing the channel.
The single ad format documented today is called a `chat_card`. It carries a 3-50 character title, up to 100 characters of body copy, an image, a favicon, and a target URL. There is no publicly documented self-serve video, carousel, or interactive format yet, although OpenAI has signalled that more formats will follow.
## How buying works
Three campaign objectives are available: a CPM-priced Reach objective, a CPC-priced Clicks objective, and, since the summer, a Conversions objective (oCPC) that bills per click while bidding toward a tracked conversion event. All three run through a relevance-weighted, second-price auction, which means bids are only one input; ad and landing-page relevance to the user's conversation also factor into ranking. Budgets, dates, and country targeting are set at the campaign level; bids and context hints are set at the ad-group level.
Public guidance on pricing is high-level. The table below summarises what is currently published and what external reporting suggests about real-world cost.
| Buying model | Objective name | Billing basis | Official bid guidance | Best public external estimate | Best suited to |
| --- | --- | --- | --- | --- | --- |
| CPM | Views / Reach | Pay per 1,000 impressions | Default max bid US$60 CPM | Pilot CPMs reportedly fell from launch levels to ~US$25 in some cases | Brand visibility, share-of-voice tests, upper-to-mid-funnel discovery |
| CPC | Clicks | Charged per click | Recommended starting max bid US$3-5 CPC | Our June test: CA$4.42 and CA$4.88 average CPC on the two CPC-bid campaigns; SE Ranking reported a 1.30% CTR across 97,000 impressions | Traffic generation, lead pages, commerce pages, qualification flows |
| oCPC | Conversions | Charged per valid click, "not per conversion" | Bid Cap per ad group, "the maximum amount you are willing to bid for a conversion"; OpenAI states "there is no recommended bid amount at this time" | None yet; OpenAI says it "does not yet have performance benchmarks" | Lead and purchase campaigns with a standard conversion event firing at volume |
OpenAI has not published average CPC, CPM, CTR, CPA, or ROAS benchmarks by vertical ("ChatGPT Ads does not yet have performance benchmarks across advertisers, industries, or campaign types"), so any media plan today should treat efficiency assumptions as provisional. The US$50,000 minimum from the spring launch has been dropped, and a daily budget is now the recommended starting control: OpenAI warns that a campaign-total budget "is a total spending limit, not a pacing control" and "spend may accumulate quickly."
The oCPC rules worth knowing before you build: the objective and the conversion event are locked at creation, one standard event per campaign, no custom events, and a Bid Cap that is "not the price charged for a conversion or a guaranteed achieved cost per acquisition." Conversion tracking has to be live before the campaign exists.
US$60 CPM default, US$3-5 CPC recommended, US$50K minimum dropped, and a third objective (oCPC) that bills per click while bidding toward a conversion; the August platform is materially more complete than the May 5 betaSource: OpenAI Help Center (Ads in ChatGPT: The Basics; Conversion-optimized Campaigns), Digiday, August 2026
## Targeting and creative
This is the area most likely to surprise planners coming from Google Ads or Meta. The most important distinction to keep straight is between signals that **shape delivery internally** at OpenAI and controls that **advertisers can explicitly configure**.
| Targeting / signal type | Current status | Notes |
| --- | --- | --- |
| Geo targeting | Documented advertiser control | Country at the campaign level everywhere; state, DMA, and ZIP in the United States; the API exposes country, region, and DMA with a downloadable location catalog |
| Custom audiences | Documented advertiser control | Email or phone lists (raw or SHA-256), 25,000 matched users minimum, usable as campaign inclusion, campaign exclusion, or ad-group bid multipliers; lists cannot be edited after creation |
| Platform targeting | Documented advertiser control | iOS app, Android app, or web (desktop and mobile web together) |
| Context hints | Documented advertiser control | Broad intent and theme guidance written at the ad-group level, not keywords |
| Current-thread relevance | Used internally | Core matching signal; no advertiser-side controls |
| Language | Used internally | No advertiser-side language control |
| Past chats, memory, prior ad interactions | Optional internal signal | Used only if the user has personalised ads enabled |
| Demographics, lookalikes, site retargeting, placement | Not publicly documented | Assume unavailable unless OpenAI or a partner explicitly enables them for your account; custom audiences cover known lists only |
Context hints are explicitly described as broad thematic guidance, not exact-match keywords, and OpenAI recommends writing them as descriptions of the questions, needs, or situations users bring to ChatGPT. Advertisers also do not receive any user data: chats, names, emails, IP addresses, and precise locations stay inside ChatGPT. Custom audiences work the same way in reverse: you upload a list, OpenAI matches it, and "Ads Manager does not show individual matched users." The 25,000 matched-user floor rules the feature out for most local businesses; a regional B2B list or an e-commerce customer file is the realistic use.
The creative implication is straightforward: this channel rewards specific, intent-matched offers far more than generic brand messaging, and squarely favors [conversion optimization](/services/conversion-optimization/) practice. OpenAI's own guidance pushes advertisers to build many distinct creative variations, write benefit-led titles and descriptions, and link to the most relevant page rather than a homepage.
## The campaign workflow
The end-to-end setup process for a new advertiser, drawn from OpenAI's onboarding and quickstart material:
1. Create advertiser account
2. Complete verification
3. Set account info and favicon
4. Add billing profile and payment method
5. Invite team members and generate API keys if needed
6. Create campaign
7. Choose objective (CPM, CPC, or oCPC with its conversion event), dates, budget, locations, platforms, and any custom audiences
8. Create ad groups
9. Add context hints and bids
10. Upload creative asset
11. Create ads with title, body, image, target URL
12. Submit for review
13. Serve if approved
14. Monitor in tables, charts, CSV, or Insights API
15. Optimise bids, context hints, ads, and landing pages
Operationally, the major friction points today are verification, policy review, and beta feature gaps. Ads Manager supports guided creation, bulk upload, performance monitoring, in-line and bulk edits, member permissions, billing, API keys, and change logs; public docs stop short of detailing review SLAs or the full bulk-upload schema.
## Measurement and the pixel
For a beta platform, the measurement stack is more developed than the buying controls. Ads Manager exposes impressions, clicks, spend, CTR, average CPC, average CPM, and conversions, with table views, charts, and CSV export. An Insights API provides programmatic access to performance data at the ad account, campaign, ad group, and ad level. The capability matrix below summarises what is and isn't there today.
| Capability | What is documented now | What is still missing or unclear |
| --- | --- | --- |
| Ads Manager reporting | Tables, charts, CSV; impressions, clicks, spend, CTR, avg CPC/CPM, conversions; per-event columns; one-day view-through (VTA 1d) reported separately; Device and Country segments | Multi-day attribution windows, MMM hooks, lift studies |
| Insights API | REST access to performance data at ad account / campaign / ad group / ad level | No officially published SDK or client libraries dedicated to Ads |
| Pixel (OAIQ SDK) | Browser measurement with `__oppref` cookie; page, content, commerce, lead, subscription, and custom events; automatic advanced matching (SHA-256 in the browser, on by default for new web pixels); multiple pixels per account | Site-visitor remarketing not exposed |
| Conversions API | Server-side events, batch sending, validation mode, deduplication via event ID, opt-out support, optional `oppref` click reference, hashed advanced-matching fields | Modeled-conversion methodology is described only as "aggregated patterns from observed conversions" |
| Partner integrations | Adobe (GenStudio), Criteo, Kargo, Pacvue, StackAdapt; agency holdcos Dentsu, Omnicom, Publicis, WPP | Workflows and commercial availability vary by partner |
| Creative upload | Image upload endpoint that returns a reusable file ID | No documented self-serve video upload format |
For conversion tracking, OpenAI offers two complementary mechanisms.
The JavaScript pixel (distributed as a small SDK called **OAIQ**, currently version 0.1.3) handles browser-side event collection. When a user clicks a ChatGPT ad and lands on the advertiser's site, the SDK sets a first-party cookie called `__oppref` on the merchant's domain with a 30-day (720-hour) lifetime, then posts subsequent event data to OpenAI's measurement endpoint. Because the cookie is first-party (set on your domain, not OpenAI's), it isn't subject to the same browser restrictions that have hollowed out third-party cookie attribution over the last few years. Independent reverse-engineering analyses describe the attribution payload as built around encrypted tokens (`oppref`, `olref`, an `ad_data_token`, and a server-side spam-integrity payload), but planners can treat that as plumbing rather than something they need to operate.
A practical quirk: OpenAI generates the pixel for the advertiser based on what they need to track, rather than letting advertisers freely write their own measurement code. This keeps event taxonomy consistent across the platform but also means changes to your tracking go through OpenAI's tooling, not yours.
The Conversions API is the server-to-server alternative. OpenAI explicitly describes it as more reliable than the pixel alone, and it supports deduplication when you reuse a common event ID across browser and server events. Out of the box, it accepts events from web, mobile_app, offline, physical_store, phone_call, and email action sources, meaning CRM and offline-conversion use cases are technically possible, though OpenAI has not yet published native first-party connectors for major CRM, MMP, or CDP platforms. The pragmatic posture for serious testers is to run pixel and Conversions API together, with a shared event ID on key conversions, and let deduplication handle the overlap. If your team isn't confident the underlying tracking is clean before the test starts, see [Why Your Conversion Tracking Probably Breaks Once a Quarter](/blog/conversion-tracking-breaks/).
Two reporting facts matter for anyone reading early results. Attributed conversions take "24-48 hours" to appear, so a two-day-old campaign is not yet measurable. And the Conversions total "includes click-through conversions only"; view-through is a separate VTA (1d) column that "does not affect CPA, post-click conversion rate, bidding, billing, or conversion optimization." What is still not documented: multi-day windows, lift studies, and incrementality tooling.
## Crawlers and landing pages
OpenAI's documented expectation is that ChatGPT ads landing pages must be valid and must not block two specific user-agents: **OAI-AdsBot** and **OAI-SearchBot**. This is worth understanding because aggressive bot management at the edge (Cloudflare, Akamai, AWS WAF) can quietly break ad approvals before any human at your agency notices.
OpenAI now publicly documents four distinct crawlers, each with a separate purpose:
- **OAI-AdsBot** is the validation crawler. It only visits pages submitted as ChatGPT ads, checks them against OpenAI's ad policies, and uses the page content to assess relevance for ad serving. Its user-agent string is `Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; OAI-AdsBot/1.0; +https://openai.com/adsbot`. OpenAI states data collected by OAI-AdsBot is **not** used to train its generative models. Unlike the other three crawlers, OpenAI has not yet published a JSON IP range list at `openai.com/adsbot.json`, which means edge-level filtering currently has to rely on user-agent matching rather than IP verification.
- **OAI-SearchBot** powers ChatGPT's search and citation features. Allowing this bot is what lets your pages surface inside ChatGPT's organic answers. Blocking it removes you from those results.
- **GPTBot** is the training crawler. This is the one to block if you do not want your content used in training future OpenAI models; blocking it has no effect on whether your ads run or whether you appear in ChatGPT search.
- **ChatGPT-User** fetches pages on demand when a logged-in ChatGPT user asks the assistant to look at a specific URL. Because visits are user-initiated, robots.txt may not always apply.
The practical takeaway is that these are independent tokens. Blocking one does not block the others, and allowing one does not allow the others. A baseline `robots.txt` that lets ads work while keeping training opt-out intact looks like:
User-agent: GPTBot
Disallow: /
User-agent: OAI-SearchBot
Allow: /
User-agent: OAI-AdsBot
Allow: /
User-agent: ChatGPT-User
Allow: /
If you front your site with a CDN or WAF, also confirm that OAI-AdsBot is not being challenged or rate-limited by managed bot rules. Until OpenAI publishes an IP range file, the safest approach is to allow the user-agent string explicitly in your bot-management ruleset and monitor server logs for visits.
## Eligibility, geography, and policy
Two eligibility lenses matter here, and they don't fully agree.
On the **user side**, ads have rolled out from the February US pilot through Canada, Australia, New Zealand, the UK (June, agency-led), Mexico, Brazil, Japan and South Korea, with 31 European countries starting August 24. Ads are shown only to Free and Go users, and only to accounts not identified as under 18.
On the **advertiser side**, the availability table now lists self-serve Ads Manager as Available in Australia, Brazil, Canada, Japan, Korea, Mexico, New Zealand, the United Kingdom, and the United States. Canadian advertisers can sign up directly at ads.openai.com; the May version of this guide told them to expect a partner path or a wait, and that is no longer the case. European advertisers buy through the partner list until self-serve follows "later this summer."
Policy is the most underrated planning constraint. Allowed categories are still concentrated in lifestyle and household goods, local services, travel and experiences, and digital products or education. Dating and sexual content, alcohol and tobacco, gambling, and political content remain disallowed. Health and financial services have moved from disallowed to **restricted**: in the US, OpenAI "may allow ads from approved advertisers on a case-by-case basis" for a named list that includes dental services, hospitals and urgent care, health insurance, medical testing, consumer medical devices, auto loans, credit cards, deposit accounts, financial planning, insurance, and investment services, with proof of licensure possibly required. Outside the US, "ads for health services" and "ads for financial services" are "generally prohibited." For a Canadian clinic or advisor the practical answer is still no.
OpenAI also bars ads from sensitive conversation contexts entirely, including child safety, self-harm, hate, weapons, terrorism, mental health, emotionally reliant interactions, and politics, which puts a real ceiling on inventory in a way feed-based platforms don't have.
## Early performance signals
Hard, comparable performance benchmarks from advertisers are not yet public, but a few directional data points have emerged.
OpenAI says trust metrics in the user experience have not been negatively affected by ads and that ad dismissals are low. Reuters has reported that the US pilot crossed roughly **US$100 million in annualised revenue within six weeks** and that more than **600 advertisers** participated. Criteo, a launch tech partner, has said that across a sample of 500 retailers it observed, LLM-referred traffic converted at roughly **1.5x** the rate of other referral channels, consistent with the platform's intent-rich positioning. Individual brand pilots, including VistaPrint's, have stayed under wraps.
~US$100M annualised revenue in six weeks; 600+ advertisers; LLM referrals converting at ~1.5x other channels; channel-level evidence the inventory is working for someone, not a forecast for any single advertiserSource: Reuters reporting on the OpenAI pilot, and Criteo retailer-sample data, 2026
These are channel-level and partner-level signals, not standardised campaign benchmarks. Two advertiser-level data points have since been published, one of them ours.
**SE Ranking's two-week test** (reported by MediaPost, August 11): three campaigns, eight ad groups, 48 ads across the US, Canada, Australia, and New Zealand, aimed at SEO agencies and in-house specialists. Result: "more than 97,000 impressions and 1,263 clicks, with an average click-through rate of 1.30%," "very few sign-ups," and delivery so uneven that "the two largest ads received around half of all impressions." Their diagnosis was audience eligibility: "the more someone looks like our ICP, the more likely they're on a paid, ad-free plan."
**Our own test** ran June 8 to June 25, 2026: two CPC-bid lead-generation campaigns (Ontario and Alberta) and one CPM-bid campaign, all pointing at our AI marketing service page, with the OAIQ pixel and Conversions API wired through GTM and our own server so a qualified lead would have reported back. Account-level: 8,940 impressions, 58 clicks, 0.65% click-through rate, CA$7.16 average cost per click (the account bills in Canadian dollars; an earlier version of this guide mislabeled these figures US$). The two CPC-bid campaigns cleared at CA$4.42 and CA$4.88 per click with click-through rates of 1.18% and 0.79%. The CPM-bid campaign delivered the most impressions (4,293) at a 0.26% click-through rate, which works out to CA$18.18 per click, roughly four times the CPC-bid price for the same destination. Lead forms submitted from those 58 clicks: none. We paused all three on June 23 for the same reason SE Ranking stopped: the buyer we want (an owner or marketing lead evaluating an agency) is disproportionately on a paid, ad-free plan, so the eligible inventory is the wrong half of the audience. The mechanics worked. The audience did not.
Two B2B tests, one conclusion: CTR between 0.65% and 1.30%, CPC-bid clicks at CA$4 to CA$5 in our test, and almost no sign-ups, because ads reach only Free and Go users and B2B buyers skew to paid plansSource: SE Ranking via MediaPost (2026-08-11) and Choice OMG account data, June 2026
## Where it fits, by goal
The table below maps each common media goal to the platform's current capability and the kind of test scope that is realistic given today's constraints. Suggested budget ranges are estimates of what is needed to generate statistically useful early signal at current bid guidance; they are not OpenAI-published recommendations.
| Goal | Current fit | Suggested approach | Primary KPIs | Approximate monthly test budget |
| --- | --- | --- | --- | --- |
| Brand awareness | Medium | CPM (Views/Reach), multiple context-specific creative variants, clean brand-to-category landers | Impressions, CTR, branded search lift, engaged sessions | US$10k-30k |
| Lead generation (consumer) | Medium to high | oCPC on a standard lead event once tracking is live, CPC before that; pixel + CAPI with a shared event ID; conversion-optimised landers | CPL, qualified-lead rate, booked appointments | US$15k-40k |
| E-commerce: considered purchases | High | CPC, strong product/category pages, full event tracking | CTR, add-to-cart, checkout, CPA, ROAS | US$20k-60k |
| E-commerce: impulse purchases | Medium | CPC, narrow context hints, fast-loading mobile landers | CTR, CPA | US$10k-25k |
| App installs | Low | Treat as secondary; install attribution is not natively supported | Web-to-install rates, custom events | Experimental only |
| B2B demand generation | Low to medium while ads reach only Free and Go users | CPC or oCPC with a standard lead event, a custom audience of known prospects if the list clears 25,000, tight context hints | Demo requests, MQLs, SQLs, pipeline velocity | US$5k-15k as a qualification test; two B2B tests so far found the buyer on ad-free plans |
The pattern: ChatGPT Ads is best when the user is already in a research, comparison, or decision mindset and your offer can be expressed clearly in one short card pointing to a tightly relevant page. It is weakest when the buyer is a professional on a paid ChatGPT plan, or when scale, granular audience control, or mature attribution are the primary requirements; that work still belongs to a mature [Google Ads](/services/google-ads/) program. Google is running its own September version of this shift: Search campaigns with legacy match-type or asset settings begin auto-upgrading to AI Max, and the [Google AI Max Field Guide](/blog/google-ai-max-field-guide/) is this guide's companion volume, with the audit queries and readiness gates for that migration.
## Where the gaps are
Several capabilities planners reasonably expect from a mature ad platform are still not there: more than one self-serve creative format; demographic, lookalike, and site-retargeting controls; multi-day attribution windows and lift studies; native CRM, MMP, and CDP connectors; published vertical benchmarks; and any way to reach paid-plan users. Three gaps from the May list have closed since: custom audiences, sub-country geo targeting, and self-serve access outside the US.
OpenAI says it will keep adding "new formats, optimization tools, and measurement solutions," and the partner ecosystem (agency holdcos Dentsu, Omnicom, Publicis, WPP, Havas and MediaPlus, plus tech partners Adobe, Criteo, Kargo, Pacvue, and StackAdapt) is filling some of the operational gaps in the meantime.
## The bottom line for planners in August 2026
ChatGPT Ads in its current form is best understood as an assistant-adjacent contextual channel that sits closer to search-intent media than to social or programmatic display. It rewards specific, well-targeted consumer offers in categories where users actively research and compare. It is not yet a substitute for platforms that depend on rich audience controls, mature attribution, or large creative formats, and it cannot reach anyone on a paid ChatGPT plan, which for B2B is the buyer.
The practical posture is straightforward: treat ChatGPT Ads as an experimental line in the media plan rather than a core channel, scope budgets and KPIs accordingly, wire up the OAIQ pixel and Conversions API before the campaign exists so oCPC is available to you, confirm your robots.txt and edge bot-management rules allow OAI-AdsBot and OAI-SearchBot, check whether your buyer is on a paid plan before you spend a dollar, and watch for the European self-serve date and the first vertical benchmarks. Scoping a test like this, then keeping or killing it on the numbers, is exactly the kind of channel evaluation an [AI marketing](/services/ai-marketing/) program exists to run.
The platform is still being built in public. The honest read in August 2026 is that the buying and measurement stack has caught up with what planners need, and the audience has not: until paid-plan users are reachable, this is a consumer channel with B2B-shaped tooling.
## Sources checked for the August 2026 update
- [OpenAI, ChatGPT Ads expands across Europe (2026-08-18)](https://openai.com/index/chatgpt-ads-expands-across-europe/)
- [OpenAI Help Center, Ads in ChatGPT: The Basics](https://help.openai.com/en/articles/20001207-ads-in-chatgpt-the-basics), [Ads Manager Availability](https://help.openai.com/en/articles/20001245-ads-manager-availability), [Create Campaigns](https://help.openai.com/en/articles/20001210-create-campaigns-for-chatgpt), [Conversion-optimized Campaigns](https://help.openai.com/en/articles/20001412-conversion-optimized-campaigns), [Custom Audiences](https://help.openai.com/en/articles/20001346-set-up-custom-audiences-for-your-campaign), [Conversion Measurement](https://help.openai.com/en/articles/20001409-conversion-measurement), [Measure Results](https://help.openai.com/en/articles/20001214-measure-results), [FAQ](https://help.openai.com/en/articles/20001220-frequently-asked-questions)
- [OpenAI developer docs, Campaign Targeting](https://developers.openai.com/ads/campaign-targeting) and [Ad Policies](https://openai.com/policies/ad-policies/)
- [Digiday, OpenAI's ads business hits Europe at the six month mark (2026-08-19)](https://digiday.com/marketing/openais-ads-business-hits-europe-at-the-six-month-mark/)
- [MediaPost, ChatGPT Serves Ads In Results On Irrelevant Topics, Data Shows (2026-08-11)](https://www.mediapost.com/publications/article/417172/chatgpt-serves-ads-in-results-on-irrelevant-topics.html)
- Choice OMG OpenAI Ads account insights (campaign flight 2026-06-08 to 2026-06-25) and lead records
All external sources were scraped and checked on 2026-08-20.
If you want a straight read on whether your tracking, robots.txt, landing-page stack, and creative would actually hold up to a ChatGPT Ads test (and whether the channel fits your current media mix at all), we offer a no-obligation audit. You get a written findings document on what's working, what isn't, and what would actually move the number.
**[Request a free audit →](/contact/)**
For related reading, see [ChatGPT Ads Are Live: The AI Answer Is the New Ad Unit](/blog/chatgpt-ads-new-ad-unit/), [The AI Max Field Guide](/blog/google-ai-max-field-guide/), [The Google Ads Job Changed in 2026](/blog/google-ads-2026-operating-model-shift/), and our work on [AI marketing](/services/ai-marketing/) and [Google Ads management](/services/google-ads/).
---
## ChatGPT Ads Are Live: The AI Answer Is the New Ad Unit
On February 9, 2026, OpenAI put ads inside ChatGPT: sponsored placements below the answer, on Free and Go tiers only, with Plus, Pro, Business, and Enterprise staying clean. The launch was deliberately measured. That should not be confused with deliberately small. This is the most consequential shift in digital advertising since mobile, and the targeting signal (the user's full reasoning context, not a keyword) rewards a very different kind of agency than the last platform inflection rewarded.
**Quick reference: ChatGPT ads in 2026**
- **Launched:** February 9, 2026 in the United States
- **Where they appear:** Below the response in ChatGPT, clearly labeled as sponsored, visually separated from the answer
- **Who sees them:** Free and Go tier users; Plus, Pro, Business, Enterprise, and Education stay ad-free, as do under-18 accounts
- **Audience scale:** 900M+ weekly active users; 50M paying subscribers (late February 2026)
- **Pricing (April 2026):** ~$25 CPM and $3-$5 CPC, ~$50K minimum spend, down from $60 CPM and $200K-$250K minimum at launch
- **Reporting:** Aggregate impressions and clicks; no chat logs, no user-level data
- **Vs. Google:** AI Overviews already serves ads above, below, and within AI-generated answers, using both query and Overview content for relevance
- **Anthropic position:** Claude has publicly committed to staying ad-free
On February 9, 2026, OpenAI did the thing it spent two years saying it didn't want to do: it put ads inside ChatGPT.
The pilot is small. The format is conservative. Sponsored placements appear below the answer, clearly labeled, on the Free and Go tiers only. Plus, Pro, Business, and Enterprise stay clean. By every public measure, OpenAI has gone out of its way to make the launch feel measured, principled, and reversible.
Don't let the calmness of the rollout fool you. This is the most consequential shift in digital advertising since mobile, and most agencies haven't even started thinking about it.
I don't say that lightly. The agencies that figured out paid social in 2012 spent the next decade outpacing the ones that kept treating Facebook like a banner ad network. The ones that figured out programmatic in 2015 did the same thing to the agencies still trafficking IO-based display. There's now a third inflection point on the table, and the framing ("we'll wait until it matures") is the exact wrong instinct.
## What ChatGPT Ads Actually Are: Three Shifts Converging
Three things are converging, fast.
The first is that **the answer surface is now a media surface**. In its January 16, 2026 announcement, OpenAI described where ads would appear: "at the bottom of answers in ChatGPT when there's a relevant sponsored product or service based on your current conversation." That is a new kind of inventory: not a search results page, not a feed, not a banner, but a placement that fires after the user has already articulated their problem in natural language and received a tailored response. The targeting signal isn't a keyword. It's the entire reasoning context.
900M+ weekly active users; 50M paying subscribers on ChatGPT as of late February 2026; the answer surface OpenAI just opened to sponsored placementsSource: TechCrunch, "ChatGPT reaches 900M weekly active users," February 27, 2026
The second is that **Google has already crossed this line**. Per Google's own Ads help documentation, ads can serve above, below, and within AI Overviews, and "both the user query as well as the content of the AI Overview are considered when serving these ads." That's not a future capability. That's a live ad surface inside the answer most of your clients are competing to be cited in. We covered the operational implications of that shift in [The Google Ads Job Changed in 2026](/blog/google-ads-2026-operating-model-shift/).
The third is that **trust is volatile but not absent**. Gartner's 2025 consumer survey (377 U.S. consumers, fielded June-July 2025) found that 53% don't trust the reliability and impartiality of AI search summaries, and 61% wish they could turn AI summaries off entirely. But that same population is the one increasingly using AI to make purchase research decisions. The audience is skeptical, present, and forming habits at the exact moment the platforms are deciding what advertising in this format looks like.
53% distrust AI search summaries; 61% want to turn them off, and the same population is doing more purchase research inside AI tools than everSource: Gartner press release, "Gartner Survey Finds 53% of Consumers Distrust AI-Powered Search Results," September 3, 2025
That combination (massive new inventory, contextual targeting that goes deeper than keywords, and a skeptical audience whose trust patterns are still being set) is the entire opportunity, and the entire risk.
## The "Wait and See" Position Is More Expensive Than It Looks
I've heard the argument from other agency owners over the last three months: ChatGPT ads are limited, the categories are restricted, the reporting is thin, the CPMs are inflated, and there's no scalable buying interface yet, so why build for it now. The pricing trend argues against waiting.
The pricing tells a sharper version of the same story. The Feb 9 launch was CPM-only at roughly $60 per thousand impressions with a $200K-$250K minimum spend; an enterprise-tier pilot. Ten weeks later, by April, CPMs had eroded to around $25, OpenAI had added CPC bidding in the $3-$5 range, and the minimum had dropped to about $50K. The reporting advertisers receive is aggregate views and clicks: no chat logs, no user-level data, no rich attribution. By every traditional metric an agency uses to evaluate a media channel, this looks unfavorable.
$250K → $50K minimum spend in 10 weeks; CPMs from $60 to $25; CPC bidding added at $3-$5; the Feb 9 enterprise pilot was effectively a different product by AprilSource: PPC Land, "ChatGPT ad CPMs drop to $25," and Search Engine Journal, "ChatGPT Ads Now Offer CPC Bidding Between $3 And $5: Report," 2026
But evaluating that as a wait-and-see proposition is exactly the mistake. Anyone who waited "until pricing comes down" already missed the window where it did; the channel got 5× more accessible in ten weeks while their RFP was still circulating internally.
Three years ago, programmatic display was cheap, granular, and generated mountains of data. It also generated almost nothing in terms of buyer confidence at the bottom of a high-consideration funnel. Cookie loss, iOS signal degradation, and walled-garden attribution reform have made every dollar I spend on display feel less and less like a real read on customer intent.
Conversational ads invert that trade-off. The data is thin, but the **moment** is qualitatively different. An ad that arrives inside a research conversation (after the user has explained their actual problem in their actual words) is closer to a referral than a banner. The right question isn't "Is the CPC higher than display?" The right question is "Does this channel produce more confident downstream behavior (deeper research engagement, faster internal forwarding, earlier technical validation) than the channels I'm comparing it to?"
Most agencies aren't built to answer that question. That's the bigger problem than the channel itself.
## The Four Things Every Agency Should Be Doing Right Now
I'll be direct about what we're doing at Choice OMG and what I think the rest of the industry should be doing too.
**One: stop treating AI search and AI ads as separate problems.** They're the same problem. If a user asks ChatGPT about your client's category, the system pulls from public web content, structured information, brand mentions, and citation patterns to compose an answer. Then, increasingly, it serves an ad next to that answer. [SEO content strategy](/services/seo/) and paid AI strategy are now operationally linked. If your SEO team is optimizing for AI Overview citations and your paid team has never opened the ChatGPT ad pilot documentation, you have a strategy gap, not a tactical one. We track citation patterns across ten AI platforms for exactly this reason; see [We Track Your Business Across 10 AI Platforms](/blog/ai-platform-tracking/).
**Two: rewrite the copy rules.** A ChatGPT ad is not a Google search ad. The user has already been answered. Your ad lives in the cognitive moment after the answer, when the user is deciding what to actually do. "Book a Demo" doesn't work in that context. What works is a continuation of the reasoning: state the problem you solve, show one concrete piece of proof, offer a low-friction next step that doesn't feel like a sales handoff. OpenAI's published ad policies are explicit on this: ads must be clearly distinguishable from the ChatGPT product (no interface imitation), claims must be truthful (no exaggerated outcomes or false endorsements), and creative must be consistent end-to-end with the landing page. Vague superlatives and "looks like a citation" creative are wrong both strategically and from a policy standpoint. Winning this format means writing copy that reads like a useful next step, not a banner squeezed into a chatbot.
**Three: redesign your landing pages for proof, not capture.** The user clicking from a ChatGPT ad is further along in their thinking than a user clicking a paid search ad. They don't need a hero image and a form. They need to see whether you can actually do the thing you said you do. That means architecture pages, sample reports, technical walkthroughs, comparison documents: proof objects that reward the higher cognitive investment of the click. The "continue the reasoning" landing page is the design pattern that matches this channel, and it sits squarely inside [conversion optimization work](/services/conversion-optimization/), not paid-search creative production. Most landing pages built for paid search will underperform here, badly.
**Four: build first-party measurement, because the platform won't give it to you.** OpenAI gives advertisers aggregate views and clicks. That's it. If you want to know whether ChatGPT ads are producing higher-quality downstream behavior than display, you have to measure it yourself. That means matched-cell experiments (same offer, same audience definition, different traffic source) and a scorecard that captures things like proof-asset engagement, multi-stakeholder visit patterns, demo show rates, and time-to-technical-review. Click-through rate is the wrong KPI. Confidence-building behavior is the right one. If your agency can't run that experiment cleanly, you don't have a measurement function; you have a reporting function.
## The Honest Part Most Agencies Won't Say
Anthropic (the company behind Claude, the AI assistant our agency uses internally for production work) has publicly committed to keeping Claude ad-free, including a Super Bowl spot on February 4, 2026 with the tagline "Ads are coming to AI. But not to Claude." Their argument is that even clearly separated conversational ads create incentive misalignment in a product whose value depends on independent reasoning. That's a real philosophical position, and it's worth taking seriously rather than dismissing as marketing differentiation.
The honest read is that **both positions can be partially right**. OpenAI's case (that ads enable broader access to AI for users who won't or can't pay) is defensible. Anthropic's case (that mixing ads and conversational reasoning is a long-term trust hazard) is also defensible. The market is going to test both theories simultaneously, and the answer probably won't be clean.
But that uncertainty is exactly the wrong reason for an agency to do nothing. The reason to build capability now is that we don't know which version of this becomes the default, and the shops with real experiments behind them, real copy written for the format, and real measurement frameworks in place will be the ones whose clients win regardless of which platform model dominates.
Agencies that wait will be paying senior strategists to do basic catch-up work in 2027 that should have been done in 2026.
## Where ChatGPT Ads and the Wider AI Advertising Shift Are Heading
The framing I keep coming back to: in 2010, Google and Facebook were the only platforms most agencies had to think seriously about. That was a luxury. The next five years are going to fragment the answer surface across ChatGPT, Google AI Overviews, Perplexity, Claude, and whatever comes next, and each of those platforms will resolve the trust-vs-monetization tension differently. Some will go ad-heavy and lose user confidence. Some will stay clean and become premium media. Some will try a middle path and fail. We don't know which is which yet.
What we do know is that the agencies pretending this isn't happening will, in eighteen months, be having uncomfortable conversations with clients who are watching competitors show up in conversational answers they don't appear in.
I'd rather be the agency that learned this format while it was still shaped by user feedback than the one that learned it after it had hardened around someone else's playbook.
The age of AI answers is here. The age of AI advertising arrived in February 2026. Agencies that conflate the two are going to be expensive to catch up to; agencies that ignore both are going to be replaced.
Decide which you want to be.
## Frequently Asked Questions
**When did ChatGPT ads launch?**
OpenAI introduced sponsored placements inside ChatGPT on February 9, 2026, in the United States. Ads appear below the response, are clearly labeled as sponsored, and are visually separated from ChatGPT's answer.
**Which ChatGPT subscription tiers see ads?**
Ads appear only on the Free and Go tiers. Plus, Pro, Business, Enterprise, and Education subscriptions stay ad-free. OpenAI also blocks ads for accounts where users have identified as under 18 or where the system predicts an underage user.
**How much do ChatGPT ads cost in 2026?**
Pricing has moved fast. The February launch was CPM-only at roughly $60 per thousand impressions with a $200,000-$250,000 minimum advertiser commitment; effectively an enterprise-tier pilot. By April 2026, CPMs had dropped to around $25, OpenAI had introduced CPC bidding in the $3-$5 range, and the minimum spend had fallen to about $50,000.
**Can my business advertise on ChatGPT?**
If your category is permitted under OpenAI's ad policies and you can meet the current minimum spend, yes. The lowered $50K threshold opens the format to mid-market advertisers, not just the launch-partner tier (Target, Adobe, Williams-Sonoma, Albertsons). Creative must comply with OpenAI's published ad policies on sponsored disclosure, accuracy, interface separation, and landing-page consistency.
**Are AI Overviews ads the same as ChatGPT ads?**
No. Google AI Overviews ads have been live longer and serve above, below, or within Google's AI-generated overview answers, using both the user query and the AI Overview content for relevance. ChatGPT ads are a separate inventory inside OpenAI's product, with different creative requirements, a different bid model, and different reporting. Both are conversational placements, but the buying interfaces and audiences are distinct.
**Will Claude (Anthropic) ever have ads?**
Anthropic says no: Claude stays ad-free, a stance it reinforced with a February 4, 2026 Super Bowl spot carrying the tagline "Ads are coming to AI. But not to Claude." The company's stated rationale is that ad-supported business models create incentive misalignment in a product whose value depends on independent reasoning. That position could change, but it has been stated explicitly and recently.
If you want a straight read on whether your current agency is treating AI search and AI advertising as the same problem (or whether your tracking, creative, and landing-page stack would actually hold up to a conversational-ad click), we offer a no-obligation audit. You get a written findings document on what's working, what isn't, and what would actually move the number.
**[Request a free audit →](/contact/)**
For related reading, see our work on [AI marketing](/services/ai-marketing/), [Google Ads management](/services/google-ads/), [The Google Ads Job Changed in 2026](/blog/google-ads-2026-operating-model-shift/), and [We Track Your Business Across 10 AI Platforms](/blog/ai-platform-tracking/).
**References:** OpenAI, [*Testing ads in ChatGPT*](https://openai.com/index/testing-ads-in-chatgpt/) and [*Ad Policies*](https://openai.com/policies/ad-policies/). TechCrunch, [*ChatGPT rolls out ads*](https://techcrunch.com/2026/02/09/chatgpt-rolls-out-ads/) (Feb 9, 2026) and [*ChatGPT reaches 900M weekly active users*](https://techcrunch.com/2026/02/27/chatgpt-reaches-900m-weekly-active-users/) (Feb 27, 2026). Google Ads Help, [*About ads and AI Overviews*](https://support.google.com/google-ads/answer/16297775?hl=en). Gartner, [*53% of Consumers Distrust AI-Powered Search Results*](https://www.gartner.com/en/newsroom/press-releases/2025-09-03-gartner-survey-finds-53-percent-of-consumers-distrust-ai-powered-search-results0) (Sept 3, 2025). Search Engine Journal, [*ChatGPT Ads Now Offer CPC Bidding Between $3 And $5: Report*](https://www.searchenginejournal.com/chatgpt-ads-now-offer-cpc-bidding-between-3-and-5-report/572652/). PPC Land, [*ChatGPT ad CPMs drop to $25*](https://ppc.land/chatgpt-ad-cpms-drop-to-25-as-openai-races-toward-global-auction/). The Register, [*Anthropic keeps Claude ad-free*](https://www.theregister.com/2026/02/04/anthropic_no_advertising_in_claude/).
---
## 7 Red Flags When Hiring an Edmonton Digital Marketing Agency (And What Actually Matters Instead)
Most agencies look at your account when it's time to write the monthly report. By then the month is over: the ad spend is gone, the tracking has been broken for weeks, the competitor has already moved. The seven red flags below are all the same problem wearing different clothes: agencies that report instead of monitor. What that distinction looks like in practice, and what to ask before you sign anything, follows.
Most "how to choose a marketing agency" articles treat this like a shopping decision. Look for experience. Ask about their process. Check their reviews.
That advice is useless because every agency in Edmonton already knows how to pass those tests. They'll show you case studies, quote you a clean process, and point to five-star reviews from clients who can't actually tell if the work is any good.
The real question isn't *who looks good in a sales meeting*. It's this: **when something breaks in your marketing (your tracking fails on a Tuesday, your ad budget overspends by 40% on a Saturday, a competitor launches a price drop on a Wednesday), will your agency know before you do?**
Most won't. Not because they don't care, but because they aren't watching: the account only gets opened once it's time to write the report, and by then the month is over.
After 15+ years running [Choice OMG](/) and auditing the ad accounts, analytics setups, and technical SEO work of agencies across Western Canada, we've seen the same patterns repeat. Below are the seven red flags that reliably predict a bad engagement, and what competent, systems-driven work looks like instead.
## The Short Version
If you don't have time to read the whole article, this is the compressed version of what separates good Edmonton agencies from bad ones:
- **The best agencies monitor. The worst agencies report.** Problems get caught in hours, not at the end of the month.
- **Your tracking either works or it doesn't.** If the agency can't show you your conversion setup live, on a screen share, in five minutes, it probably doesn't work.
- **Flat fees beat percentage-of-spend.** Agencies paid a cut of your ad budget are structurally incentivized to grow your spend, not your results.
- **The person in your meeting should be the person in your account.** If every technical question gets "I'll check with the team," you're paying for a middleman.
- **Vanity metrics mean the business numbers aren't there.** Reports that lead with impressions and rankings are hiding the leads and revenue that didn't show up.
The rest of this article explains why, with specific red flags and what to look for instead.
## Red Flag #1: They Can't Explain What They're Tracking (Or There's Nothing To Track)
The single most common failure we see when a business comes to us from a previous agency: **there is no functioning measurement setup.**
Not "the analytics could be better." Not "the attribution is imperfect." We mean:
- GA4 installed but with no conversion events configured
- Google Ads running with no conversion import from GA4, or conversions double-counted across platforms
- Form submissions that don't fire any event at all
- Phone calls that are the primary lead source, with zero call tracking in place
- Enhanced conversions disabled, meaning the ad platform is flying blind on match rates
If your agency can't tell you, in one sentence, exactly how a lead is attributed from first click to qualified inquiry, they are guessing. Every report they send you is fiction dressed up as data.
**What to look for instead:** Ask them to walk you through your conversion setup on a screen share. A competent agency can show you the events firing in GA4 DebugView, the conversion actions in Google Ads, and the call tracking integration within five minutes. If they need to "get back to you," the answer is that nobody on the team actually knows.
At Choice OMG, tracking health is one of the things our automated systems verify daily across every client site, because a tracking setup that worked when it was built is not the same as a tracking setup that still works today. We've written about how [conversion tracking breaks silently](/blog/conversion-tracking-breaks/) if nothing is watching for the drift.
## Red Flag #2: Nobody Is Watching Your Ad Spend Between Reports
Here is a scenario we have cleaned up more than once: a Google Ads account is set to a $5,000 monthly budget. On day 22 of the month, spend is already at $6,800. The agency notices during the monthly review on day 5 of the following month, eleven days after the overspend started.
The agency apologizes, credits some of the management fee, and promises it won't happen again. But the overspend itself is gone. That money was spent on clicks that weren't planned for and weren't optimized toward.
This isn't rare. It's the default when nobody has an automated check running against the account.
Every 30 minutes budget pacing is verified across all managed Google Ads accounts: 48 checks per account per day, not once a monthSource: Choice OMG budget monitoring pipeline
Most agencies review your ad spend once a month. We verify it every 30 minutes. If spend crosses 110% of monthly budget across any of the Google Ads accounts we manage, an alert fires and someone is looking at the account within the hour, not within the next reporting cycle.
**What to look for instead:** Ask the agency what their automated alerting looks like on your ad spend. The answer should involve a specific frequency ("we check every X") and a specific threshold ("the alert fires when spend exceeds Y"). If the answer is that they "keep an eye on it" or "review it weekly," you are buying weekly attention for a system that can go wrong by the hour.
## Red Flag #3: The Google Ads Account Looks Like It Was Set Up Once and Forgotten
We audit Edmonton Google Ads accounts regularly, and the pattern is so consistent it's almost a signature:
- Broad match keywords running without a meaningful negative keyword list
- Search terms report showing the account paying for clicks on wildly irrelevant queries (we've seen law firms paying for "free legal advice" clicks for months)
- No negative keyword list shared at the account level
- Ad schedules that don't match when the business actually converts
- Location targeting set to "presence or interest" instead of "presence," which in Edmonton means you're paying for clicks from people searching about Edmonton from anywhere in the world
- Single ad groups containing 40+ keywords with one generic ad
This isn't a "Google Ads is hard" problem. It's a "nobody is logging into this account" problem.
**What to look for instead:** Ask to see the search terms report from the last 30 days and the negative keyword list. An account under active management has a negative keyword list that grows weekly. An abandoned account has the defaults from the day it was built.
*Notice the pattern so far? Broken tracking. Unwatched spend. Dormant ad accounts. These aren't three different problems; they're three symptoms of the same one. We'll name it explicitly later in the article. First, four more red flags that all trace back to the same root cause.*
## Red Flag #4: Locked-In Contracts and Percentage-Of-Spend Billing
Two of the oldest agency-protection mechanisms in the industry are still going strong: the 12-month lock-in contract, and the percentage-of-spend fee structure.
The lock-in contract exists for exactly one reason: to make it expensive to leave when the work isn't working. If we lock the client in for a year, we don't have to be good; we just have to be good *enough that leaving feels like more work than staying*.
The percentage-of-spend model is worse. It pays the agency more when you spend more. The incentive is misaligned from the first month. An agency earning 15% of ad spend has a structural reason to push you toward a $10,000 budget when a $4,000 budget would have delivered the same result. They aren't necessarily being dishonest. They are responding rationally to how they get paid.
**What to look for instead:** Flat monthly fees. Month-to-month or clearly-defined performance exit clauses. An agency whose revenue goes up when *your results* go up, not when *your spend* goes up. Choice OMG has operated on flat-fee, no-ad-spend-percentage engagements since 2010, because the alternative structures reward the wrong behaviour. We wrote up the incentive math in more detail in [Why We Don't Charge a Percentage of Ad Spend](/blog/why-flat-fees/).
## Red Flag #5: Your Account Manager Can't Answer Technical Questions
This is the tell that separates agencies that *do* technical work from agencies that *resell* technical work.
Ask your account manager:
- "Can you walk me through what schema markup is on our homepage right now?"
- "What's our Core Web Vitals score and what's causing the LCP issue?"
- "Why did organic traffic drop 14% in October; was that a core update or a site change?"
- "What negative keywords did you add last month?"
If the answer is always "let me check with the team and get back to you," you are paying account-management markup on work being done by someone who is not in the meeting. That's fine if the work is good. It's a disaster if the account manager can't evaluate whether the work is good, because they become a telephone game between you and whoever is actually touching the account.
**What to look for instead:** An agency small enough that the person on your call is also the person in your account. Choice OMG is built this way deliberately: a 12-person specialist team instead of a 200-person generalist shop. You don't need your account manager to be a developer, but they need to be technically literate enough to open DevTools, pull up GA4, or log into Google Ads and answer the question in real time.
## Red Flag #6: They Report on Vanity Metrics Instead of Business Outcomes
Impressions are up 40%. Click-through rate improved. You're ranking #3 for a keyword.
None of these things are business outcomes. They are intermediate metrics that *might* correlate with business outcomes, if the rest of the funnel is working. Agencies lean on them when the business outcomes aren't there to report.
The honest report answers one question: **did the marketing spend produce more qualified leads or revenue than it cost?**
Everything else is context that helps explain the answer. If your monthly report leads with impressions and rankings, and you have to dig to find lead volume or revenue, the agency is managing your perception, not your pipeline.
**What to look for instead:** Reports that lead with leads, qualified leads, pipeline value, or revenue (whichever is measurable in your business), and use the intermediate metrics (traffic, rankings, CTR) to explain *why* the business number moved. For high-value procedure practices like dental implants or elective medical, where a single converted lead can be worth $20,000 or more, reporting that doesn't close the loop to booked consultations is essentially decorative. See our write-up on [high-value procedure campaigns](/blog/high-value-procedure-campaigns/) for the full argument on lead-quality reporting.
## Red Flag #7: No Real Technical SEO Work, Just "Content and Links"
There's a whole tier of agencies whose entire SEO offering is:
1. Write a blog post per month
2. Buy some backlinks from a vendor
3. Install Yoast
That's not SEO. That's content marketing with a plugin.
Real technical SEO in 2026 includes:
- Schema markup beyond what Yoast generates out of the box: LocalBusiness with proper geo data, Service schema for each core offering, FAQ schema on relevant pages, AggregateRating where legitimately applicable
- Core Web Vitals work that actually moves the numbers, not just a plugin that claims to
- Daily rank tracking at scale, not monthly spot-checks on five keywords, but position tracking across the full keyword set that actually reflects the business (we track 1,000+ keyword positions daily across our client base)
- Daily automated site health checks: fatal errors, broken CSS, broken images, JavaScript crashes, failed network requests, cache misconfiguration, navigation accessibility, visual regressions. A WordPress update on Tuesday can silently break your homepage, and you won't know until someone complains
- Proper canonical and hreflang setup if applicable
- Internal linking structure built around topic clusters, not just "related posts" widgets
- AI search visibility tracking across Google AI Overviews, ChatGPT, Perplexity, Gemini, and Copilot, where an increasing share of buyer research is happening
If your agency's SEO work is invisible to you (you never see code changes, schema updates, or technical audits), it's because there isn't any happening. Content alone has not been a complete SEO strategy since approximately 2018.
**What to look for instead:** Ask to see the last three technical changes they made to your site. Real answers sound like "we added Service schema to the five core service pages last week; the validator output is attached, along with the custom mu-plugin that generates it." Vague answers sound like "we've been optimizing the site." Related: [We Track Your Business Across 10 AI Platforms](/blog/ai-platform-tracking/).
## The Common Thread: Monitoring vs. Reporting
Go back and re-read the seven red flags. They're all the same problem wearing different clothes.
Broken tracking, overspent budgets, abandoned ad accounts, vanity metric reports, invisible SEO work: each of these is a symptom of an agency that *looks at your account when it's time to write the report*. By the time a monthly report shows a problem, the month is already over. You've already lost the money, missed the leads, or handed the market to a competitor who was paying closer attention.
Our approach is structurally different, and the contrast is stated plainly below:
- **Most agencies check your Google Ads account once a month. We check every 30 minutes.**
- **Most agencies look at your website when something's obviously broken. We run automated health checks every day across eight failure categories.**
- **Most agencies track a handful of rankings quarterly. We track 1,000+ keyword positions daily.**
- **Most agencies wait for you to notice a problem. We monitor 60,000+ data points a day so we see it first.**
60,000+ data points monitored daily across the Choice OMG client base; the infrastructure that lets us catch problems in hours, not at month-endSource: How We Monitor 60,000 Data Points a Day
Other agencies will show you a dashboard. We built the system that feeds the dashboard, catches problems before they show up on a dashboard, and alerts the team the moment something breaks. That's the difference between monitoring and reporting, and it's the thing no other agency at this size and price point can match.
## Real Examples
**A US-based dental practice focused on implant surgery.** When they came to us, their Google Ads were running but the conversion tracking treated any contact-page view as a conversion, not actual consultation requests. The ad platform was optimizing for people who *looked at* the contact page, not people who *booked consultations*. Nobody was tracking phone calls, and phone was how most new patients actually inquired.
We rebuilt the measurement layer from the ground up: proper GA4 events, real conversion imports into Google Ads, dynamic call tracking, enhanced conversions. We reworked the negative keyword strategy against 12 months of search term data, added Service and FAQ schema across the procedure pages, and set up daily automated checks so tracking drift would surface immediately.
Over the following year, monthly implant surgery revenue moved from roughly $300,000 to $800,000. We did not invent a new channel or multiply the ad budget. We fixed the instrumentation, plugged the leaks, and made sure nothing silently broke without someone on our team knowing about it within the hour.
**A multi-location optometry group in Alberta.** The business operated three clinics and wanted to grow, but their previous agency's reporting made it nearly impossible to tell which locations, services, and campaigns were actually driving new patient bookings. They were spending on Google Ads across all three locations without any attribution granularity.
We restructured the accounts for per-location attribution, built daily monitoring into every campaign, implemented call tracking with location-level number routing, and set up reporting that tied ad spend to booked eye exams at each specific clinic. Over the next two years, they expanded from three clinics to six while reducing their overall patient acquisition cost by roughly 30%.
Again, no magic. The growth came from being able to see what was working at which location, and reallocating in weeks instead of quarters. We've written up the playbook for this kind of expansion in [Scaling Multi-Location Healthcare](/blog/scaling-multi-location-healthcare/).
## What Actually Matters
If you read this article looking for a list of what to look for in an Edmonton agency, this is the short version:
**Infrastructure you can verify.** Is someone, or some system, actually watching your campaigns between reports? How often? What triggers an alert?
**Measurement you can trust.** Is the conversion setup correct? Do the reports lead with business outcomes, not vanity metrics?
**Incentive alignment.** Flat fees instead of percentage-of-spend. Month-to-month or clear performance terms instead of lock-in.
**Specialists, not middlemen.** The person in your meeting should be able to answer technical questions about your account without "checking with the team."
None of this is about whether an agency is cheap or expensive. It's about whether the spend is being managed by people and systems that are actually watching.
A note on why I think this framing matters. I spent 22 years in the Canadian Armed Forces Reserve, 18 of those as an instructor teaching disciplines that ranged from psychological operations to cyber. Those two fields map almost perfectly onto the two halves of modern digital marketing. Psyops is the study of how audiences form beliefs and take action: the persuasion layer. Cyber is the infrastructure layer, the systems and signals and verification. Most agencies are built around one half or the other: marketers who don't really understand the systems, or developers who don't really understand persuasion. The work only holds up when both halves are taken seriously, and when someone on the team is watching both of them every day.
## Before You Sign Anything
A short checklist you can use in your next agency conversation:
1. Ask them to screen-share your GA4 and walk you through the conversion events that are firing.
2. Ask how frequently your ad spend is monitored automatically, and at what threshold an alert fires.
3. Ask to see the last 30 days of search terms from your Google Ads account, and the account-level negative keyword list.
4. Ask what schema markup exists on your site right now, and request the validator output.
5. Ask whether the contract is flat-fee or percentage-of-spend, and whether it's month-to-month.
6. Ask the account manager to answer one technical question about your account without "checking with the team."
7. Ask what their last three technical changes to your site were, specifically.
If an agency passes all seven, they're worth a serious conversation. If they fail three or more, you already have your answer.
## Frequently Asked Questions
**What does a digital marketing agency in Edmonton cost?**
Honest answer: it varies more by *what you're buying* than by *who you're buying it from*. A freelancer running your Google Ads part-time costs less than a specialist team with automated monitoring, daily site health checks, and a data warehouse tracking your keyword positions, but you're also buying a fundamentally different product. The more useful question is what a missed month costs you. If your tracking breaks in week one and nobody notices until the monthly report in week five, that's a full month of ad spend optimized against bad data. That's almost always more expensive than the management fee difference between a cheap option and a competent one.
**Is it better to hire a local Edmonton agency or go remote?**
It depends on the channel. For Google Ads, technical SEO, and web optimization, geography is largely irrelevant; the work is remote-native and the results don't care where the account manager's desk is. Local matters more when the channel involves on-the-ground knowledge: local media buying, in-person photo or video production, networking with Edmonton-specific business communities. For most SMBs, the real question isn't local vs. remote. It's whether the people running your account actually understand the technical work, regardless of where they're based.
**How long before I see results from SEO or Google Ads?**
Google Ads: you'll see traffic and leads within the first week. You'll see whether the campaigns are *profitable* after roughly 60-90 days, because that's how long it takes to collect enough conversion data to optimize intelligently. Any agency that promises profitability in week one is guessing.
SEO: typically 4-6 months for meaningful organic traffic movement on a site that already has some authority, and 9-12 months on a newer site. Anyone promising first-page rankings in 30 days is either targeting keywords nobody searches, or lying.
**How do I know if my current agency is actually doing the work?**
Three questions will answer it. First, ask them to screen-share your Google Ads search terms report and show you the negative keywords they've added in the last 30 days. Second, ask them what schema markup is currently on your homepage. Third, ask what changed in your GA4 configuration since they took over the account. An agency doing the work can answer all three in the call. An agency collecting a retainer without doing the work can't.
**What should I do if I think my current agency is underperforming?**
Don't cancel first; audit first. Get an independent review of your tracking setup, your Google Ads account health, and your technical SEO. You need to know whether the problem is the agency's execution, the original setup they inherited, or a strategy mismatch. Cancelling a mediocre agency and hiring another one without understanding the underlying issues usually produces the same result twelve months later.
## Before You Keep Paying Your Current Agency Another Month
If you read this article and recognized your current setup in more than a couple of the red flags, you have three options: hope it sorts itself out, start a painful vendor-switch process, or get a straight second opinion first.
We offer a no-obligation audit covering the things this article actually measures: your GA4 and conversion tracking, Google Ads account health, technical SEO and schema markup, and whether anything is being monitored between reports. You get a written findings document. We tell you what's working, what isn't, and what would actually move the number. If the answer is "your current agency is doing fine, stay where you are", we'll tell you that too.
**[Request a free audit →](/contact/)**
For related reading, see our pieces on [Why We Don't Charge a Percentage of Ad Spend](/blog/why-flat-fees/), [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/), and [Conversion Tracking Breaks Silently](/blog/conversion-tracking-breaks/). To go deeper on what we actually do, see our [Edmonton Google Ads practice](/edmonton/google-ads/) and [SEO services](/services/seo/).
---
## The Google Ads Job Changed in 2026: What We Rebuilt Across 24 Accounts
Between 2025 and 2026, Google stopped shipping advertisers a toolkit and started shipping an operating system. The quiet commercial changes (the March 2026 ad-schedule pacing rewrite, the end of call ads, the forced September 2026 DSA migration) will reshape Canadian SMB budgets before any AI-Overview headline does. We rebuilt the operating model across 24 accounts in response.
## The Headline Everyone Wrote vs. the Story That Actually Matters
The coverage of Google Marketing Live 2025 and the twelve months that followed was mostly about the "Power Pack", Google's name for Demand Gen, AI Max for Search, and Performance Max working as a single AI-led system. Every agency blog in Canada wrote some version of "everything you need to know about the Power Pack."
That coverage is accurate but incomplete for a Western Canadian HVAC company, a Spruce Grove law firm, or a three-location dental group. The Power Pack is real, and we will get to the independent data on it below. But three smaller, quieter changes Google shipped between late 2025 and April 2026 are more likely to reshape your next invoice than anything the AI press release promised.
Those three changes are the March 1, 2026 ad-schedule budget pacing rewrite, the deprecation of call ads, and the April 15 announcement that Dynamic Search Ads will be auto-upgraded into AI Max starting September 2026. Each change is individually small. Together, they change how you budget, how you generate phone leads, and how you scope AI-led expansion.
This post walks through what each of those changes actually does, what the independent data says about Google's AI narrative, and the operational adjustments we made across our portfolio so the changes became our own decisions instead of Google's.
## The March 2026 Budget Trap
On March 1, 2026, Google changed how budget pacing works for any campaign that uses ad scheduling. The headline spending limits are unchanged: still up to 2x the average daily budget on a single day, still up to 30.4x the daily budget in a month. What changed is that campaigns are now pacing proactively toward the full 30.4x monthly cap inside whatever schedule you have set, regardless of how many days that schedule actually runs.
The math matters more than the language. Take an Edmonton HVAC account running Monday to Friday at $100 per day. Before March, that campaign behaved roughly like a $2,200-per-month campaign: five days a week at the daily target. After March, the same campaign is now allowed to pace toward the full $3,040 monthly envelope, concentrated into those same five days. An office-hours B2B campaign scheduled Monday to Thursday at $100 per day jumps from about $1,700 to roughly $3,040. A weekends-only campaign at $100 per day moves from about $800 to around $1,600, constrained by the 2x daily cap rather than the monthly one.
Up to 38% additional monthly spend on an existing Mon-Fri campaign with no account changesSource: Choice OMG portfolio math against Google's 30.4x monthly spending limit, post-March 2026
Nothing changed in the account. No new campaign, no budget edit, no strategy change. The client just spent more.
The mitigation is mechanical. If monthly budget is the actual business constraint, set daily budget to monthly target divided by 30.4 and stop using ad scheduling as a soft brake. Where a campaign is genuinely time-bound, such as a spring paving push or a one-week promotion, campaign total budgets are the cleaner tool because they cap the full campaign duration rather than relying on averaged daily logic. The catch is that campaign total budgets are only available on new campaigns and cannot be retrofitted onto existing ones. Deciding which campaigns to rebuild versus which to reset daily budgets on is itself a scoped piece of operational work, and skipping it is how accounts quietly start overspending.
## Call Ads Are Gone. Your Intake Probably Noticed.
Google announced in October 2025 that call ads were being deprecated. The ability to create new call ads was removed in February 2026. Existing call ads are scheduled to stop receiving impressions in February 2027. The replacement is a standard responsive search ad with call assets attached.
Practitioner reports in March and April suggest the UI rollout has been inconsistent, with some accounts temporarily regaining the ability to create or edit call ads; the direction is not in doubt, even where the operational timeline still varies account to account.
Call ads were mobile-only and explicitly designed to drive a phone call as the primary response. For phone-led verticals (HVAC, plumbing, restoration, legal, automotive service, medical) that format was doing real work. Responsive search ads with call assets preserve the ability to call, but the ad surface is wider, the landing page matters more, and the asset mix shifts clicks toward the website as well as the phone.
What that does to lead mix is predictable. A plumbing account that was previously getting 70% phone calls and 30% form submissions can find itself at 55/45 or 50/50 within a few weeks of the transition, with total lead volume flat or slightly up. Cost per lead does not necessarily change. Intake economics might. A phone-led business that trained its front office to close on the call now has more form submissions landing in an inbox that was an afterthought.
We treat the call-ad transition as an intake operations project, not a media change. Conversion reporting gets split so phone-call conversions and form-fill conversions track separately. The CRM or intake system gets a usable form-follow-up workflow. Landing pages get click-to-call buttons treated as primary, not secondary. Only then is the RSA plus call-asset replacement a clean swap. Clients who skipped the intake work and just changed the ad format saw the same lead count and worse conversion to booked work, because the form submissions were queueing up behind a process that was never built for them.
## DSA Gets Auto-Upgraded to AI Max in September
On April 15, 2026, Google confirmed that campaigns using Dynamic Search Ads, automatically created assets, and campaign-level broad match settings will begin auto-upgrading to AI Max in September 2026. The upgrades are expected to conclude by the end of that month. New DSA campaign creation is being wound down in parallel.
For mature accounts, this is a bigger operational event than the announcement suggests. DSA was, for many advertisers, a controlled long-tail catch-all that ran alongside a disciplined keyword structure. It filled the gaps between the exact-match queries the planner had accounted for and the real variation in how people searched. AI Max is a different animal. It expands queries more aggressively, layers creative automation on top, and is built to find conversions outside of whatever keyword scaffolding you have erected.
September 2026: Google's stated window to auto-upgrade DSA, campaign-level broad match, and auto-created assets into AI MaxSource: Google Ads Blog, "We're upgrading Dynamic Search Ads to AI Max," April 15, 2026
Being migrated involuntarily into a more expansionist system is not the same as running a controlled AI Max test on your own schedule. The advertisers who will do well with the migration are the ones who ran AI Max as an opt-in experiment earlier, measured it against qualified-lead outcomes rather than topline click or conversion counts, and have a view on whether the expansion is incremental to their existing Search coverage or substitutional. The advertisers who will do badly are the ones who find out in late September.
The operating manual for that decision is our [AI Max Field Guide](/blog/google-ai-max-field-guide/): paste-ready audit queries, seven readiness gates, and a scorecard for deciding campaign by campaign. The product mechanics, cohort defaults, and opt-out paths are documented in the [verified dossier on the September auto-upgrade](/research/google-ai-max-auto-upgrade/), and the results of running that audit across our own portfolio are in [We Audited 19 Google Ads Accounts for September's AI Max Auto-Upgrade](/blog/ai-max-september-audit/).
## The Power Pack Lift Numbers, Honestly Read
Google's own performance claims for the Power Pack are strong, specific, and mostly sourced from Google's internal data. AI Max typically produces 14% more conversions or conversion value at a similar CPA or ROAS; for non-retail campaigns still dominated by exact and phrase match, the figure rises to 27%. Performance Max users outside retail see an average 27% lift. Demand Gen was reported to deliver a 26% increase in conversions per dollar in 2025. Smart Bidding Exploration averaged 18% more unique converting search categories and 19% more conversions.
Those are useful directional signals. They are not a clean, like-for-like proof that the Power Pack outperforms a well-built legacy account in every vertical.
The most useful independent pushback came from Mike Ryan's analysis at Smarter Ecommerce, summarized by Search Engine Journal, covering more than 250 campaigns that adopted AI Max. Across that set, the median campaign gained 13% in conversion value, close to Google's claim. The median campaign also gained 16% in CPA. ROAS outcomes were dispersed enough that individual campaigns ranged from 42% above baseline to 35% below it.
+13% conversion value, +16% CPA, ROAS range +42% to -35% across 250+ independent AI Max campaignsSource: Search Engine Journal summary of Smarter Ecommerce analysis, 2026
Read carefully, that data describes AI Max as a volume-expansion layer rather than an efficiency improvement. Revenue grows, the marginal conversion costs more, and whether the total is a win depends on your margin structure and how rigorously you measure lead quality.
| Source | Conversion value | CPA | Notes |
|---|---|---|---|
| Google, AI Max launch (May 2025) | +14% | similar | Excludes retail |
| Google, AI Max (April 2026) | +7% | similar | Full feature suite vs. search-term matching alone |
| Google, Performance Max | +27% | similar | Non-retail |
| Google, Demand Gen 2025 | +26% per dollar | n/a | Internal year-end summary |
| SMEC independent, 250+ campaigns | +13% median | +16% median | ROAS range +42% to -35% |
This is not a refutation of Google's narrative. It is a qualification. For a retail advertiser on 40% gross margin, 13% more revenue at 16% higher CPA is probably fine. For a lead-generation account where the cost of a bad lead is not just wasted ad spend but wasted intake time, the same numbers are not fine.
## The Canadian Wrinkle
Ads within AI Overviews have been live in English in Canada across mobile and desktop since the 2025 expansion. Ads above and below AI Overviews run in every market where AI Overviews themselves are available. That means AI-mediated search is already a live operating environment for Canadian advertisers.
Two caveats matter for the kind of portfolio we run. First, Google excludes sensitive verticals, explicitly including finance and healthcare, from ads inside AI Overviews. For dental practices, optometry clinics, medical specialists, and financial advisors, that exclusion is not cosmetic. It means AI Overview inventory is not available to those accounts on the same terms as a paving contractor or a home-services business, and the generic "get into AI search" marketing narrative does not map cleanly onto their account.
Second, the old exact-match mental model no longer reaches all of the inventory. Google has clarified that exact and phrase match keywords are not eligible to trigger ads within AI Overviews. The match types that can trigger those placements are broad match, AI Max, Performance Max, Shopping, and DSA. Exact-match discipline is still useful for cost control and quality assurance. It is no longer sufficient on its own to access every valuable Google surface.
The practical implication is that a Canadian SMB account in 2026 needs a deliberate view on which match-type layers it runs, which AI-eligible layers it has explicitly tested, and which layers it has explicitly declined. "Default settings" is no longer a stable posture.
## What the New Advertiser Job Looks Like
Put the three quiet changes and the Power Pack context together and the outline of the new advertiser job resolves. The scarce skill is no longer adjusting hundreds of bids or splitting match types into ever-finer ad groups. Google's AI is going to do that work, well or badly, with or without you.
What Google's AI cannot do on its own is define what a good conversion actually looks like for your business. It cannot import qualified-lead or revenue signals from a CRM you have not connected. It cannot tell whether a cheap conversion is a form fill from a real prospect or a returning customer who would have called anyway. It cannot structure budgets across Search, AI Max, Performance Max, and Demand Gen so those campaigns stop bidding against each other. It cannot feed itself higher-quality creative, better landing pages, or cleaner offline value signals.
Those are the jobs that actually move the numbers in 2026. Clean conversion actions. Offline value imports. Budget architecture that respects campaign boundaries. Structured creative and landing-page pipelines. Regular review of the channel-performance and asset-level reports Google added under advertiser pressure. Experimentation discipline that lets you test AI-led features on your own terms instead of inheriting their rollout.
The change is not from tactical to passive. It is from tactical to strategic. The agencies that understood that shift by mid-2026 are running portfolios that look operationally different from the ones that did not. That's where we have pointed the practice.
## What We Changed Across the Portfolio
Across our active Google Ads accounts, the shift looked like a set of concrete, documented operational changes rather than a single strategy pivot, mechanical work executed account by account.
**Budget recalibration.** Every ad-scheduled campaign was audited against true monthly spend intent. Where ad scheduling was being used as a soft brake (which, historically, it was on roughly half of the affected campaigns) daily budgets were reset to monthly target divided by 30.4 and ad scheduling was either removed or preserved only as a genuine day-part lever. For a handful of genuinely time-bound pushes, the legacy campaign was replaced with a new campaign using a total budget cap.
**Call-ad migration with split reporting.** For every phone-led account, call ads were replaced with responsive search ads plus call assets before the February 2027 impression sunset rather than at the deadline. Conversion tracking was split so phone-call conversions and form-fill conversions reported separately. Intake workflows were updated so form submissions stopped being an afterthought inbox.
**Opt-in AI Max testing, on our own timeline.** For accounts with enough conversion volume to produce a readable signal, AI Max was turned on inside a dedicated test campaign with explicit guardrails: brand exclusions, location intent controls, an experiment window, and a lead-quality criterion more strict than Google Ads' default. The point was to enter September 2026 with our own data on whether AI Max expansion was incremental or substitutional, not Google's.
**Tighter conversion-action hygiene.** Every account's conversion configuration was reviewed for duplicate actions, mis-scoped primary/secondary flags, and stale offline imports. Smart Bidding only performs as well as what you let it optimize toward, and no amount of AI can fix a quiet tracking break from the inside, a recurring theme in our operations work we wrote up separately in [Conversion Tracking Breaks Silently](/blog/conversion-tracking-breaks/).
**Weekly ops added channel and asset reports.** Performance Max channel performance reports and the new asset-level reports were added to the standing weekly review, alongside the Search-term and placement reviews we already ran. The reports exist because advertisers pushed Google for them. Using them is how you get the value they were built to deliver.
## The Short Version
The tactical advertiser's edge is shrinking. The strategic advertiser's edge is growing. The agencies winning in 2026 are not the ones that surrendered control to Google's AI fastest, and they are not the ones that clung hardest to exact-match nostalgia. They are the ones that accepted where the platform was going, then built stronger measurement, cleaner budget architecture, better creative feedstock, and tighter lead-quality feedback loops than their competitors.
Read more about our [Google Ads management approach](/services/google-ads/), our [Edmonton PPC practice](/edmonton/google-ads/), and our broader work on [AI marketing](/services/ai-marketing/) and [conversion optimization](/services/conversion-optimization/). For related posts, see [We Track Your Business Across 10 AI Platforms](/blog/ai-platform-tracking/) and [Google Ads vs Meta Ads: Where to Spend Your First Dollar](/blog/google-ads-vs-meta-ads/).
---
## We Track Your Business Across 10 AI Platforms: What We've Found
We monitor whether our clients' businesses appear in responses from Google AI Overviews, ChatGPT, Perplexity, Claude, Gemini, and five other AI platforms. The numbers are small because the entire space is early. But the baseline data we're collecting now will be invaluable when optimization playbooks mature.
## Why We Started Tracking AI Mentions
For twenty years, the question was: "Where does your business rank on Google?" That question still matters. But a parallel question is emerging: "Does your business appear when someone asks an AI for a recommendation?"
When a potential customer asks ChatGPT "What's the best dentist in Edmonton?" or asks Perplexity "Who does commercial paving in Calgary?" or gets a Google AI Overview for "optometrist near me," the AI generates an answer. That answer may or may not include your business. If it does, that's a discovery channel. If it doesn't, that's information you need.
We started tracking AI mentions because we track everything else. We monitor 60,000+ data points daily across Google Ads, organic search, page performance, and competitor activity. AI visibility is a new data stream, and ignoring it would leave a gap in our understanding of where our clients' businesses appear online.
The tracking isn't driven by hype. Nobody's organic traffic from AI referrals has replaced Google yet. For most local businesses, AI-generated traffic is a rounding error compared to traditional search. We track it because the trajectory matters more than the current volume, and because having 12 months of baseline data when the optimization playbook matures will be significantly more valuable than starting from zero.
## The 10 Platforms We Monitor
Each AI platform discovers and cites businesses differently. Understanding the mechanics of each one is necessary to interpret the data.
10+ AI platforms monitored for client business mentions and citationsSource: AI visibility monitoring via DataForSEO LLM Mentions API and GA4 referral tracking
**Google AI Overviews.** Google's AI-generated summaries appear at the top of search results for an increasing percentage of queries. When someone searches "best paving company in Edmonton," Google may generate an AI Overview that names specific businesses. This is the highest-impact AI visibility channel because it appears within the Google search experience itself, where the traffic already is. Visibility here correlates heavily with existing organic ranking signals.
**ChatGPT.** OpenAI's conversational AI has a web browsing capability and increasingly includes business recommendations in its responses. When a user asks ChatGPT for local business recommendations, it synthesizes information from multiple sources. The model's knowledge has a training data cutoff, but web browsing fills some gaps. ChatGPT is the highest-traffic AI platform globally, but its local business recommendation capability is still developing.
**Perplexity.** Perplexity functions as an AI-powered search engine that cites its sources. When it recommends a business, it links to the source material. This makes Perplexity mentions particularly trackable because the citation includes a URL. The referral traffic is measurable in GA4. Perplexity's audience skews toward researchers and professionals who want cited answers rather than generated text.
**Claude.** Anthropic's AI assistant handles business-related queries with a research-oriented approach. Claude's training data includes business directories, review sites, and industry publications. For local business queries, Claude tends to recommend based on published reviews and directory presence rather than generating novel recommendations.
**Gemini.** Google's AI assistant has deep integration with Google's own data, including Google Maps and Google Business Profile information. Gemini recommendations for local businesses draw heavily from GBP data, making GBP optimization directly relevant to Gemini visibility.
**Copilot.** Microsoft's AI assistant, integrated into Bing and Microsoft 365, draws from Bing's search index. Businesses with strong Bing presence see Copilot mentions. Given that Bing's market share is smaller than Google's, the volume is proportionally lower, but the audience includes a significant enterprise user base.
**You.com.** An AI search engine that provides cited answers. Lower traffic than the major platforms, but its search-engine format means mentions are structured and attributable.
**Phind.** An AI search engine focused on technical and professional queries. Relevant for B2B services and technology companies rather than consumer-facing businesses.
**Meta AI.** Meta's AI assistant is integrated into WhatsApp, Instagram, and Facebook Messenger. When users ask Meta AI for local recommendations, it draws from Meta's business directory and Facebook page data. The integration with messaging platforms means these recommendations happen in private conversations, making them harder to track but potentially high-impact for conversion.
**AI-enhanced search results.** Beyond dedicated AI platforms, traditional search results increasingly include AI-generated elements: featured snippets that synthesize multiple sources, "People also ask" boxes with AI-generated answers, and knowledge panels with AI-curated information.
| Platform | Primary Data Source | Trackable Via | Current Volume |
|---|---|---|---|
| Google AI Overviews | Google Search index | SERP monitoring, DataForSEO | Growing, tied to search volume |
| ChatGPT | Web browsing + training data | LLM Mentions API | Low for local, growing |
| Perplexity | Web search, cited sources | GA4 referral traffic, LLM API | Small but attributable |
| Claude | Training data, publications | LLM Mentions API | Small |
| Gemini | Google Maps, GBP, Search | LLM Mentions API | Moderate, Google-integrated |
| Copilot | Bing index | LLM Mentions API | Small, enterprise skew |
| You.com | Web search, cited | GA4 referral traffic | Very small |
| Phind | Web search, technical focus | GA4 referral traffic | Very small, B2B only |
| Meta AI | Facebook/IG data | Limited, platform-internal | Unknown, hard to measure |
## How We Track It
We use two complementary approaches to measure AI visibility. Neither is perfect, but together they provide a useful picture.
**DataForSEO LLM Mentions API.** This API queries AI platforms with specific prompts and returns whether a business is mentioned in the response. We run client-relevant queries (service + location combinations) across the platforms and record whether the client's business appears, how prominently, and what competitors appear alongside it. This gives us a snapshot of AI visibility at a specific point in time for specific queries.
The API approach has limitations. AI responses are non-deterministic: the same query can produce different answers on different days. We address this by running queries repeatedly and tracking mention frequency rather than treating any single response as definitive. A business that appears in 7 out of 10 queries for a term has meaningfully different visibility than one that appears in 1 out of 10.
**GA4 referral traffic filtering.** When someone clicks a link in an AI platform's response and visits a client's website, that visit appears in GA4 as a referral from the AI platform's domain. We filter GA4 referral data for known AI platform domains: chat.openai.com, perplexity.ai, you.com, and others. This gives us actual traffic volume from AI sources.
The referral approach also has limitations. Not all AI interactions result in a website click. A user who gets a business recommendation from ChatGPT might call the business directly without visiting the website. The referral data captures only the subset of AI visibility that produces a measurable website visit.
Between the two approaches, we get both visibility (are you being mentioned?) and traffic (are those mentions driving visits?). The visibility data is leading: it shows where you appear before that appearance translates to traffic. The traffic data is confirming: it validates that visibility is producing actual engagement.
## What We've Actually Found
We want to be direct about the current state of the data. For most local businesses, AI-generated traffic is small. Most of our clients see fewer than 50 AI-referral visits per month. Some see fewer than 10. This is not a channel that's replacing Google organic traffic or Google Ads conversions in 2026.
What we have found, across the clients where we have enough data to draw conclusions:
**Structured data correlates with AI visibility.** Clients whose websites have comprehensive schema markup (LocalBusiness, Service, FAQ, Review) appear in AI responses more frequently than clients without structured data. This isn't a causal claim; businesses with well-built websites tend to have both good schema and good content, and AI platforms draw from both. But the correlation is consistent enough that we consider schema markup a prerequisite for AI visibility, not an optional enhancement.
**Google Business Profile completeness matters for Gemini and Google AI Overviews.** Clients with fully completed GBP profiles (all services listed, Q&A populated, regular posts, extensive photo galleries) appear more frequently in Gemini responses and Google AI Overviews than clients with minimal profiles. This makes sense given that Gemini draws directly from Google's data ecosystem.
**llms.txt files are appearing in citation contexts.** Several clients where we've implemented llms.txt files (machine-readable summaries of business information designed for AI consumption) are seeing their llms.txt content reflected in AI responses. The sample size is small, but the pattern is that AI platforms with web browsing capabilities find and use this structured business summary when formulating responses.
Structured data + complete GBP correlate with higher AI visibility across the platforms we monitorSource: AI visibility monitoring data across client portfolio
**Review volume influences recommendations.** AI platforms frequently cite review volume and rating when recommending local businesses. A business with 200+ Google reviews and a 4.7 rating appears in AI recommendations more often than a competitor with 30 reviews and a 4.5 rating. The AI platforms appear to use review signals as a proxy for business quality, similar to how Google's organic algorithm uses them.
**Content depth matters more than content volume.** A dental practice with one comprehensive page about dental implants (2,000+ words covering cost, procedure, recovery, candidacy) appears in AI responses for implant-related queries more often than competitors with five thin pages covering the same topics superficially. AI platforms seem to favor authoritative, comprehensive content that can be directly quoted or synthesized.
## The Honest Framing
We can't optimize your way into ChatGPT's answers yet. Nobody can, and anyone who claims they can is selling something that doesn't exist.
AI platforms don't have a transparent ranking algorithm like Google (which itself isn't fully transparent). There's no equivalent of "title tags" or "backlinks" that reliably influence AI responses. The platforms are evolving their recommendation mechanics rapidly, and what works today may not work next month.
What we can do:
**Tell you whether you're showing up.** If your business appears in AI responses for your key service queries, you know. If it doesn't, you know that too. This visibility data is the starting point for any future optimization work.
**Track changes over time.** When we add structured data to your website, does your AI visibility change in the following months? When we publish a comprehensive service page, does it start getting cited? The baseline data lets us measure the impact of changes that might otherwise be invisible.
**Monitor your competitors.** When an AI platform recommends a competitor for a query that should include your business, that's competitive intelligence. We can see which competitors appear and for which queries, which tells us something about what the AI platforms consider authoritative in your market.
**Prepare for the shift.** AI-generated answers are eating into traditional search clicks. Google AI Overviews appear on an increasing percentage of queries. ChatGPT and Perplexity are growing in usage. The businesses that understand their AI visibility profile now will be better positioned to optimize when the playbook matures than businesses that start measuring from zero.
The trajectory is clear even if the timeline isn't. Five years from now, "where does your business appear in AI answers?" will be as standard a question as "where does your website rank on Google?" is today. The businesses that have been tracking this data for years will have a compounding advantage over those that start tracking when it becomes obvious.
## What We're Building Toward
Our AI visibility monitoring is integrated into the same infrastructure that monitors everything else. The data flows into the same centralized database. The same analysts review AI visibility alongside organic rankings, Google Ads performance, and site health. This integration matters because AI visibility doesn't exist in isolation: it's influenced by the same signals (content quality, structured data, online reputation) that drive traditional search performance.
When we build a comprehensive service page optimized for organic search, we're also building content that AI platforms can cite. When we optimize a Google Business Profile for local pack visibility, we're also building the data that Gemini uses for local recommendations. When we implement schema markup for rich results in Google, we're also providing structured data that AI platforms can parse.
The optimization work isn't separate. It's the same work producing value across an expanding set of discovery channels. AI visibility is an additional return on existing SEO investment, not a separate line item.
This kind of AI platform tracking is part of our broader [AI digital marketing program](/services/ai-marketing/), one of several places we use AI to remove manual toil from marketing operations.
We don't know yet which AI platforms will matter most in two years. We don't know which optimization tactics will be most effective. What we do know is that having baseline data across all the platforms, collected consistently over time, will be the foundation for whatever optimization approach emerges. And that foundation is being built now, for every client, as part of the monitoring infrastructure we already run.
Learn more about our [SEO services](/services/seo/) and the infrastructure behind our monitoring in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/). For more on how we build content that serves both traditional and AI-driven discovery, see [our approach](/about/).
---
## Seasonal Marketing for Trades: Managing the Construction Calendar
Seasonal businesses waste money running the same campaigns year-round. We manage the full marketing calendar: pre-season keyword building, in-season budget scaling, off-season brand maintenance. One construction client saw 316% organic traffic growth.
## The Seasonal Pattern
Most trades businesses in Alberta and the Prairie provinces operate on a construction calendar that has very little in common with the flat, year-round demand curves that most marketing advice assumes. A paving company doesn't get inquiries in January. A landscaper doesn't book projects in November. A roofing contractor's phone rings constantly from April through September and barely at all from November through February.
Running the same marketing strategy and the same budget allocation twelve months a year for these businesses is the equivalent of heating an empty building: the money goes out and nothing useful comes back.
We manage SEO and Google Ads for multiple trades clients across Western Canada, and we've structured our approach around four distinct phases. Not as a framework we impose on the data, but as a pattern the data consistently shows.
| Season | Months | Search Volume | Marketing Focus |
|---|---|---|---|
| Pre-season | Feb - Mar | Rising, 20-30% of peak | Build content, prepare campaigns, technical SEO |
| Peak | Apr - Oct | 100% | Scale budget, maximize visibility, convert traffic |
| Wind-down | Nov | Declining, 40-50% of peak | Reduce spend, shift to brand, close pipeline |
| Off-season | Dec - Jan | 10-15% of peak | Maintain rankings, plan, build for next cycle |
These phases aren't arbitrary. They're derived from 15+ years of managing trades clients and confirmed by search volume data. The exact timing shifts slightly by trade and geography: a concrete contractor in Edmonton has a shorter peak season than a general contractor in Vancouver. But the four-phase pattern holds across all of them.
## Pre-Season: Building While Competitors Sleep
The most valuable marketing work for a seasonal business happens in the months before demand arrives. SEO content published in February starts ranking by April. Technical improvements made during quiet months compound into better site performance when traffic peaks. Campaign structures built in March are ready to scale when search volume climbs in April.
Most trades businesses cut their marketing budget during the slow months and ramp it back up when the phone starts ringing. This is exactly backwards. By the time demand arrives, there's no time to build. You're either already positioned or you're scrambling to catch up while your competitors, who did the work in February, capture the early-season leads.
Pre-season work breaks into four categories:
**Content targeting seasonal queries.** We publish service pages and blog content targeting queries that peak in spring and summer: "driveway paving cost [year]," "deck building season," "when to seal asphalt." This content needs 4-8 weeks to index and rank. Publish in February, rank by April, capture traffic at peak demand.
**Technical SEO cleanup.** Page speed optimization, crawl error fixes, schema markup updates, and mobile usability improvements. These changes improve the site's overall ranking potential and are best done when traffic is low, because any temporary disruption from site changes affects fewer visitors.
**Campaign preparation.** Google Ads campaign structures are reviewed and rebuilt for the coming season. New ad copy reflecting current pricing. Updated keyword lists based on the previous season's search term data. New negative keywords from the previous season's wasted spend. Landing pages updated with current project photos and testimonials.
**Competitive analysis.** We pull competitor positioning data during pre-season because it shows us who's been working during the off-season. If a competitor has published 10 new service pages in January, we know they're planning an aggressive spring push and we can adjust our strategy.
4-8 weeks is the typical time from content publication to competitive ranking, which is why pre-season SEO work is essentialSource: Position tracking data across trades clients
The pre-season investment is also when we do the planning work that makes in-season execution efficient. Monthly strategy calls during peak season focus on performance and adjustments, not on foundational decisions that should have been made two months earlier.
## In-Season: Budget Scaling Without Overspend
When search volume climbs in April, campaigns need to scale with it. A Google Ads budget that was appropriate for March isn't enough for May. But scaling a budget isn't as simple as increasing a number in a dashboard. Without discipline, seasonal scaling turns into seasonal overspending.
Our budget monitoring runs every 30 minutes across all managed accounts. For seasonal businesses, this monitoring is especially critical during the ramp-up and ramp-down transitions. A campaign set to "Maximize Conversions" will happily spend $500 in a single day if Google's algorithm sees an opportunity, even if the monthly budget only supports $200 per day.
Every 30 minutes budget pacing is verified across all managed accounts, preventing seasonal overspend during demand rampsSource: Budget monitoring cron schedule
The in-season phase has its own set of strategic adjustments:
**Progressive budget increases.** We don't jump from a $3,000 monthly budget to $8,000 on April 1. The increase is gradual over 3-4 weeks, matching the actual ramp-up in search volume. This gives Smart Bidding time to adjust to the higher budget and prevents a sudden spend spike that produces clicks but not conversions.
**Search term monitoring.** During peak season, the volume of irrelevant search terms increases. "Paving" triggers queries for "paving stones" and "paving slabs" that a commercial paving contractor doesn't serve. The search term report needs weekly review during peak months to add negative keywords. Our data pipeline pulls search term reports every 6 hours, so new irrelevant terms are visible quickly.
**Position tracking intensity.** Competitive landscape shifts happen fastest during peak season. Competitors launch campaigns, increase budgets, and push new content. We track keyword positions daily and flag significant movements. When a competitor suddenly appears in the top 3 for a target keyword, we see it within a day and can adjust.
**Landing page performance.** Traffic volumes during peak season expose page performance issues that were invisible at low traffic. A landing page with a 30% bounce rate at 100 visits per month is a different problem at 800 visits per month. We monitor bounce rates and conversion rates weekly during peak season and make adjustments when the data warrants it.
The in-season discipline is about capturing demand efficiently, not just capturing demand. A trades business can waste $2,000-$3,000 per month on irrelevant clicks, competitor clicks, and poorly timed bid increases if the campaigns aren't actively managed through the peak period.
## Wind-Down: The Transition Most Agencies Ignore
November is when most agencies realize they should probably reduce the trades client's budget. By that point, search volume has already dropped 50-60% from peak. The client has been paying peak-season rates for 2-3 weeks of declining returns.
We start the wind-down process in mid-October for most Alberta trades clients. The timing is based on search volume data, not the calendar.
**Budget reduction schedule.** We reduce Google Ads budgets in 2-3 steps over 4-6 weeks, matching the decline in search volume. This is where flat-fee pricing matters: our recommendation to reduce spend costs us nothing, so we make it as soon as the data supports it. Read more about why this alignment matters in [Why We Don't Charge a Percentage of Ad Spend](/blog/why-flat-fees/).
**Campaign pausing order.** Not all campaigns wind down at the same rate. Brand campaigns that capture existing awareness continue longer than broad match campaigns targeting new customers. Remarketing campaigns that follow up with summer visitors continue into November. We pause campaigns in order of declining ROI, not all at once.
**Shift to brand content.** As paid campaigns reduce, we shift focus to organic brand content. Project showcases from the completed season, customer testimonials, and "planning ahead for spring" content. This keeps the site active and indexed without paying for clicks on queries that won't convert into winter projects.
**Pipeline management.** Leads generated in October often won't convert to projects until spring. We work with clients to tag these leads appropriately and maintain communication through the off-season. A homeowner who inquired about a new driveway in October and received a quote is a warm prospect for April, if the practice stays in touch.
## Off-Season: The Work That Compounds
December through January is when the least visible but most impactful work happens. The site still needs to be maintained, indexed, and improving. The difference between a trades business that maintains its marketing presence during the off-season and one that goes dark is visible in the spring results.
**Link building.** The off-season is the best time for outreach and link building. Industry directories, supplier websites, local business associations, and trade publications are more responsive during their own quiet periods. Links acquired in December and January strengthen the site's authority before the spring ranking competition intensifies.
**Technical audits.** We run comprehensive site audits during the off-season: page speed analysis, mobile usability, structured data validation, crawl budget optimization, and competitive gap analysis. These audits produce a prioritized list of improvements that get implemented during pre-season.
**Content planning.** We analyze the previous season's keyword data to identify gaps. Which keywords drove traffic but didn't have dedicated content? Which service pages had high bounce rates? Which blog posts attracted traffic from queries we didn't deliberately target? The answers shape the pre-season content calendar.
**Strategy planning.** Annual strategy reviews happen in January. This is when we set goals for the coming season, adjust keyword targets based on competitive changes, and plan any major site changes (redesigns, new service pages, location expansions).
The off-season isn't a break from marketing. It's when the foundation for the next season gets built. Businesses that maintain consistent SEO effort through the winter start each spring with a stronger baseline than businesses that start and stop with the seasons.
## The Results
One Alberta paving company illustrates the full-cycle approach over a 2+ year engagement.
316% organic traffic growth for an Alberta paving company over a multi-year engagement with seasonal strategy alignmentSource: GA4 traffic data via Thor centralized database, anonymized
The 316% growth in organic traffic wasn't a straight line. It followed the seasonal curve: peaks in summer, valleys in winter. But each year's peak was higher than the last, and each year's valley was higher than the previous year's valley. The compounding effect of consistent off-season work produced a rising baseline that seasonal demand amplified.
Key factors in the growth:
**Pre-season content.** Service pages published during off-season months ranked competitively by the following spring. Over two seasons, the site went from ranking for 15 targeted keywords to ranking for 40+, with 12 in the top 3 positions.
**Budget discipline.** Google Ads spend matched demand curves rather than running flat. Off-season budget reductions saved $4,000-$6,000 annually that would have been spent on low-intent clicks. That money was redirected to content production and technical improvements during the quiet months.
**Monitoring catch.** During the second season, a site migration by the client's web developer broke several service page URLs. Our daily site health checks caught the broken pages the next morning. The redirects were implemented within hours, preserving the ranking equity those pages had built over the previous 12 months. Without monitoring, those pages would have returned 404 errors for days or weeks, losing rankings that took months to build.
The seasonal approach isn't about doing more. It's about doing the right work at the right time. February work is different from July work, which is different from December work. A generic retainer that delivers the same services at the same intensity twelve months a year doesn't match how seasonal businesses actually operate.
See our [SEO services](/services/seo/) for how we structure seasonal engagements, or learn about our [Google Ads management approach](/services/google-ads/) for budget scaling strategies. For more on the monitoring infrastructure, read [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/).
---
## From 3 Clinics to 6: Scaling Multi-Location Healthcare Marketing
Multi-location healthcare marketing fails when each location competes with itself for the same keywords. Centralized monitoring and location-specific strategies let us scale an optometry group from 3 to 6 clinics while reducing acquisition cost by 30%.
## The Multi-Location Problem
An optometry group with three clinics in a mid-size Canadian city came to us with a straightforward request: help us open three more locations over the next 18 months. The marketing budget would grow, but they wanted the cost to acquire each new patient to stay flat or decrease, a straightforward request that turned out to be far harder to execute than it sounds.
The problem with multi-location healthcare marketing is that it breaks the assumptions behind most SEO and local search strategies. A single-location business targets "optometrist near me" and "eye exam [city name]" and builds content around those keywords. When you add a second location in the same metro area, both locations now compete for the same queries. When you add a third, fourth, fifth, and sixth, you've created an internal competition that can be worse than the external one.
We see this pattern across healthcare, dental, physiotherapy, and veterinary practices. Each location gets its own website page, its own Google Business Profile, and its own set of keywords. Without centralized oversight, the locations cannibalize each other's rankings. Location A's service page outranks Location B's for a query that Location B should own because it's closer to the searcher. Location C's Google Business Profile gets optimized for "comprehensive eye exams" while Location D, which actually specializes in pediatric eye care, gets the same generic treatment.
The result is a portfolio of locations that collectively underperforms what each location could achieve individually with the right targeting. More locations, more content, more GBP profiles, less clarity for Google about which location should rank for which query.
| Problem | Single Location | Multi-Location (Without Strategy) |
|---|---|---|
| Keyword targeting | One set of targets | Multiple locations targeting the same keywords |
| GBP optimization | One profile to manage | 6 profiles competing in the same market |
| Content strategy | Straightforward local focus | Risk of duplicate content across location pages |
| Ranking attribution | Clear | Ambiguous - which location should rank where? |
| Performance monitoring | One dashboard | Data scattered across multiple properties |
## How We Managed 6 Locations Without 6x the Work
The first thing we built was centralized monitoring. All six locations' keyword positions, GBP performance, and organic traffic flow into the same database. We track 1,000+ keyword positions daily across all clients, and for this practice, each location had its own tracked keyword set.
1,000+ keyword positions tracked daily across all clients, with per-location breakdowns for multi-location practicesSource: SEMrush position tracking via Thor centralized database
This centralization is what makes multi-location management feasible without multiplying the team size. When all six locations share a single dashboard, one analyst can spot problems that would be invisible if each location were managed in isolation. The most important pattern to catch: two of your own locations competing for the same query.
We built alerts for exactly that. When Location A and Location B both appear in the top 20 results for the same keyword, the system flags it. This isn't necessarily a problem: sometimes you want two locations to rank for a broad term. But when one location is ranking 4th and the other is ranking 11th for a term that's geographically specific to the second location, that's a signal to adjust the content strategy.
The monitoring also shows when a new competitor enters a specific location's market. If a new optometry practice opens near one of the six clinics, we see the position shifts within days, not months. We can adjust the content and GBP strategy for that specific location without disrupting the other five.
Without centralization, this work requires six separate logins, six separate reports, and six separate strategy conversations. The chance that anyone notices Location B cannibalizing Location D's traffic on a specific keyword cluster is close to zero. With centralization, it's flagged automatically and reviewed in the next strategy session.
## Location-Specific Strategy
Centralized monitoring solves the visibility problem. Location-specific strategy solves the targeting problem.
Each clinic served a different area with different demographics, commuter patterns, and competitive landscapes. We built distinct keyword strategies for each.
**Neighborhood targeting.** Instead of all six locations competing for "optometrist [city name]," each location targeted the surrounding neighborhoods and suburbs. Location A targeted "[neighborhood] eye doctor" and "[suburb] eye exam." Location B, 15 minutes away, targeted its own surrounding areas. This gave each location a clear keyword territory with minimal overlap.
**Service specialization.** The practice offered different specialty services at different locations. One clinic had a pediatric optometrist. Another specialized in contact lens fittings. A third was the primary location for medical eye care referrals. We built content around these specializations, giving Google clear signals about which location to surface for which type of query.
**Commuter pattern content.** We identified that patients often searched for eye care near their workplace, not just near home. Two of the clinics were in commercial districts, so we built content targeting "[business district] eye exam" and "eye doctor near [major employer/mall/office park]." This captured a traffic segment that location-based targeting alone would miss.
| Location | Primary Service Focus | Keyword Territory | Content Angle |
|---|---|---|---|
| Clinic A | General optometry | Northwest neighborhoods | Family eye care, routine exams |
| Clinic B | Pediatric | School catchment areas | Children's vision, learning-related |
| Clinic C | Contact lens specialist | Central commercial district | Contact lens fitting, downtown workers |
| Clinic D | Medical eye care | Referral network area | Glaucoma, diabetic eye, specialist |
| Clinic E | General optometry | Southern suburbs | New residents, comprehensive exams |
| Clinic F | General + dry eye | Eastern corridor | Dry eye treatment, screen fatigue |
Each location page had unique content that reflected its actual service mix and geographic context. Not six copies of the same template with the address swapped out, which is what we see in most multi-location setups we inherit.
The content wasn't long for the sake of length. Each location page included the specific services offered at that clinic, the surrounding neighborhoods it served, parking and transit access, the specific optometrists practicing there, and relevant specialty content. A patient searching for pediatric eye care in the clinic's area would find content specifically addressing children's vision needs at that location.
## GBP at Scale
Google Business Profile management for six locations is where most practices lose discipline. The first profile gets careful attention: professional photos, regular posts, prompt review responses, complete service listings. By the time you get to location four or five, updates become sporadic and the profiles start looking neglected.
We managed all six profiles on a structured monthly cadence.
**Photos.** Each location had a quarterly photo refresh. Interior shots, staff photos, equipment photos, and exterior shots updated seasonally. Google rewards active profiles with better visibility, and photo quality directly impacts click-through rates from the map pack.
**Posts.** Each profile received at least two Google Posts per month, with content specific to that location. Not the same post copied across six profiles. Location-specific promotions, seasonal reminders relevant to the area, and content aligned with the location's service specialization.
**Reviews.** We tracked review volume and sentiment across all six locations. When one clinic's review volume dropped below the others, we flagged it for the practice to address internally. We didn't generate fake reviews; we made sure the practice had a consistent process for asking satisfied patients to leave reviews at each location, and we monitored whether that process was working.
**Q&A.** Google Business Profiles have a Q&A section that most businesses ignore. We seeded each profile with the most common questions and answers covering that location's services: parking availability, insurance acceptance, whether they see children, whether walk-ins are available. This pre-empts the "People also ask" box with answers we control.
**Citation consistency.** Six locations mean six entries across every directory: Google, Bing, Apple Maps, Yelp, Healthgrades, RateMDs, local chambers of commerce, and healthcare directories. NAP (Name, Address, Phone) consistency across all of these matters for local ranking signals. We audited citation accuracy quarterly, which meant checking and correcting six entries across 15+ directories, roughly 90 individual listings.
6 GBP profiles managed on a structured monthly cadence, with quarterly citation audits across 15+ directoriesSource: Choice OMG local SEO management process
The compounding effect was significant. Each individual profile optimization had a small impact. But when all six profiles were consistently maintained over 12 months, the practice's overall map pack presence across the metro area improved materially. Patients searching from any part of the city were more likely to see one of the six clinics in the local pack results.
## Scaling Without Scaling Costs
The infrastructure that makes this work is the same infrastructure we've built for all 30 clients. Position tracking, centralized data, automated alerts, and structured workflows. Adding locations 4, 5, and 6 didn't require hiring additional analysts or buying additional tools. The monitoring was already built to handle multiple entities per client.
This is the practical outcome of the automation investment we describe in [The Automation Stack](/blog/automation-stack/). The per-location marginal cost of monitoring and management is low because the infrastructure already exists. We're adding rows to a tracking database, not adding headcount.
The practice's marketing spend increased as locations were added, but not proportionally. Three locations to six locations did not require doubling the management budget. The centralized approach meant strategy work was shared where appropriate (brand-level content, practice-wide campaigns) and differentiated where necessary (location-specific targeting, GBP management).
## The Results
Over 18 months, the practice went from three clinics to six. The patient acquisition numbers tell the story.
~30% lower patient acquisition cost across the expanded 6-location network compared to the original 3-clinic baselineSource: Client campaign data, anonymized
The 30% reduction in acquisition cost came from three factors working together. First, the location-specific keyword strategies eliminated internal cannibalization, so ad and organic spend wasn't competing against itself. Second, the centralized monitoring caught performance issues at individual locations quickly, preventing wasted spend from accumulating. Third, the structured GBP management improved organic visibility in local search, reducing the practice's dependence on paid advertising at each location.
Position tracking showed each location ranking in the top 3 for its targeted neighborhood keywords within 6 months of launch. The locations that launched with a full local SEO strategy in place from day one reached competitive positions faster than the original three clinics had, because we applied the lessons from the first three immediately rather than learning them again.
The practice also gained a competitive advantage that's harder to quantify: when a patient searches for eye care anywhere in the metro area, they're likely to see one of the six clinics. That geographic coverage creates a brand presence that a single-location competitor can't match, regardless of how well that competitor optimizes their one profile.
## When Multi-Location Strategy Matters
This approach isn't only relevant to optometry. The same patterns apply to any healthcare practice expanding across a metro area: dental groups, physiotherapy chains, veterinary clinics, urgent care centers, medical aesthetics practices.
The common thread is that each location serves a geographic area, offers a set of services, and needs to be discoverable for searches tied to that area and those services. Without centralized management, each location is an isolated marketing effort with no awareness of what the other locations are doing. With it, the portfolio works as a system.
The investment in centralized monitoring pays for itself at the third location. At two locations, the risk of cannibalization is manageable. At three or more, it becomes a structural problem that gets worse with each addition. The earlier you centralize, the less cleanup you need when you scale.
Learn more about our [local SEO services](/services/local-seo/) or see how centralized monitoring works in practice at [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/). For healthcare-specific approaches, see our work with [multi-location eye care practices](/results/multi-location-eye-care/).
---
## How a High-Value Procedure Ad Campaign Actually Works
When a single dental implant case is worth $20,000-50,000, you cannot afford imprecise tracking. We grew one practice's implant revenue from $300K to $800K by building airtight click-to-consultation attribution.
## The Economics of High-Value Procedures
Most Google Ads campaigns operate in a world of volume. A plumber might spend $50 per click and need 20 clicks to get a lead worth $500. The math works because each conversion is a small transaction, and the law of large numbers smooths out the noise. A few wasted clicks don't materially change the monthly return.
High-value procedure campaigns operate under completely different economics. A dental implant case can be worth $20,000 to $50,000 to the practice. A full-arch reconstruction might be $40,000 or more. At those values, a single conversion can justify the entire month's ad spend. The flip side: a single month of broken tracking can mean the difference between the campaign appearing profitable and appearing to lose money.
We managed a dental practice's implant campaign over two years. When we started, the practice attributed roughly $300,000 per year in implant revenue to their marketing efforts. The campaigns were running and leads were coming in, but nobody had clear visibility into which clicks were producing which consultations or which consultations were converting to procedures, so there was no way to tell whether the campaigns were actually failing or simply unmeasured, and unmeasured campaigns can't be optimized.
| Metric | Low-Value Service | High-Value Procedure |
|---|---|---|
| Typical conversion value | $200-$500 | $20,000-$50,000 |
| Required accuracy | Directional | Precise - one missed conversion distorts the data |
| Attribution window | 1-7 days | 30-90 days (research, consultation, decision) |
| Smart Bidding sensitivity | Tolerant of noise | Highly sensitive to missing signals |
| Cost of tracking failure | Moderate inefficiency | Campaign appears to fail when it's succeeding |
## The Conversion Pipeline
The attribution chain for a high-value procedure campaign has more steps and longer timelines than a typical lead gen campaign. Each step can fail independently, and the failure is always silent.
**Click.** A patient searches "dental implants [city]" or "full mouth reconstruction cost" and clicks an ad. The Google Click ID (GCLID) attaches to this click. This is the anchor of the entire attribution chain. If the GCLID doesn't survive the journey from click to form submission, the conversion can never be attributed back to the specific keyword, ad, and campaign that produced it.
**Landing page.** The patient arrives on a page built specifically for implant inquiries. The page needs to do two things: persuade the patient to take the next step, and preserve the tracking parameters through that step. If the form redirects through a third-party booking system that strips URL parameters, the GCLID is lost.
**Form or call.** The patient either fills out a consultation request form or calls the practice directly. Form submissions fire a GTM tag that sends the event to GA4, including the GCLID. Phone calls use call tracking that associates the call with the web session. Both paths need to capture the attribution data, not just the lead's contact information.
**GA4 event.** The form submission or call event is recorded in GA4 as a key event. This is where Google Ads gets its conversion signal. The event name has to match the key event configuration in GA4. The GA4 property has to be linked to the Google Ads account. The key event has to be marked for import.
**Google Ads import.** GA4 exports the key event to Google Ads as a conversion. This import has a 24-to-72-hour lag. For Smart Bidding, this conversion data is the signal it uses to decide which searches to bid on and how much to bid. If the signal doesn't arrive, Smart Bidding flies blind.
24-72 hours is the typical lag between a GA4 key event and its import into Google Ads for Smart BiddingSource: Google Ads conversion import documentation
For a dental implant campaign, the stakes of each step failing are amplified by the conversion value. A typical lead gen campaign might see 50 conversions per month, so 2-3 missed conversions don't materially change Smart Bidding's behavior. An implant campaign might see 8-12 qualified leads per month. If 2 of those are lost to tracking failures, Smart Bidding sees a 20% drop in conversion volume and starts adjusting bids downward, reducing the campaign's reach at exactly the wrong time.
## Building the Attribution Chain
We rebuilt this practice's tracking from scratch. The previous setup was not badly built; high-value campaigns demand a higher standard of reliability than most setups provide.
**GTM tag configuration.** We configured the form submission tag to fire on the actual form completion event, not on a page redirect. Many tracking setups fire the conversion tag when the user lands on a "thank you" page. That works until the thank-you page URL changes, or a pop-up confirmation replaces the page redirect, or the form plugin starts handling submissions via AJAX without a page load. We fired the tag on the form submission event itself, using data layer pushes from the form plugin. This is more work to set up, but it's resilient to front-end changes.
**Phone call tracking.** The practice received more calls than form submissions. Patients researching a $30,000 procedure want to talk to a person, not fill out a form. We integrated call tracking that associated each call with the web session that preceded it. When a patient clicked on the phone number displayed on the landing page, a GTM tag fired the phone_click event. Dynamic number insertion on the page associated the displayed number with the visitor's session, connecting the phone call to the original click.
**Cross-device handling.** Implant patients have long research cycles. A common pattern: the patient searches on their phone during lunch, browses the practice's website, then calls from their office phone the next day. Without cross-device attribution, that phone call has no connection to the ad click that started the journey. Google's cross-device conversion modeling handles some of this, but only if the foundational tracking is correct. We ensured the base tracking was solid so the modeling had clean data to work with.
**GCLID preservation.** We tested every form on the landing pages to verify that the GCLID parameter survived from the initial page load through form submission. Forms that used iframes, external booking systems, or multi-step wizards were all potential points of GCLID loss. We rebuilt two forms specifically because they dropped URL parameters on submission.
## What Monitoring Catches
Building the attribution chain is the first step. Keeping it intact is the ongoing work. Tracking breaks are not if-it-happens problems. They are when-it-happens problems. See our detailed breakdown of [how conversion tracking breaks](/blog/conversion-tracking-breaks/) for the full taxonomy.
For this implant campaign, our monitoring caught three specific breaks over two years.
**Break 1: GTM container version conflict.** The practice's web developer published a GTM workspace that didn't include our conversion tags. This is the most common GTM failure mode. The tags simply disappeared from the live container. Our GTM version monitoring flagged the container change within hours. We reviewed the published version, identified the missing tags, and republished a corrected version. Total downtime: roughly 6 hours. Without monitoring, this would have gone unnoticed for weeks.
**Break 2: Form plugin update.** The WordPress form plugin updated from one major version to another. The update changed the CSS class names on the form elements. The GTM trigger that fired on form submission was matching against the old class name. Forms still worked perfectly; patients could still submit requests. But the tracking tag stopped firing, so GA4 stopped recording conversions, and Smart Bidding stopped receiving signals. Our Playwright end-to-end tests caught the form interaction failure the same day the update was applied.
3 tracking breaks caught within hours over a 2-year campaign, each of which would have gone undetected for weeks without automated monitoringSource: Client campaign monitoring logs
**Break 3: GA4 key event toggle.** Someone on the practice's team was exploring GA4 and accidentally toggled the form submission event from "key event" to a regular event. GA4 still recorded the event. The data still appeared in GA4 reports. But the conversion stopped importing to Google Ads. Our cross-source comparison (GA4 events present but Google Ads conversions absent) flagged the discrepancy within one sync cycle.
Each of these breaks would have caused 2-4 weeks of damage if caught through manual review. For a campaign where each conversion is worth $20,000+, even one week of broken tracking means Smart Bidding makes bid adjustments based on false data, and the recovery period extends the impact further.
## Smart Bidding Needs Clean Data
The relationship between tracking accuracy and Smart Bidding performance follows a threshold effect: below a certain volume and accuracy of conversion signals, Smart Bidding switches from optimizing effectively to guessing, and for low-volume, high-value campaigns that threshold is easy to cross.
Smart Bidding algorithms learn from patterns in the conversion data. They identify which search queries, demographics, devices, times of day, and geographic locations correlate with conversions. For a high-volume campaign with 100+ conversions per month, the algorithm has plenty of data to find patterns. Missing a few conversions doesn't change the overall signal.
For an implant campaign with 8-12 conversions per month, every conversion is a significant data point, and missing 2 conversions removes 20% of the count along with 2 of the algorithm's best signals about what a converting search looks like. The algorithm might conclude that the keyword "dental implant cost" doesn't convert (because the 2 patients who converted from that keyword had their tracking broken) and shifts budget toward keywords that happen to have intact tracking but lower intent.
This is why high-value procedure campaigns demand a higher standard of tracking reliability. The cost of imprecision isn't just a slightly higher cost per lead. It's an algorithm that systematically misallocates budget because its training data is incomplete.
## The Results
Over two years, we grew the practice's attributable implant revenue from $300,000 to $800,000 annually.
$300K to $800K in annual implant procedure revenue, driven by airtight click-to-consultation attributionSource: Client campaign data, anonymized
That growth came from three sources, and it's important to separate them because they compound.
**Attribution accuracy.** Some of the growth was simply making visible what was previously invisible. Before we rebuilt the tracking, conversions were being lost at each step of the pipeline. Patients were calling the practice and booking implant consultations, but those calls weren't attributed to the campaigns that produced them. When we fixed the tracking, the campaigns appeared to improve overnight, but what actually improved was our ability to measure them.
**Smart Bidding optimization.** Once Smart Bidding had clean, consistent conversion data, it started doing what it's designed to do. It identified the search queries, geographies, and times of day that produced consultations and shifted budget accordingly. The algorithm is good at this work when it has good data. The previous tracking gaps had prevented it from learning effectively.
**Campaign expansion.** With clear attribution showing which campaigns and keywords produced consultations, we could expand confidently. We added campaigns for specific procedures (All-on-4, implant-supported dentures) and geographic targets that the data showed were producing qualified patients. Each expansion was backed by attribution data, not guesswork.
The practice's cost per qualified consultation decreased even as total ad spend increased. That's the signature of a well-tracked campaign: spend goes up, volume goes up, and efficiency improves because the algorithm gets better at targeting as it accumulates more high-quality conversion data.
## When This Approach Applies
Any business where individual conversions are worth thousands of dollars operates under the same dynamics. Medical practices (dental implants, cosmetic surgery, LASIK, orthodontics), law firms (personal injury, family law), financial services (wealth management, mortgage brokerage), and high-end home services (kitchen renovations, custom builds) all share the pattern: low conversion volume, high conversion value, and Smart Bidding sensitivity to tracking accuracy.
The common mistake is treating these campaigns like high-volume lead gen. Running the same tracking setup you'd use for a plumbing company that gets 50 calls a month doesn't work for a practice that gets 10 implant inquiries a month. The tracking standard has to match the economics. When one conversion is worth $20,000, the monitoring infrastructure that catches tracking breaks in hours instead of weeks pays for itself many times over.
Read about the monitoring infrastructure behind this approach in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/). Learn about [our Google Ads management approach](/services/google-ads/) and what happens when [conversion tracking breaks silently](/blog/conversion-tracking-breaks/).
---
## The Real Cost of SEO in 2026: Lessons from 30 Client Engagements
SEO costs range from $1,500 to $5,000+/month depending on competitive landscape and location count. The real cost difference between agencies is what happens when something breaks and nobody's watching.
## What Drives SEO Cost
SEO pricing isn't arbitrary, but it's also not standardized. Two businesses in different industries with different competitive landscapes will have genuinely different costs to achieve meaningful results. The variables that matter:
**Competitive market density.** A plumber in a small city with three competitors bidding for "plumber near me" has a fundamentally different optimization challenge than a personal injury lawyer in a metro area with 40 firms all investing in SEO. The more competitive the market, the more content production, link building, and technical refinement is required to move positions.
**Number of locations.** A single-location business needs one set of location pages, one Google Business Profile optimization, and one local SEO strategy. A business with five locations needs all of that multiplied, plus a strategy for managing cannibalization between locations targeting similar keywords.
**Content production needs.** Some industries have thin content requirements: a few strong service pages and a handful of FAQ entries. Others, particularly professional services and healthcare, require ongoing content production to establish topical authority. The difference between "set up the pages and optimize them" and "produce 4-8 pieces of substantive content per month" is significant in both effort and cost.
**Technical complexity.** A simple WordPress site with 20 pages has different technical SEO needs than a custom-built site with dynamic content, JavaScript rendering, multiple subdomains, and international targeting. The more complex the technical foundation, the more specialized the audit and remediation work.
**Domain age and existing authority.** A brand-new domain starting from zero needs months of foundational work before it can compete for anything meaningful. An established domain with years of history and existing backlinks has a head start that reduces the time-to-results and, in some cases, the ongoing effort required.
**AI visibility requirements.** In 2026, SEO increasingly includes visibility in AI-generated answers across platforms like Google AI Overviews, ChatGPT, Perplexity, and others. Businesses that need to appear in these AI-generated citations require structured content strategies that go beyond traditional keyword optimization. This is an emerging cost factor that didn't exist two years ago, and it affects both the content production workload and the monitoring scope.
## Three Tiers, Honest Expectations
We've structured our SEO services into three tiers based on what the engagement actually requires. These tiers reflect the real differences in work volume and scope, not an attempt to upsell.
| Tier | Monthly Investment | Typical Client Profile | What's Included |
|---|---|---|---|
| Starter | $1,500/mo | 1-3 locations, moderate competition, established domain | Technical audit and fixes, up to 20 keyword targets, on-page optimization, monthly reporting, daily position tracking |
| Growth | $3,000/mo | Multi-location, competitive markets, content needs | Everything in Starter plus content production (2-4 pieces/month), link building, competitor monitoring, bi-weekly strategy calls |
| Authority | $5,000/mo | Aggressive growth goals, highly competitive verticals, regional or national targeting | Everything in Growth plus expanded content (6-8 pieces/month), aggressive link acquisition, weekly strategy calls, full technical oversight |
$1,500 to $5,000/month SEO investment range based on competitive landscape and engagement scopeSource: Choice OMG active service pricing across 30 client engagements
**What Starter gets you.** The foundational work: a technical audit that finds and fixes crawlability issues, proper site structure, optimized title tags and meta descriptions, internal linking improvements, and daily keyword position tracking for up to 20 target keywords. This tier works for businesses in moderately competitive markets that need their existing site to perform better. It doesn't include content production or link building, which means position gains come from technical and on-page improvements.
**What Growth adds.** Content production and off-site signals. This tier includes everything in Starter plus 2-4 pieces of content per month (blog posts, service page expansions, FAQ content), active link building, and competitor monitoring. The content fills gaps in topical coverage that technical optimization alone can't address. This is the tier where we start seeing compounding returns: each piece of content strengthens the overall domain, which helps every other page rank better.
**What Authority delivers.** Full-spectrum SEO for businesses that need to dominate their market. Expanded content production, aggressive link acquisition, weekly strategy alignment, and complete technical oversight including JavaScript rendering audits, Core Web Vitals monitoring, and site architecture planning. This tier is for businesses where SEO is a primary growth channel, not a supplementary one.
### What Each Tier Doesn't Get You
Honesty matters here. Starter tier clients should not expect to rank for highly competitive head terms in a crowded metro market. That takes the sustained content and link building that comes with Growth or Authority tiers. Growth tier clients should not expect to outrank national brands for broad category terms. That requires the investment level and timeline of Authority tier work.
Setting realistic expectations up front avoids the disappointment cycle that plagues this industry, where agencies promise results they can't deliver, produce average performance, and then blame the algorithm when the client notices the gap.
### Timeline Expectations
Regardless of tier, SEO is not instant. Meaningful results typically follow this trajectory:
| Timeline | What Happens |
|---|---|
| Month 1 | Technical audit, fixes deployed, baseline metrics documented |
| Months 2-3 | Content production begins, on-page optimization applied, indexation verified |
| Months 3-6 | Position gains become visible for lower-competition keywords, traffic starts trending upward |
| Months 6-12 | Competitive keywords show movement, content authority compounds, measurable traffic and lead growth |
| Year 2+ | Market position established, ongoing optimization sustains and extends gains |
Any proposal that promises significant results in 30-60 days is either targeting keywords with zero competition (which produce negligible business value) or is not being honest about how SEO works.
## What Matters More Than Price
When comparing SEO providers, the monthly fee is the easiest thing to compare and the least informative. What separates effective SEO management from expensive mediocrity is the operational infrastructure behind the work.
**Monitoring cadence.** Are keyword positions tracked daily or checked manually once a month? Daily tracking means a sudden position drop gets noticed the day it happens. Monthly tracking means you find out 30 days later in a report. We track 1,000+ positions daily across our client base.
**Technical depth.** Is the technical audit automated and recurring, or is it a one-time manual check? Websites change. Plugins update. Content gets added. A technical issue introduced by a WordPress update in February won't appear in a technical audit that happened in January. Our site audit data syncs weekly, catching new issues as they're introduced.
**Reporting quality.** Does the report align with strategic objectives, or is it a PDF of charts? A good report connects the data to the strategy: what we set out to do, what the data shows, and what we're adjusting as a result. A mediocre report shows traffic went up or down without context for what that means or what's changing as a result.
**Data infrastructure.** Where does the data live? Can the agency reproduce a report from six months ago? Can they trace a specific metric back to its source? Our centralized database stores all performance data with full traceability, from the raw API response to the final report number. Read more about this in [Why We Built a Single Source of Truth for Client Data](/blog/single-source-of-truth/).
## What We've Seen Work
These are real results from real engagements, anonymized to protect client confidentiality.
**A paving company in western Canada, Growth tier.** Starting from near-zero organic visibility, we focused on technical fixes during winter months, built out service-specific landing pages with geographic targeting, and timed the work so that position gains were established before the spring search volume spike. Result: 316% organic traffic growth within the first year. The seasonal timing strategy was as important as the optimization work itself. [Read the full case study](/results/construction-seo-growth/).
**An optometry group in western Canada, Authority tier.** A multi-location eye care practice expanding from 3 to 6 clinics. The SEO challenge wasn't just ranking for optometry terms. It was managing the location expansion without cannibalizing existing rankings, building unique content for each location that wasn't thin duplicate content, and maintaining local SEO authority across a growing geographic footprint. The Authority tier investment matched the complexity of coordinating SEO strategy across multiple locations with overlapping service areas.
**A professional services firm, Starter tier.** An established firm with a decent domain but outdated website structure. The site had been built years ago and never updated for SEO. Technical audit found significant crawlability issues, duplicate content from pagination handling, and completely missing meta descriptions. Starter tier work fixed the technical foundation and optimized existing content. Traffic increased meaningfully without any new content production, purely from making the existing site visible to search engines.
30 active client engagements across SEO, Google Ads, and web optimization servicesSource: Choice OMG CRM, active managed services
The pattern across these engagements: the tier that works isn't determined by budget preference. It's determined by competitive reality. A business in a low-competition market can get strong results at the Starter tier. A business trying to compete in a crowded market needs Growth or Authority investment to move the needle. Underspending relative to competitive requirements wastes money on work that can't produce results at that investment level.
## Red Flags in SEO Proposals
We lose prospects to cheaper proposals regularly. Some of those prospects come back months later when the results didn't materialize. Here are the patterns we see in proposals that underdeliver:
**Guaranteed rankings.** No one can guarantee a specific ranking position. Google's algorithm considers hundreds of factors, many of which are outside any agency's control (competitor activity, algorithm updates, domain history). An agency that guarantees rankings is either being dishonest or using a definition of "guarantee" that includes enough caveats to be meaningless.
**Percentage-of-spend pricing for SEO.** This pricing model makes sense for ad management (where it also has problems, which we discuss in [Why We Don't Charge a Percentage of Ad Spend](/blog/why-flat-fees/)). For SEO, percentage-of-what pricing doesn't even have a logical basis. SEO doesn't have a media spend component. If an agency is charging a percentage of something for SEO work, ask what that something is.
**No baseline documentation.** Before you can measure improvement, you need to know where you started. An agency that doesn't document baseline metrics (current traffic, current rankings, current technical health) before starting work has no way to prove their impact. Any traffic growth could be seasonal, market-driven, or coincidental. Baselines make attribution possible.
**No strategy document.** "We'll optimize your website" is not a strategy. A strategy document specifies which keywords you're targeting and why, which pages you're optimizing or creating, what the competitive landscape looks like, and what success looks like at 3, 6, and 12 months. Without this document, there's no way to evaluate whether the work is on track.
**Vague reporting.** "Your traffic increased 15%" without context is not useful reporting. 15% compared to what period? Organic or total? Are the new visitors in your target geography? Are they landing on service pages or blog posts? Good reporting connects metrics to strategy and translates data into business implications.
## The Real Cost Equation
The monthly fee is the visible cost. The invisible cost is opportunity: what happens to your business over the 6-12 months of an engagement that doesn't produce results? The leads you don't get, the customers who find your competitor instead, the market position you don't establish.
The real gap between a $1,500/month engagement that works and a $1,000/month engagement that doesn't is the full value of the results the effective engagement produces, not the $500/month difference in fees. Spending less than a market requires wastes whatever gets spent, since that budget can't produce results at that investment level.
## How We Structure the First Conversation
When a business contacts us about SEO, we don't start with pricing. We start with four questions:
1. **What keywords matter to your business?** Not what you'd like to rank for. What do your customers actually search when they need what you sell? We validate this with search volume data, not assumptions.
2. **Who's already ranking?** We run a competitive analysis to see who occupies the top positions for those keywords, how long they've been there, what their content looks like, and what their backlink profile includes. This tells us the level of effort required to compete.
3. **What does your site look like today?** A technical audit reveals whether the foundation is sound or needs repair. The answer determines how much of the early engagement goes toward fixing problems versus building on strengths.
4. **What does success look like?** Not "more traffic," but specifically: what business outcomes would justify the investment? More phone calls? More form submissions? More revenue from a specific service line? This becomes the measurable goal the strategy targets.
The answers to these questions determine the tier recommendation. If the competitive analysis shows a moderately competitive local market with a technically sound site, Starter may be the right fit. If the analysis reveals 10 well-funded competitors with mature content strategies and strong backlink profiles, Authority is the minimum viable investment.
We'd rather lose a deal by being honest about what a market requires than win a deal by underselling the work and delivering disappointing results. That's why the conversation about SEO cost starts with competitive reality, not budget preference. What does your market actually require? What level of investment produces results at the scale you need? Those questions have data-driven answers, and we start every engagement by finding them.
Explore our [SEO services](/services/seo/) in detail, or read about our infrastructure approach to see how we monitor and protect SEO performance daily in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/).
---
## Google Ads vs Meta Ads: Where to Spend Your First Dollar
A law firm spending $3,000/month on Meta Ads was getting fake phone numbers and low-intent form fills. We pivoted their primary spend to Google Ads targeting high-intent searchers. The question isn't which platform is better; it's which one matches how your customers actually buy.
## The Law Firm With a Lead Quality Problem
A personal injury law firm in Western Canada was spending $3,000 per month on Meta (Facebook/Instagram) lead generation ads. The volume looked good on paper. Leads were coming in. The cost per lead was under $20. By the standard metrics most agencies report, the campaign was succeeding.
The firm's intake team told a different story. Of the 150+ leads per month, roughly 40% had fake phone numbers. Another 20% didn't remember filling out the form when contacted. Of the remaining 60 or so, only 8-12 had anything resembling a genuine legal need that matched the firm's practice areas, putting the effective cost per qualified lead over $250, not $20.
Meta's lead gen forms are designed to minimize friction. The form pre-fills with the user's Facebook profile information. One tap submits it. This is excellent for volume. It's terrible for lead quality in professional services, because the form requires so little effort that people submit it accidentally, out of curiosity, or without understanding what they're signing up for.
The firm tried adding custom questions to the Meta form to filter out low-intent submissions. This helped, reducing fake submissions by about 30%. But it also reduced total volume proportionally, and the remaining leads still had a high rate of "I don't remember doing that." They tried instant forms with SMS verification, which improved quality significantly but dropped volume to the point where cost per qualified lead exceeded what they were willing to pay.
| Metric | Meta Lead Gen Ads | After Google Ads Pivot |
|---|---|---|
| Monthly spend | $3,000 | $3,000 |
| Total leads | 150+ | 25-35 |
| Fake/invalid leads | ~40% | <5% |
| Leads who don't remember | ~20% | <3% |
| Qualified consultations | 8-12 | 12-18 |
| Cost per qualified consultation | $250+ | $170-$240 |
| Cost per retained case | $1,500+ | $600-$900 |
The pattern wasn't unique to this firm. We've seen the same lead quality problem with Meta lead gen ads across legal, medical, financial, and other professional services where the prospect needs to have genuine intent for the lead to be worth anything.
## The Pivot
We moved the firm's primary spend to Google Ads, targeting search campaigns for high-intent queries: "personal injury lawyer [city]," "car accident attorney near me," "slip and fall lawyer consultation." These queries represent people actively looking for legal help, not people scrolling through their Instagram feed who happened to see an ad.
The trade-off was immediate and expected: total lead volume dropped from 150+ to 25-35 per month. The cost per lead increased from $20 to $85-$120. Every surface-level metric looked worse.
But the metrics that matter to a law firm looked dramatically better. The 25-35 leads were people who had searched for a lawyer, read an ad, clicked through to a landing page, and voluntarily submitted their contact information. The qualification rate jumped. Fake phone numbers dropped to near zero. "I don't remember" calls essentially disappeared.
The firm retained more cases from 30 Google Ads leads than from 150 Meta leads. Revenue attributable to paid advertising increased. The intake team spent less time chasing dead leads and more time on actual consultations.
12-18 qualified consultations per month from Google Ads vs. 8-12 from Meta Ads at the same $3,000 monthly spendSource: Client intake data, anonymized
We didn't eliminate Meta entirely. We kept a smaller Meta budget running for retargeting: people who visited the firm's website but didn't convert. Retargeting warm audiences on Meta is a fundamentally different use case than cold prospecting, and it works well because the audience has already demonstrated intent by visiting the site.
## When Google Ads Wins
Google Ads captures demand. Someone types a query into Google because they need something. The ad appears in response to that expressed need. This is why Google Ads consistently outperforms Meta for services where the buyer has a specific, immediate problem to solve.
**Professional services.** Legal, medical, financial, and accounting services are searched for when someone has a need. "Dentist accepting new patients," "accountant for small business," "divorce lawyer consultation." These searches represent high intent. The person has identified their need and is actively seeking a provider.
**Emergency and urgent services.** Plumbing, HVAC, automotive repair, locksmith. When the furnace breaks at 10 PM, nobody scrolls Facebook looking for HVAC companies. They search Google. The Google Ads campaign that's running captures the demand at the moment it's most urgent and most likely to convert.
**Considered purchases.** Home renovations, dental implants, custom furniture, and other high-value services where the buyer researches before committing. The research starts with a search query. Google Ads positions you in front of the buyer during the research phase, when they're actively comparing options.
**Services people know they need.** If your target customer knows the name of the service they're looking for, they'll search for it. "Eye exam near me," "paving contractor," "landscape design." Google Ads captures this known-need demand efficiently.
The common thread: Google Ads works best when the customer has already identified their need and is looking for a provider. You're not creating awareness; you're capturing existing demand.
## When Meta Ads Wins
Meta Ads create demand. The ad appears in someone's feed and introduces a possibility they weren't actively considering. This is a fundamentally different marketing motion, and it's the right choice in specific situations.
**Visual products and services.** Aesthetics, fitness transformations, home renovations, fashion, and anything where the before-and-after tells the story. A dental practice showing cosmetic veneers results. A med spa showing skin rejuvenation results. A kitchen renovation company showing a dated kitchen transformed into a modern space. These images stop the scroll because the visual impact creates desire.
**Services people don't know they need.** Not everyone knows that a financial advisor could save them $10,000 in taxes. Not everyone knows that a custom closet system exists. Meta puts these possibilities in front of people who didn't know to search for them. Awareness advertising for services with no natural search demand.
**Local brand building.** A new restaurant, a just-opened gym, a recently launched e-commerce brand. When nobody knows you exist, there's no search demand to capture. Meta builds awareness within a geographic or demographic audience. Once people know you exist, they'll search for you later, and then Google Ads captures that demand.
**Retargeting warm audiences.** Someone visited your website, looked at a specific service page, but didn't convert. A Meta retargeting ad that follows them through their Instagram feed with a reminder or a specific offer can close the loop. This re-engages people who already showed interest, a warmer motion than cold prospecting.
**Before-and-after narratives.** Weight loss, cosmetic procedures, home transformations, fitness programs. The narrative format of Meta ads (carousel of before/after images, video testimonials, transformation stories) is built for this kind of content. Google Search can't convey a visual transformation in a text ad.
| Factor | Google Ads | Meta Ads |
|---|---|---|
| Buyer state | Active searcher | Passive scroller |
| Best for | Known-need services | Visual/aspirational services |
| Lead quality | High intent, lower volume | Lower intent, higher volume |
| Creative format | Text ads, extensions | Images, video, carousels |
| Attribution | Click-to-call/form, direct | Multi-touch, harder to attribute |
| Learning curve | Keyword + bid management | Audience + creative management |
| Cost per lead | Higher | Lower |
| Cost per qualified lead | Often lower | Often higher for professional services |
## The Framework We Use
When a new client asks "where should I advertise?" we don't start with platform preferences. We start with how their customers buy.
**Step 1: Map the buyer journey.** How do people discover they need this service? Do they search for it (Google) or do they need to see it (Meta)? A plumber's customer has a broken pipe and searches for help. A med spa's customer sees a friend's results and gets curious. Different journeys, different starting platforms.
**Step 2: Assess search volume.** We pull keyword data for the client's services in their geography. If there are 1,000+ monthly searches for relevant terms with commercial intent, Google Ads can capture that demand. If search volume is under 200 for all relevant terms, there may not be enough demand to capture, and awareness building through Meta makes more sense.
**Step 3: Evaluate creative assets.** Meta Ads require strong visual content. If the client has professional photos, video content, before-and-after documentation, and a visually compelling service, Meta is viable. If the service is functional rather than visual (accounting, legal, IT services), Google Ads usually performs better because the value proposition is communicated through information, not imagery.
**Step 4: Define the conversion action.** What does a successful lead look like? For a law firm, it's a qualified consultation with a real legal need. For a restaurant, it's a reservation or a first visit. The conversion definition determines which platform's lead quality model is acceptable. High-stakes conversions (legal, medical, financial) need high-intent leads. Lower-stakes conversions (restaurant visits, retail purchases) can tolerate lower-intent traffic.
24 Google Ads accounts and multiple Meta campaigns managed, giving us cross-platform comparison data across industriesSource: Choice OMG active client roster
**Step 5: Set budgets proportionally.** Most clients end up running both platforms, but with different budgets and different objectives. The typical split for a professional services client: 70-80% Google Ads (demand capture), 20-30% Meta (retargeting + brand awareness). For a visual/lifestyle business: 40-50% Meta (awareness + engagement), 50-60% Google (demand capture for known-need searches).
## The Mistake Most Businesses Make
The most common mistake is evaluating platforms on cost per lead alone. A $20 Meta lead and a $100 Google Ads lead are not comparable units. The $20 lead that never answers the phone or doesn't remember submitting the form costs infinitely more per acquisition than the $100 lead that books a consultation.
We've seen businesses abandon Google Ads because "leads cost $100 each" and move to Meta because "leads cost $15." Three months later, the business has 500 Meta leads in a spreadsheet and 4 actual customers. The math that looked efficient on a cost-per-lead basis is disastrous on a cost-per-customer basis.
The reverse mistake happens too. A lifestyle brand that should be running visual content on Instagram pours its entire budget into Google Search ads for generic keywords. The search volume isn't there, the text ads can't convey the visual appeal of the product, and the campaigns underperform because the platform doesn't match the buying behavior, regardless of how good the product is.
Platform selection is a starting point, refined over time as data accumulates. We start with the platform that matches the buyer journey, collect 60-90 days of conversion data, and adjust. Some clients end up 100% Google Ads. Some run a balanced split. A few are primarily Meta with Google Ads for brand protection and retargeting capture. The allocation follows the data, not a preference.
## What the Data Tells Us Across 24 Accounts
Managing 24 Google Ads accounts and multiple Meta campaigns across different industries gives us comparison data that a single-client perspective can't provide. Some patterns are consistent:
Professional services (legal, medical, dental, financial) almost always see better cost-per-qualified-lead from Google Ads. The intent gap is too large for Meta's volume advantage to overcome.
Home services (renovation, landscaping, paving) perform well on Google Ads for immediate-need queries and on Meta for project-inspiration content. The best results come from running both with different creative strategies.
Aesthetics and wellness (med spas, cosmetic dentistry, fitness) get the most value from Meta's visual format for awareness and Google Ads for capture when the prospect moves to active research.
B2B services rarely work on Meta outside of retargeting. Decision-makers don't make vendor selections from their personal Instagram feed.
These are patterns, not rules. Every client's data eventually tells its own story. But starting with the pattern that matches your industry saves 60-90 days of learning that the platform doesn't fit.
Read about our [Google Ads management approach](/services/google-ads/) or see results from a [real personal injury law campaign](/results/personal-injury-law/). For more on how pricing models affect budget recommendations, read [Why We Don't Charge a Percentage of Ad Spend](/blog/why-flat-fees/).
---
## Why We Don't Charge a Percentage of Ad Spend
Percentage-of-spend pricing incentivizes agencies to increase your spend. Flat monthly fees incentivize us to increase your results. We manage 24 Google Ads accounts on flat fees and have recommended reducing spend when the data supported it.
## The Incentive Problem
The most common Google Ads management pricing model is percentage of spend: the agency charges 10-20% of whatever you spend on ads each month. At first glance, this seems fair. You spend more, the agency does more work, so they earn more. The problem is in what it incentivizes.
An agency charging 15% of spend manages a client spending $20,000 per month. The agency fee is $3,000. The client asks: "Should we increase budget to $30,000?" The agency has two interests pulling in different directions. Their professional interest says: look at the data, determine if the marginal return on that additional $10,000 justifies the spend. Their financial interest says: that additional $10,000 produces an additional $1,500 in agency revenue.
| Monthly Ad Spend | Agency Fee (15%) | Agency Revenue Increase |
|---|---|---|
| $10,000 | $1,500 | Baseline |
| $20,000 | $3,000 | +$1,500 |
| $30,000 | $4,500 | +$3,000 |
| $50,000 | $7,500 | +$6,000 |
Every recommendation to increase spend is also a recommendation to increase the agency's own revenue, and every recommendation to decrease spend cuts it. These are structural incentives, not hypothetical conflicts, and they shape budget decisions month after month.
This doesn't mean every percentage-based agency gives bad advice. Many professionals act against their financial interest and recommend spend reductions when the data warrants it. But the pricing model creates a headwind against those recommendations. The honest recommendation costs the agency money.
## The Math That Changes Recommendations
Consider a concrete scenario. A home services company spends $15,000 per month on Google Ads. At $15,000, they get 75 leads at $200 cost per acquisition. The question on the table: should we increase to $20,000?
**Under percentage-of-spend pricing (15%):**
The agency currently earns $2,250/month. Increasing to $20,000 would earn them $3,000/month, a $750 increase. If the additional $5,000 in spend produces only 15 leads (marginal CPA of $333), the total CPA rises from $200 to $222. The campaign is less efficient, but the agency earns more. The recommendation to increase spend is financially rewarded regardless of whether it's strategically optimal.
**Under flat-fee pricing:**
The agency earns the same fee whether the client spends $15,000 or $20,000 or $10,000. The only thing that changes the agency's revenue is whether the client continues the engagement, which depends on whether results justify the investment. The agency is financially incentivized to give the recommendation that produces the best results, because that's what retains the client.
24 Google Ads accounts managed on flat monthly fees, with budget recommendations based solely on performance dataSource: Choice OMG CRM, active Google Ads management services
The inverse scenario is equally revealing. What happens when the data says "reduce spend"?
A seasonal business spends $8,000/month during peak season and the same during off-season. The data shows that off-season search volume drops 60% and cost per acquisition rises significantly. The optimal recommendation is to reduce off-season spend to $3,000-$4,000.
Under percentage pricing, that recommendation costs the agency $600-$750 per month for 4-5 months. That's $3,000+ in lost annual revenue per client. Multiply that across a book of business and the financial pressure against making the right call becomes substantial.
Under flat fees, the recommendation costs the agency nothing. The fee stays the same. The client gets better results because their budget is allocated to periods where it produces returns. The engagement is stronger because the client sees that budget recommendations are driven by data, not billing.
This isn't a subtle distinction. It changes the nature of every budget conversation. When a client asks "should we spend more?" and the answer is no, we can say so without internal conflict. When the answer is "yes, but only on search campaigns in your highest-converting geography," we can give that specific guidance without wondering whether we're leaving revenue on the table.
## What Flat Fees Look Like in Practice
We manage 24 Google Ads accounts on flat monthly fees. The fee reflects the complexity and scope of the management work: the number of campaigns, the sophistication of the bidding strategy, the volume of negative keyword management, the depth of search term analysis, and the frequency of reporting and strategy calls.
The fee does not change when spend goes up or down. If a client's business grows and they increase their ad budget from $10,000 to $25,000, our fee stays the same unless the scope of management work materially changes (more campaigns, new services, new geographies). If a client needs to pull back spend during a slow period, our fee stays the same and we help them optimize the reduced budget for maximum impact.
We've recommended reducing spend to clients when the data showed diminishing returns. A dental practice was spending across search and display campaigns. The display campaigns were generating impressions but negligible conversions at a high cost per click. We recommended reallocating the display budget to search and reducing total spend by 20%. Conversions stayed flat. Cost per acquisition improved. The client's total ad investment decreased while results held steady.
Under percentage pricing, that recommendation would have cost us revenue; under flat fees, it was simply the right call.
## Budget Monitoring at Scale
Flat-fee pricing also changes what we're willing to invest in monitoring infrastructure. When revenue doesn't depend on spend volume, we can invest in systems that keep spend disciplined.
Every 30 minutes budget pacing is verified across all managed accounts, 48 checks per account per daySource: Budget monitoring cron schedule
Our budget monitoring runs every 30 minutes, every day. For each of the 24 managed accounts, it compares current spend against the expected pace for that point in the month. When spend exceeds 110% of the expected daily run rate, an alert fires.
That's 48 verification cycles per day per account. Not a weekly check. Not a monthly review. Continuous monitoring that catches overspend risks within 30 minutes of them appearing.
This level of monitoring exists because budget discipline serves our clients' interests and doesn't conflict with ours. Under percentage pricing, an overspend produces more agency revenue. The financial incentive to build aggressive budget monitoring simply isn't there.
| Monitoring Approach | Check Frequency | Detection Time | Budget Overrun Risk |
|---|---|---|---|
| Monthly manual review | Once/month | Up to 30 days | High - overspend discovered after the fact |
| Weekly dashboard check | Once/week | Up to 7 days | Moderate - seasonal spikes can run unchecked for days |
| Daily automated check | Once/day | Up to 24 hours | Lower - but intraday spikes can still cause problems |
| Our approach | Every 30 minutes | Up to 30 minutes | Minimal - alerts fire before overspend becomes significant |
The monitoring feeds into our centralized data infrastructure. Budget data joins campaign performance data, conversion data, and competitive data in the same database. This means budget pacing is evaluated in context: not just "is spend on track?" but "is spend producing proportional results?"
Read how all this data comes together in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/).
## The Question That Ends Most Comparisons
When a prospect is evaluating us against a percentage-of-spend agency, one question usually clarifies the difference: "What happens when something breaks and nobody's watching?"
It's not a rhetorical question. Things do break. Conversion tracking goes dark and Smart Bidding optimizes against the wrong signal for a month. A seasonal spike hits and the daily budget cap isn't enough to prevent a monthly overspend. A landing page goes down and clicks keep flowing to a 404 error.
Under percentage pricing, an agency's revenue is protected by your spend continuing. The financial incentive is to keep the campaigns running. Under flat fees, our revenue is protected by your results continuing. The financial incentive is to catch problems fast, because problems that go undetected produce bad results, and bad results end engagements.
That's why we invest in infrastructure that watches things continuously:
- **Budget monitoring every 30 minutes** catches overspend before it becomes significant
- **Conversion pipeline monitoring** catches tracking breaks within hours instead of weeks
- **Site health checks daily** catch broken pages before clients see the impact in traffic
- **Anomaly detection on key metrics** flags unexpected changes for human review
This infrastructure has a cost. Engineering time, server resources, ongoing maintenance. Under percentage pricing, that cost competes with profit margin. Under flat fees, it's a retention investment: the systems that keep clients getting results are the systems that keep clients on retainer.
## When Percentage Pricing Makes Sense (And When It Doesn't)
We're not arguing that percentage-of-spend pricing is always wrong. For very large accounts spending $100,000+ per month, the management complexity genuinely scales with spend. More campaigns, more keyword groups, more geographic targets, more creative variations. In those cases, tying compensation to scale has logical underpinning.
For most businesses spending $3,000 to $30,000 per month on Google Ads, the management work doesn't scale linearly with spend. A $30,000/month account doesn't require twice the strategy, twice the keyword management, or twice the reporting of a $15,000/month account. It often uses the same campaign structures and strategies at higher budget levels. Percentage pricing in this range charges more without delivering proportionally more work.
The question to ask any agency, regardless of pricing model: "In the last 12 months, have you recommended a spend reduction to any client?" If the answer is no, either every single client had perfectly optimized spend (unlikely) or the pricing model created a barrier to making that recommendation (very likely).
We've made that recommendation multiple times. We'll make it again whenever the data supports it. Our fee doesn't change, so our advice doesn't have a financial filter.
## What Clients Actually Experience
The pricing model isn't just a philosophical position. It changes the day-to-day client experience in specific ways.
**Budget conversations are about performance, not billing.** When we review monthly results, the discussion covers what the data shows and what we recommend adjusting. The client doesn't need to wonder whether a budget increase recommendation benefits them or the agency. The answer is always: it only helps if the data supports it.
**Seasonal adjustments happen naturally.** Businesses with seasonal demand patterns need their ad spend to flex. A landscaping company should spend more in spring and less in winter. Under flat fees, we make these adjustments based purely on when spend produces results. The January recommendation to drop from $6,000 to $2,000 costs us nothing, so we make it without hesitation.
**Scope expansions are transparent.** If a client adds a new service line that needs its own campaigns, and the management complexity genuinely increases, we discuss a fee adjustment based on the actual work involved. The conversation is about scope, not about how much more they're spending on ads. A client who doubles their ad spend on existing campaigns doesn't see a fee increase, because the management work didn't change.
**There's no penalty for efficiency.** If we improve Quality Scores and reduce cost per click, the client's spend drops while results stay the same. Under percentage pricing, that efficiency improvement would reduce agency revenue, creating a perverse disincentive. Under flat fees, efficiency gains are simply good work that strengthens the engagement.
These are the practical result of removing the financial conflict between the agency's revenue and the client's best interest, not abstract theory. The alignment isn't perfect in any model, but flat fees remove the most common and consequential source of misalignment in ad management.
See our [Google Ads management services](/services/google-ads/) for how we structure engagements, or read a [case study from a real automotive Google Ads engagement](/results/automotive-google-ads/) to see flat-fee management in action.
---
## What Happens When Conversion Tracking Breaks (And Nobody Notices)
A conversion tracking break that goes undetected for 30 days wastes an entire month of ad spend optimization. Google Ads Smart Bidding needs conversion data to work. When that data stops flowing, the algorithm optimizes for the wrong signals, and performance degrades quietly. Automated pipeline audits catch breaks within hours.
## The Conversion Pipeline
Before we talk about what breaks, you need to understand the chain. Modern Google Ads conversion tracking isn't a single connection. It's a four-step pipeline, and every step has to work for the data to flow.
**Step 1: Website.** A visitor takes an action you care about. They submit a contact form, click a phone number, complete a purchase, or book an appointment. The website needs to recognize that this happened and communicate it.
**Step 2: Google Tag Manager (GTM).** A tag fires in response to the action. GTM watches for specific triggers, like a form submission event or a button click, and sends the event data to GA4. The tag needs to be configured correctly, the trigger needs to match the actual on-page behavior, and the container version needs to be published.
**Step 3: Google Analytics 4 (GA4).** GA4 receives the event and records it. For the event to count as a conversion in Google Ads, it needs to be marked as a "key event" in GA4's configuration. The event name needs to match what GTM sends, and the GA4 property needs to be linked to the correct Google Ads account.
**Step 4: Google Ads.** Google Ads imports conversions from GA4. This import has a natural lag of 24 to 72 hours. Once imported, Smart Bidding uses the conversion data to optimize bids, shifting budget toward the keywords and audiences that produce conversions.
| Pipeline Step | Owner | Typical Lag | Break Visibility |
|---|---|---|---|
| Website | Developer / CMS | Immediate | Low - site looks normal |
| GTM | Marketing / Developer | Immediate | None - no user-facing change |
| GA4 | Marketing | Minutes | Low - requires checking GA4 real-time reports |
| Google Ads Import | Automated | 24-72 hours | Low - conversion column just shows zero |
The critical insight: when any step in this chain breaks, nothing downstream throws an error. The website still loads. GTM still loads. GA4 still receives pageview events. Google Ads still runs campaigns. The only signal is an absence: conversions stop appearing. And absence is the hardest kind of signal to notice.
This makes conversion tracking breaks fundamentally different from site outages or ad disapprovals. Those failures generate alerts, error messages, and visible symptoms. A tracking break produces silence. And silence gets noticed only when someone asks the right question at the right time.
## Five Ways Tracking Breaks
These aren't theoretical failure modes. We've seen each of these across our client base.
### 1. GTM Container Version Conflict
Two people have access to Google Tag Manager. Person A makes changes to a tag and saves a workspace but doesn't publish. Person B publishes a different workspace, which creates a new container version that doesn't include Person A's changes. Person A's tracking breaks without either person realizing it.
This is the most common tracking break we encounter. GTM's versioning system is powerful but unforgiving. There's no merge conflict resolution like in code version control. Publishing one workspace simply overwrites the live container with that workspace's state.
**Detection window without monitoring:** Typically 30+ days, discovered when the monthly report shows a conversion drop.
### 2. GA4 Key Event Reconfiguration
Google has renamed this concept twice (Goals to Conversions to Key Events), and the settings interface has moved each time. A well-meaning team member goes into GA4 to investigate a report, accidentally toggles a key event off, or marks a different event as key. GA4 still records the events, but they no longer flow to Google Ads as conversions.
This one is subtle because GA4's own reports still show the event data. It's only the conversion import to Google Ads that stops. If you're only checking GA4, everything looks fine.
### 3. Form Plugin Update Changes Element IDs
A WordPress form plugin updates from version 3.x to 4.x. The update changes the CSS class names and element IDs used by the form. GTM triggers that relied on matching those element IDs or class names stop firing. Forms still submit successfully. Leads still arrive in the inbox. But the tracking event never fires, so the conversion is invisible to analytics.
This is common with popular form plugins like Contact Form 7, Gravity Forms, and WPForms. Major version updates frequently restructure the DOM elements that GTM relies on for trigger matching. The form works perfectly from the user's perspective. Leads still arrive. The business owner has no reason to suspect anything is wrong. The only thing that stopped working is the invisible measurement layer.
### 4. Tag Firing Conditions Change
A Google Ads campaign links to a landing page at `/services/plumbing`. The GTM trigger is configured to fire the conversion tag when a form submission occurs on pages matching `/services/*`. A site redesign moves the services pages to `/our-services/*`, so the trigger no longer matches and the tag stops firing.
No error. No notification. The pages work perfectly. The forms submit correctly. The data just stops flowing.
### 5. GA4-to-Google Ads Link Breaks
The link between GA4 and Google Ads can break when someone removes and re-adds a Google Ads account connection, when GA4 property ownership changes, or when the linked GA4 property gets migrated to a different measurement ID. The link configuration lives deep in GA4's admin settings, and breaks here are invisible from the Google Ads side.
## The Cost of 30 Days Blind
The math makes this consequential.
Assume a business spends $5,000 per month on Google Ads and gets 50 conversions per month at a $100 cost per acquisition. Smart Bidding uses those 50 conversion data points to decide which searches to bid on and how much to bid.
When conversion tracking breaks:
**Days 1-7:** Smart Bidding sees conversions drop. It doesn't know tracking is broken, so it assumes the campaigns have gotten worse. It starts adjusting: testing different keywords, shifting budget, changing bid levels. These adjustments are based on a false premise.
**Days 8-14:** Smart Bidding has now spent a full week learning the wrong lessons. It has moved budget away from keywords that were converting (it can't see the conversions) and toward keywords that generate clicks but may not convert. Cost per click may actually decrease, which masks the problem if you're only watching surface metrics.
**Days 15-30:** The algorithm has fully recalibrated to optimize for engagement signals rather than conversions. The campaigns are running, money is being spent, but the targeting is systematically wrong. The $5,000 in spend this month is generating significantly fewer actual conversions than it should.
**Days 31-60 (recovery):** The tracking gets fixed. Smart Bidding starts receiving conversion data again. But Smart Bidding has spent a month learning the wrong patterns. It needs 2-4 weeks of clean data to recalibrate. During this recovery period, performance gradually improves but hasn't returned to its pre-break baseline. The total impact: two months of suboptimal performance from a single break.
$5,000+ in wasted ad spend is the typical cost of one month of undetected conversion tracking failureSource: Calculated from average client monthly spend and Smart Bidding recalibration timeline
Now add the recovery period. Once tracking is fixed, Smart Bidding needs another 2-4 weeks of accurate data to recalibrate. That's two months of degraded performance from a single break that could have been caught in hours.
For larger accounts spending $15,000 or $20,000 per month, the cost multiplies proportionally. And these breaks don't announce themselves. They sit quietly while the algorithm learns incorrect patterns.
## How We Catch It
Detecting a tracking break requires monitoring the pipeline at multiple points, not just checking whether the campaigns are running.
### Daily Data Sync Comparisons
Our gads-sync pipeline pulls conversion data from Google Ads every six hours. Our webopt-data-sync pulls GA4 event data daily. When conversions appear in GA4 but not in Google Ads, or when form submissions appear in the CRM but not in GA4, the discrepancy points to a specific break in the pipeline.
This comparative approach is what makes the monitoring effective. A single data source can only tell you what it sees. Comparing across data sources reveals what's missing.
### Playwright End-to-End Tests
For clients where conversion tracking is critical, which is most of them, we run end-to-end tests that simulate the actual user journey: load the page, fill out the form, submit, and verify that the expected GTM tags fire and the expected GA4 events are recorded. These tests run in a real browser engine, which means they test the same code path that actual visitors use.
When a form plugin update changes element IDs, the end-to-end test fails because the form interaction no longer triggers the expected events. We see the failure before it impacts real conversion data.
### GTM Version Tracking
Our monitoring tracks the active GTM container version. When the version number changes, we get a notification. This doesn't prevent container version conflicts, but it ensures we know when changes are published and can verify that tracking still works after each publish.
### Conversion Volume Anomaly Detection
Beyond comparing data sources, we monitor conversion volume trends. If an account typically records 2-3 conversions per day and suddenly drops to zero, the anomaly detection flags it. This catches even the breaks that don't show up as cross-source discrepancies, like a complete tracking failure where no data flows to any system.
## What This Means in Practice
The monitoring infrastructure described above exists because conversion tracking breaks are not rare events. They're regular occurrences in any environment where multiple people touch the website, the CMS, GTM, or GA4. The question is never whether tracking will break. The question is how quickly you'll know about it.
The difference between catching a break in 6 hours and catching it in 30 days is not marginal. It's the difference between losing a morning of conversion data and losing a month of campaign performance plus a month of recovery.
Every dollar of ad spend assumes that the feedback loop works. That the system can see what's converting and optimize toward it. When the feedback loop breaks silently, the dollars keep flowing but the optimization stops. Automated monitoring is how you keep the feedback loop intact.
## The Broader Tracking Landscape
The conversion pipeline described above covers the most common setup: website form submissions tracked through GTM and GA4 into Google Ads. But modern businesses have multiple conversion types, each with their own tracking requirements.
**Phone calls.** Call tracking requires either dynamic number insertion on the website or Google forwarding numbers in ads. Both can break independently of form tracking. A website redesign that doesn't include the call tracking script loses phone conversion data. Google forwarding numbers that get removed from ad extensions lose call conversion attribution.
**Chat interactions.** Businesses using live chat or chatbot tools need those interactions tracked as conversions. The chat widget loads via JavaScript, which means it's subject to the same script-loading failures and GTM trigger issues as form tracking.
**E-commerce transactions.** Revenue tracking adds another layer of complexity. The purchase event needs to include the transaction value, and that value needs to flow correctly through GTM to GA4 to Google Ads. A mismatch in currency formatting, a missing data layer variable, or a change to the checkout page template can all break revenue reporting without breaking the checkout itself.
Each conversion type adds another potential break point. The more complex the tracking setup, the more valuable automated monitoring becomes. Manual verification of every conversion type across every page at every GTM version change simply doesn't scale.
Catching broken tracking is a core part of our [conversion optimization](/services/conversion-optimization/) program; you can't improve what you can't measure.
The infrastructure investment we've made in monitoring isn't about any single scenario. It's about the recognition that tracking breaks are a permanent, ongoing risk in any marketing technology stack. The question isn't whether to invest in monitoring. It's whether you'd rather catch breaks in hours or discover them in hindsight.
See how our monitoring infrastructure works across all channels in [What Breaks at 2 AM](/blog/what-breaks-at-2am/). Learn about our [Google Ads management approach](/services/google-ads/) and see results from a [real automotive Google Ads engagement](/results/automotive-google-ads/).
---
## Why We Built a Single Source of Truth for Client Data
All performance data for all clients flows into one PostgreSQL database. When we say a number, we can trace it back to the original API response. This architectural decision is why our reports are trustworthy and our problems get diagnosed quickly.
## The Problem With Scattered Data
At most agencies, client data lives scattered across disconnected tools. The Google Ads manager has their data in the Google Ads interface and maybe an exported spreadsheet. The SEO team has their data in SEMrush dashboards and Google Search Console. The web team has their data in GA4. The account manager has a slide deck from two weeks ago with numbers that may or may not match any of the above.
A client asks: "Is our organic traffic up or down?" The SEO team checks GA4 and says up 8%. The account manager checks the last report and says up 12%. The discrepancy exists because they're looking at different date ranges, different filters, or different comparison periods. Neither number is wrong, exactly. But the client has now lost confidence in both.
This problem compounds with scale. At 5 clients, you can keep track of which spreadsheet has the latest numbers. At 30 clients across Google Ads, SEO, and web optimization, scattered data becomes a structural risk. Someone will report a wrong number. Someone will miss a trend because they were looking at the wrong dashboard. Someone will make a strategy recommendation based on stale data.
The problem isn't people being careless. It's that scattered data systems make correctness impossible to guarantee. When the same metric can be queried in three different tools with three different default date ranges and three different attribution models, discrepancies aren't bugs. They're a feature of the architecture. The only way to eliminate them is to change the architecture.
We built Thor to make this problem impossible.
## Three Authorities, Zero Overlap
The first design decision was defining clear boundaries. Not everything goes in the database. Three systems each own specific types of information, and their responsibilities don't overlap.
| Authority | What It Answers | What It Does NOT Answer |
|---|---|---|
| Thor (PostgreSQL database) | How is performance trending? What are the numbers? What happened on this date? | Who is this client? What services do they pay for? What's the strategic direction? |
| CRM | Who are our clients? What services are active? When was the last communication? | What are the traffic numbers? How is the campaign performing? |
| Strategy documents | What are we trying to achieve? What keywords are we targeting? What's the competitive positioning? | What are the actual performance metrics? Who's the billing contact? |
This separation is enforced, not suggested. When someone needs performance data, they query Thor. When someone needs client context, they check the CRM. When someone needs strategic direction, they read the strategy document. There's exactly one place to look for any given question.
The benefit isn't just organizational tidiness. It eliminates an entire category of errors: the error that comes from updating data in one place but not another. If traffic data only lives in Thor, there is no second copy anywhere else that could say something different, so the database can't disagree with a spreadsheet that doesn't exist.
## Four Pipelines, One Destination
Thor receives data from four independent pipelines, each with its own schedule, its own failure handling, and its own data domain.
### gads-sync: Google Ads Data (Every 6 Hours)
This pipeline connects to all 24 managed Google Ads accounts and pulls campaign metrics, keyword performance data, search term reports, ad group statistics, Quality Score components, and auction insights. The sync runs every six hours, producing roughly 53,000 data points per day.
The pipeline handles each account independently. If one account's API call fails (expired token, temporary API error), the other 23 accounts still sync successfully. Failed accounts are logged and retried on the next cycle.
### webopt-data-sync: Organic Performance (Daily)
This pipeline pulls GA4 traffic metrics (sessions, bounce rates, page-level performance), Google Search Console data (impressions, clicks, average position by query and page), and PageSpeed scores (Core Web Vitals, Lighthouse scores). It runs once daily because these metrics don't change at the granularity that would justify more frequent pulls.
Each data source within the pipeline operates independently. A GA4 authentication failure doesn't prevent Search Console data from syncing. This independence is a deliberate design choice: partial data is better than no data, and a failure in one source shouldn't cascade into a gap across all sources.
### semrush-data-sync: SEO Intelligence (Mixed Schedule)
SEMrush data syncs on three cadences matched to how quickly each metric type changes:
- **Daily:** Position tracking for 1,000+ keywords, visibility scores, competitor rank movements
- **Weekly:** Backlink profile changes, referring domain counts and quality, site audit health scores and issue counts
- **Monthly:** Domain analytics, authority score trends, organic traffic estimates, competitive landscape analysis
1,000+ keyword positions tracked daily via SEMrush Position TrackingSource: semrush-data-sync daily pipeline, position tracking dataset
### Budget monitoring (Every 30 Minutes)
The highest-frequency pipeline. Every 30 minutes, it checks current spend levels across all managed Google Ads accounts against their monthly budgets. This produces roughly 3,744 data points per day (24 accounts, 48 checks, multiple metrics per check).
All four pipelines write to Thor. Each pipeline has its own set of tables, its own schema, and its own data lifecycle. But they all share the same database instance, which means cross-pipeline queries are straightforward. Want to compare organic traffic trends against paid spend changes? It's a SQL join, not a spreadsheet merge. Want to see if a keyword position improvement in SEMrush data correlates with a Google Search Console traffic increase for the same page? That's a query against two tables with a shared client identifier and date column.
This cross-pipeline analysis is where the real strategic value emerges. Individual data sources tell you what happened within their domain. Combined data tells you why.
## The Raw Snapshot Archive
This is the piece that makes Thor more than a reporting database.
Every time a pipeline pulls data from an API, it stores two things: the processed, structured data that goes into the normal reporting tables, and the raw API response as a write-once JSONB record in the `raw_snapshots` table.
The raw snapshot is never modified after it's written. It preserves the exact response the API returned at that moment. This creates an audit trail that goes all the way back to the source.
Why this matters:
**Debugging discrepancies.** When a number in a report doesn't match what a client sees in their own Google Ads dashboard, we can pull the raw snapshot from the date in question and compare it against the structured data. If the structured data differs from the raw snapshot, we have a processing bug to fix. If the raw snapshot matches our report, the discrepancy is in the dashboard's date range or filter settings. Either way, we can resolve it with evidence, not guesswork.
**Detecting retroactive changes.** Google Ads can retroactively adjust conversion numbers as attribution data comes in. If we pull campaign data on the 15th and again on the 30th, the numbers for the same date range may differ. With raw snapshots from both pulls, we can see exactly what changed and understand why the month-end report doesn't match the mid-month check. This is expected behavior, but without the snapshot archive, it looks like someone changed the numbers.
**Historical context for new team members.** When someone new takes over an account, they can see not just the current state but the full history. Not just the processed metrics, but the raw data that produced them. This matters when trying to understand why a strategy change was made six months ago. The data that informed the decision is preserved, not just the result.
80+ tables with write-once raw snapshots preserving original API responses indefinitelySource: Thor database schema on thor3
## What This Means for Clients
The infrastructure described above is invisible to clients in their daily interactions with us. They see reports, strategy documents, and recommendations. But the quality of all those outputs depends on the data underneath them.
**Numbers never conflict.** When a monthly report says cost per acquisition decreased 15%, that number came from one query against one database. There's no possibility of a different team member running a different query and getting a different answer. The number is the number.
**Problems surface faster.** Because four pipelines are writing data continuously, a sudden change in any metric gets noticed quickly. A conversion drop, a traffic spike, a budget anomaly. These appear in the data within hours, not in the monthly report review weeks later. Read about specific failure scenarios in [What Breaks at 2 AM](/blog/what-breaks-at-2am/).
**Historical data is always available.** We don't age out data. We don't overwrite last month's numbers with this month's. When a client asks how this quarter compares to the same quarter last year, the data is there. When a strategy review needs to reference the baseline from the start of the engagement, the baseline is there.
**Reports are reproducible.** Run the same query with the same parameters twice and you get the same answer. This sounds obvious, but it's not the norm in environments where reports are built from dashboard screenshots and spreadsheet exports. Those artifacts change every time the underlying data refreshes. Our reports are queries, and queries against immutable data produce deterministic results.
## Why Competitors Can't Easily Replicate This
Building a centralized data infrastructure isn't a feature you bolt on. It's a foundational decision that shapes how everything else works.
**Custom sync engines.** Each pipeline is a purpose-built synchronization engine. gads-sync understands the Google Ads API's pagination, rate limits, and data freshness characteristics. semrush-data-sync handles SEMrush's three different cadences and API-specific quirks. These aren't off-the-shelf connectors. They were built for this specific purpose, tested against real data at real scale, and refined over months of production use.
**Unified schema.** The 80+ tables in Thor follow a consistent schema design. Client identifiers match across tables. Date fields use the same conventions. Metric definitions are standardized. This consistency is what makes cross-pipeline queries possible, and it's the result of deliberate design work, not a natural outcome of connecting APIs to a database.
**Months of historical backfill.** When we add a new data source or a new metric, we backfill historical data where possible. This means the database contains not just current data but a usable history from the start of each engagement. Backfilling takes time and careful validation, and it stays an ongoing investment as data sources evolve and API schemas change.
**Engineering investment.** The monitoring infrastructure, the pipeline error handling, the raw snapshot archive, the anomaly detection, the budget alerting: each of these represents significant engineering work. An agency that decides today to build this capability is months away from having it operational, and years away from having the historical depth that makes it valuable.
This isn't an argument that technology is a substitute for strategy or execution. It's an observation that reliable data infrastructure makes strategy and execution measurably better. Every recommendation is grounded in data you can verify. Every report is reproducible. Every problem is diagnosable. Those properties come from the architecture, and the architecture takes time to build.
## The Decision to Build vs. Buy
We considered third-party data aggregation tools before building Thor. Platforms like Supermetrics, Funnel.io, and Agency Analytics offer data connectors that pull from multiple sources. We chose to build our own for specific reasons:
**Schema control.** Third-party tools normalize data into their own schemas, which means you lose source-specific nuance. Google Ads search term reports and SEMrush keyword position data have different semantics even when they both contain "keyword" and "position" columns. Controlling the schema lets us preserve those distinctions.
**Raw snapshot preservation.** No off-the-shelf tool we evaluated offered write-once raw response archival. They process and normalize the data, which is useful for reporting but eliminates the audit trail connecting a report number to the response that produced it.
**Pipeline independence.** Most aggregation tools run all data pulls as a single scheduled job. If the job fails, everything fails. Our architecture isolates each pipeline and each client within each pipeline, so failures are contained and specific.
**Custom alerting logic.** Budget pacing alerts at 110% of expected daily spend, conversion volume anomaly detection, cross-source discrepancy flagging: these are business-specific rules that don't map cleanly to generic alerting frameworks.
The tradeoff is real: we maintain the sync engines, handle API changes, and manage the database infrastructure ourselves. That's ongoing engineering work. But the result is a data foundation that's exactly what we need, not an approximation of it.
Learn how all this data comes together in our daily monitoring in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/). Learn more [about our team](/about/) and explore our [full service offerings](/services/).
---
## The Automation Stack: How n8n and MCP Run Our Marketing Operations
A 12-person team managing 30 clients requires significant automation. We use n8n for workflow automation and MCP (Model Context Protocol) for AI-assisted content and reporting, with 240+ tools across three MCP servers.
## The Scale Problem
We manage 30 active clients. Each client has some combination of SEO, Google Ads, web optimization, and content marketing. A typical managed client generates daily position tracking data, weekly search term reports, monthly performance summaries, and quarterly strategy reviews. Across the portfolio, that's hundreds of data collection tasks, dozens of report generation tasks, and a constant stream of monitoring and alerting that runs 24/7.
If every task required manual execution, the math doesn't work. Checking budget pacing for 24 Google Ads accounts manually takes an analyst several hours. Pulling keyword position data for every client takes longer. Generating monthly reports by hand, with data from multiple sources that needs to be cross-referenced, takes days. Monitoring 21 websites for errors, broken images, and performance regressions would be a full-time job by itself.
30 active clients managed by a 12-person team, enabled by automation that handles data collection, monitoring, and report assemblySource: Choice OMG CRM, active client roster
We don't solve this by hiring proportionally. We solve it by automating the work that should be automated and focusing human expertise on the work that requires judgment. The line between those two categories is specific and deliberate. We've been refining it for 15+ years.
The automation stack has two primary components: n8n handles event-driven workflow automation, and MCP (Model Context Protocol) provides AI assistants with structured access to our tools and data.
## n8n: Workflow Automation
n8n is an open-source workflow automation platform. We run it on our own infrastructure, not on a SaaS plan. This matters because marketing automation workflows handle client data, API credentials, and lead information. Keeping that on infrastructure we control is a security and compliance decision, not a technical one.
The workflows handle the repetitive operational tasks that connect our systems.
### Lead Attribution
When a form submission arrives from a client's website, a chain of events needs to happen: identify which client it belongs to, determine the source (organic, Google Ads, Meta, direct), extract UTM parameters, create a CRM activity record, and notify the account manager.
Without automation, this is a manual process. Someone checks the form submission, looks up the client, checks the UTM parameters, logs into the CRM, creates a record, and sends a message to the account manager. That's 5-10 minutes per lead, and for clients that generate 20+ leads per month, it adds up to hours of administrative work.
Our n8n workflow handles this in seconds. The form submission triggers the workflow. n8n parses the UTM parameters from the form data, identifies the client based on the form source, creates the CRM activity with full attribution data, and posts the update to the appropriate team channel, so the account manager sees the lead with its source, campaign, and keyword already attached, with no manual data entry and no attribution gaps.
For Google Ads leads specifically, the workflow parses the GCLID from the UTM parameters, which connects the lead to the specific keyword and ad that produced it. This attribution data feeds back into our campaign optimization process. When we can see that a specific keyword produced 8 qualified leads this month and another keyword produced 2, the budget allocation decision is data-driven rather than intuitive.
### Form Routing
Different clients have different lead handling requirements: some want leads delivered via email, some want them in their CRM, some want a text message to the business owner, and some want all three routed at once.
n8n workflows handle the routing logic. Each client has a routing configuration that specifies where leads go and what information to include. When the configuration changes (a client adds a new team member who should receive notifications, or a client switches CRM systems), we update the workflow, not the website form.
This separation of concerns is important. The website form collects the data. The workflow decides what to do with it. Changes to routing don't require website changes, and website changes don't affect routing.
### Notification Workflows
Beyond lead routing, n8n handles operational notifications.
**Budget alerts.** When our budget monitoring detects an account pacing to overspend, the alert goes through n8n. The workflow determines severity (warning vs. critical), identifies the account manager, and delivers the alert to the right channel. Critical alerts escalate to the team lead.
**Health check failures.** When our Playwright health checks detect a site issue (broken images, console errors, SSL problems, 404 pages), the failure report routes through n8n. The workflow includes context: which site, what failed, when it last passed, and a screenshot of the error. The assigned web developer gets a notification with everything they need to start investigating immediately.
**Campaign status changes.** When a Google Ads campaign's status changes (paused, budget-limited, disapproved ads), n8n routes the notification to the campaign manager. The workflow includes the reason for the change and links to the relevant Google Ads interface page.
## MCP: AI-Assisted Operations
MCP (Model Context Protocol) is a standard for connecting AI assistants to external tools and data sources. Instead of having AI generate analysis from general knowledge, MCP gives AI structured access to our actual data and systems. The AI can query our database, pull specific reports, and access platform APIs through defined tool interfaces.
We run three MCP servers, each providing a set of tools for a specific domain.
240+ MCP tools across three servers for data access, SEMrush intelligence, and Google Ads managementSource: MCP server tool counts: data-studio (62), sem-rush (32), google-ads (146)
### Data-Studio MCP (62 Tools)
This server exposes our centralized reporting database through defined tool calls. The tools cover:
- **Performance reporting.** Pull traffic, conversion, and ranking data for any client and date range. The reports are pre-structured to answer specific questions: "How did this client's organic traffic trend month-over-month?" rather than "Give me all the data."
- **Anomaly detection.** Identify unexpected changes in key metrics. Rolling statistical analysis flags when a metric deviates significantly from its historical pattern.
- **PageSpeed monitoring.** Pull Core Web Vitals scores and Lighthouse results for any managed site.
- **Validation tools.** Verify that data pipelines are running correctly and that client configurations are complete before generating reports.
The tools are read-only. The AI can pull and analyze data. It cannot modify data, delete records, or change configurations. This constraint is deliberate: data integrity in the centralized database is critical, and write access is restricted to the automated pipelines.
### SEMrush MCP (32 Tools)
This server wraps the SEMrush API with tools for competitive intelligence:
- **Domain analytics.** Pull organic and paid search metrics for any domain. Useful for competitive analysis: "What keywords is this competitor ranking for that we're not?"
- **Position tracking.** Access keyword position data across all tracked campaigns. 1,000+ positions tracked daily across the client portfolio.
- **Backlink analysis.** Review referring domains, anchor text distribution, and new/lost backlink trends.
- **Keyword research.** Pull keyword difficulty, search volume, and SERP features for target keywords.
### Google Ads MCP (146 Tools)
This is the largest server by tool count because Google Ads has the most granular management surface:
- **Campaign management.** Review and adjust campaign settings, budgets, bidding strategies, and geographic targeting.
- **Keyword management.** Pull keyword performance, add negative keywords, adjust bids, and review Quality Score components.
- **Ad management.** Review ad performance, pause underperforming ads, and access ad strength signals.
- **Reporting.** Pull detailed performance reports at campaign, ad group, keyword, and search term levels.
- **Conversion tracking.** Review conversion action configurations, verify tracking pipeline status.
The Google Ads tools include both read and write capabilities. An AI assistant can recommend a bid adjustment and, with human approval, execute it through the MCP tool. But the workflow always includes a human review step. The AI drafts the action. A specialist reviews and approves it.
## What We Automate vs What We Don't
The line between automated and human work is specific and intentional. We've refined it over years of managing client campaigns, and it reflects a clear principle: automate the execution, keep human judgment on the decisions.
| Automated | Human |
|---|---|
| Data collection from APIs | Strategy decisions |
| Budget pacing alerts | Budget change recommendations |
| Report assembly and formatting | Report analysis and commentary |
| Notification routing | Client communication |
| Health check execution | Issue diagnosis and resolution |
| Search term report pulling | Negative keyword decisions |
| Position tracking data collection | Competitive response strategy |
| Lead attribution tagging | Lead qualification and follow-up |
| Anomaly detection flagging | Root cause analysis |
| Content data retrieval | Content creation and editing |
The distinction is practical, not philosophical. Automation handles tasks where the correct action is deterministic: if X happens, do Y. A form submission arrives, route it to the CRM. Budget pacing exceeds threshold, send an alert. A health check fails, notify the developer.
Human judgment handles tasks where the correct action depends on context. Should we increase this client's budget? That depends on their business goals, seasonal patterns, competitive landscape, and capacity to handle more leads. No automation handles that decision, because the variables aren't fully quantifiable and the trade-offs require understanding the client's business.
The AI-assisted layer (MCP) sits between pure automation and pure human judgment. It accelerates human work by pulling relevant data, identifying patterns, and drafting analyses. But the output goes through human review. A brief generated with MCP tools is reviewed and edited by a specialist before it reaches a client. A keyword analysis pulled through MCP is interpreted by a strategist who understands the competitive context.
## Why This Matters for Clients
The automation stack isn't a product we sell. Clients don't interact with n8n or MCP directly. But the infrastructure shapes their experience in measurable ways.
**Lower overhead per client means more specialist time on strategy.** When data collection, report assembly, and notification routing are automated, the 12-person team spends its time on analysis, strategy, and client communication. The ratio of strategic work to administrative work is much higher than it would be without automation. This means each client gets more thoughtful attention, not just more hours.
**Faster response to issues.** Automated detection combined with human resolution means issues get identified in minutes or hours, not days or weeks. A broken conversion tracking tag gets caught by the automated audit and flagged to the campaign manager, who can investigate and fix it the same day. Without automation, that break sits undetected until someone manually checks, which might happen next week or next month.
12-person team managing 30 clients, with automation handling data collection, monitoring, and report assemblySource: Choice OMG team roster and client count
**Consistent execution across all accounts.** Automation doesn't have off days. Budget monitoring runs every 30 minutes for every account, every day. Health checks run every day for every site. Position tracking runs daily for every client. There's no variance in execution quality between the first account checked and the last, because the checking is automated.
**The infrastructure scales; the expertise stays focused.** Adding a new client to our monitoring infrastructure means adding their accounts to existing pipelines, not hiring additional staff. The marginal cost of monitoring one more client is a configuration change, not a headcount change. This means we can grow the client roster without diluting the expertise available to each client.
The alternative is what most agencies do: hire proportionally as they grow, spreading junior staff across more accounts with less oversight. The automation approach keeps senior specialists involved across all accounts because the administrative burden is handled by systems rather than people.
## The Build vs. Buy Decision
We built most of this infrastructure ourselves. n8n is open-source, but the workflows are custom. The MCP servers are custom-built against the APIs we use. The monitoring pipelines are custom. The centralized database schema is custom.
We could have assembled a stack of SaaS tools: Zapier for workflows, third-party reporting dashboards, commercial monitoring services. We chose to build because the integration quality between custom components is higher than what you get from connecting SaaS tools through their public APIs. Our n8n workflows talk directly to our database. Our MCP tools query the same centralized data that our reports use. Everything shares the same source of truth.
The trade-off is maintenance cost. We maintain all of this infrastructure ourselves. When an API changes, we update the integration. When a client has a unique requirement, we build the workflow. This is engineering work that most agencies don't do, and it's a deliberate investment in operational capability that compounds over time.
This automation layer is what makes our [AI-powered marketing stack](/services/ai-marketing/) practical at scale across 30 clients.
Every workflow we build, every monitoring pipeline we deploy, every MCP tool we add, reduces the per-client cost of the next client. The infrastructure scales because it's designed to. And the clients benefit because the team's time goes to strategy and judgment rather than data wrangling and manual reporting.
Read about the data infrastructure behind this automation in [Why We Built a Single Source of Truth for Client Data](/blog/single-source-of-truth/) and the monitoring it enables in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/). Learn more about [our team and approach](/about/).
---
## What Breaks at 2 AM: Why Marketing Needs Automated Infrastructure
Marketing infrastructure breaks silently. Conversion tracking goes dark, sites throw errors, budgets overspend, images disappear. Automated monitoring catches these in hours instead of weeks. Here are the real failure scenarios we've built our systems to detect.
## The Midnight Site Error
A WordPress site runs an automatic plugin update at 2 AM on Saturday. The update introduces a CSS conflict that breaks the mobile layout. Navigation links overlap, the contact form renders below the fold, and the hero image stretches to twice its intended width. The site is technically "up" so uptime monitors report everything as fine.
Nobody notices until Monday morning. That's 54 hours of a broken mobile experience. For a business where 60-70% of traffic comes from phones, that's a weekend of potential customers seeing a site that looks unprofessional and navigates poorly. Every one of those visitors forms an opinion about the business based on a broken experience that has nothing to do with the business's actual quality of work.
The site's uptime monitor, if there is one, reports 100% uptime the whole time, since the site was technically up even though it looked terrible.
This is the exact scenario our Playwright health checks are designed to catch.
21 websites health-checked daily across 8 categoriesSource: Playwright health check suite, daily execution
Every day, automated browser tests load each site and check eight categories: fatal errors, broken CSS, broken images, JavaScript crashes, failed network requests, cache misconfiguration, navigation accessibility, and visual regressions. The tests run in a real browser, not a simple HTTP check. They render the page, interact with navigation, verify images load, and compare against known-good visual baselines.
If that Saturday plugin update breaks the CSS, Monday's check catches it. The team sees the alert in the operations channel before clients see it in their analytics. The fix goes in Monday morning, not Thursday afternoon when someone finally notices the bounce rate spike.
The visual regression check is particularly valuable here. The test suite compares page screenshots against known-good baselines. Even subtle shifts, like a header that's 20 pixels taller than expected or a sidebar that's overflowing its container, get flagged. These aren't the kind of problems that trigger error logs or crash reports. They're the kind that make a site look slightly off, and visitors notice "off" even when they can't articulate what changed.
**What the alternative looks like:** Without automated checks, the failure mode is "wait until someone notices." That someone is usually a client who calls to say "something looks wrong on our website." By then, the damage to visitor impressions has been accumulating for days.
## The Silent Tracking Break
A marketing manager logs into Google Tag Manager to add a Facebook pixel. They publish a new container version. What they don't realize is that the publish overwrites a recent change made by their developer: a custom event trigger that fires when someone submits the contact form.
Google Analytics 4 stops receiving form submission events. Google Ads stops receiving conversion imports, because GA4 is the source. Smart Bidding, which relies on conversion data to optimize bids, is now flying blind. It doesn't crash or throw an error. It just gradually shifts budget toward whatever signals it still has, which are typically lower-quality engagement signals.
Thirty days later, the monthly report shows conversion volume dropped. The team investigates, discovers the tracking break, fixes it, and now needs another 30 days for Smart Bidding to recalibrate on real conversion data. That's two months of degraded ad performance from a single accidental change.
30 days of wasted ad optimization is the typical cost of an undetected conversion tracking breakSource: Google Ads Smart Bidding documentation on learning periods
The conversion pipeline has four links, and a break at any point silences everything downstream:
| Step | What Happens | Common Break Points |
|---|---|---|
| Website | User submits form, clicks phone number, completes purchase | Form plugin update changes element IDs, site redesign removes tracking hooks |
| GTM | Tag fires, sends event to GA4 | Container version conflict, trigger condition change, tag paused accidentally |
| GA4 | Event recorded, key event configured | Key event reconfigured, data stream changed, property-level settings altered |
| Google Ads | Conversion imported from GA4, used by Smart Bidding | GA4 link breaks, conversion action recategorized, import delayed beyond 72 hours |
We monitor this pipeline at each step. Daily data syncs compare expected conversion volume against actual. If form submissions show up in the CRM but not in GA4, we know the break is between the website and GTM. If GA4 has the events but Google Ads doesn't, the import link is broken. The data tells us not just that something broke, but where.
The cost of missing this is not proportional to the break's duration. It's exponential. A 3-day break costs a few missed conversions. A 30-day break costs an entire month of Smart Bidding learning, plus another 2-4 weeks for the algorithm to recalibrate after the fix. That's potentially two months of degraded ad performance from one silent failure.
Read the full breakdown in [What Happens When Conversion Tracking Breaks](/blog/conversion-tracking-breaks/).
## The Budget Overspend
A home services company runs Google Ads with a $6,000 monthly budget. In a normal month, that works out to about $200 per day. But seasonal demand isn't flat. In the first week of spring, search volume for their core services triples. Google's daily budget algorithm, which is allowed to spend up to twice the daily budget on high-traffic days, starts spending $350-$400 per day.
By the middle of the month, the account has already spent 70% of the monthly budget. If nobody catches it, the account will exhaust its budget by the 20th, leaving the last ten days of the month with no ads running. Or worse, the spend continues and the monthly invoice comes in at $8,500 instead of $6,000.
This isn't just an annoyance for the bookkeeper. For businesses with tight margins, an unexpected $2,500 in ad spend can be the difference between a profitable month and a loss. And the reverse scenario is equally costly: if campaigns exhaust their budget by the 20th, the last 10 days of the month generate zero leads from paid search while competitors continue to capture that demand.
Our budget monitoring runs every 30 minutes. It compares actual spend against expected pacing for that point in the month. When spend exceeds 110% of the expected pace, an alert fires.
Every 30 minutes budget pacing is verified across all managed Google Ads accountsSource: Budget monitoring cron schedule, 48 checks per account per day
That's 48 verification cycles per day per account. The alert fires within 30 minutes of the threshold breach, giving us time to adjust bids, reduce budgets, or pause lower-priority campaigns. The client's budget stays on track.
**What the alternative looks like:** Many agencies review budgets weekly. Some review monthly. A seasonal spike that starts on Tuesday won't get caught until the following Monday at best. By then, the overspend is a fact, not a risk.
## The Image That Disappeared
A web developer enables WebP image optimization on a WordPress site. The server-level rewrite rule converts JPEG and PNG images to WebP format on the fly, serving smaller files to browsers that support the format. Page speed improves and everything looks great.
Three weeks later, the hosting provider updates the server's image processing library. The update breaks the WebP conversion for a subset of images, specifically PNGs with transparency. Those images now return 404 errors. The browser shows broken image icons where product photos or team headshots should be.
The site doesn't crash. No error appears in the WordPress dashboard. The broken images are scattered across interior pages that nobody on the team visits regularly, so customers see them but the team doesn't.
Our Playwright health checks include image verification. During each daily check, the test suite identifies all images on the page and verifies they return valid responses. The image check sends `Accept: image/webp` headers to match real browser behavior, which means it tests the same WebP rewrite path that visitors actually use.
When the WebP conversion breaks, the next health check flags the broken images with their URLs. The fix can be in place before most visitors encounter the problem.
**What the alternative looks like:** Broken images on interior pages can persist for months. They erode trust in ways that are hard to measure but easy to feel. A visitor looking at a "Meet Our Team" page with broken headshots forms an impression about the business's attention to detail.
## What Automated Monitoring Actually Looks Like
The scenarios above aren't hypothetical edge cases. They're patterns we've seen across our client base. The question isn't whether these things will happen. The question is how quickly they get caught.
Our monitoring stack runs daily. Each of the 21 managed sites goes through the full eight-category check:
| Check Category | What It Detects | Example |
|---|---|---|
| Fatal errors | Server 500 errors, PHP fatal errors, white screens | Plugin conflict after update crashes the site |
| Broken CSS | Layout breaks, missing stylesheets, render-blocking issues | Theme update breaks mobile navigation |
| Broken images | Image 404s, failed WebP rewrites, missing assets | Server config change breaks image optimization |
| JS crashes | JavaScript errors that break interactive elements | Third-party script conflict breaks form validation |
| Failed requests | Network requests that return errors | CDN configuration change blocks asset delivery |
| Cache misconfiguration | Pages serving stale or incorrect cached content | Cache plugin serves logged-in user content to logged-out visitors |
| Nav accessibility | Navigation elements that are broken or inaccessible | Menu dropdown breaks, links go to 404 pages |
| Visual regressions | Pages that look different from their known-good baseline | CSS change shifts layout, content overlaps |
Results post to the team's operations channel. Green means all clear. Failures include screenshots and specific error details so the developer assigned to the fix has context immediately.
The entire system runs without human initiation. Nobody has to remember to check. Nobody has to log into 21 different sites. The checks happen, the results post, and the team acts on what surfaces.
This is the layer of infrastructure that sits underneath the strategy work, the keyword research, the content creation, and the campaign optimization. It's what makes it possible to manage 30 clients at the level of attention each one deserves. Not because we have unlimited staff, but because we built systems that watch while we sleep.
## The Compound Effect of Automated Monitoring
Each individual check seems simple. Load a page, verify images load, check a budget number against a threshold. The value isn't in any single check. It's in the compound effect of running all of them, every day, without human effort or memory.
A human checking 21 sites manually takes most of a day. Doing that every day consumes most of a workday, every day. Within a week, shortcuts happen. Within a month, the checks become weekly. Within a quarter, they're "when someone remembers." The monitoring gap widens until something breaks badly enough to force a reaction.
Automated monitoring doesn't get bored, doesn't prioritize, doesn't decide that a site "probably hasn't changed" and skip it. It runs the same checks with the same thoroughness every day. The check on the Tuesday after a long weekend is exactly as thorough as the check on any other day. That consistency is what creates reliability.
30 clients monitored daily with automated infrastructure across all managed servicesSource: Choice OMG CRM, active managed services count
The businesses we manage depend on their websites and ad campaigns working correctly around the clock. Their customers don't check business hours before searching Google or visiting a website. A broken site at 10 PM on a Saturday loses exactly the same potential customer as a broken site at 10 AM on a Tuesday. Automated monitoring treats every hour the same.
Learn how this monitoring feeds into our data infrastructure in [How We Monitor 60,000 Data Points a Day](/blog/how-we-monitor-60000-data-points/). See our [Google Ads management services](/services/google-ads/) for how monitoring integrates with campaign optimization.
---
## How We Monitor 60,000 Data Points a Day
Choice OMG monitors 60,000+ data points daily through four independent pipelines feeding a centralized PostgreSQL database. Every number in every report traces back to a raw API response. This is the infrastructure that makes the rest of the work possible.
## What 60,000 Data Points Actually Means
When we say we monitor 60,000+ data points daily, that number breaks down into specific, countable inputs:
| Pipeline | Data Points/Day | What It Collects |
|---|---|---|
| gads-sync | ~53,000 | Campaign metrics, keyword performance, search terms, ad group stats, budget pacing, Quality Scores, auction insights across 24 Google Ads accounts |
| webopt-data-sync | ~2,000 | GA4 sessions, bounce rates, page performance, Google Search Console impressions, clicks, positions, PageSpeed scores |
| semrush-data-sync | ~2,500 | Keyword positions, visibility scores, competitor movements, backlink profiles, site audit findings, domain authority metrics |
| Budget monitoring | ~3,744 | Spend snapshots every 30 minutes across all managed accounts (24 accounts x 48 checks x ~3.25 metrics per check) |
| Playwright health checks | 168 | Site status across 21 websites, 8 categories each: fatal errors, broken CSS, broken images, JS crashes, failed requests, cache config, nav accessibility, visual regressions |
60,000+ data points monitored daily across all clientsSource: Thor centralized database ingest logs, sum of pipeline row counts
That total is the sum of database rows written per day across the four pipelines, not a marketing estimate. Each row represents a specific metric at a specific time for a specific client, and the exact count can be queried on any given day.
## The Four Pipelines
Each pipeline runs independently. If one fails, the others keep collecting, so no single failure takes the whole system down.
### Pipeline 1: gads-sync (Every 6 Hours)
This is the largest pipeline by volume. It connects to each of our 24 managed Google Ads accounts and pulls campaign-level metrics, keyword performance data, search term reports, ad group statistics, Quality Score components, and auction insights. The sync runs every six hours, producing four snapshots per day per account. That means we see spend, conversion, and performance data within a quarter of a business day.
The dataset count is large because Google Ads exposes data at multiple levels of granularity. A single account with 5 campaigns, 20 ad groups, and 200 keywords generates campaign-level rows, ad-group-level rows, keyword-level rows, and search-term-level rows. Multiply that across 24 accounts and four sync cycles per day, and 53,000 data points is a conservative count.
What it catches: a campaign that suddenly stops converting, a keyword whose cost-per-click spikes beyond historical norms, a search term report showing irrelevant queries eating budget, a competitor entering an auction and driving up impression share competition. These patterns surface in the data hours after they happen, not days. A search term that costs $50 before anyone notices it would have cost $200 or more by the time a weekly check caught it.
What a break looks like: if the Google Ads API returns errors or an account's OAuth token expires, the pipeline logs the failure and retries on the next cycle. No data is lost from other accounts; the failure is isolated. We've designed each pipeline to treat accounts as independent units. An authentication problem with one account doesn't block or delay data collection for the other 23.
### Pipeline 2: webopt-data-sync (Daily)
This pipeline pulls organic performance data from three sources per client: GA4 traffic metrics (sessions, engaged sessions, bounce rates, page-level performance), Google Search Console data (impressions, clicks, average position, and click-through rates broken down by query and page), and PageSpeed scores (Core Web Vitals: Largest Contentful Paint, Cumulative Layout Shift, Interaction to Next Paint, plus overall Lighthouse scores).
It runs once daily because these metrics don't change hour-to-hour the way ad spend does. Organic search positions shift gradually, and GA4 processes data with a delay that makes intraday polling unnecessary.
What it catches: a sudden drop in organic traffic that signals an indexation problem or algorithm update impact, a page that lost its featured snippet to a competitor, a PageSpeed regression caused by a new third-party script or unoptimized hero image, a Search Console coverage error that's preventing new pages from being indexed.
The daily cadence also creates a clean time series. When a client asks "when did our traffic start dropping?" we can point to the exact day, not an approximate week. That precision matters for root cause analysis. A traffic drop that coincides with a plugin update on the same day tells a different story than a gradual decline over two weeks.
What a break looks like: GA4 or Search Console API authentication failures are caught and logged. The pipeline reports which clients succeeded and which failed, so we can address access issues without losing data from functioning accounts. A common cause is Google Workspace permission changes on the client side. When someone on the client's team changes their GA4 property permissions, our service account loses access. The pipeline flags it, and we resolve the access issue, typically within a business day.
### Pipeline 3: semrush-data-sync (Daily/Weekly/Monthly)
SEMrush data operates on three cadences because different metrics change at different rates:
- **Daily:** Position tracking visibility scores and keyword rankings for 1,000+ tracked keywords
- **Weekly:** Backlink profile changes, referring domain counts, site audit health scores
- **Monthly:** Domain analytics, authority score trends, competitive landscape shifts
What it catches: a competitor launching a content campaign (visible in their position changes before their traffic impact shows up), a sudden spike in toxic backlinks, a site audit regression from a CMS update.
What a break looks like: SEMrush API rate limits occasionally throttle the sync. The pipeline backs off and retries. Individual dataset failures don't block other datasets.
### Pipeline 4: Budget Monitoring (Every 30 Minutes)
This is the most time-sensitive pipeline. Every 30 minutes, it checks spend levels across all managed Google Ads accounts against their monthly budgets.
30 minutes maximum time to detect a budget threshold breachSource: Budget monitoring cron schedule and alert configuration
What it catches: an account pacing to overspend its monthly budget. Alerts fire at 110% of the expected daily run rate, giving us time to adjust bids or pause campaigns before the overspend becomes significant.
What a break looks like: if the monitoring script fails, the team is notified of the monitoring failure itself. The system monitors itself. We treat a monitoring gap the same as a detected problem, because a gap in monitoring is itself a risk that needs immediate resolution.
## One Database, Zero Conflicting Numbers
Every pipeline writes to the same PostgreSQL database. We call it Thor. It holds 80+ tables, each with a defined schema, and every table traces back to a specific data source.
This solves the most common reporting problem in marketing: conflicting numbers. When GA4 shows one traffic number, the SEMrush dashboard shows another, and last week's report used a third, nobody knows what's real. With Thor, there's one number for each metric, and it came from one source at one time.
80+ tables in a centralized PostgreSQL database serving all client reportingSource: Thor database schema, reporting DB on thor3
We enforce three authorities, each responsible for different questions:
| Authority | What It Answers | Examples |
|---|---|---|
| Thor | How is performance trending? What are the numbers? | Traffic, conversions, keyword positions, ad spend, PageSpeed scores |
| CRM | Who are our clients? What services do they have? | Client roster, active services, contact information, billing |
| Strategy docs | What are we trying to achieve? | Keyword targets, competitive positioning, quarterly goals |
These three never overlap. Thor doesn't store client contact information. The CRM doesn't store keyword rankings. Strategy docs don't contain raw performance data. When you need an answer, there's exactly one place to look.
Read more about why this separation matters in [Why We Built a Single Source of Truth for Client Data](/blog/single-source-of-truth/).
## The Traceability Chain
Every number in a client report follows a five-step chain back to its origin:
1. **Brief** - The strategy document that set the objective and defined what metrics to track
2. **Data layer** - The tag, event, or API endpoint that generates the raw data
3. **Structured table** - The Thor database table where the pipeline writes the processed data
4. **Raw snapshot** - The original API response, stored as write-once JSONB, preserved indefinitely
5. **Report run** - The specific report generation that pulled the number and presented it
If a client asks "where did this number come from?" we can walk backward from the report to the raw API response. If the number looks wrong, we can compare the structured table against the raw snapshot to see if a processing error introduced a discrepancy. If the raw snapshot itself looks wrong, we can re-pull from the source API and compare.
We've used the traceability chain to debug a real discrepancy between Google Ads reported conversions and our internal tracking. The raw snapshots showed a conversion action had been reconfigured mid-month, splitting what was one metric into two. Without the snapshot archive, that would have looked like a conversion drop. With it, we could see exactly what changed and when.
Another example: a client's GA4 property showed a traffic spike that didn't correspond to any campaign change. Walking the traceability chain backward, we found the spike coincided with a referral spam domain hitting the site. The raw Search Console snapshot from that day showed no corresponding increase in organic impressions, which confirmed the traffic was not from search. Without the chain, the team might have spent hours investigating a "growth" signal that was actually noise.
## Why This Matters for Your Business
The infrastructure described above isn't something clients interact with directly. But it shapes every interaction they do have with us.
**Problems caught in hours, not weeks.** A conversion tracking break that goes undetected for 30 days means 30 days of ad spend optimized against the wrong signal. Our pipelines catch that within 6 hours. A site error that makes your business look broken on mobile gets caught at the next morning's health check, not when a customer mentions it. Read about specific failure scenarios in [What Breaks at 2 AM](/blog/what-breaks-at-2am/).
**Numbers never conflict.** When your monthly report says organic traffic grew 12%, that number came from one place and we can prove it. There's no "well, GA4 shows this but Search Console shows that" ambiguity, because every metric has exactly one source and one value.
**Historical data is preserved.** When we want to compare this March to last March, the data is there. When we want to see how a specific keyword's position has trended over 12 months, the daily snapshots are there. When a new team member picks up an account, they can see the full history, not just last month.
**Reports are reproducible.** If you run the same report query against the same date range twice, you get the same answer. Data doesn't get overwritten or aged out. The raw snapshots are write-once and permanent.
This infrastructure is what separates reactive marketing management (waiting for something to go wrong, then scrambling) from proactive marketing management (catching problems early, having the data to diagnose them, and having the history to put them in context). The monthly fee pays for the system that makes those dashboards trustworthy, not just for someone to look at them.
## What About AI Visibility?
The monitoring landscape is changing. Traditional SEO tracked positions in Google's organic results. Now businesses appear in AI-generated answers across multiple platforms: Google AI Overviews, ChatGPT, Perplexity, Claude, Gemini, Copilot, You.com, Phind, and Meta AI.
10+ AI platforms tracked for client visibility in AI-generated answersSource: AI visibility monitoring across Google AI Overviews, ChatGPT, Perplexity, Claude, Gemini, Copilot, You.com, Phind, Meta AI
We're building this monitoring into our pipeline infrastructure because AI citation is becoming a traffic and credibility signal that matters. When an AI platform cites your business in a response, that's visibility you can't get from traditional ranking. When it stops citing you, that's a loss you need to understand. The same pipeline architecture that monitors 60,000 data points from traditional sources extends naturally to AI visibility tracking.
The principle remains the same: measure it consistently, store it centrally, and make it traceable. Whether the data comes from a Google Ads API or an AI platform's citation pattern, the infrastructure handles it the same way.
Explore our [SEO services](/services/seo/) to see how this infrastructure supports ongoing optimization work.
---
## Enhanced Meta Lead Ads Compliance Standards
## Meta Lead Ads Compliance: What Changed and How to Stay Ahead
Meta updated its privacy and data-handling requirements for Lead Ads on Facebook and Instagram, and if you are running lead generation campaigns, these changes affect how you collect, store, and follow up on leads. The updates are not dramatic, but ignoring them risks ad disapprovals, account restrictions, and degraded lead quality.
Here is what actually changed and what we recommend doing about it.
## What Meta Now Requires
Meta's updated Lead Ads policies tighten requirements in four areas:
**Explicit consent language.** Lead forms must include clear, specific consent language that tells users exactly what they are agreeing to. Generic "by submitting you agree to our terms" language is no longer sufficient. Users need to understand what data you are collecting, how you will use it, and who will contact them.
**Data minimization.** Lead forms should collect only the information you genuinely need. If you are running a general inquiry form, asking for phone number, email, company size, annual revenue, and job title is excessive. Meta is enforcing the principle of collecting only relevant, necessary user information.
**Privacy policy integration.** Your lead forms must link to a current, accessible privacy policy that covers how lead data is handled. If your privacy policy was last updated in 2021 and does not mention Meta Lead Ads data collection, it needs revision.
**Responsible follow-up practices.** How you handle leads after collection matters. Selling lead data to third parties, contacting leads outside the scope of what they consented to, or failing to honor opt-out requests are all violations that can trigger account-level consequences.
## Why This Is Actually Good for Your Campaigns
It is tempting to view compliance updates as friction. They are not. Every one of these requirements improves lead quality.
**Explicit consent filters out low-intent leads.** When users have to acknowledge what they are signing up for, the people who submit are genuinely interested. Your sales team spends less time chasing dead leads.
**Data minimization improves completion rates.** Shorter forms with fewer fields convert better. Meta is essentially pushing you toward a best practice that most marketers already know but ignore because "more data feels better."
**Privacy policy links build trust.** A visible, accessible privacy policy signals legitimacy. In a landscape where consumers are increasingly skeptical of lead forms, that trust signal matters for conversion rates.
**Clean data practices prevent account issues.** Meta's enforcement is real. Account restrictions on lead ad campaigns can take weeks to resolve and directly impact pipeline generation. Proactive compliance avoids that entirely.
## What to Do Right Now
### Audit Your Active Lead Forms
Pull up every active lead ad campaign and check:
- Does the consent language specifically describe how you will use the data?
- Are you collecting only the fields you actually need?
- Is the privacy policy link current and functional?
- Does the privacy policy cover Meta Lead Ads data collection?
### Update Your Follow-Up Processes
Review how leads move through your systems after collection:
- Are leads contacted within the scope of what they consented to?
- Do you have a clear opt-out mechanism that is honored promptly?
- Is lead data stored securely and not shared with unauthorized third parties?
### Document Your Compliance
Keep a record of your lead form consent language, privacy policy version, and data handling procedures. If Meta ever reviews your account, having documentation ready speeds up resolution dramatically.
### Test Your Forms From the User Perspective
Submit your own lead forms. Read the consent language as a consumer would. Is it clear what happens next? Do you know who will contact you and about what? If the experience feels vague or confusing, your prospects feel the same way, and that erodes both trust and conversion rates.
Also verify the post-submission experience. Does the thank-you screen set expectations? Does the first follow-up email match what the form promised? Disconnects between what users consent to and what they actually experience are exactly what Meta is targeting with these updates.
## Common Compliance Gaps We Find
When we audit lead ad accounts, the same issues appear repeatedly:
**Stale privacy policies.** The privacy policy linked in the lead form was written in 2020 and does not mention Meta, Facebook, Instagram, or lead form data collection. Meta can and does check this.
**Over-collection of fields.** Forms asking for information the business never uses. If you are collecting "company size" and "annual revenue" but your sales process never references those fields, you are adding friction for no benefit and technically violating data minimization principles.
**No opt-out process.** Users submit a lead form and receive follow-up emails for months with no clear way to stop them. Under Meta's updated requirements, this is a violation that can trigger account restrictions.
**Third-party data sharing without disclosure.** Lead data gets shared with partner organizations or lead distribution services without the user's knowledge. If your lead form does not explicitly disclose this, you are non-compliant.
## The Broader Trend
Meta's Lead Ads update is part of a broader industry shift toward transparency and accountability in digital advertising. Google has implemented similar changes through its advertiser verification and pricing disclosure requirements. The platforms are converging on the same principles: controlled access, clear consent, and verifiable identity.
Businesses that build compliance into their standard operating procedures will not be disrupted by these updates. Businesses that treat compliance as an afterthought will spend increasing amounts of time dealing with disapprovals and restrictions.
## How We Handle This for Clients
We updated our internal processes, lead form templates, and campaign review procedures to align with Meta's requirements before they went into enforcement. Clients currently running Meta Lead Ads with us will not experience disruptions. Where updates are required, we guide clients through the process and recommend improvements tailored to their specific campaigns.
If you are running lead generation campaigns on Meta and are not sure whether your forms meet current requirements, [we can audit your setup and bring it into compliance](/services/google-ads/).
Clean data practices benefit everyone: higher quality leads for your sales team, better experiences for users, and stable ad accounts that do not get shut down mid-campaign.
---
## Google Ads Advertiser Verification and Transparency Update
## Google Ads Advertiser Verification: What Changed in 2025 and What You Need to Do
Google continued expanding its advertiser verification and transparency requirements throughout 2025, with several updates affecting how advertisers are identified, how ads are displayed, and how compliance is enforced. For most legitimate businesses, these are standard compliance maintenance, not operational disruption. But accuracy and transparency now matter more than ever, and falling behind on verification can mean paused ads and lost revenue.
Here is what changed and what you need to act on.
## Payer Name Disclosure
Google now displays the name of the entity funding an advertisement within the My Ad Center panel and the Ads Transparency Center. This means users can see who is behind an ad before they engage with it.
Two key changes affect agencies and advertisers directly:
**Agency re-verification.** Agencies that were previously verified as direct advertisers were required to re-verify as agencies by May 31, 2025, ensuring the correct client payment profile is displayed. If your agency manages Google Ads on your behalf and you did not re-verify, your ads may be showing incorrect payer information.
**Manual payer name editing.** As of June 2025, advertisers can manually edit the displayed payer name within their verification settings. This allows businesses to show a clear, accurate funding name instead of a default payment profile label. If your ads currently display a holding company name or a generic profile label, fix this now.
## Stricter Enforcement on False Information
In November 2025, Google updated its Circumventing Systems policy to explicitly state that providing false or misleading information during advertiser verification is a violation. This is not a minor policy footnote. Submitting fraudulent or inaccurate details may now result in:
- Immediate account suspension
- Permanent loss of advertising privileges
If any information in your advertiser verification is outdated, such as a former business address, old legal entity name, or expired documentation, update it proactively. Google is not asking whether your details were misleading intentionally. They are checking whether they are accurate right now.
## Enhanced Verification for Regulated Industries
Advertisers in regulated sectors now face more rigorous verification. This includes:
- **Financial services** (including debt-related services in certain regions)
- **Healthcare and telemedicine**
- **Other compliance-sensitive verticals**
In some markets, additional documentation or third-party certifications like LegitScript are required before ads can run. If you operate in a regulated industry and have not checked your verification status recently, do it today. Account restrictions in these verticals can take weeks to resolve.
## Clearer Pricing Disclosure Requirements
As of October 2025, Google introduced stricter rules around pricing transparency in ads:
- Ads must clearly disclose full costs and payment structures
- Hidden fees or misleading pricing models are violations
- The term "free" can only be used when no payment or obligation exists
If you run ads with pricing claims, trial offers, or "free" language, audit your ad copy against these requirements. Non-compliant ads get disapproved, and repeated violations escalate to account-level consequences.
## Phone Number Policy Enforcement
Beginning December 2025, Google began blocking phone numbers associated with fraudulent activity, spam complaints, or repeated policy violations from use in advertising.
Ensure that contact details in your ads are authentic, accurate, and consistent across platforms. If your Google Ads use a tracking number, verify that the number has no spam complaints associated with it.
## What You Should Do Right Now
1. **Verify your payer name display.** Log into your Google Ads account, check verification settings, and ensure the displayed payer name accurately reflects your business.
2. **Audit verification details for accuracy.** Business name, address, documentation. Make sure everything is current.
3. **Review ad copy for pricing compliance.** Check any ads with pricing claims, "free" offers, or trial language.
4. **Check phone numbers.** Ensure all numbers used in ads are clean, accurate, and consistent with your business listings.
5. **Set a quarterly verification review.** These policy updates are accelerating. Build verification audits into your regular account maintenance.
## Common Mistakes We See
**Outdated business addresses.** A business moves offices but never updates their Google Ads verification. The verification record shows an old address, which technically constitutes inaccurate information under the updated policy. Low risk in isolation, but if flagged during a review, it creates unnecessary friction.
**Generic agency payer names.** An agency sets up Google Ads accounts under their own billing profile. With the new payer name disclosure, the agency name shows as the ad funder rather than the actual business. Consumers see an unfamiliar company name behind the ad, which hurts trust and can depress click-through rates.
**Expired documentation.** Business registrations, licenses, and certifications expire. If you submitted documentation during initial verification and it has since expired, your verification status may be at risk. Google has not historically been aggressive about re-checking documentation, but the November 2025 policy change gives them explicit grounds to do so.
**Tracking number spam flags.** Call tracking services route through shared phone number pools. If a previous user of that number generated spam complaints, those complaints may now affect your ads. Check the spam status of any tracking numbers you use in ad extensions.
## Why This Matters Beyond Compliance
Keeping advertiser information current is not just about avoiding ad interruptions. It directly affects user trust and ad credibility. Ads that clearly show who is behind them perform better with increasingly skeptical audiences. Google's transparency push is fundamentally about consumer trust, and clean verification positions your business as legitimate in a landscape where users are increasingly wary of online advertising.
Clean verification also improves account stability. Fewer sudden disapprovals mean smoother campaign performance, more consistent pacing, and no emergency scrambles to get ads reapproved during a critical promotion window.
We monitor platform policy updates across Google, Meta, and other major advertising networks as part of ongoing [Google Ads management](/services/google-ads/). When verification updates or disclosures are required, we help clients navigate the process and ensure their ad presence stays compliant and stable.
Advertiser verification is no longer a one-time setup task. It is a core part of ongoing Google Ads account management.
---
## n8n Version 2.0 Announced: What It Means for Automation Reliability
## n8n Version 2.0: What the Automation Update Means for Your Workflows
n8n has announced Version 2.0, and this release is less about flashy new features and more about the structural improvements that determine whether your automations hold up over time. For businesses running n8n to power integrations, lead routing, CRM synchronization, or internal reporting, this is a future-proofing update worth understanding.
## What Is Changing in n8n 2.0
The release focuses on four areas that matter for production reliability:
**Improved internal architecture.** Under-the-hood changes to how n8n processes workflows. You will not see these directly, but they reduce edge cases where workflows fail silently or produce inconsistent results.
**Better long-term support and stability.** The n8n team is committing to clearer versioning and support windows. For teams that depend on n8n in production, this means fewer surprises when upgrading.
**Clearer handling of breaking changes.** Version 2.0 includes an explicit framework for identifying and communicating breaking changes before they affect your workflows.
**Built-in Migration Report.** Before you upgrade, n8n 2.0 generates a report that identifies which of your existing workflows may need updates. This is a significant improvement over the old approach of upgrading and hoping nothing breaks.
## Why This Matters More Than It Sounds
Automations are invisible infrastructure. They sit quietly in the background handling tasks that would otherwise require manual work:
- Lead routing from form submissions to CRM
- Data synchronization between platforms
- Billing and invoicing triggers
- Internal notifications and reporting pipelines
- Campaign data aggregation
When these automations work, nobody thinks about them. When they break, critical business processes stop. A lead routing automation that silently fails means sales inquiries sit in a dead queue. A CRM sync that stops working means your team operates on stale data without knowing it.
Version 2.0's focus on reliability and predictable maintenance reduces the risk of exactly these kinds of silent failures. The migration report alone saves hours of manual testing that teams typically skip, only to discover problems weeks later when a client complains about a missing follow-up.
## The Hidden Cost of Automation Neglect
Most businesses set up automations and forget about them. This works until it does not. Here is what we commonly see when auditing neglected automation environments:
**Zombie workflows.** Automations created for one-time projects or campaigns that ended months ago, still running, still consuming resources, sometimes still sending emails or updating records in ways nobody intended.
**Credential rot.** API keys and OAuth tokens expire. When an automation's credentials expire, it fails silently. The workflow still "runs" but produces no results, and nobody notices until downstream processes start breaking.
**Version drift.** Node packages and integration modules fall behind. When you finally need to modify a workflow, you discover that updating one component requires updating six others, and the cascade of changes is unpredictable.
**No monitoring.** The most common gap we see: no alerting when a workflow fails. Teams assume everything is working because nobody is complaining, when in reality a critical automation broke weeks ago.
n8n 2.0 addresses several of these problems structurally, but good operational hygiene still requires deliberate effort.
## How to Approach the Upgrade
If you are running n8n in production, here is a practical upgrade plan:
1. **Run the migration report first.** n8n 2.0 tells you what will break before you upgrade. Read it.
2. **Test in a staging environment.** Clone your instance, upgrade the clone, and verify your critical workflows still execute correctly.
3. **Prioritize high-impact workflows.** Focus testing on automations that touch revenue (lead routing, billing) or client-facing systems (reporting, notifications).
4. **Schedule the upgrade during low-traffic hours.** Even with thorough testing, have a rollback plan ready.
5. **Document what changed.** If any workflows need adjustments, record what you changed and why. Future-you will thank present-you.
6. **Set up monitoring post-upgrade.** Use n8n's built-in execution history and error notifications to catch any regressions in the first week after upgrading.
## Our Approach to Platform Updates
We monitor major platform updates across automation, advertising, and web infrastructure. When structural changes like n8n 2.0 are announced, we review potential impact on client systems, test compatibility, and plan upgrades methodically instead of reactively.
Clients using automation solutions we manage get advised proactively if any action is required, not after something breaks.
## What This Means for Choosing an Automation Platform
If you are evaluating automation platforms right now, n8n 2.0 is a signal worth paying attention to. The decision to invest in internal architecture and migration tooling over flashy features shows a team thinking about production use, not just demos.
For businesses comparing n8n to alternatives like Zapier or Make, the key differentiator remains self-hosting. Your workflow data, credentials, and execution history stay on your infrastructure. With n8n 2.0, the operational maturity of self-hosted n8n gets meaningfully closer to what you would expect from enterprise SaaS platforms, but without the per-execution pricing that makes those platforms expensive at scale.
The tradeoff is real, though: self-hosted means you own the maintenance. Updates, backups, monitoring, and troubleshooting are your responsibility. For teams without technical resources, that overhead may outweigh the benefits. For teams with the capability, or an agency partner handling it, self-hosted n8n remains one of the best values in the automation space.
If your business relies on automation workflows and you want them managed with the same discipline as production software, [that is exactly what we do](/services/).
---
## n8n Becomes MCP-Ready: Enabling Secure AI-Driven Automation
## n8n Becomes MCP-Ready: What It Means for AI-Driven Automation
n8n announced that entire self-hosted instances can now be made MCP-ready, enabling secure connections between automation workflows and AI systems through a single standardized interface. For teams already running n8n for workflow automation, this is a significant architectural upgrade that simplifies how AI tools interact with real business systems.
## What MCP Actually Is
Model Context Protocol (MCP) is a standard that allows AI systems to interact with tools and data in a controlled, permission-based way. Think of it as a secure API layer between AI agents and your business infrastructure.
Before MCP, connecting an AI agent to your CRM, ticketing system, or internal tools meant building custom integrations for each connection. Each integration was bespoke, fragile, and difficult to audit. MCP standardizes that interface.
With n8n's MCP support:
- A single secure connection can expose approved workflows to AI agents
- Access is centralized and auditable, so you know exactly what AI systems can and cannot do
- Sensitive systems remain protected behind explicit permission boundaries
- New AI tools can connect without building new integrations from scratch
## Why This Matters Right Now
AI is moving beyond chat interfaces into action-based systems that trigger workflows, update records, and coordinate tasks across tools. This is where the real operational value lives, but it is also where security and compliance risks multiply.
An AI agent that can read your CRM but accidentally update the wrong records is a liability. An AI agent operating through MCP, with explicit permissions scoped to specific workflows, is a tool you can actually trust in production.
This parallels the broader industry shift toward controlled access and clear accountability in digital platforms. The same principles driving stricter advertiser verification on Google and updated consent requirements on Meta apply to AI system access: you need to know who is doing what, and you need to be able to prove it.
## What This Enables in Practice
**AI-assisted operations.** An AI agent can now trigger an n8n workflow to, for example, look up a customer record, generate a summary, and draft a response, all without direct database access. The workflow defines the boundaries. A support agent AI can pull order history, check shipping status, and draft a customer email, but it cannot modify the order or issue a refund unless you explicitly allow it in the workflow.
**Safer experimentation.** Teams can test AI agent capabilities against real systems without risking uncontrolled access. If the AI makes a mistake, the workflow layer catches it before it reaches production data. This is critical for businesses that want to explore AI automation without putting live customer data at risk during the testing phase.
**Cleaner architecture.** Instead of a web of point-to-point integrations between AI tools and business systems, MCP creates a single control plane. Add a new AI tool? Point it at your MCP endpoint. Done. When you need to revoke access, you do it in one place instead of hunting down API keys scattered across 15 different services.
**Reduced integration maintenance.** Every custom integration is a maintenance liability. When an API changes, your integration breaks. MCP reduces the number of custom connections you need to maintain by standardizing the interface between AI systems and your workflows. Fewer bespoke integrations means fewer things that break at 2 AM.
## Practical Use Cases We Are Watching
Several patterns are emerging as businesses adopt MCP-ready automation:
**Intelligent lead qualification.** An AI agent connected via MCP reads new form submissions from your CRM, scores them based on criteria you define, enriches the lead with publicly available company data, and routes high-value leads to the appropriate sales rep, all through n8n workflows that you control and can modify without touching code.
**Automated reporting with context.** Instead of just pulling numbers, an MCP-connected AI agent can generate narrative summaries of campaign performance, flagging anomalies and suggesting next steps. The n8n workflow handles the data pipeline; the AI handles the interpretation.
**Customer support triage.** AI reads incoming support tickets, categorizes them by urgency and topic, drafts initial responses for common issues, and escalates complex issues to human agents with relevant context attached. The MCP boundary ensures the AI can read tickets and create drafts, but final send authority stays with your team.
## How We Approach This
We evaluate AI and automation infrastructure with a focus on security, predictability, and business value. The n8n MCP update aligns with how we build automation for clients: controlled systems designed for production use, not experimental setups that break under real-world conditions.
For teams exploring AI-assisted workflows, MCP-ready platforms like n8n mean more standardized and maintainable solutions as the ecosystem matures. If you are evaluating automation infrastructure for your business, [we can help you build it right from the start](/services/).
---
## Conversational Search Is Here: Is Your Schema Ready?
## Conversational Search Is Here: Is Your Schema Ready?
Google processed over 5 trillion searches last year. That number is meaningless on its own. What matters is how those searches changed. Queries are becoming longer, more specific, and more conversational.
People are not searching "best pizza Calgary" anymore. They are searching "where can I get a really good thin-crust pepperoni pizza that's open late near Kensington and also has decent vegetarian options for my partner?"
That is not a keyword. That is a paragraph. And Google does not answer paragraphs by guessing. It answers them by understanding entities, relationships, and context. If your website cannot communicate those things in a language Google's systems actually read, you are invisible to the queries that matter most.
## How Search Behavior Has Changed
Three behavioral shifts are directly reshaping how businesses need to structure their web presence.
### Complex, Conversational Queries Are the Norm
People ask full questions with multiple constraints. Not "plumber Calgary" but "emergency plumber who can come tonight and doesn't charge extra for after-hours." Not "running shoes" but "best running shoes for flat feet under $150 that work on trails."
These queries do not have a single keyword to optimize for. They have intent, and Google's language models like BERT and MUM are trained to parse that intent by understanding relationships between concepts, not just matching words.
### Visual Search Keeps Growing
Google Lens usage for product discovery continues to climb. People photograph products, plants, outfits, and expect instant answers. Visual search relies on entity recognition: Google connects what it sees in an image to what it knows about your business. That connection depends on image alt text that actually describes the content, product schema with properly linked image properties, image sitemaps that tell Google where your visual assets live, and consistent entity data across your site.
Most businesses treat alt text as an accessibility checkbox. It is also a search visibility signal.
### Queries Now Expect AI-Assisted Answers
People are asking task-oriented questions that assume intelligent parsing: "help me plan a weekend trip to Banff that's dog-friendly and under $500." Google's AI Overviews and featured snippets pull from sources the system can parse confidently. If your content is technically ambiguous, you do not get cited.
## Why This Breaks Traditional SEO
Traditional SEO taught us to identify keywords and ensure they appear with appropriate frequency. This worked when queries were two or three words. Conversational queries of 10-20 words do not have a "keyword." They have intent.
**Old query:** "Calgary web design"
**New query:** "who builds websites for small restaurants in Calgary that include online ordering"
The second query contains "Calgary," "web design" loosely, and "restaurants," but no single phrase captures what the searcher actually wants. The page that ranks is not the one with the best keyword density. It is the one that answers the question.
For businesses, ranking is less about repeating phrases and more about whether Google can confidently understand who you are, what you offer, and under what conditions you are relevant.
## Schema Markup: From Nice-to-Have to Essential
Structured data tells Google explicitly what your content means. When someone asks a complex question, Google does not just match words. It matches entities and relationships.
Here is what Google actually reads, not your page design:
```json
{
"@context": "https://schema.org",
"@type": "Restaurant",
"@id": "https://example.com/#restaurant",
"name": "Example Trattoria",
"servesCuisine": "Italian",
"openingHoursSpecification": {
"@type": "OpeningHoursSpecification",
"dayOfWeek": ["Monday", "Tuesday", "Wednesday", "Thursday", "Friday", "Saturday"],
"opens": "11:00",
"closes": "23:00"
},
"address": {
"@type": "PostalAddress",
"addressLocality": "Calgary",
"addressRegion": "AB",
"streetAddress": "123 Kensington Road NW"
}
}
```
With this markup, when someone searches "Italian restaurant open late Kensington outdoor seating," Google does not have to infer from your page copy. It knows. Your restaurant becomes a structured entity in Google's knowledge graph, not just a page with some text on it.
This is where our [technical SEO team](/services/seo/) spends significant time on client projects: building the machine-readable layer that most agencies skip entirely.
## What We Have Implemented for Clients
For a multi-location optometry practice, comprehensive schema markup resulted in:
- Rich results appearing for 12 of their 15 target service keywords
- Knowledge panel appearances for 4 of 6 locations
- 73% increase in "near me" query visibility within 90 days
The implementation included LocalBusiness schema for each location with linked service offerings, FAQ schema for their most common patient questions, and proper `@id` references connecting their practice entity across all location pages.
For an e-commerce client, Product schema with proper review markup increased click-through rates on Shopping results by 28%. Star ratings and price visibility in search results make a measurable difference.
## The Case for Aggressive Schema Implementation
**First-mover advantage is real.** Most local businesses have zero or minimal structured data. Implementing comprehensive schema now puts you ahead of competitors who will not catch up for years.
**AI Overviews favor structured data.** Google's AI-generated summaries pull from sources it can parse confidently. Schema makes your content parseable.
**Voice search is conversational by nature.** Every smart speaker query is a conversational query. Schema answers voice queries directly.
**It is measurable.** Rich results, knowledge panel appearances, and featured snippets are trackable wins that demonstrate ROI.
## The Honest Caveats
**Schema alone does not rank you.** Structured data helps Google understand your content. It does not make bad content good. A site with great schema and thin content still loses to a site with excellent content and no schema.
**Implementation cost is non-trivial.** Proper schema requires developer time. For a small business with a five-page WordPress site, the ROI may not justify custom implementation. That said, plugins like Yoast and RankMath handle basics adequately for simple sites.
**Over-engineering is possible.** Adding schema for every conceivable entity can create maintenance burden and potential errors. Start with high-impact schema types before going deep.
The real risk is not doing schema wrong. It is doing nothing while your competitors quietly build machine-readable sites.
## What to Implement, by Priority
### Tier 1: Table Stakes
Every business, regardless of size, should have:
- LocalBusiness or Organization schema with complete NAP (Name, Address, Phone)
- OpeningHoursSpecification for every location
- Review/AggregateRating schema if you have testimonials
- Proper image alt text that describes what is actually in the image
### Tier 2: Industry-Specific (Where ROI Shows Up)
Based on your business type:
- Product schema for e-commerce (price, availability, reviews)
- Service schema for service businesses (service area, service types)
- FAQ schema for common questions (appears directly in search results)
- HowTo schema for instructional content
- Event schema for businesses with recurring events
### Tier 3: Advanced (How You Outrank Better-Known Competitors)
For businesses ready to invest in technical differentiation:
- Speakable schema for content optimized for voice assistants
- Interconnected schema with `@id` references creating a local knowledge graph
- Video schema with clip markup for YouTube embeds
- BreadcrumbList for site navigation signals
## The Technical Floor Is Rising
The minimum technical competence required to compete in search rises every year. Five years ago, you could rank with good content and basic on-page SEO. Today, you need that plus structured data, plus Core Web Vitals compliance, plus mobile optimization, plus proper internal linking architecture.
The way people search has changed. The queries are longer. The expectations are higher. And Google's systems are getting better at distinguishing between sites that actually answer the question versus sites that just contain the right words.
The businesses that win in search over the next five years will not be the loudest. They will be the ones Google understands best.
Ready to find out where your site stands? We offer [technical SEO audits](/services/seo/) and [local SEO assessments](/services/local-seo/) that show you exactly what Google sees and what it is missing.
---
## Q5: The Post-Christmas Revenue Window Most Businesses Ignore
## Q5: The Post-Christmas Revenue Window Most Advertisers Miss
87% of shopping occasions end in a purchase during Q5.
If that number does not make you reconsider your post-Christmas ad spend, nothing will.
"Q5" is the unofficial name for the period between December 26 and mid-January, the weeks after the holidays when most businesses assume shopping is over. It is not. According to Google's data, this window sees more purchase completion than almost any other time of year.
The difference? Shoppers are no longer buying for others. They are buying for themselves. Gift cards are burning holes in pockets. Holiday bonuses just landed. And after weeks of buying for everyone else, consumers are finally ready to purchase the things they actually want. Meanwhile, most advertisers have paused their campaigns, assuming the season is over.
That gap between consumer intent and advertiser presence is where the Q5 opportunity lives.
## What Makes Q5 Shoppers Different
Q5 shoppers behave fundamentally differently from holiday shoppers:
**High intent.** 87% of shopping occasions end in purchase, compared to 50-60% during the browsing-heavy periods earlier in the season.
**Self-gifting mindset.** Gift cards do not feel like "real money." Holiday bonuses feel like windfalls. The psychological barriers to purchasing drop significantly.
**Research already done.** Many Q5 purchasers spent November and December researching products. They know exactly what they want. They just did not buy it yet.
**Deal expectations.** Post-Christmas clearance conditioning means shoppers expect discounts, but they are also ready to buy, not just browse.
The businesses that win Q5 are not necessarily the ones with the biggest budgets. They are the ones who show up when everyone else goes home.
## Real Q5 Results: What We Have Seen
Last Q5, one of our e-commerce clients in the outdoor recreation space maintained their Google Ads presence while competitors went dark. The results:
- Cost-per-click dropped 23% compared to December 15-24
- Conversion rate increased from 2.8% to 4.1%
- January revenue exceeded December despite 40% lower ad spend
The key was not spending more. It was spending consistently when others stopped. Their remarketing audiences, built from November and December browsers, converted at nearly double the rate of cold traffic.
Canadian fashion retailer Aritzia provides a larger-scale example. Instead of going all-in on the Black Friday-to-Christmas frenzy and then disappearing, they built a strategy that extended through Q5. Local inventory ads connected physical store inventory to Google Ads. Performance Max campaigns allocated budget across Search, Shopping, YouTube, and Display based on real-time performance. The result: 55% lift in holiday demand and 42% growth in e-commerce revenue.
For smaller businesses, the lesson is not "do exactly what Aritzia did." It is "do not disappear when your competitors do."
## The Technical Side: What Actually Moves the Needle
### Feed Management
Q5 success requires accurate, real-time product data. Nothing kills conversion like "in stock" ads for out-of-stock products.
Your product feed needs:
- **Inventory accuracy:** Update at least daily, ideally in real-time. Overselling destroys trust.
- **Price accuracy:** Post-Christmas sales mean price changes. Stale feeds show wrong prices, wasting clicks.
- **Sale attributes configured:** Google Merchant Center supports `sale_price` and `sale_price_effective_date`. Use them. Sale annotations in search results drive clicks.
### Audience Signals
Q5 shoppers are different from holiday shoppers. Your targeting should reflect this.
**Cart abandoners from November/December:** They researched but did not buy. Now they are ready. Create a custom audience of users who viewed product pages or added to cart but did not purchase. These are warm leads with holiday cash, not cold prospects.
**Past purchasers:** Someone who bought from you in Q4 is primed to buy again, especially if you are running clearance on complementary products.
**Self-reward messaging:** Shift your ad copy from gift-giving to self-gifting. "You spent all season giving. Time to get something for yourself."
### Budget Pacing
If you are running Performance Max or any automated bidding strategy, the algorithm needs time to learn. Turning campaigns off on December 25 and back on December 27 resets the learning phase. You will spend the first few days of Q5 in inefficient "learning" mode while competitors with continuous campaigns capture the demand.
Reduce budgets if you need to. But maintain continuity.
## The Case for Q5 Investment
1. **Lower CPCs.** Many competitors reduce spend after Christmas. Less competition means lower cost per click for the same inventory.
2. **Higher conversion rates.** That 87% purchase completion rate speaks for itself. You are advertising to buyers, not browsers.
3. **New customer acquisition.** People flush with gift money are willing to try new brands. Q5 is discovery season.
4. **Inventory clearance.** Move holiday stock before it becomes dead weight eating warehouse space.
5. **Q1 momentum.** Starting the year with strong sales sets the tone for budget allocation and team morale.
## The Honest Caveats
**Margin pressure.** Q5 is deal-driven. If you are discounting heavily, volume gains may not translate to profit. Know your margins before you scale.
**Return surge.** Q5 is also return season. High sales volume can be offset by high return rates, especially in apparel. Factor return logistics and costs into your planning.
**Inventory risk.** Advertising products you cannot fulfill damages reputation and wastes spend. Q5 requires operational readiness, not just ad budgets.
**Team capacity.** Your team is exhausted from the holiday push. Q5 effort requires either pre-planning or bringing in help. Do not assume you can "just keep going."
**Not all industries benefit equally.** Q5 is strongest for retail, fashion, electronics, and home goods. Service businesses see less dramatic lift, though "new year, new [service]" positioning can still work.
## Planning Your Q5 Strategy
### October
Build Q5 audiences. Start collecting site visitors, cart abandoners, and email subscribers who will become your Q5 remarketing pool.
### November
Calendar dedicated Q5 budget. Do not let it get absorbed into "Q4" or "Q1." Treat it as its own mini-season.
### Early December
Prepare Q5 creative. Self-gifting messaging, clearance announcements, "new year" positioning. Have it ready before the holiday rush consumes your team.
### December 20-25
Brief your team or agency. Everyone should know that campaigns continue through Q5 and what the goals are.
### December 26
Execute. Monitor performance daily. Q5 moves fast.
## The Window Is Open
December 26 is not the end of shopping. It is the beginning of a three-week window where customers are more ready to buy than any other time of year.
Most businesses will pause their campaigns, assume the season is over, and wait for January planning meetings to think about advertising again. Their customers will still be searching. They will just find someone else.
If your campaigns are paused, unpause them. If your feeds are stale, update them. If you need help making Q5 work for your business, [we have been through this cycle with clients before and know what actually moves the needle](/services/google-ads/).
---
## Dependency Hell Isnt Just for Developers
## Dependency Hell in Your Marketing Stack: Why Audits Matter
Every developer knows dependency hell. You ignore updates for six months, then one day everything breaks because Package A requires Package B version 3, but Package C still needs version 2, and now your build fails at 4 PM on a Friday.
Marketing stacks have the same problem. Nobody talks about it.
Your GTM container has tags from campaigns that ended two years ago, still firing on every page load. Your WordPress site runs plugins that have not been updated since 2022. Your tracking scripts reference APIs that were deprecated last year. None of it is broken yet. But it is rotting, and the longer you wait, the worse the eventual failure.
We know because we audit these stacks constantly. What we find is almost always the same: technical debt that nobody tracks, because marketing teams do not think of their tools as code. They should.
## What Marketing Dependency Hell Actually Looks Like
### GTM Container Bloat
Most GTM containers we audit are graveyards. Tags added for campaigns that ended years ago, still firing. Triggers that do not match the current site structure. Custom HTML tags with inline scripts from vendors who have pivoted twice since implementation.
The problem compounds over time. Each orphaned tag adds potential conflicts, debugging complexity, and page load overhead. GTM containers have a 200 KB size cap. We have seen containers approach that limit purely from accumulated cruft.
### WordPress Plugin Vulnerabilities
The data is stark: over 52% of WordPress vulnerabilities come from outdated plugins. Not sophisticated zero-day exploits, just plugins with patches available but not applied.
It gets worse. According to Patchstack's 2024 security report, 97% of all new WordPress vulnerabilities were in plugins, versus just 0.2% in WordPress core. The plugin ecosystem is where the risk lives. Sucuri's security analysis found that just three outdated plugins, RevSlider, GravityForms, and the TimThumb image script, were responsible for about 25% of all WordPress hacks observed in a single quarter. Each had updates available long before the breaches. Nobody applied them.
If your site has plugins that have not been updated in months, you are not "stable." You are exposed.
### Third-Party Script Sprawl
The average web page today includes 35+ third-party scripts running in the background: tracking pixels, analytics, A/B testing tools, chat widgets, review platforms, consent managers. They accumulate silently.
HTTP Archive data shows websites typically serve about 450 KB of their own code but approximately 850 KB of third-party script code, nearly twice as much external code as internal. A single badly-behaved third-party script can completely block your page from rendering. One analysis found that common A/B testing tools add anywhere from 100 ms to 1,500 ms of load time and degrade Core Web Vitals scores by 10-30%.
The script meant to optimize conversions may be silently killing them by making your page slower.
## Why This Never Gets Fixed
The honest answer: it is not billable, not visible, and not urgent, until it is.
**Not billable:** Clients do not ask for "audit my GTM container for dead tags." They ask for "run more ads" or "fix the conversion tracking." Proactive maintenance does not fit neatly into a statement of work.
**Not visible:** Unlike a broken website, a rotting marketing stack degrades silently. Page speed slows by 200 ms. Conversion data gets slightly less accurate. Security vulnerabilities exist but are not exploited. Nobody notices until the audit or the breach.
**Not urgent:** The WordPress plugin that has not been updated in two years still works. Why touch it? Because when it finally breaks, it breaks catastrophically. Nearly 14% of hacked websites had at least one vulnerable component at the time of attack, often a plugin with a known patch that simply was not applied.
## How We Approach Marketing Infrastructure
We treat marketing infrastructure like code. That means version control, scheduled audits, and automated maintenance.
### Version Control for GTM
Google's own documentation encourages exporting GTM containers as JSON files for version control. We do exactly this. Container configurations get exported and committed to Git alongside website code. Every change to tracking setup, adding a tag, modifying a trigger, is tracked, reviewable, and reversible.
This eliminates the "someone changed something in GTM and we don't know what" problem. When debugging why a conversion stopped firing, you can diff the current container against last month's version and see exactly what changed.
### Scheduled Audit Cadence
GTM containers need the same maintenance discipline as code: a light review monthly and a deeper cleanup quarterly. Not when something breaks, but on a schedule.
What we check in every audit:
- **Orphaned tags:** Anything from ended campaigns, still firing
- **Duplicate tags/variables:** Redundant items that slow page loads and confuse debugging
- **Heavy custom code:** Custom HTML tags that should be refactored or moved to the codebase
- **Naming conventions:** Standardized prefixes (e.g., "GA4 --" or "Meta Pixel --") so anyone can understand the container at a glance
- **Performance impact:** Tags firing on every page that do not need to, or loading large libraries unnecessarily
### Automated Plugin Updates
Manually logging into 20+ client websites to update plugins weekly does not scale. We use WordPress management platforms like ManageWP and MainWP to centrally monitor and update all client sites from a single dashboard. Updates get pushed weekly with proper backups in place, dramatically reducing the window of exposure to known vulnerabilities.
## Questions to Ask Your Marketing Agency
If you work with a marketing agency, ask them these five questions:
1. When was the last time you audited our GTM container?
2. Do you have a process for updating WordPress plugins, or do you wait until something breaks?
3. Can you show me documentation of what tracking scripts are running on our site?
4. What happens to the tags and pixels you add when a campaign ends?
5. Is our GTM container configuration backed up anywhere outside of GTM itself?
Most agencies will not have good answers. That is not because they are bad agencies. It is because the industry does not treat marketing infrastructure as infrastructure. We do.
## What You Can Do Today
**Audit your GTM container.** Export it (Admin, then Export Container), open the JSON file, and search for tags you do not recognize. If you find tags referencing campaigns from years ago, they should not still be firing.
**Check your WordPress plugins.** Log in, go to Plugins, and look at when each was last updated. Anything that has not been updated in 12+ months is either abandoned or you have missed updates. Both are problems.
**Inventory your third-party scripts.** Open your site in Chrome DevTools, go to the Network tab, reload, and filter by "JS." Count how many external domains are loading scripts. If the number surprises you, you have cleanup to do.
**Run a Core Web Vitals test.** Use Google's PageSpeed Insights on your key pages. If your scores are orange or red, third-party scripts are often the culprit.
## The Bottom Line
Dependency hell is not just for developers. It hits anyone running a modern marketing stack, which is everyone.
The difference between a technical agency and a traditional one is not just that we can write code. It is that we think about your marketing infrastructure the way engineers think about production systems: something that requires monitoring, maintenance, and proactive care.
Your GTM container is code. Your WordPress site is infrastructure. Your tracking scripts are dependencies. Treat them accordingly.
Not sure what is running on your site? We offer [marketing infrastructure audits](/services/web-design/) that document what you have, identify what is broken or rotting, and prioritize what to fix.
---
## Competitor Monitoring Without the Enterprise Price Tag
## Competitor Monitoring with Open Source Tools: A Practical Guide
When was the last time you checked what your competitors changed on their website? If the answer is "during our last strategy session," you are operating with a stale map in a market that shifts weekly.
A local professional services firm we work with learned a national franchise was entering their market, not from a press release, but from automated monitoring that caught new location pages appearing in the franchise's sitemap. They had weeks to adjust messaging before the national brand launched locally. That is the difference between reactive and proactive competitive intelligence.
You do not need a six-figure enterprise platform to do this. A self-hosted stack built on open source tools costs virtually nothing beyond server time, gives you full control, and keeps your competitive data in-house.
## What to Actually Monitor
Effective competitor monitoring is not about watching everything. It is about watching the right signals at the right frequency.
**Pricing intelligence.** Track product prices, promotional banners, sale timing, and pricing page changes. Pricing changes are high-signal events: a competitor raising prices suggests confidence or cost pressure. Frequent promotions suggest inventory issues or growth pressure. Either insight informs your strategy.
**Messaging and positioning.** Monitor homepage headlines, taglines, and key CTAs. Subtle shifts reveal strategic decisions. A shift from "powerful" to "easy" suggests a different buyer persona. A new emphasis on "security" over "speed" signals repositioning you need to understand.
**SEO and technical structure.** Watch meta titles, meta descriptions, schema markup additions, and heading structure changes. A competitor adding FAQ schema to key pages is optimizing for featured snippets. New landing page templates suggest paid campaign expansion.
**Content strategy.** Monitor blog feeds, sitemap changes, and new page creation. Content investments take months to pay off. Knowing where competitors invest now tells you where they expect to compete in six months.
## The Open Source Stack
### Changedetection.io: The Foundation
For straightforward page monitoring, Changedetection.io is remarkably capable. It tracks content changes on any webpage, highlights differences at the word level, and sends alerts through email, Slack, Discord, or webhooks.
Key capabilities include a visual CSS selector tool for monitoring specific page sections, built-in price tracking mode that extracts pricing metadata, Playwright integration for JavaScript-heavy pages, and threshold alerts that only notify when price changes exceed a defined percentage.
Deploy it with a single Docker command:
```bash
docker run -d \
--name changedetection \
-p 5000:5000 \
-v changedetection-data:/datastore \
ghcr.io/dgtlmoon/changedetection.io
```
For pages that require JavaScript rendering, add a Playwright container via Docker Compose. This handles roughly 80% of competitor monitoring needs with minimal configuration.
### Scrapy: Structured Data at Scale
When you need to extract structured data across many pages, monitoring an entire product catalog, tracking prices across dozens of SKUs, or auditing technical SEO elements site-wide, Scrapy is the right tool.
A practical Scrapy spider for competitor pricing pulls product names and prices, compares them against previous runs stored as JSON, and flags changes with percentage calculations. Schedule it via cron to run daily and pipe the output to your alert system.
For anti-bot protection on modern websites, pair Scrapy with a residential proxy service and configure polite scraping settings: download delays between requests, limited concurrent connections per domain, and user agent rotation.
### AI-Powered Change Interpretation
Raw diffs are useful, but context is better. When Changedetection.io flags a change, pipe the old and new content through an LLM to get a one-sentence summary of what changed, what the change likely signals about competitor strategy, whether it warrants immediate attention, and recommended actions for your team.
This turns raw monitoring data into actionable intelligence without requiring a human to review every diff.
### Orchestrating with n8n
For teams that prefer visual workflow builders, n8n provides a self-hosted alternative to Zapier that ties the stack together. A typical workflow runs Scrapy on a schedule, reads the results, checks for changes against the previous run, and pushes alerts to Slack with formatted messages showing the competitor name, old price, new price, and change percentage.
## Putting It Into Practice
### Sitemap Monitoring for New Content
One of the highest-value, lowest-effort monitors you can set up tracks competitor sitemaps for new URLs. A simple Python script fetches all URLs from a sitemap, compares them against the previous run, and reports additions and removals. When a competitor quietly launches 15 new location pages or a cluster of blog posts targeting a new keyword vertical, you know about it immediately.
### SEO Change Tracking
A Scrapy spider that extracts meta titles, meta descriptions, canonical tags, heading structure, and JSON-LD schema types from competitor pages, then hashes the results for change detection, reveals where competitors are investing in [organic search optimization](/services/seo/). When their homepage meta title suddenly includes a new keyword, or they add Product schema to their catalog, that is intelligence you can act on.
## Ethics and Practical Boundaries
Monitoring publicly available information on competitor websites is standard business practice. That said, respect boundaries: honor robots.txt directives, use reasonable request delays, never attempt to access authenticated content, and focus exclusively on public pages and public pricing.
## When to DIY vs. Bring in Help
Self-hosted monitoring works well when you have technical resources to maintain scripts, a manageable number of competitors (3-5), relatively stable competitor website structures, and time to review alerts and derive insights.
Consider agency support when you need monitoring at scale across many competitors, structured reporting and strategic analysis layered on top of raw data, integration with broader competitive intelligence, or someone else to handle the maintenance.
Your competitors made changes to their website this week. You can find out next quarter when someone mentions it in a meeting. Or you can know by Monday morning.
The tools are free. The infrastructure cost is negligible. The only investment is the hour it takes to set up your first monitor. If you want help building a competitive monitoring system tailored to your market, [we build these for clients regularly](/services/seo/).
---
## The End of Unlimited AI: Why Envato Retreat Signals a Market Correction
## The End of Unlimited AI: Why Envato's Retreat Signals a Market Correction
When Envato Elements slashed AI generations from unlimited to just 10 per month, the marketing industry cried foul. But the uncomfortable truth is this: unlimited AI access was never sustainable. Envato's retreat is the canary in the coal mine for every agency that built workflows around infinite AI compute.
The question is not whether your tools will follow suit. It is when.
## The Hidden Cost of "Free" AI Generations
Unlimited AI pricing hid a massive infrastructure problem. Every AI generation consumes real compute, real electricity, and real water for data center cooling. Training a single frontier model like GPT-4 required roughly 62 gigawatt-hours of electricity, enough to power 5,000 European homes for a year. By 2030, AI-driven data centers are projected to consume 945 terawatt-hours annually.
SaaS companies absorbed these costs for two years, betting on growth. That bet is ending. Envato is not the exception here, they are the leading indicator.
The pricing models that worked for stock photo downloads, where storage costs are relatively fixed, break down completely when every single generation demands fresh compute, electricity, and cooling. Unlimited AI was always a subsidy. Now the bill is arriving.
## What This Means for Marketing Agencies
For agencies that built workflows around unlimited iteration, the shift forces a strategic rethink. We think that is actually a good thing.
### The Volume Game Is Over
When AI was unlimited, anyone could generate 100 logo variations, 50 headline options, and 30 social media captions without thinking twice. Quantity became the differentiator. With hard generation limits, craft matters again. Strategy matters. Knowing what to ask for on the first or second try matters more than iterating endlessly.
This is not hypothetical. We have seen agencies that relied on AI-generated volume suddenly struggling when Canva, Adobe Express, and Jasper each introduced their own generation caps in early 2026. The agencies that had no process beyond "generate more options" had nothing to fall back on. The ones that used AI as a refinement tool, starting with strategic direction and using AI to execute, barely noticed the change.
### Budget Discipline Returns
Agencies will need to treat AI generation costs the same way they once treated stock photography: as visible line items that get planned, tracked, and potentially passed through to clients. This transparency is healthier than the current model where AI costs hide in subscription overhead and nobody asks questions until prices jump.
For agencies managing multiple client accounts, the math adds up fast. A 10-person creative team generating 50 images per day across three AI tools hits meaningful cost thresholds quickly under metered pricing. Without tracking, you will not know where the budget goes until the invoice arrives.
### Strategic Beats Experimental
The agencies that thrive in a metered-AI world will be those who deliver better creative with fewer generations. That rewards professionals who understand effective prompting, intelligent critique, and manual refinement rather than brute-force iteration.
Prompt engineering is no longer a nice skill to have on the team. It is a cost control mechanism. A well-structured prompt that produces a usable result on the first or second attempt versus a vague prompt that requires 15 iterations is the difference between a profitable project and a losing one.
## The Boutique Agency Advantage
If you are running a large agency built on volume and scale, this shift is existential. Your competitive advantage was iteration speed: throw AI at everything and let quantity win. But for a boutique agency like ours, built on expertise and strategic thinking, metered AI levels the playing field.
When everyone has limited AI access, the differentiator shifts back to who makes better decisions with less. That is craft. That is strategy. That is experience.
## What You Should Do Right Now
**Audit your AI usage.** Track how many AI generations you actually consume across all your tools each month. Most agencies are surprised by the volume when they actually measure it.
**Develop AI usage guidelines.** When does AI generation make sense versus traditional methods? Document those decisions now, before you are forced to make them under constraint.
**Educate your clients.** Start the conversation about AI costs before it becomes a crisis. Transparency now prevents uncomfortable conversations later.
**Invest in prompt engineering.** The ability to get high-quality results with fewer iterations is now a competitive advantage, not a nice-to-have.
**Build hybrid workflows.** Not everything needs AI. Identify which parts of your creative process benefit from AI generation and which are better served by traditional methods, templates, manual design, or licensed assets. The most resilient agencies use AI as one tool among many, not as the entire toolbox.
## The Correction Is Coming, and That Is Okay
Envato's move is not about greed. It is about math. Unlimited AI access was economically unsustainable, environmentally irresponsible, and artificially inflated market expectations.
Adobe, Canva, and every other creative platform will follow. The agencies that prepare now will thrive. The ones that wait will be scrambling to explain why their costs tripled overnight.
We have been preparing for this shift at Choice OMG by building workflows that prioritize strategic AI use over brute-force generation. If you are rethinking how AI fits into your marketing operations, we can help you build a sustainable approach. [See how we work](/services/).
The age of unlimited AI is ending. The age of strategic AI is just beginning.
---
## The Website Rebuild That Made Every Booking Measurable
A four-clinic optometry group asked for proof, not promises: which locations and which campaigns produce booked appointments. Their decade-old WordPress site could not answer, so we rebuilt it from the ground up on a code-first stack, cut 126 crawled URLs down to 46 purposeful pages, and engineered measurement across the third-party booking domain that had been erasing every appointment's origin. Two months after cutover the site loads its headline in 1.7 seconds on throttled mobile, organic click-through has nearly tripled, every tracked commercial ranking survived the migration, and July alone recorded 460 completed new-patient bookings with channel and location attribution attached.
## The Challenge
The previous site was a WordPress build carrying a decade of accumulated technical debt, and it failed the practice in three distinct ways.
Performance dragged on the devices that matter. Mobile audits during discovery scored the old site around 70, with recurring image-delivery and caching problems. Most "optometrist near me" traffic is mobile, and a slow site costs bookings before a patient ever reaches the contact page.
The search index was bloated with pages that never produced a patient. Search engines were crawling 126 URLs, and a large share were aging blog posts on general eye trivia. In March and April 2026 alone, pages outside the site's commercial core generated roughly 44,000 impressions and just 131 clicks: a click-through rate under 0.3%. That surplus content diluted the site's topical focus while the four location pages and the specialty services fought for attention.
Measurement was broken at the most important step. The practice books appointments through a third-party scheduling platform that runs on its own separate domain. When a patient clicked from the website into the booking system, analytics treated the jump as the end of one visit and the start of an unrelated one, so the original ad, campaign, or organic search was lost. The practice could see traffic, and it could see bookings, but it could not connect the two. The owner had asked specifically for year-over-year, per-location conversion reporting, and the old architecture made that impossible.
## Our Approach
We rebuilt the entire site on a code-first stack: Next.js with TypeScript, content managed as structured data and MDX in the codebase, deliberately no CMS. That choice removes the WordPress plugin-security treadmill, raises the performance ceiling, and makes the site maintainable by AI agents, because structured, typed, documented code is something an agent can read and modify confidently. The full build is 46 pages: home, 4 location pages, 12 service pages, nearly 20 optometrist profiles, plus booking, insurance, contact, and policy pages.
Every page was structured for local search. Location pages carry MedicalClinic and LocalBusiness structured data with accurate name-address-phone, hours, and live Google review ratings; service pages carry FAQPage markup; every provider profile carries Physician markup. Signature specialty services route deliberately to the clinics best positioned to deliver and rank for them, so the right location competes for the right high-value search. The clinics' 4.8 to 4.9 star Google ratings, built on hundreds of reviews each, surface directly on the location cards.
Delivery is edge-first: the site sits behind a CDN with an intentional caching policy (static assets for a year, images for a week, HTML for an hour, API bypassed) and an automatic cache purge on every deploy.
The measurement layer was the hardest engineering in the project. We stitched sessions across the practice's domain and the booking provider's domain so the original source, medium, and campaign travel with the patient instead of resetting at the handoff. The booking handoff itself was re-engineered as a genuine trackable click, because cross-domain linking silently ignores programmatic redirects. Our identity cookie is namespaced separately so the booking provider's own analytics remain completely untouched. Booking-funnel events flow into the practice's analytics property, and Google Ads click IDs are captured on landing and forwarded through to the booking URL. Everything runs through Google Tag Manager, so the marketing team can adjust tracking without a code deploy.
Accessibility and privacy were treated as first principles, not add-ons: WCAG 2.2 Level AA across public pages, no web form that invites medical detail, form contents that never reach analytics, and external PHI-handling systems clearly disclosed. The contact form's disclosure satisfies Alberta PIPA without a consent banner.
## The Results
1.7-second mobile Largest Contentful Paint with layout shift of 0.08, both inside Google's "good" Core Web Vitals thresholdsSource: Lighthouse 12 lab testing on emulated mobile with network and CPU throttling, July 2026
Organic click-through rate up 2.6x (1.1% to 2.9%) with average position steady, after pruning ~44,000 low-intent impressions per two-month windowSource: Google Search Console, March-April vs. June-July 2026
24 of 38 tracked commercial keywords in the top 10 both before and after the full URL migration, with identical top-3 countsSource: daily position tracking
460 completed new-patient bookings measured in July each carrying source, campaign, and location contextSource: GA4 cross-domain booking events, verified against our reporting warehouse
The speed results hold up under scrutiny. The rebuilt homepage paints its headline in 1.7 seconds on an emulated mobile device with network and CPU throttling, with a cumulative layout shift of 0.08. The whole page, analytics and tag manager included, weighs 746 KB across 34 requests, and server response time stays under 350 ms through the CDN. The image-delivery and caching problems that dogged the old build are designed out rather than patched: image optimization is native to the framework, and caching is a declared policy at the edge instead of a plugin setting.
The search results show a deliberate trade of empty impressions for qualified clicks. Sitewide organic click-through rose from 1.1% to 2.9% while average position held around 9, which means the site now earns roughly the same commercial clicks from a third of the impressions. The pages that book patients held or grew through the migration: location pages averaged 17.2 organic clicks per day before cutover and 18.3 after, and clicks to optometrist profiles rose 67% per day, because patients search for doctors by name and nearly twenty structured, personal profile pages now answer them. Rankings crossed the migration intact, with 24 of 38 tracked commercial keywords in the top 10 on both sides of cutover.
The attribution results answer the owner's original question. Since cutover, the booking funnel reports into the practice's own analytics across the booking provider's domain boundary: 133 website booking handoffs in the partial May window, 401 in June, and 436 in July, alongside 460 completed new-patient bookings in July and 370 tracked phone-call clicks since June. New-patient completions can exceed website handoffs because the cross-domain layer also captures bookings that begin outside the site, from bookmarks or Google Business Profile links, so the practice sees the whole funnel rather than just the slice that started on its homepage.
The measurement layer also feeds the advertising forward. Conversion values distinguish a specialty contact-lens fitting from a routine check, five remarketing audiences are defined and mapped to campaign uses, and every event carries a location identifier, so dashboards finally report conversions per clinic.
Two metrics are behaving the way post-migration metrics do, and we monitor both daily rather than declaring victory early. Specialty-service pages moved to new URLs and are still re-earning the rankings their old counterparts held, and a volume-weighted visibility index that includes that long tail dipped through the migration window for the same reason. The tracked commercial keyword set is stable, which is the leading indicator we care about; service-page recovery is the trailing one, and it is reported honestly, per location, from the same measurement layer described above.
Read more about [web design and development](/services/web-design/), [local SEO for multi-location practices](/services/local-seo/), and [our optometry industry work](/industries/optometry/). If your website can show you traffic but cannot show you booked appointments, [talk to us](/contact/).
---
## Pivoting from Poor Meta Leads to Qualified Google Ads Consultations for a Personal Injury Firm
A personal injury law firm was spending on Meta Ads but getting leads with fake phone numbers and no real intent. We implemented SMS verification on forms, which improved lead quality but reduced volume. The lead quality data made the case for pivoting primary spend to Google Ads, targeting high-intent searchers actively looking for a lawyer. Combined with local map pack optimization in a competitive Southern California market, the firm went from chasing bad leads to booking qualified consultations. Budget: $3,130+ per month.
## The Challenge
Personal injury law is one of the most expensive verticals in digital advertising. Google Ads clicks for "personal injury lawyer" can cost $100 or more in competitive markets. That cost pushes many firms toward Meta Ads (Facebook and Instagram), where clicks are cheaper and lead forms are easy to deploy, even though cheaper leads aren't necessarily better ones.
This firm was running Meta lead generation campaigns and spending meaningful budget on them. The volume looked acceptable on paper: leads were coming in, forms were being filled out. But when the intake team followed up, the reality was different. Phone numbers were invalid or disconnected. Email addresses were throwaway accounts. Many leads showed no recollection of filling out a form at all. The firm was paying for volume that didn't convert to consultations, let alone retained cases.
This is a known pattern with Meta lead ads, especially in high-value legal verticals. The platform optimizes for form completions, not lead quality. When someone scrolling through their feed taps a lead form, the barrier to submission is so low that many fills are impulsive, accidental, or fraudulent, and this firm was spending thousands per month on exactly that problem.
The market added another layer of difficulty. Southern California's Orange County area is saturated with personal injury firms competing for the same pool of potential clients. Standing out in local search results requires more than just spending. It requires a strategic approach to which channels get what portion of the budget, and the tracking infrastructure to measure what's actually working.
## Our Approach
Before pivoting away from Meta, we wanted data, not assumptions. We implemented SMS verification on the lead forms: after a prospect submits their information, they receive an SMS code that they must enter to confirm. This single step filtered out the vast majority of fake and low-intent leads.
The results were stark. Lead volume from Meta dropped significantly once verification was in place, but the leads that made it through were real people with real phone numbers who had confirmed their intent. This gave us a clean dataset to compare Meta lead quality against other channels. The numbers made the decision clear: Meta was producing some legitimate leads, but at a cost per qualified lead that was higher than Google Ads despite the lower cost per click.
We built the Google Ads strategy around high-intent keywords. "Personal injury lawyer near me," "car accident attorney," and procedure-specific queries like "slip and fall lawyer" target people who have already decided they need legal help and are actively searching for a firm. The intent gap between these searches and someone passively scrolling Meta is enormous.
Campaign structure followed the firm's practice areas. Motor vehicle accidents, premises liability, workplace injuries, and medical malpractice each got dedicated campaigns with keyword sets matching the specific terms potential clients use when searching for help with that type of case. Ad copy addressed the specific concerns of each case type: statute of limitations urgency, free consultation offers, and "no fee unless we win" messaging that addresses the financial barrier to hiring a lawyer.
Local map pack optimization was the second priority. For "personal injury lawyer near me" searches, the local three-pack is prime real estate. We optimized the firm's Google Business Profile with accurate practice area descriptions, review management, and regular profile updates. In a market with dozens of competing firms, GBP signals like review volume, review recency, and profile completeness influence map pack rankings.
Conversion tracking was set up to measure what actually matters: consultation bookings. Not form fills, not phone calls to the front desk, but confirmed consultation appointments. This is the metric that correlates to case intake, which correlates to revenue. We tracked the full funnel from ad click through form submission through intake confirmation so the firm could see actual cost per consultation, not just cost per lead.
Meta stayed in the mix at a lower budget for brand awareness and retargeting, where it performs better than as a primary lead generation channel. The bulk of the budget shifted to Google Ads where high-intent searchers were actively looking for representation.
## The Results
Lead quality transformed after SMS verification filtered out fake and low-intent form fills from Meta campaignsSource: intake team conversion rate data before and after verification
Primary spend pivoted to Google Ads with consultation bookings as the optimization target, not just lead volumeSource: conversion tracking on consultation booking flow
The pivot from Meta to Google Ads wasn't based on preference or theory. It was driven by actual lead quality data that showed the true cost per qualified consultation on each channel. The economics work when a click costs $100 and one in five converts to a retained case worth five figures; they don't when a click costs $5 but only one in fifty submissions is even a real person.
SMS verification, which many firms resist because it reduces volume, turned out to be the most valuable diagnostic tool we deployed. It didn't just improve Meta lead quality; it gave us the data that justified the channel pivot. Without verification, the firm would have continued spending on Meta based on misleading volume metrics.
The local map pack investment delivered results in a market where map pack visibility is heavily contested. The firm's GBP now consistently appears for high-intent local searches, providing a steady stream of organic consultation requests that supplement the paid campaigns.
At $3,130+ per month in ad spend, every dollar has to work. The infrastructure we built, from SMS verification to full-funnel conversion tracking to channel comparison, ensures budget goes to the channels and campaigns that produce retained cases, not just activity metrics.
[Learn about our Google Ads management](/services/google-ads/) and read about [when to use Google Ads versus Meta Ads](/blog/google-ads-vs-meta-ads/).
---
## Building Organic Visibility from Scratch for an Outdoor Recreation Brand
An outdoor recreation brand needed a complete web presence built from the ground up. We designed a performance-first site that passed Core Web Vitals on launch day, implemented proper schema markup and technical SEO foundations, and built a content strategy targeting niche keywords with low competition but strong commercial intent. The brand went from invisible online to ranking for its target terms within months.
## The Challenge
Starting from zero is both liberating and daunting. This outdoor recreation brand had a physical presence and a loyal local customer base, but no meaningful web presence. No website worth mentioning, no organic search visibility, and no infrastructure for tracking performance or competitors.
The outdoor recreation space in Western Canada is a mix of established brands with deep content libraries and small operators with barely functional websites. The opportunity was in the middle: niche keywords with real commercial intent that the big brands were too broad to target effectively and the small operators weren't sophisticated enough to pursue.
The brand needed more than a brochure site. They needed a platform that could compete technically, rank for targeted keywords, and convert visitors into customers. And they needed it built right the first time, because retrofitting SEO and performance into an existing site is always harder than building with those priorities from the start.
## Our Approach
We designed the site with Core Web Vitals as a first-class constraint, not an afterthought. That meant decisions about image formats, font loading, JavaScript execution, and layout stability were made during design, not discovered during a post-launch audit. Images were served in WebP format with proper sizing and lazy loading. Fonts were subset to include only the characters needed and loaded with font-display: swap to prevent layout shift. JavaScript was minimized and deferred where possible. The site passed all Core Web Vitals thresholds on its first PageSpeed assessment after launch. That's unusual, and it's only possible when performance is treated as a design requirement rather than a technical nice-to-have.
The technical SEO foundation was built into the site architecture. Every page had proper heading hierarchy, semantic HTML, and structured data markup relevant to the business type. We implemented Organization, LocalBusiness, and Product schema where applicable. The XML sitemap was generated automatically, canonical tags were in place from day one, and the site's internal linking structure was designed to distribute authority to the pages that mattered most. We also configured proper crawl directives and ensured that the site's URL structure was clean, descriptive, and stable from launch so there would be no need for redirects later.
The content strategy focused on keywords that met two criteria: commercial intent strong enough to drive revenue, and competition low enough to achieve rankings without years of domain authority accumulation. In outdoor recreation, these keywords tend to be specific to activities, locations, or equipment categories rather than broad terms. Someone searching for a specific activity in a specific region is much closer to a booking decision than someone searching for generic outdoor recreation content. We used keyword research tools to validate volume and difficulty, then prioritized terms where the brand could realistically reach page one within six months.
We built out content in tiers. The first tier was core service and product pages optimized for the highest-value keywords. The second tier was supporting content that targeted longer-tail variations and provided internal linking support to the core pages. Each piece of content was written to be genuinely useful to someone planning an outdoor activity, not just to satisfy a keyword target. Location-specific guides helped searchers in different regions find relevant information, while activity-specific content captured people at different stages of their planning process.
The design itself reflected the brand's identity. Outdoor recreation brands need to convey adventure and capability through visual design without sacrificing the performance metrics that affect rankings. We achieved this through optimized photography, purposeful use of whitespace, and a visual hierarchy that guided visitors from inspiration to action without relying on heavy frameworks or animation libraries that would have slowed the site down.
## The Results
Core Web Vitals passing on launch day across all page typesSource: Google PageSpeed Insights and Chrome User Experience Report
First-page rankings for target keywords within 4 months of launchSource: daily position tracking
Launching with a technically sound foundation made the content strategy dramatically more effective. New pages started ranking faster than we typically see because the site wasn't fighting technical debt. There were no crawl errors to fix, no performance issues to resolve, no structural problems to work around.
The niche keyword strategy paid off quickly. Within four months, the site was ranking on the first page for its primary commercial keywords. These weren't vanity terms with massive volume; they were specific, high-intent queries from people actively looking to buy or book. The conversion rate from organic traffic reflected that intent.
The brand now has a web presence that matches its physical reputation, a growing organic traffic stream, and the technical foundation to scale content and visibility as the business grows. The performance-first approach means that as content is added, the site doesn't slow down. New pages inherit the same technical foundation and start ranking faster because they're part of a technically sound domain.
The tiered content strategy continues to build on itself. Each new piece of supporting content strengthens the topical authority of the core pages, and the daily position tracking shows this compounding effect clearly. Pages that started on page two are moving to page one as the overall site authority grows.
[Read about our approach to web design](/services/web-design/) and how we [integrate SEO from the start](/services/seo/).
---
## Scaling a Multi-Location Optometry Group Without Cannibalizing Rankings
A growing optometry group needed to double its clinic count without its locations competing against each other in search results. We built a location-specific SEO strategy with independent Google Business Profiles, daily position tracking across all locations, and cannibalization detection that flagged problems before they affected rankings. Patient acquisition cost dropped roughly 30% even as the practice expanded from 3 to 6 locations.
## The Challenge
Multi-location healthcare practices face a problem that single-location businesses never think about: your own clinics start competing against each other in search results. When a patient in one part of a city searches for "optometrist near me," you want the nearest clinic to show up, not whichever location happens to have the strongest domain authority that week.
This optometry group had three established clinics in Alberta and was planning to open three more. Their existing SEO was managed as a single entity: one set of keywords, one content strategy, one Google Business Profile getting most of the attention. The other two profiles were barely maintained. Rankings were inconsistent across locations, and the practice had no visibility into which clinic was winning (or losing) for which searches in which areas.
The expansion plan made the problem urgent. Six locations targeting variations of the same keywords in overlapping service areas would create a mess without a structured approach to local search.
## Our Approach
We started by auditing every location's search presence independently. Each clinic got its own keyword map based on its specific service area, competitive landscape, and the search behavior patterns we could see in that part of the province. A clinic in a smaller market with one competitor needs a fundamentally different keyword strategy than a clinic in a competitive urban area. We mapped keyword intent by location: patients searching near a mall location use different terms than patients searching near a hospital campus. Those differences informed everything from page titles to ad copy.
Each Google Business Profile was treated as its own project. We standardized the basics (categories, attributes, service descriptions) but customized the elements that matter for local ranking: review response strategy, photo cadence, post frequency, and Q&A content. The profiles for the three existing clinics needed cleanup and optimization. One had an incorrect address pin, another had outdated hours that had been wrong for over a year. The three new clinics needed profiles built from scratch with the right foundation from day one, including pre-launch photo content and initial review generation strategies timed to opening week.
On the website, we built location-specific landing pages that targeted each clinic's unique keyword set. The key was making these pages genuinely useful for patients in each area rather than thin location doorway pages. Each page included location-specific information: the optometrists at that clinic, services available at that specific location, insurance providers accepted, and local context that made the page worth ranking. We implemented LocalBusiness schema markup on each location page with accurate coordinates, service areas, and operating hours so search engines could clearly distinguish each clinic as a separate entity.
The content strategy went beyond landing pages. Each location got a cadence of locally relevant content: community events, seasonal eye health tips relevant to that area's demographics, and educational content about the specific services that location emphasizes. A clinic near a university campus got content about digital eye strain and student eye care. A clinic in a family-oriented suburb got content about children's vision screenings. This wasn't just SEO; it was content that patients found genuinely useful, which generated engagement signals that reinforced rankings.
The infrastructure piece was critical. We set up daily position tracking across all six locations, monitoring each clinic's target keywords segmented by location. This gave us a cannibalization detection system: if two locations started ranking for the same keyword in the same geographic area, we could see it within 24 hours and adjust before it affected performance. Without this monitoring, cannibalization issues can quietly erode rankings for weeks before anyone notices. The tracking dashboard gave the practice's marketing team visibility into all six locations in a single view, replacing a fragmented process where each clinic was a black box.
## The Results
~30% reduction in patient acquisition cost across the practice, even while expanding from 3 to 6 locationsSource: practice management system booking data correlated with marketing spend
6 independently ranking locations with zero sustained cannibalization incidentsSource: daily position tracking across all locations
The reduction in acquisition cost came from two things: better organic visibility across all locations reduced dependence on paid channels, and the location-specific approach meant each clinic was attracting patients actually in its service area rather than competing for the same pool.
The daily monitoring system caught three cannibalization incidents during the expansion. Each was resolved within a week through content adjustments and GBP signal optimization. Without the tracking infrastructure, these would have gone undetected and compounded.
The three new locations reached first-page rankings for their primary keywords within four months of launch, faster than the industry average for new healthcare locations. The foundation work on technical SEO and proper schema markup gave them a head start that organic-only efforts without technical investment simply cannot match.
The practice now has a scalable playbook for adding new locations: when the seventh clinic opens, the keyword mapping, GBP setup, content strategy, and monitoring integration follow a documented process refined through the first six, so growth no longer means starting from scratch with each new location. The monitoring infrastructure scales linearly, too. Adding a new location to the tracking system takes hours, not weeks, and the cannibalization detection works across any number of locations.
[Learn how local SEO drives patient acquisition for healthcare practices](/services/local-seo/) or read about [our approach to organic search strategy](/services/seo/).
---
## Google Ads and GBP Optimization Driving New Patient Bookings for a Medical Aesthetics Clinic
A medical aesthetics clinic in Winnipeg needed to stand out in a crowded market where competitors were all bidding on the same broad procedure terms. We built Google Ads campaigns around procedure-specific keywords with high commercial intent, optimized their Google Business Profile for "near me" searches, and set up conversion tracking for consultation bookings. Our daily health checks caught a site performance issue that would have degraded Quality Scores and increased costs if left unaddressed.
## The Challenge
Medical aesthetics is one of the more competitive healthcare verticals in search advertising. In a mid-size market like Winnipeg, a dozen clinics may be bidding on terms like "Botox" and "dermal fillers," driving up click costs while competing for the same pool of potential patients.
This clinic offered a range of injectable and aesthetic treatments and had a solid reputation locally, but their online patient acquisition wasn't keeping pace with newer competitors who were investing heavily in digital marketing. Their existing Google Ads setup was basic: a single campaign with broad keywords, generic ad copy, and no meaningful differentiation from competing ads showing up for the same queries.
The Google Business Profile was maintained but not optimized. In aesthetics, GBP is particularly important because patients want to see a clinic's work (through photos), read reviews from real patients, and confirm the clinic is nearby. An underoptimized profile in this space means losing potential patients to competitors who present a more complete and compelling listing.
The clinic's website was functional but had performance issues. Page load times were inconsistent, and some procedure pages were loading slowly enough to affect user experience. In Google Ads, site performance directly impacts Quality Score, which determines how much you pay per click and whether your ads show at all, so a slow site quietly drives up advertising costs.
## Our Approach
We restructured the Google Ads account around procedure-specific campaigns. Rather than one campaign bidding on broad aesthetics terms, we built separate campaigns for each procedure category: injectables, skin treatments, body contouring, and consultation-focused campaigns. Each campaign had tightly themed ad groups with keywords matching specific procedures and the intent signals that indicate someone is ready to book rather than just browsing.
The keyword strategy focused on high-intent queries. Someone searching "Botox clinic Winnipeg" is further along the decision path than someone searching "how long does Botox last." We targeted the former with direct-response campaigns and used the latter for awareness-level campaigns with lower bids and different ad copy.
The Google Business Profile received a thorough optimization. We updated categories to reflect the clinic's full service range, added procedure-specific descriptions, ensured business hours and contact information were accurate across all Google surfaces, and established a cadence for posting updates and responding to reviews. Photo content was updated to reflect the clinic's actual environment and results.
For conversion tracking, we implemented event tracking on the consultation booking flow: form submissions, phone clicks, and booking button interactions. This data fed back into Google Ads to inform bidding algorithms and let us measure actual cost per consultation booking rather than just cost per click.
We set up daily automated health checks on the clinic's website. These checks monitor page load performance, identify broken elements, catch console errors, and flag any degradation before it impacts ad performance. Within the first month, these checks identified a performance issue on two key landing pages. The pages were loading slowly due to unoptimized images and a render-blocking script, problems that weren't visible in normal browsing but were measurable in performance metrics and would have affected Quality Scores over time.
Budget monitoring ensured ad spend stayed on track as campaigns scaled. As we identified high-performing procedure campaigns and increased their budgets, the monitoring system verified that daily spend pacing remained consistent and flagged any anomalies caused by competitive pressure or seasonal demand shifts. Medical aesthetics has its own seasonal patterns: injectable treatments peak before holiday season and wedding season, and budget allocation needs to flex with that demand without losing control of overall spend.
Landing page optimization was ongoing. Each procedure campaign pointed to a dedicated landing page with content specific to that treatment: what to expect, recovery timelines, candidate qualification criteria, and consultation booking. These pages were designed for the aesthetics audience, which skews toward visual research and mobile browsing. Page speed, mobile responsiveness, and clear booking CTAs were tested and refined based on conversion data from each campaign.
## The Results
Consultation bookings increased with measurable attribution to specific procedure campaignsSource: conversion tracking on booking flow
Site performance issue caught by automated health checks before it degraded Quality ScoresSource: daily health check monitoring
The procedure-specific campaign structure revealed which treatments were the strongest patient acquisition channels. The clinic was able to allocate more budget to their highest-margin procedures and reduce spend on categories where the cost per consultation was too high relative to treatment value.
GBP optimization produced measurable increases in profile views and direction requests. For a location-based business like an aesthetics clinic, "near me" visibility translates directly to foot traffic and consultations.
The performance fix identified by our health checks was the kind of issue that compounds quietly. Quality Score degradation from slow pages increases cost-per-click gradually, so there's no single moment where the problem becomes obvious. By catching and fixing the issue early, we prevented what would have been a slow, steady increase in the clinic's advertising costs.
The ongoing data from procedure-specific campaigns also informed the clinic's broader marketing decisions. When the data showed that certain treatments had consistently lower acquisition costs and higher booking rates, the clinic adjusted its promotional calendar to lean into those treatments during key seasons, building its marketing strategy on actual campaign data rather than assumptions about what patients want.
[Learn about our Google Ads management](/services/google-ads/) and [local SEO services for healthcare practices](/services/local-seo/).
---
## Building Local Search Presence for a Specialized Industrial Services Company
An industrial services company in rural Alberta had no meaningful web presence despite operating in a niche with high-value contracts. We built their local search visibility from scratch through Google Business Profile optimization, citation building, and service-area-specific content. The keyword set was small but each ranking position had direct revenue impact, and our monitoring infrastructure tracked every gain.
## The Challenge
Industrial services in rural Alberta occupy a particular corner of the market: low search volume, high contract value, and a very small number of competitors. When someone searches for specialized industrial services in a specific region, they're usually ready to hire. There aren't many casual browsers looking for aggregate crushing or oilfield services on a Saturday afternoon.
This company had operated successfully on relationships and reputation for years. Their website was a basic template with a company description and a phone number. No Google Business Profile. No presence in local directories. No content targeting the specific services and areas they cover. They were invisible online, and as younger decision-makers moved into procurement roles at their client companies, that invisibility was starting to cost them opportunities.
The challenge wasn't competing against a crowded field. It was establishing any presence at all in a space where the few competitors who had invested in their web presence were capturing all the search-driven leads by default.
## Our Approach
We started with the Google Business Profile. For a service-area business in a rural region, GBP is often the single most important search asset. We built the profile from scratch with accurate service area definitions, complete service descriptions using the terminology that industrial buyers actually search for, and proper business categorization. Industrial services don't always map neatly to Google's categories, so getting this right required understanding both the business and Google's category taxonomy. We tested multiple category combinations and monitored which configurations produced the best visibility for the company's core services.
Citation building came next. We identified the directories and industry-specific platforms where this company's competitors were listed and ensured consistent NAP (name, address, phone) information across all relevant platforms. In industrial services, industry-specific directories often carry more weight than general business listings. We prioritized platforms that industrial procurement officers actually use when sourcing contractors, including provincial contractor registries, industry association member directories, and supply chain platforms. The goal wasn't volume of citations but accuracy and relevance in the directories that matter for this industry.
The website needed a complete rebuild. We replaced the single-page template with a structured site that had individual pages for each service line. In industrial services, the terminology matters: the difference between "aggregate crushing" and "gravel production" might seem minor, but it's the difference between matching and missing the exact query a buyer uses. Each service page was written with the specific technical vocabulary of the industry and included the service areas where the company operates. We included details that matter to procurement teams: equipment capabilities, certifications held, safety record context, and project scale ranges. This information was already in the company's physical bid packages; we brought it online where search engines and early-stage researchers could find it.
The site design reflected the industrial context. Clean, professional, fast-loading pages with clear calls to action. No unnecessary animation or complex layouts. The target audience, project managers and procurement officers, wants information quickly and judges credibility by professionalism, not visual flair. The site passed Core Web Vitals on launch, which matters even in niches with low volume because Google's ranking signals apply regardless of search volume.
We set up daily position tracking across the company's target keyword set. In a niche this specialized, the keyword list was small, maybe 30 terms. But each keyword represented a direct line to high-value contract opportunities. Tracking positions daily meant we could see the impact of every optimization and respond quickly if a competitor made a move. We also monitored the competitors' web activity, so when a rival updated their site or started appearing for new terms, we knew immediately and could adjust our strategy.
## The Results
First-page GBP visibility for primary industrial service keywords within 3 monthsSource: daily position tracking and GBP insights
Search-driven leads from zero to a consistent monthly volumeSource: call tracking and form submissions
The timeline from zero presence to meaningful visibility was faster than expected. Rural and industrial niches reward early movers, and this company was the first in its specific service area to invest in a structured local SEO approach.
The return on investment was significant because of the contract values involved. A single lead from organic search that converts to a contract can pay for a year of SEO work in industrial services. The company went from zero search-driven leads to receiving qualified inquiries specifically from prospects who found them through search.
Our monitoring infrastructure continues to track positions daily. In a small niche, competitor movements are immediately visible, and we can respond before they affect lead flow. The company now has a web presence that matches its reputation in the field, and for the first time, prospects are finding them through search rather than exclusively through existing industry relationships.
For specialized B2B businesses, low search volume doesn't mean low value. In industrial services, a keyword with 20 monthly searches can represent millions in annual contract revenue, and the businesses that invest in owning those keywords capture opportunities their competitors don't even know exist online.
The infrastructure we built, from GBP to citations to a technically sound website to daily position tracking, gives this company a durable competitive advantage in its market. Competitors would need to make the same investment and wait months for results, and that first-mover advantage in a specialized niche compounds over time.
[Learn about our local SEO services for specialized businesses](/services/local-seo/) and [our approach to web design for industrial and trades companies](/services/web-design/).
---
## Content-Driven Web Optimization for a Seasonal HVAC Business
An HVAC company with furnace, air conditioning, and duct cleaning services needed a web presence that matched the seasonal rhythms of their business. We built service-specific pages tied to seasonal search patterns, created content around energy efficiency programs and maintenance topics, and tracked keyword positions to correlate publishing cadence with ranking gains. This turned seasonal search demand into a predictable lead pipeline.
## The Challenge
HVAC is one of the most seasonal businesses in digital marketing. In Winnipeg, furnace repair searches spike when temperatures drop below -20C in November, peak through January, and fall off by March. Air conditioning searches follow the opposite pattern, climbing in May and peaking in July. Duct cleaning has its own cycle, often tied to spring renovation season and fall pre-heating maintenance.
This company operated across all three service lines, plus a sister brand for specialized cleaning services. Their website treated all services equally, with a generic layout that didn't reflect the seasonal urgency that drives most HVAC purchasing decisions. When someone's furnace stops working at -30C, they're searching for immediate help, and the businesses that show up in that moment capture the call.
The content challenge was twofold. First, the site needed service-specific pages that could rank for the keywords customers use when they need each service. Second, the site needed supporting content that built topical authority throughout the year, not just during peak demand periods. HVAC companies that only show up in search during emergencies miss the customers who plan ahead: the ones scheduling maintenance, researching new systems, or comparing efficiency upgrades.
Managing the sister brand added complexity. Two related brands targeting overlapping keywords in the same market need careful coordination to avoid cannibalization, the same challenge as multi-location businesses but with brand identity instead of geography as the differentiating factor.
There was also a credibility problem common to HVAC websites: thin pages with no real content beyond a service name and a phone number. Homeowners making a decision about a furnace replacement or a maintenance contract want to understand what they're paying for, so the site needed to educate and build trust rather than function as a bare listing.
## Our Approach
We started with a keyword analysis mapped to seasonal demand curves. Using historical search volume data, we identified the specific terms that spike in each season and the timing of those spikes. This gave us a content calendar that wasn't arbitrary. We published furnace maintenance content in early fall before demand peaked, AC efficiency content in late spring before summer searches ramped up, and duct cleaning content aligned with the renovation and pre-season maintenance windows.
Each service line got dedicated pages built around the keywords people actually use when searching for that service. "Furnace repair Winnipeg" and "emergency furnace repair" are different keywords with different intent, and they needed different content. The emergency-focused pages were designed for fast scanning and immediate action (phone number prominent, service area clear, response time stated). The planned-service pages had more detail about what the service involves, pricing context, and what to expect.
We extended the approach beyond service pages, building out supporting content around topics that demonstrate expertise and capture searches from people who aren't in emergency mode: energy efficiency program guides (Manitoba has specific rebate programs that homeowners search for), seasonal maintenance checklists, and comparison content for system upgrades. Each piece linked back to the relevant service pages, creating topical clusters that signal authority to search engines.
For the sister brand, we established clear keyword boundaries. The parent HVAC brand owned furnace, AC, and general HVAC terms. The sister cleaning brand owned duct cleaning and related terms. Where overlap was unavoidable, we used canonical signals and internal linking to direct authority to the appropriate brand. Daily position tracking across both brands let us monitor for cannibalization and adjust when needed.
Our keyword tracking showed the relationship between content publishing and ranking gains in near real-time. When we published a furnace maintenance guide in September, we could track the position gains on related keywords through October and November as the content accumulated signals and search volume increased simultaneously.
## The Results
Seasonal content timing matched to demand curves with position gains visible before each peak periodSource: daily keyword tracking correlated with seasonal search volume data
Service-specific pages ranking for target keywords across furnace, AC, and duct cleaning verticalsSource: daily position tracking
The content strategy transformed the company's relationship with seasonal demand. Instead of reacting to peak seasons, they were positioned in search results before demand spiked. Furnace content published in September was ranking by November. AC content published in April was ranking by June. This lead time made the difference between capturing early-season searches and scrambling to rank once everyone else was also trying.
The keyword tracking data revealed a clear pattern: consistent content publishing produced compounding ranking gains, while gaps in publishing corresponded to stagnation or decline. This data made the business case for ongoing content investment tangible. Rather than asking the client to trust that content marketing works in theory, we could show them position gains correlating directly with publishing cadence.
The sister brand management proved that two related brands can coexist in the same market without undermining each other, as long as keyword targeting is intentional and monitoring catches overlap early. Both brands achieved strong rankings in their respective lanes without diminishing each other's performance.
The broader takeaway for seasonal businesses is that content strategy should follow the calendar, not fight it. HVAC companies that try to rank for furnace keywords by publishing content in December are already too late, while the companies that invest months before demand arrives own the search results when the temperature drops and the phone starts ringing. Our daily tracking data made that pattern visible, repeatable, and measurable enough to plan the next season's calendar around it.
[Read about our approach to SEO](/services/seo/), [web design for trades businesses](/services/web-design/), and [seasonal marketing strategies for trades companies](/blog/seasonal-marketing-trades/).
---
## Growing Implant Revenue from $300K to $800K with Airtight Attribution
A dental implant practice running high-value procedure campaigns needed conversion tracking they could trust. Individual procedures range from $20K to $50K, so every click matters and attribution must be airtight. We built the full conversion pipeline from GTM through GA4 to Google Ads import, created landing pages optimized for the implant consultation journey, and deployed automated monitoring that caught a tracking break within hours. Implant procedure revenue grew from $300K to $800K annually.
## The Challenge
Dental implant marketing operates on different economics than most healthcare advertising. A single full-arch implant case can generate $30,000 to $50,000 in revenue. At that value, the math on cost-per-click is completely different from a general dentistry practice spending $5 per click to book a cleaning.
This practice was spending significant budget on Google Ads to attract implant consultation requests. The problem was attribution. They knew roughly how many consultations they were booking, and they knew roughly what they were spending on ads, but the connection between the two was fuzzy. Conversion tracking was partially implemented: form submissions were being counted in Google Ads, but the data flowing from the website through Google Tag Manager to GA4 to Google Ads had gaps. Phone calls, which represent a significant portion of high-value procedure inquiries, weren't being tracked at all.
Without accurate attribution, the practice couldn't tell which campaigns, keywords, or ad copy were driving the consultations that actually converted to procedures. They were optimizing blind, and at their spend level, a single week of misattributed conversions could misdirect thousands of dollars.
The other challenge was the lag. Google Ads conversion imports from GA4 have a 24 to 72 hour delay. In high-spend campaigns, that lag means you're always making decisions based on data that's at least a day old. The bidding algorithms are working with delayed signals. If tracking breaks, you might not see the impact for three days.
Adding to the complexity, the patient journey for dental implants is long. A patient might click an ad, spend weeks researching, and then call to book a consultation. Traditional last-click attribution misses the full picture. The practice needed tracking that accounted for this extended decision timeline and could attribute revenue back to the initial touchpoint accurately.
## Our Approach
We rebuilt the conversion pipeline end to end. The chain is specific and each link matters: website event fires to Google Tag Manager, GTM processes and forwards to GA4, GA4 records the conversion, and Google Ads imports the conversion data from GA4 with the inherent 24-72 hour lag. Every link in that chain needs to work correctly, and we needed to verify that it was working continuously.
On the website, we implemented conversion tracking for every meaningful patient action: consultation request forms, phone clicks, and click-to-call events. Each conversion type was tagged with the relevant context (which procedure type, which landing page) so we could attribute revenue back to specific campaigns.
The landing pages were built specifically for the implant consultation journey. These patients aren't impulse buyers. They're researching a major health decision that involves significant cost and a multi-visit treatment plan. The landing pages reflected that reality: detailed procedure information, before-and-after context, financing options, and clear consultation CTAs. We built separate landing pages for different implant procedure types because a patient searching for "single tooth implant" is in a different mindset than someone searching for "full mouth dental implants."
Budget monitoring was critical at this spend level. We implemented automated checks that verify ad spend pace and flag anomalies. A budget that runs out at 2 PM because of a spike in competitive bidding means the practice misses evening searchers, who often research high-value procedures after work hours.
The most important piece was the automated conversion pipeline monitoring. We built checks that verify the full GTM-to-GA4-to-Google-Ads chain is functioning correctly. If any link in the chain breaks, an event stops firing, or import data stops flowing, the system flags it within hours rather than days.
## The Results
Implant procedure revenue grew from $300K to $800K annuallySource: practice management system revenue reports correlated with campaign attribution data
Tracking break detected within hours by automated pipeline monitoring, preventing an estimated $5,000+ in wasted spendSource: automated conversion pipeline audit logs
The revenue growth came from two factors working together. First, accurate attribution let us identify which campaigns and keywords were actually driving procedure revenue, and shift budget accordingly. Second, the optimized landing pages improved consultation conversion rates, meaning more of the clicks we paid for turned into booked consultations.
The automated monitoring proved its value early. Within the first quarter, it caught a tracking break caused by a website update that modified a form element the GTM trigger depended on. The break happened on a Friday afternoon. Without automated monitoring, it would likely have gone unnoticed until Monday at the earliest, and the impact wouldn't have shown in Google Ads data until Wednesday or Thursday. Instead, we were alerted within hours and had the fix deployed the same day.
At this practice's daily spend level, three days of broken conversion tracking would have caused Google Ads' automated bidding to lose its optimization signals, potentially wasting $5,000 or more before the data corrected itself, enough on its own to cover the cost of the monitoring system.
The practice now has a reliable, measurable patient acquisition channel that scales with budget. The attribution pipeline gives them confidence that the numbers they see reflect real patient activity, and the automated monitoring ensures that confidence is warranted. When the practice considers expanding its service offerings or opening a new location, the advertising infrastructure is ready to support that growth with the same level of tracking precision.
[Learn about our Google Ads management for high-value services](/services/google-ads/) and read about [why conversion tracking breaks happen and how to prevent them](/blog/conversion-tracking-breaks/).
---
## 316% Organic Traffic Growth for a Seasonal Construction Business
A paving and construction company had zero organic strategy and a website with serious technical problems. We fixed indexation issues, built out service-specific landing pages with location targeting, and timed the SEO work to winter months so position gains were in place before spring search volume spiked, growing organic traffic 316%.
## The Challenge
Construction and trades businesses often treat their website as a digital business card, listing what they do and a phone number to call and little else. This paving company was no different. The site had a handful of pages with thin content, no clear keyword targeting, and technical issues that were actively preventing search engines from indexing what little content existed.
The business was heavily seasonal. Paving work in Alberta runs roughly April through October, and the company's revenue was almost entirely concentrated in those months. Marketing had been limited to word-of-mouth and occasional print advertising. When competitors started showing up in search results for "paving company" and "asphalt driveway" queries, the phone started ringing less.
The seasonal dynamic created both a challenge and an opportunity. The challenge: the client needed results before spring, not after. The opportunity: competitors in the trades space rarely invest in SEO during the off-season, which meant winter was the best time to build and earn position gains with less resistance.
## Our Approach
The technical audit came first. We found a combination of problems that are common on older trades websites: duplicate content from a poorly configured CMS, pages blocked by a robots.txt file that had been copied from a template without modification, missing or duplicate title tags, and no XML sitemap. These are the kinds of issues that don't matter to someone visiting the site directly but effectively make large portions of the site invisible to search engines. The site had been live for years, but search engines were only seeing a fraction of its pages.
We fixed the technical foundation in the first month: proper robots.txt, XML sitemap submitted and validated, canonical tags on all pages, and a site structure that made sense for both users and crawlers. We also addressed page speed issues, compressing images, implementing lazy loading, and removing unused scripts that were slowing down every page load. The site went from a PageSpeed score in the 30s to passing Core Web Vitals.
Then we built out service-specific pages. The original site had a single "Services" page that listed everything in bullet points. We replaced it with individual pages for each service line: residential paving, commercial paving, asphalt repair, seal coating, concrete work, and excavation. Each page targeted the specific keywords people use when searching for that service, included the geographic areas the company serves, and had enough substantive content to demonstrate expertise. We wrote from the company's actual experience: material selection for Alberta's freeze-thaw cycles, project timelines that account for weather windows, and the differences between residential and commercial specifications.
The content work happened through the winter months. By February, the new pages were indexed and starting to accumulate authority. We tracked keyword positions daily and could see the upward movement accelerating through March and into April, exactly when search volume for paving and construction services begins its seasonal climb. The daily tracking data let us prioritize: pages that were close to page one got additional internal linking and content refinements to push them over the threshold before peak season.
Location targeting was the third pillar. The company served a specific region, and we made sure every service page included the cities and areas within that region. This wasn't keyword stuffing; it was genuinely useful information about where the company operates, travel considerations, and area-specific services. For rural areas, we included context about service radius and project minimums that helped qualify leads before they picked up the phone.
Google Business Profile optimization rounded out the strategy. The existing profile was bare: no photos, no posts, a generic description. We updated it with project photos, service descriptions matching the website content, and a regular posting cadence that kept the profile active through the winter when competitors' profiles went dormant.
## The Results
316% organic traffic growth within the first yearSource: Google Analytics year-over-year comparison
First-page rankings for primary service keywords before peak seasonSource: daily position tracking data
The timing mattered as much as the work itself. Because the technical fixes and content build happened during winter, the site was fully optimized and accumulating ranking signals by the time search demand spiked in spring. Competitors who started their SEO work in spring were months behind.
Daily keyword tracking showed a clear pattern: positions gained steadily through winter with low search volume, then held or improved as volume increased in spring. The site went from virtually invisible in search results to ranking on the first page for its primary service keywords in the markets that mattered.
The 316% traffic growth translated directly to leads. The company reported that the phone was busier than any previous season, with callers specifically referencing what they had found on the website. Several mentioned specific service pages as the reason they called, confirming that the detailed content was doing its job of converting search visitors into prospects.
The seasonal strategy is now repeatable. Each winter, we review keyword performance from the previous season, update content to reflect any new services or service area changes, and publish supporting content that builds authority ahead of the next spring surge. The first year proved the approach. Subsequent years have compounded the gains.
[See how we approach SEO for trades and construction businesses](/services/seo/) or read about [seasonal marketing strategies for trades companies](/blog/seasonal-marketing-trades/).
---
## 825% Return on Ad Spend for an Automotive Service Business
An automotive service business in Edmonton was spending on Google Ads but hemorrhaging budget through broad match keywords and poor campaign structure. We restructured campaigns into tight service-specific ad groups, built comprehensive negative keyword lists from search term analysis, set up proper conversion tracking for phone calls and form submissions, and implemented budget monitoring that checks spend every 30 minutes. Return on ad spend hit 825%.
## The Challenge
The business was already spending on Google Ads when we took over the account. That's sometimes harder than starting from scratch, because there's an existing structure with its own momentum and a client who's used to seeing certain metrics, even if those metrics don't reflect actual business results.
The account had a classic set of problems. Broad match keywords were consuming most of the budget on irrelevant searches. A campaign targeting "mechanic" was paying for clicks from people searching for "mechanic jobs," "mechanic schools," and "mechanic tool sets." There was no negative keyword strategy. Campaign structure was flat: one or two campaigns with large ad groups mixing different service types together, making it impossible to control budgets or tailor ad copy to specific services.
Conversion tracking was partially implemented. Form submissions were being counted, but phone calls, the primary way automotive service customers contact a shop, were not. The business had no real picture of which campaigns were driving actual customers versus which were generating clicks that went nowhere.
The automotive service market in Edmonton is competitive. Multiple shops target the same keywords, and Google Ads costs reflect that competition. Wasting budget on irrelevant clicks in this market means subsidizing your competitors' cheaper cost-per-click by inflating auction prices without benefiting from them.
## Our Approach
We rebuilt the account structure from scratch. Each service line got its own campaign with tightly themed ad groups. Oil changes, brake service, transmission work, and general repair each had dedicated campaigns with budgets we could control independently. This let us allocate more budget to high-margin services and less to commodity services where margins are thin.
The negative keyword work was extensive. We pulled the search term reports from the existing account and found hundreds of irrelevant queries that had been consuming budget. We built negative keyword lists organized by theme: employment-related terms, educational queries, DIY searches, competitor names, and geographic areas outside the service region. These lists were applied at the campaign and account level as appropriate, and we review search terms weekly to catch new irrelevant queries.
Conversion tracking was the foundation for everything else. We set up call tracking with dynamic number insertion so every call from an ad was attributed to the specific campaign and keyword that triggered it. Form submissions were tracked with proper event firing. Both conversion types were imported into Google Ads so the bidding algorithms had accurate data to optimize against.
We implemented budget monitoring that checks spend every 30 minutes. In a competitive market with seasonal demand fluctuations, daily budgets can be exhausted by mid-morning during peak periods. The monitoring system alerts us when spend pace is ahead of target, letting us adjust before budget runs out and the ads go dark for the rest of the day. During seasonal peaks, like the period before winter when everyone needs winter tires and vehicle inspections, this monitoring prevented multiple potential overspend situations.
Ad copy was rewritten for every ad group with specific service messaging, pricing where appropriate, and calls to action tailored to the service type. We used ad extensions systematically: location extensions, call extensions, structured snippets listing services, and sitelinks to specific service pages.
We also aligned the organic SEO strategy with the paid campaigns. Service pages on the website were optimized to match the landing pages we used for ads, which improved Quality Scores and lowered cost-per-click. When someone clicks an ad for "brake repair Edmonton" and lands on a page specifically about brake repair with relevant content, pricing context, and a clear call to action, the conversion rate is dramatically higher than landing on a generic services page. The SEO work ensured these pages also ranked organically, giving the business both paid and organic visibility for the same high-value searches.
## The Results
825% return on ad spend measured by revenue attributed to Google Ads campaignsSource: conversion tracking data correlated with point-of-sale revenue
Budget waste eliminated through negative keywords blocking 200+ irrelevant query patternsSource: search term reports and negative keyword lists
The 825% ROAS means that for every dollar spent on Google Ads, the business generated $8.25 in tracked revenue. This number is conservative because it only counts revenue directly attributed through the conversion tracking system. Walk-in customers who saw an ad but didn't click, or who called from a number they remembered rather than the tracking number, aren't included.
The restructured campaigns also gave the business control it didn't have before. When brake service demand spiked before winter, we could increase that campaign's budget without affecting other service lines. When a promotion on oil changes ran, we could push that specific campaign without overspending on the account overall.
The 30-minute budget monitoring caught overspend risk on 12 separate occasions during the first year, typically during seasonal demand spikes when competitors were also increasing their spend and click costs rose. Each catch prevented the ads from going dark during peak hours, which in automotive service translates directly to missed phone calls and lost revenue.
The combination of paid and organic visibility created a compounding advantage. As the SEO work improved organic rankings for service keywords, the business appeared in both paid and organic results for the same searches. This dual presence increases click-through rates and builds credibility, and the organic rankings provide a safety net that keeps the phone ringing even on days when ad budgets are constrained.
[See how we manage Google Ads campaigns](/services/google-ads/) and read about [why flat-fee pricing aligns our incentives with yours](/blog/why-flat-fees/).
---